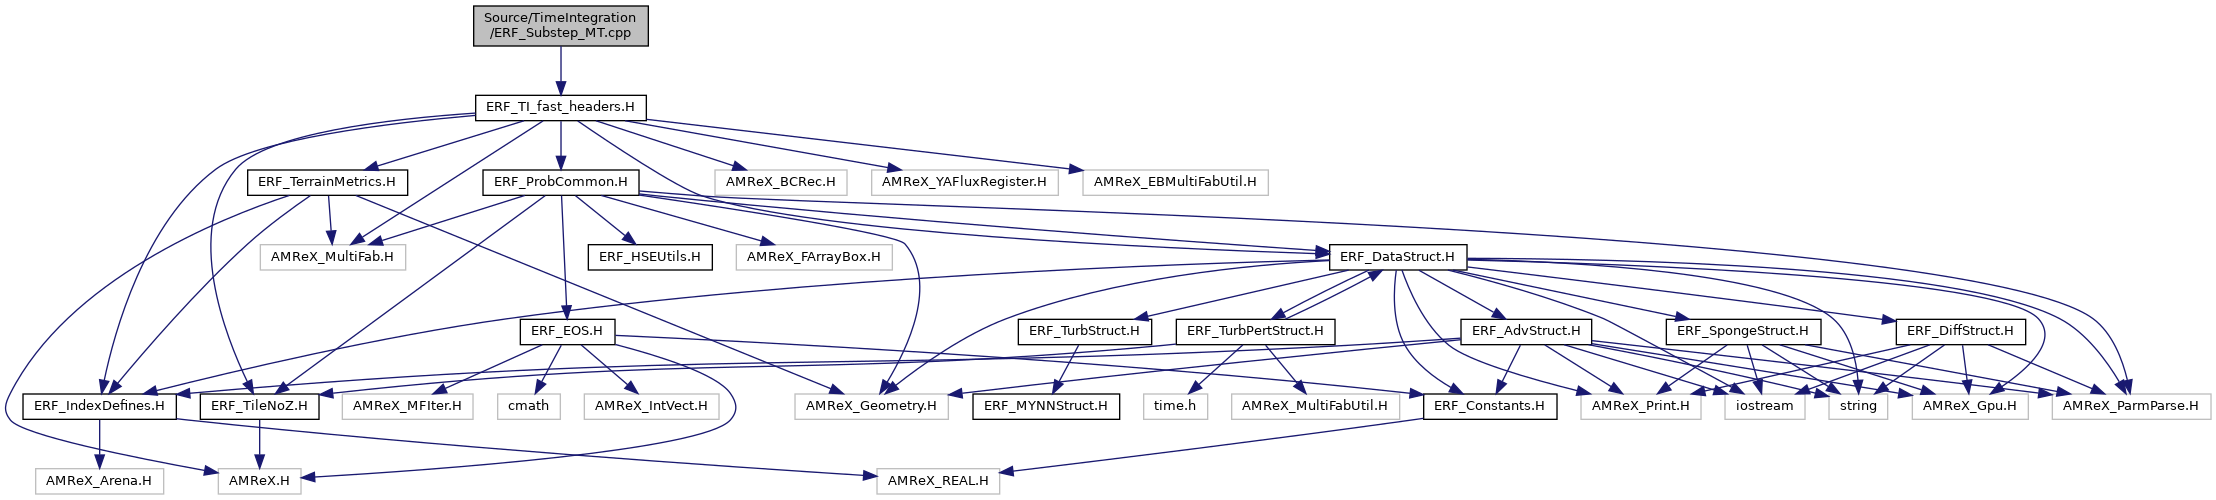
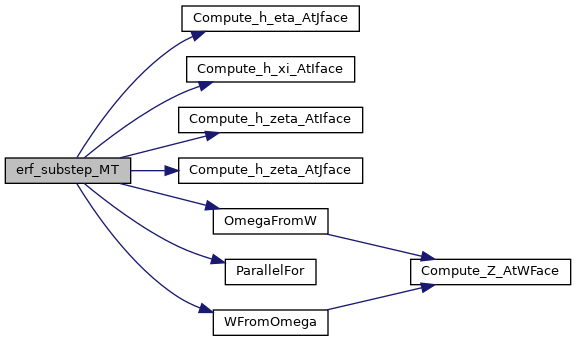
91 BL_PROFILE_REGION(
"erf_substep_MT()");
93 Real dtau =
static_cast<Real>(dtau_d);
103 bool l_rayleigh_impl_for_w = (sinesq_stag_d !=
nullptr);
105 const Real*
dx = geom.CellSize();
106 const GpuArray<Real, AMREX_SPACEDIM>
dxInv = geom.InvCellSizeArray();
112 MultiFab coeff_A_mf(fast_coeffs, make_alias, 0, 1);
113 MultiFab inv_coeff_B_mf(fast_coeffs, make_alias, 1, 1);
114 MultiFab coeff_C_mf(fast_coeffs, make_alias, 2, 1);
115 MultiFab coeff_P_mf(fast_coeffs, make_alias, 3, 1);
116 MultiFab coeff_Q_mf(fast_coeffs, make_alias, 4, 1);
120 const Array<Real,AMREX_SPACEDIM> grav{
zero,
zero, -gravity};
121 const GpuArray<Real,AMREX_SPACEDIM> grav_gpu{grav[0], grav[1], grav[2]};
131 #pragma omp parallel if (Gpu::notInLaunchRegion())
134 FArrayBox temp_rhs_fab;
139 std::array<FArrayBox,AMREX_SPACEDIM> flux;
143 for ( MFIter mfi(S_stg_data[
IntVars::cons],
false); mfi.isValid(); ++mfi)
145 Box bx = mfi.tilebox();
146 Box tbx = surroundingNodes(bx,0);
147 Box tby = surroundingNodes(bx,1);
148 Box tbz = surroundingNodes(bx,2);
150 Box vbx = mfi.validbox();
151 const auto& vbx_hi = ubound(vbx);
153 const Array4<Real const>& xmom_src_arr = xmom_src.const_array(mfi);
154 const Array4<Real const>& ymom_src_arr = ymom_src.const_array(mfi);
155 const Array4<Real const>& zmom_src_arr = zmom_src.const_array(mfi);
156 const Array4<Real const>& cc_src_arr = cc_src.const_array(mfi);
158 const Array4<const Real> & stg_cons = S_stg_data[
IntVars::cons].const_array(mfi);
159 const Array4<const Real> & stg_xmom = S_stg_data[
IntVars::xmom].const_array(mfi);
160 const Array4<const Real> & stg_ymom = S_stg_data[
IntVars::ymom].const_array(mfi);
161 const Array4<const Real> & stg_zmom = S_stg_data[
IntVars::zmom].const_array(mfi);
162 const Array4<const Real> & prim = S_stg_prim.const_array(mfi);
163 const Array4<const Real> & qt_arr =
qt.const_array(mfi);
165 const Array4<const Real>& slow_rhs_cons = S_slow_rhs[
IntVars::cons].const_array(mfi);
166 const Array4<const Real>& slow_rhs_rho_u = S_slow_rhs[
IntVars::xmom].const_array(mfi);
167 const Array4<const Real>& slow_rhs_rho_v = S_slow_rhs[
IntVars::ymom].const_array(mfi);
168 const Array4<const Real>& slow_rhs_rho_w = S_slow_rhs[
IntVars::zmom].const_array(mfi);
170 const Array4<Real>& cur_cons = S_data[
IntVars::cons].array(mfi);
171 const Array4<Real>& cur_xmom = S_data[
IntVars::xmom].array(mfi);
172 const Array4<Real>& cur_ymom = S_data[
IntVars::ymom].array(mfi);
173 const Array4<Real>& cur_zmom = S_data[
IntVars::zmom].array(mfi);
175 const Array4<Real>& lagged = lagged_delta_rt.array(mfi);
177 const Array4<const Real>& prev_cons = S_prev[
IntVars::cons].const_array(mfi);
178 const Array4<const Real>& prev_xmom = S_prev[
IntVars::xmom].const_array(mfi);
179 const Array4<const Real>& prev_ymom = S_prev[
IntVars::ymom].const_array(mfi);
180 const Array4<const Real>& prev_zmom = S_prev[
IntVars::zmom].const_array(mfi);
183 const Array4<Real>& avg_xmom_arr = avg_xmom.array(mfi);
184 const Array4<Real>& avg_ymom_arr = avg_ymom.array(mfi);
185 const Array4<Real>& avg_zmom_arr = avg_zmom.array(mfi);
187 const Array4<const Real>& z_nd_old = z_phys_nd_old->const_array(mfi);
188 const Array4<const Real>& z_nd_new = z_phys_nd_new->const_array(mfi);
189 const Array4<const Real>& z_nd_stg = z_phys_nd_stg->const_array(mfi);
190 const Array4<const Real>& detJ_old = detJ_cc_old->const_array(mfi);
191 const Array4<const Real>& detJ_new = detJ_cc_new->const_array(mfi);
192 const Array4<const Real>& detJ_stg = detJ_cc_stg->const_array(mfi);
194 const Array4<const Real>& z_t_arr = z_t_rk->const_array(mfi);
195 const Array4<const Real>& zp_t_arr = z_t_pert->const_array(mfi);
197 const Array4< Real>& omega_arr = Omega.array(mfi);
200 const Array4<const Real>& mf_mx = mapfac[
MapFacType::m_x]->const_array(mfi);
201 const Array4<const Real>& mf_my = mapfac[
MapFacType::m_y]->const_array(mfi);
202 const Array4<const Real>& mf_ux = mapfac[
MapFacType::u_x]->const_array(mfi);
203 const Array4<const Real>& mf_vy = mapfac[
MapFacType::v_y]->const_array(mfi);
209 Box gbxo = mfi.nodaltilebox(2);
211 BL_PROFILE(
"fast_MT_making_omega");
212 Box gbxo_lo = gbxo; gbxo_lo.setBig(2,0);
213 ParallelFor(gbxo_lo, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept {
214 omega_arr(i,j,k) =
zero;
216 Box gbxo_hi = gbxo; gbxo_hi.setSmall(2,gbxo.bigEnd(2));
217 ParallelFor(gbxo_hi, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept {
218 omega_arr(i,j,k) = prev_zmom(i,j,k) - stg_zmom(i,j,k) - zp_t_arr(i,j,k);
225 gbxo_mid.setSmall(2, std::max(gbxo.smallEnd(2), 1));
226 gbxo_mid.setBig (2, gbxo.bigEnd(2)-1);
228 ParallelFor(gbxo_mid, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept {
230 (
OmegaFromW(i,j,k,prev_zmom(i,j,k),prev_xmom,prev_ymom,mf_ux,mf_vy,z_nd_old,
dxInv)
231 -
OmegaFromW(i,j,k, stg_zmom(i,j,k), stg_xmom, stg_ymom,mf_ux,mf_vy,z_nd_old,
dxInv) )
237 const Array4<const Real>& pi_stage_ca = pi_stage.const_array(mfi);
239 const Array4<Real>& theta_extrap = extrap.array(mfi);
243 Box gbx = mfi.tilebox(); gbx.grow(1);
244 Box gtbx = mfi.nodaltilebox(0); gtbx.grow(1); gtbx.setSmall(2,0);
245 Box gtby = mfi.nodaltilebox(1); gtby.grow(1); gtby.setSmall(2,0);
249 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept {
254 theta_extrap(i,j,k) = delta_rt;
258 theta_extrap(i,j,k) *= (
one + RvOverRd*
qv);
261 lagged(i,j,k) = delta_rt;
263 }
else if (use_lagged_delta_rt) {
266 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept {
268 theta_extrap(i,j,k) = delta_rt + beta_d * (delta_rt - lagged(i,j,k));
272 theta_extrap(i,j,k) *= (
one + RvOverRd*
qv);
275 lagged(i,j,k) = delta_rt;
280 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept {
285 theta_extrap(i,j,k) *= (
one + RvOverRd*
qv);
289 RHS_fab.resize (tbz,1, The_Async_Arena());
290 soln_fab.resize (tbz,1, The_Async_Arena());
291 temp_rhs_fab.resize(tbz,2, The_Async_Arena());
293 auto const& RHS_a = RHS_fab.array();
294 auto const& soln_a = soln_fab.array();
295 auto const& temp_rhs_arr = temp_rhs_fab.array();
297 auto const& coeffA_a = coeff_A_mf.array(mfi);
298 auto const& inv_coeffB_a = inv_coeff_B_mf.array(mfi);
299 auto const& coeffC_a = coeff_C_mf.array(mfi);
300 auto const& coeffP_a = coeff_P_mf.array(mfi);
301 auto const& coeffQ_a = coeff_Q_mf.array(mfi);
307 BL_PROFILE(
"substep_xymom_T");
309 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
314 Real gp_xi = (theta_extrap(i,j,k) - theta_extrap(i-1,j,k)) * dxi;
315 Real gp_zeta_on_iface = (k == 0) ?
316 myhalf * dzi * ( theta_extrap(i-1,j,k+1) + theta_extrap(i,j,k+1)
317 - theta_extrap(i-1,j,k ) - theta_extrap(i,j,k ) ) :
318 fourth * dzi * ( theta_extrap(i-1,j,k+1) + theta_extrap(i,j,k+1)
319 - theta_extrap(i-1,j,k-1) - theta_extrap(i,j,k-1) );
320 Real gpx = h_zeta_old * gp_xi - h_xi_old * gp_zeta_on_iface;
323 Real q = (l_use_moisture) ?
myhalf * (qt_arr(i-1,j,k) + qt_arr(i,j,k)) :
zero;
325 Real pi_c =
myhalf * (pi_stage_ca(i-1,j,k) + pi_stage_ca(i ,j,k));
329 cur_xmom(i,j,k) = h_zeta_old * prev_xmom(i,j,k) + dtau * fast_rhs_rho_u
330 + dtau * slow_rhs_rho_u(i,j,k)
331 + dtau * xmom_src_arr(i,j,k);
333 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
338 Real gp_eta = (theta_extrap(i,j,k) -theta_extrap(i,j-1,k)) * dyi;
339 Real gp_zeta_on_jface = (k == 0) ?
340 myhalf * dzi * ( theta_extrap(i,j,k+1) + theta_extrap(i,j-1,k+1)
341 - theta_extrap(i,j,k ) - theta_extrap(i,j-1,k ) ) :
342 fourth * dzi * ( theta_extrap(i,j,k+1) + theta_extrap(i,j-1,k+1)
343 - theta_extrap(i,j,k-1) - theta_extrap(i,j-1,k-1) );
344 Real gpy = h_zeta_old * gp_eta - h_eta_old * gp_zeta_on_jface;
347 Real q = (l_use_moisture) ?
myhalf * (qt_arr(i,j-1,k) + qt_arr(i,j,k)) :
zero;
349 Real pi_c =
myhalf * (pi_stage_ca(i,j-1,k) + pi_stage_ca(i,j ,k));
353 cur_ymom(i, j, k) = h_zeta_old * prev_ymom(i,j,k) + dtau * fast_rhs_rho_v
354 + dtau * slow_rhs_rho_v(i,j,k)
355 + dtau * ymom_src_arr(i,j,k);
362 for (
int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
363 flux[dir].resize(surroundingNodes(bx,dir),2,The_Async_Arena());
364 flux[dir].setVal<RunOn::Device>(0);
366 const GpuArray<const Array4<Real>, AMREX_SPACEDIM>
367 flx_arr{{AMREX_D_DECL(flux[0].array(), flux[1].array(), flux[2].array())}};
371 BL_PROFILE(
"fast_T_making_rho_rhs");
372 ParallelFor(bx, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept
376 Real xflux_lo = cur_xmom(i ,j,k) - stg_xmom(i ,j,k)*h_zeta_stg_xlo;
377 Real xflux_hi = cur_xmom(i+1,j,k) - stg_xmom(i+1,j,k)*h_zeta_stg_xhi;
381 Real yflux_lo = cur_ymom(i,j ,k) - stg_ymom(i,j ,k)*h_zeta_stg_ylo;
382 Real yflux_hi = cur_ymom(i,j+1,k) - stg_ymom(i,j+1,k)*h_zeta_stg_yhi;
385 temp_rhs_arr(i,j,k,0) = ( xflux_hi - xflux_lo ) * dxi + ( yflux_hi - yflux_lo ) * dyi;
386 temp_rhs_arr(i,j,k,1) = (( xflux_hi * (prim(i,j,k,0) + prim(i+1,j,k,0)) -
387 xflux_lo * (prim(i,j,k,0) + prim(i-1,j,k,0)) ) * dxi +
388 ( yflux_hi * (prim(i,j,k,0) + prim(i,j+1,k,0)) -
389 yflux_lo * (prim(i,j,k,0) + prim(i,j-1,k,0)) ) * dyi) *
myhalf;
392 (flx_arr[0])(i,j,k,0) = xflux_lo;
393 (flx_arr[0])(i,j,k,1) = (flx_arr[0])(i ,j,k,0) *
myhalf * (prim(i,j,k,0) + prim(i-1,j,k,0));
395 (flx_arr[1])(i,j,k,0) = yflux_lo;
396 (flx_arr[1])(i,j,k,1) = (flx_arr[1])(i,j ,k,0) *
myhalf * (prim(i,j,k,0) + prim(i,j-1,k,0));
399 (flx_arr[0])(i+1,j,k,0) = xflux_hi;
400 (flx_arr[0])(i+1,j,k,1) = (flx_arr[0])(i+1,j,k,0) *
myhalf * (prim(i,j,k,0) + prim(i+1,j,k,0));
403 (flx_arr[1])(i,j+1,k,0) = yflux_hi;
404 (flx_arr[1])(i,j+1,k,1) = (flx_arr[1])(i,j+1,k,0) *
myhalf * (prim(i,j,k,0) + prim(i,j+1,k,0));
411 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
414 cur_xmom(i, j, k) /= h_zeta_new;
415 avg_xmom_arr(i,j,k) += facinv*(cur_xmom(i,j,k) - stg_xmom(i,j,k));
417 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
420 cur_ymom(i, j, k) /= h_zeta_new;
421 avg_ymom_arr(i,j,k) += facinv*(cur_ymom(i,j,k) - stg_ymom(i,j,k));
424 Box bx_shrunk_in_k = bx;
425 int klo = tbz.smallEnd(2);
426 int khi = tbz.bigEnd(2);
427 bx_shrunk_in_k.setSmall(2,
klo+1);
428 bx_shrunk_in_k.setBig(2,
khi-1);
436 BL_PROFILE(
"fast_loop_on_shrunk_t");
438 ParallelFor(bx_shrunk_in_k, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
440 Real dJ_old_kface =
myhalf * (detJ_old(i,j,k) + detJ_old(i,j,k-1));
441 Real dJ_new_kface =
myhalf * (detJ_new(i,j,k) + detJ_new(i,j,k-1));
442 Real dJ_stg_kface =
myhalf * (detJ_stg(i,j,k) + detJ_stg(i,j,k-1));
444 Real coeff_P = coeffP_a(i,j,k);
445 Real coeff_Q = coeffQ_a(i,j,k);
454 - coeff_P * stg_cons(i,j,k ,
RhoTheta_comp) * (dJ_stg_kface/dJ_old_kface)
455 - coeff_Q * stg_cons(i,j,k-1,
RhoTheta_comp) * (dJ_stg_kface/dJ_old_kface)
457 + halfg * ( stg_cons(i,j,k,
Rho_comp) + stg_cons(i,j,k-1,
Rho_comp) ) * (dJ_stg_kface/dJ_old_kface);
463 Real Omega_kp1 = omega_arr(i,j,k+1);
464 Real Omega_k = omega_arr(i,j,k );
465 Real Omega_km1 = omega_arr(i,j,k-1);
467 Real detJdiff = (detJ_old(i,j,k) - detJ_old(i,j,k-1)) / (detJ_old(i,j,k)*detJ_old(i,j,k-1));
470 R1_tmp += halfg * ( beta_1 * dzi * (Omega_kp1/detJ_old(i,j,k) + detJdiff*Omega_k - Omega_km1/detJ_old(i,j,k-1))
471 + temp_rhs_arr(i,j,k,
Rho_comp)/detJ_old(i,j,k) + temp_rhs_arr(i,j,k-1,
Rho_comp)/detJ_old(i,j,k-1) );
475 coeff_P/detJ_old(i,j,k ) * ( beta_1 * dzi * (Omega_kp1*theta_t_hi - Omega_k*theta_t_mid)
477 coeff_Q/detJ_old(i,j,k-1) * ( beta_1 * dzi * (Omega_k*theta_t_mid - Omega_km1*theta_t_lo)
481 RHS_a(i,j,k) = prev_zmom(i,j,k) - (dJ_stg_kface/dJ_old_kface) * stg_zmom(i,j,k)
482 + dtau * slow_rhs_rho_w(i,j,k) / dJ_stg_kface
483 + dtau * zmom_src_arr(i,j,k);
485 RHS_a(i,j,k) += dtau * R0_tmp;
487 RHS_a(i,j,k) += dtau * dtau*beta_2*R1_tmp;
490 Real UppVpp = (dJ_new_kface/dJ_old_kface) *
OmegaFromW(i,j,k,0.,cur_xmom,cur_ymom,mf_ux,mf_vy,z_nd_new,
dxInv)
491 -(dJ_stg_kface/dJ_old_kface) *
OmegaFromW(i,j,k,0.,stg_xmom,stg_ymom,mf_ux,mf_vy,z_nd_stg,
dxInv);
492 RHS_a(i,j,k) += UppVpp;
499 auto const lo = lbound(bx);
500 auto const hi = ubound(bx);
503 BL_PROFILE(
"substep_b2d_loop_t");
506 ParallelFor(b2d, [=] AMREX_GPU_DEVICE (
int i,
int j,
int)
509 Real rho_on_bdy =
myhalf * ( prev_cons(i,j,
lo.z) + prev_cons(i,j,
lo.z-1) );
510 RHS_a(i,j,
lo.z) = rho_on_bdy * zp_t_arr(i,j,
lo.z);
512 soln_a(i,j,
lo.z) = RHS_a(i,j,
lo.z) * inv_coeffB_a(i,j,
lo.z);
514 RHS_a(i,j,
hi.z+1) = dtau * (slow_rhs_rho_w(i,j,
hi.z+1) + zmom_src_arr(i,j,
hi.z+1));
516 for (
int k =
lo.z+1; k <=
hi.z+1; k++) {
517 soln_a(i,j,k) = (RHS_a(i,j,k)-coeffA_a(i,j,k)*soln_a(i,j,k-1)) * inv_coeffB_a(i,j,k);
520 for (
int k =
hi.z; k >=
lo.z; k--) {
521 soln_a(i,j,k) -= ( coeffC_a(i,j,k) * inv_coeffB_a(i,j,k) ) * soln_a(i,j,k+1);
525 cur_zmom(i,j,
hi.z+1) = stg_zmom(i,j,
hi.z+1) + soln_a(i,j,
hi.z+1);
528 for (
int j =
lo.y; j <=
hi.y; ++j) {
530 for (
int i =
lo.x; i <=
hi.x; ++i) {
532 Real rho_on_bdy =
myhalf * ( prev_cons(i,j,
lo.z) + prev_cons(i,j,
lo.z-1) );
533 RHS_a(i,j,
lo.z) = rho_on_bdy * zp_t_arr(i,j,
lo.z);
535 soln_a(i,j,
lo.z) = RHS_a(i,j,
lo.z) * inv_coeffB_a(i,j,
lo.z);
539 for (
int j =
lo.y; j <=
hi.y; ++j) {
541 for (
int i =
lo.x; i <=
hi.x; ++i) {
542 RHS_a(i,j,
hi.z+1) = dtau * (slow_rhs_rho_w(i,j,
hi.z+1) + zmom_src_arr(i,j,
hi.z+1));
545 for (
int k =
lo.z+1; k <=
hi.z+1; ++k) {
546 for (
int j =
lo.y; j <=
hi.y; ++j) {
548 for (
int i =
lo.x; i <=
hi.x; ++i) {
549 soln_a(i,j,k) = (RHS_a(i,j,k)-coeffA_a(i,j,k)*soln_a(i,j,k-1)) * inv_coeffB_a(i,j,k);
553 for (
int k =
hi.z; k >=
lo.z; --k) {
554 for (
int j =
lo.y; j <=
hi.y; ++j) {
556 for (
int i =
lo.x; i <=
hi.x; ++i) {
557 soln_a(i,j,k) -= ( coeffC_a(i,j,k) * inv_coeffB_a(i,j,k) ) * soln_a(i,j,k+1);
563 for (
int j =
lo.y; j <=
hi.y; ++j) {
565 for (
int i =
lo.x; i <=
hi.x; ++i) {
566 cur_zmom(i,j,
hi.z+1) = stg_zmom(i,j,
hi.z+1) + soln_a(i,j,
hi.z+1);
573 BL_PROFILE(
"substep_new_drhow");
575 ParallelFor(tbz, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
580 cur_zmom(i,j,k) =
WFromOmega(i,j,k,rho_on_face*(z_t_arr(i,j,k)+zp_t_arr(i,j,k)),
581 cur_xmom,cur_ymom,mf_ux,mf_vy,z_nd_new,
dxInv);
584 soln_a(i,j,k) =
zero;
590 Real wpp = soln_a(i,j,k) + UppVpp;
591 Real dJ_old_kface =
myhalf * (detJ_old(i,j,k) + detJ_old(i,j,k-1));
592 Real dJ_new_kface =
myhalf * (detJ_new(i,j,k) + detJ_new(i,j,k-1));
594 cur_zmom(i,j,k) = dJ_old_kface * (stg_zmom(i,j,k) + wpp);
595 cur_zmom(i,j,k) /= dJ_new_kface;
597 soln_a(i,j,k) =
OmegaFromW(i,j,k,cur_zmom(i,j,k),cur_xmom,cur_ymom,mf_ux,mf_vy,z_nd_new,
dxInv)
598 -
OmegaFromW(i,j,k,stg_zmom(i,j,k),stg_xmom,stg_ymom,mf_ux,mf_vy,z_nd_stg,
dxInv);
599 soln_a(i,j,k) -= rho_on_face * zp_t_arr(i,j,k);
602 if (l_rayleigh_impl_for_w && k > 0) {
603 Real damping_coeff = l_damp_coef * dtau * sinesq_stag_d[k];
604 cur_zmom(i,j,k) /= (
one + damping_coeff);
613 BL_PROFILE(
"fast_rho_final_update");
614 ParallelFor(bx, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept
616 Real zflux_lo = beta_2 * soln_a(i,j,k ) + beta_1 * omega_arr(i,j,k);
617 Real zflux_hi = beta_2 * soln_a(i,j,k+1) + beta_1 * omega_arr(i,j,k+1);
621 avg_zmom_arr(i,j,k) += facinv*zflux_lo / (mf_mx(i,j,0) * mf_my(i,j,0));
623 (flx_arr[2])(i,j,k,0) = zflux_lo / (mf_mx(i,j,0) * mf_my(i,j,0));
629 Real fast_rhs_rho = -(temp_rhs_arr(i,j,k,0) + ( zflux_hi - zflux_lo ) * dzi);
630 Real fast_rhs_rhotheta = -( temp_rhs_arr(i,j,k,1) +
myhalf *
631 ( zflux_hi * (prim(i,j,k) + prim(i,j,k+1))
632 - zflux_lo * (prim(i,j,k) + prim(i,j,k-1)) ) * dzi );
634 cur_cons(i,j,k,0) *= (detJ_old(i,j,k)/detJ_new(i,j,k));
635 cur_cons(i,j,k,1) *= (detJ_old(i,j,k)/detJ_new(i,j,k));
637 cur_cons(i,j,k,0) += dtau * ( slow_rhs_cons(i,j,k,0) + fast_rhs_rho / detJ_new(i,j,k));
638 cur_cons(i,j,k,1) += dtau * ( slow_rhs_cons(i,j,k,1) + fast_rhs_rhotheta / detJ_new(i,j,k));
641 (flx_arr[2])(i,j,k,1) = (flx_arr[2])(i,j,k,0) *
myhalf * (prim(i,j,k) + prim(i,j,k-1));
645 avg_zmom_arr(i,j,k+1) += facinv * zflux_hi / (mf_mx(i,j,0) * mf_my(i,j,0));
647 (flx_arr[2])(i,j,k+1,0) = zflux_hi / (mf_mx(i,j,0) * mf_my(i,j,0));
648 (flx_arr[2])(i,j,k+1,1) = (flx_arr[2])(i,j,k+1,0) *
myhalf * (prim(i,j,k) + prim(i,j,k+1));
660 int strt_comp_reflux = 0;
662 int num_comp_reflux = 1;
663 if (level < finest_level) {
664 fr_as_crse->CrseAdd(mfi,
665 {{AMREX_D_DECL(&(flux[0]), &(flux[1]), &(flux[2]))}},
666 dx, dtau, strt_comp_reflux, strt_comp_reflux, num_comp_reflux, RunOn::Device);
669 fr_as_fine->FineAdd(mfi,
670 {{AMREX_D_DECL(&(flux[0]), &(flux[1]), &(flux[2]))}},
671 dx, dtau, strt_comp_reflux, strt_comp_reflux, num_comp_reflux, RunOn::Device);
677 Gpu::streamSynchronize();
constexpr amrex::Real R_v
Definition: ERF_Constants.H:35
constexpr amrex::Real R_d
Definition: ERF_Constants.H:34
constexpr amrex::Real Gamma
Definition: ERF_Constants.H:54
@ v_y
Definition: ERF_DataStruct.H:30
@ m_y
Definition: ERF_DataStruct.H:30
@ u_x
Definition: ERF_DataStruct.H:29
@ m_x
Definition: ERF_DataStruct.H:29
#define PrimQ1_comp
Definition: ERF_IndexDefines.H:61
#define Rho_comp
Definition: ERF_IndexDefines.H:39
#define RhoTheta_comp
Definition: ERF_IndexDefines.H:40
#define PrimTheta_comp
Definition: ERF_IndexDefines.H:58
amrex::GpuArray< Real, AMREX_SPACEDIM > dxInv
Definition: ERF_InitCustomPertVels_ParticleTests.H:17
const int klo
Definition: ERF_InitCustomPert_ABL.H:75
const Real dx
Definition: ERF_InitCustomPert_ABL.H:44
const int khi
Definition: ERF_InitCustomPert_Bubble.H:21
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
constexpr amrex::Real one
Definition: ERF_NumericalConstants.H:30
constexpr amrex::Real fourth
Definition: ERF_NumericalConstants.H:35
constexpr amrex::Real zero
Definition: ERF_NumericalConstants.H:29
constexpr amrex::Real myhalf
Definition: ERF_NumericalConstants.H:34
amrex::Real Real
Definition: ERF_ShocInterface.H:19
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real OmegaFromW(int &i, int &j, int &k, amrex::Real w, const amrex::Array4< const amrex::Real > &u_arr, const amrex::Array4< const amrex::Real > &v_arr, const amrex::Array4< const amrex::Real > &mf_u, const amrex::Array4< const amrex::Real > &mf_v, const amrex::Array4< const amrex::Real > &z_nd, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &dxInv)
Definition: ERF_TerrainMetrics.H:791
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_xi_AtIface(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:292
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_zeta_AtIface(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:269
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_zeta_AtJface(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:339
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_eta_AtJface(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:385
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real WFromOmega(int &i, int &j, int &k, amrex::Real omega, const amrex::Array4< const amrex::Real > &u_arr, const amrex::Array4< const amrex::Real > &v_arr, const amrex::Array4< const amrex::Real > &mf_u, const amrex::Array4< const amrex::Real > &mf_v, const amrex::Array4< const amrex::Real > &z_nd, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &dxInv)
Definition: ERF_TerrainMetrics.H:856
@ gpy
Definition: ERF_IndexDefines.H:225
@ gpx
Definition: ERF_IndexDefines.H:224
@ ymom
Definition: ERF_IndexDefines.H:234
@ cons
Definition: ERF_IndexDefines.H:232
@ zmom
Definition: ERF_IndexDefines.H:235
@ xmom
Definition: ERF_IndexDefines.H:233
@ qt
Definition: ERF_Kessler.H:30
@ qv
Definition: ERF_Kessler.H:31
@ q
Definition: ERF_WSM6.H:273