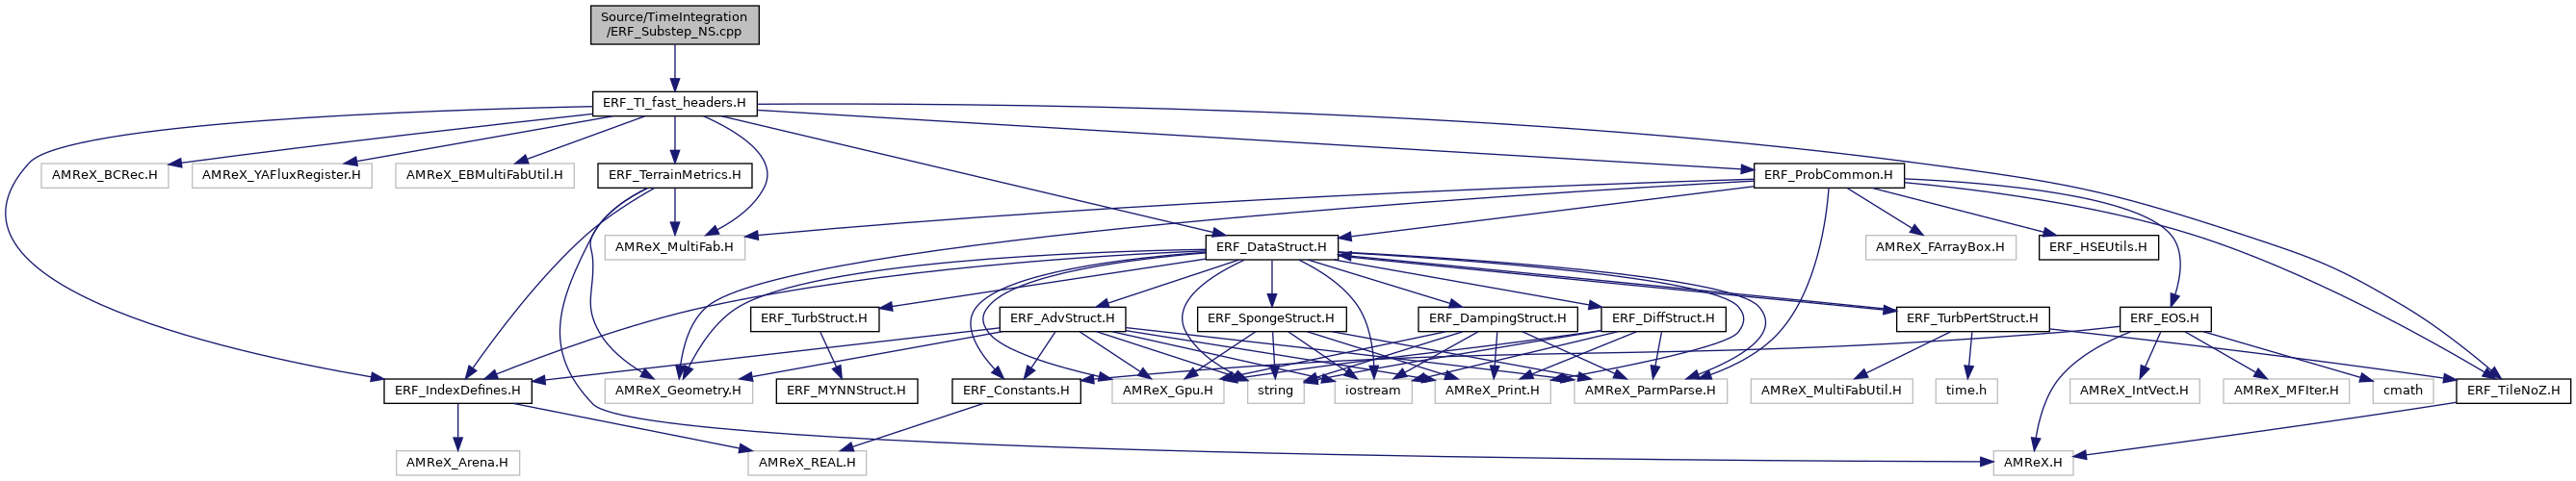
Function for computing the fast RHS with no terrain and variable vertical spacing
79 BL_PROFILE_REGION(
"erf_substep_NS()");
81 Real dtau =
static_cast<Real>(dtau_d);
83 const Box& domain = geom.Domain();
84 auto const domlo = lbound(domain);
85 auto const domhi = ubound(domain);
88 int ihi = domhi.x + 1;
90 int jhi = domhi.y + 1;
98 bool l_rayleigh_impl_for_w = (sinesq_stag_d !=
nullptr);
100 const Real*
dx = geom.CellSize();
101 const GpuArray<Real, AMREX_SPACEDIM>
dxInv = geom.InvCellSizeArray();
107 auto dz_ptr = stretched_dz_d.data();
110 const auto& dm = S_stage_data[
IntVars::cons].DistributionMap();
112 MultiFab Delta_rho_theta( ba , dm, 1, 1);
113 MultiFab Delta_rho_w (convert(ba,IntVect(0,0,1)), dm, 1, IntVect(1,1,0));
115 MultiFab coeff_A_mf(fast_coeffs, make_alias, 0, 1);
116 MultiFab inv_coeff_B_mf(fast_coeffs, make_alias, 1, 1);
117 MultiFab coeff_C_mf(fast_coeffs, make_alias, 2, 1);
118 MultiFab coeff_P_mf(fast_coeffs, make_alias, 3, 1);
119 MultiFab coeff_Q_mf(fast_coeffs, make_alias, 4, 1);
123 const Array<Real,AMREX_SPACEDIM> grav{
zero,
zero, -gravity};
124 const GpuArray<Real,AMREX_SPACEDIM> grav_gpu{grav[0], grav[1], grav[2]};
144 #pragma omp parallel if (Gpu::notInLaunchRegion())
146 for ( MFIter mfi(S_stage_data[
IntVars::cons],TilingIfNotGPU()); mfi.isValid(); ++mfi)
148 const Array4<const Real>& prev_cons = S_prev[
IntVars::cons].const_array(mfi);
149 const Array4<const Real>& prev_zmom = S_prev[
IntVars::zmom].const_array(mfi);
151 const Array4<const Real>& stage_cons = S_stage_data[
IntVars::cons].const_array(mfi);
152 const Array4<const Real>& stage_zmom = S_stage_data[
IntVars::zmom].const_array(mfi);
154 const Array4<Real>& prev_drho_w = Delta_rho_w.array(mfi);
155 const Array4<Real>& prev_drho_theta = Delta_rho_theta.array(mfi);
156 const Array4<Real>& lagged_arr = lagged_delta_rt.array(mfi);
157 const Array4<Real>& theta_extrap = extrap.array(mfi);
158 const Array4<const Real>& prim = S_stage_prim.const_array(mfi);
160 Box gbx = mfi.growntilebox(1);
161 ParallelFor(gbx, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept
166 theta_extrap(i,j,k) = prev_drho_theta(i,j,k);
168 theta_extrap(i,j,k) = prev_drho_theta(i,j,k) + beta_d *
169 ( prev_drho_theta(i,j,k) - lagged_arr(i,j,k) );
178 lagged_arr(i,j,k) = prev_drho_theta(i,j,k);
190 Box gtbz = mfi.grownnodaltilebox(2,IntVect(1,1,0));
191 ParallelFor(gtbz, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept {
192 prev_drho_w(i,j,k) = prev_zmom(i,j,k) - stage_zmom(i,j,k);
201 #pragma omp parallel if (Gpu::notInLaunchRegion())
203 for ( MFIter mfi(S_stage_data[
IntVars::cons],TilingIfNotGPU()); mfi.isValid(); ++mfi)
205 Box tbx = mfi.nodaltilebox(0);
206 Box tby = mfi.nodaltilebox(1);
208 const Array4<Real const>& xmom_src_arr = xmom_src.const_array(mfi);
209 const Array4<Real const>& ymom_src_arr = ymom_src.const_array(mfi);
211 const Array4<const Real> & stage_xmom = S_stage_data[
IntVars::xmom].const_array(mfi);
212 const Array4<const Real> & stage_ymom = S_stage_data[
IntVars::ymom].const_array(mfi);
213 const Array4<const Real> & qt_arr =
qt.const_array(mfi);
215 const Array4<const Real>& slow_rhs_rho_u = S_slow_rhs[
IntVars::xmom].const_array(mfi);
216 const Array4<const Real>& slow_rhs_rho_v = S_slow_rhs[
IntVars::ymom].const_array(mfi);
218 const Array4<Real>& temp_cur_xmom_arr = temp_cur_xmom.array(mfi);
219 const Array4<Real>& temp_cur_ymom_arr = temp_cur_ymom.array(mfi);
221 const Array4<const Real>& prev_xmom = S_prev[
IntVars::xmom].const_array(mfi);
222 const Array4<const Real>& prev_ymom = S_prev[
IntVars::ymom].const_array(mfi);
225 const Array4< Real>& avg_xmom_arr = avg_xmom.array(mfi);
226 const Array4< Real>& avg_ymom_arr = avg_ymom.array(mfi);
228 const Array4<const Real>& pi_stage_ca = pi_stage.const_array(mfi);
230 const Array4<Real>& theta_extrap = extrap.array(mfi);
233 const Array4<const Real>& mf_ux = mapfac[
MapFacType::u_x]->const_array(mfi);
234 const Array4<const Real>& mf_uy = mapfac[
MapFacType::u_y]->const_array(mfi);
235 const Array4<const Real>& mf_vx = mapfac[
MapFacType::v_x]->const_array(mfi);
236 const Array4<const Real>& mf_vy = mapfac[
MapFacType::v_y]->const_array(mfi);
256 if (nrk == 0 and step == 0) {
258 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
260 Real h_zeta = dz_ptr[k] * dzi;
261 Real new_drho_u = dtau * slow_rhs_rho_u(i,j,k) + dtau * xmom_src_arr(i,j,k);;
262 avg_xmom_arr(i,j,k) += facinv * new_drho_u * h_zeta / mf_uy(i,j,0);
263 temp_cur_xmom_arr(i,j,k) = stage_xmom(i,j,k) + new_drho_u;
265 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
267 Real h_zeta = dz_ptr[k] * dzi;
268 Real new_drho_v = dtau * slow_rhs_rho_v(i,j,k) + dtau * ymom_src_arr(i,j,k);
269 avg_ymom_arr(i,j,k) += facinv * new_drho_v * h_zeta / mf_vx(i,j,0);
270 temp_cur_ymom_arr(i,j,k) = stage_ymom(i,j,k) + new_drho_v;
274 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
277 Real gpx = (l_real_bc && (level==0) && (i==ilo || i==ihi)) ?
Real(0.) :
278 (theta_extrap(i,j,k) - theta_extrap(i-1,j,k))*dxi;
281 Real q = (l_use_moisture) ?
myhalf * (qt_arr(i,j,k) + qt_arr(i-1,j,k)) :
zero;
283 Real pi_c =
myhalf * (pi_stage_ca(i-1,j,k,0) + pi_stage_ca(i,j,k,0));
286 Real new_drho_u = prev_xmom(i,j,k) - stage_xmom(i,j,k)
287 + dtau * fast_rhs_rho_u + dtau * slow_rhs_rho_u(i,j,k)
288 + dtau * xmom_src_arr(i,j,k);
290 Real h_zeta = dz_ptr[k] * dzi;
291 avg_xmom_arr(i,j,k) += facinv * new_drho_u * h_zeta / mf_uy(i,j,0);
293 temp_cur_xmom_arr(i,j,k) = stage_xmom(i,j,k) + new_drho_u;
295 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
298 Real gpy = (l_real_bc && (level==0) && (j==jlo || j==jhi)) ?
Real(0.) :
299 (theta_extrap(i,j,k) - theta_extrap(i,j-1,k))*dyi;
302 Real q = (l_use_moisture) ?
myhalf * (qt_arr(i,j,k) + qt_arr(i,j-1,k)) :
zero;
304 Real pi_c =
myhalf * (pi_stage_ca(i,j-1,k,0) + pi_stage_ca(i,j,k,0));
307 Real new_drho_v = prev_ymom(i,j,k) - stage_ymom(i,j,k)
308 + dtau * fast_rhs_rho_v + dtau * slow_rhs_rho_v(i,j,k)
309 + dtau * ymom_src_arr(i,j,k);
311 Real h_zeta = dz_ptr[k] * dzi;
312 avg_ymom_arr(i,j,k) += facinv * new_drho_v * h_zeta / mf_vx(i,j,0);
314 temp_cur_ymom_arr(i,j,k) = stage_ymom(i,j,k) + new_drho_v;
320 #pragma omp parallel if (Gpu::notInLaunchRegion())
323 std::array<FArrayBox,AMREX_SPACEDIM> flux;
326 Box bx = mfi.tilebox();
327 Box tbz = surroundingNodes(bx,2);
329 Box vbx = mfi.validbox();
330 const auto& vbx_hi = ubound(vbx);
332 const Array4<Real const>& zmom_src_arr = zmom_src.const_array(mfi);
334 const Array4<const Real>& stage_xmom = S_stage_data[
IntVars::xmom].const_array(mfi);
335 const Array4<const Real>& stage_ymom = S_stage_data[
IntVars::ymom].const_array(mfi);
336 const Array4<const Real>& stage_zmom = S_stage_data[
IntVars::zmom].const_array(mfi);
337 const Array4<const Real> & prim = S_stage_prim.const_array(mfi);
339 const Array4<const Real>& prev_drho_theta = Delta_rho_theta.array(mfi);
341 const Array4<const Real>& prev_cons = S_prev[
IntVars::cons].const_array(mfi);
342 const Array4<const Real>& stage_cons = S_stage_data[
IntVars::cons].const_array(mfi);
344 const Array4<const Real>& slow_rhs_cons = S_slow_rhs[
IntVars::cons].const_array(mfi);
345 const Array4<const Real>& slow_rhs_rho_w = S_slow_rhs[
IntVars::zmom].const_array(mfi);
347 const Array4<const Real>& prev_zmom = S_prev[
IntVars::zmom].const_array(mfi);
348 const Array4< Real>& cur_zmom = S_data[
IntVars::zmom].array(mfi);
350 const Array4<Real>& temp_cur_xmom_arr = temp_cur_xmom.array(mfi);
351 const Array4<Real>& temp_cur_ymom_arr = temp_cur_ymom.array(mfi);
354 const Array4< Real>& avg_zmom_arr = avg_zmom.array(mfi);
357 const Array4<const Real>& mf_mx = mapfac[
MapFacType::m_x]->const_array(mfi);
358 const Array4<const Real>& mf_my = mapfac[
MapFacType::m_y]->const_array(mfi);
359 const Array4<const Real>& mf_uy = mapfac[
MapFacType::u_y]->const_array(mfi);
360 const Array4<const Real>& mf_vx = mapfac[
MapFacType::v_x]->const_array(mfi);
363 RHS_fab.resize(tbz,1, The_Async_Arena());
366 soln_fab.resize(tbz,1, The_Async_Arena());
368 auto const& RHS_a = RHS_fab.array();
369 auto const& soln_a = soln_fab.array();
371 auto const& temp_rhs_arr = temp_rhs.array(mfi);
373 auto const& coeffA_a = coeff_A_mf.array(mfi);
374 auto const& inv_coeffB_a = inv_coeff_B_mf.array(mfi);
375 auto const& coeffC_a = coeff_C_mf.array(mfi);
376 auto const& coeffP_a = coeff_P_mf.array(mfi);
377 auto const& coeffQ_a = coeff_Q_mf.array(mfi);
382 for (
int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
383 flux[dir].resize(surroundingNodes(bx,dir),2,The_Async_Arena());
384 flux[dir].setVal<RunOn::Device>(0);
386 const GpuArray<const Array4<Real>, AMREX_SPACEDIM>
387 flx_arr{{AMREX_D_DECL(flux[0].array(), flux[1].array(), flux[2].array())}};
390 ParallelFor(bx, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept {
391 Real xflux_lo = (temp_cur_xmom_arr(i ,j,k) - stage_xmom(i ,j,k)) / mf_uy(i ,j,0);
392 Real xflux_hi = (temp_cur_xmom_arr(i+1,j,k) - stage_xmom(i+1,j,k)) / mf_uy(i+1,j,0);
393 Real yflux_lo = (temp_cur_ymom_arr(i,j ,k) - stage_ymom(i,j ,k)) / mf_vx(i,j ,0);
394 Real yflux_hi = (temp_cur_ymom_arr(i,j+1,k) - stage_ymom(i,j+1,k)) / mf_vx(i,j+1,0);
396 Real mfsq = mf_mx(i,j,0) * mf_my(i,j,0);
398 temp_rhs_arr(i,j,k,
Rho_comp ) = ( xflux_hi - xflux_lo ) * dxi * mfsq
399 + ( yflux_hi - yflux_lo ) * dyi * mfsq;
400 temp_rhs_arr(i,j,k,
RhoTheta_comp) = (( xflux_hi * (prim(i,j,k,0) + prim(i+1,j,k,0)) -
401 xflux_lo * (prim(i,j,k,0) + prim(i-1,j,k,0)) ) * dxi * mfsq +
402 ( yflux_hi * (prim(i,j,k,0) + prim(i,j+1,k,0)) -
403 yflux_lo * (prim(i,j,k,0) + prim(i,j-1,k,0)) ) * dyi * mfsq) *
myhalf;
406 (flx_arr[0])(i,j,k,0) = xflux_lo;
407 (flx_arr[0])(i,j,k,1) = (flx_arr[0])(i ,j,k,0) *
myhalf * (prim(i,j,k,0) + prim(i-1,j,k,0));
409 (flx_arr[1])(i,j,k,0) = yflux_lo;
410 (flx_arr[1])(i,j,k,1) = (flx_arr[1])(i,j ,k,0) *
myhalf * (prim(i,j,k,0) + prim(i,j-1,k,0));
413 (flx_arr[0])(i+1,j,k,0) = xflux_hi;
414 (flx_arr[0])(i+1,j,k,1) = (flx_arr[0])(i+1,j,k,0) *
myhalf * (prim(i,j,k,0) + prim(i+1,j,k,0));
417 (flx_arr[1])(i,j+1,k,0) = yflux_hi;
418 (flx_arr[1])(i,j+1,k,1) = (flx_arr[1])(i,j+1,k,0) *
myhalf * (prim(i,j,k,0) + prim(i,j+1,k,0));
423 Box bx_shrunk_in_k = bx;
424 int klo = tbz.smallEnd(2);
425 int khi = tbz.bigEnd(2);
426 bx_shrunk_in_k.setSmall(2,
klo+1);
427 bx_shrunk_in_k.setBig(2,
khi-1);
438 ParallelFor(bx_shrunk_in_k, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
440 Real coeff_P = coeffP_a(i,j,k);
441 Real coeff_Q = coeffQ_a(i,j,k);
447 Real Omega_kp1 = prev_zmom(i,j,k+1) - stage_zmom(i,j,k+1);
448 Real Omega_k = prev_zmom(i,j,k ) - stage_zmom(i,j,k );
449 Real Omega_km1 = prev_zmom(i,j,k-1) - stage_zmom(i,j,k-1);
454 Real R0_tmp = coeff_P * prev_drho_theta(i,j,k) + coeff_Q * prev_drho_theta(i,j,k-1)
455 - halfg * ( old_drho_k + old_drho_km1 );
464 R1_tmp += beta_1 * ( ( (Omega_kp1 - Omega_k) / dz_ptr[k] + (Omega_k - Omega_km1) / dz_ptr[k-1] ) * halfg
465 +(-(Omega_kp1*theta_t_hi - Omega_k *theta_t_mid) * coeff_P / dz_ptr[k]
466 -(Omega_k *theta_t_mid - Omega_km1*theta_t_lo ) * coeff_Q / dz_ptr[k-1]) );
469 RHS_a(i,j,k) = Omega_k + dtau * (slow_rhs_rho_w(i,j,k) + R0_tmp + dtau * beta_2 * R1_tmp + zmom_src_arr(i,j,k));
476 auto const lo = lbound(bx);
477 auto const hi = ubound(bx);
479 ParallelFor(b2d, [=] AMREX_GPU_DEVICE (
int i,
int j,
int)
482 RHS_a (i,j,
lo.z) = prev_zmom(i,j,
lo.z) - stage_zmom(i,j,
lo.z)
483 + dtau * slow_rhs_rho_w(i,j,
lo.z)
484 + dtau * zmom_src_arr(i,j,
lo.z);
487 RHS_a (i,j,
hi.z+1) = prev_zmom(i,j,
hi.z+1) - stage_zmom(i,j,
hi.z+1)
488 + dtau * slow_rhs_rho_w(i,j,
hi.z+1)
489 + dtau * zmom_src_arr(i,j,
hi.z+1);
493 ParallelFor(b2d, [=] AMREX_GPU_DEVICE (
int i,
int j,
int)
496 soln_a(i,j,
lo.z) = RHS_a(i,j,
lo.z) * inv_coeffB_a(i,j,
lo.z);
497 cur_zmom(i,j,
lo.z) = stage_zmom(i,j,
lo.z) + soln_a(i,j,
lo.z);
499 for (
int k =
lo.z+1; k <=
hi.z+1; k++) {
500 soln_a(i,j,k) = (RHS_a(i,j,k)-coeffA_a(i,j,k)*soln_a(i,j,k-1)) * inv_coeffB_a(i,j,k);
503 cur_zmom(i,j,
hi.z+1) = stage_zmom(i,j,
hi.z+1) + soln_a(i,j,
hi.z+1);
505 for (
int k =
hi.z; k >=
lo.z; k--) {
506 soln_a(i,j,k) -= ( coeffC_a(i,j,k) * inv_coeffB_a(i,j,k) ) *soln_a(i,j,k+1);
507 cur_zmom(i,j,k) = stage_zmom(i,j,k) + soln_a(i,j,k);
511 for (
int j =
lo.y; j <=
hi.y; ++j) {
513 for (
int i =
lo.x; i <=
hi.x; ++i) {
514 soln_a(i,j,
lo.z) = RHS_a(i,j,
lo.z) * inv_coeffB_a(i,j,
lo.z);
517 for (
int k =
lo.z+1; k <=
hi.z+1; ++k) {
518 for (
int j =
lo.y; j <=
hi.y; ++j) {
520 for (
int i =
lo.x; i <=
hi.x; ++i) {
521 soln_a(i,j,k) = (RHS_a(i,j,k)-coeffA_a(i,j,k)*soln_a(i,j,k-1)) * inv_coeffB_a(i,j,k);
525 for (
int j =
lo.y; j <=
hi.y; ++j) {
527 for (
int i =
lo.x; i <=
hi.x; ++i) {
528 cur_zmom(i,j,
hi.z+1) = stage_zmom(i,j,
hi.z+1) + soln_a(i,j,
hi.z+1);
531 for (
int k =
hi.z; k >=
lo.z; --k) {
532 for (
int j =
lo.y; j <=
hi.y; ++j) {
534 for (
int i =
lo.x; i <=
hi.x; ++i) {
535 soln_a(i,j,k) -= ( coeffC_a(i,j,k) * inv_coeffB_a(i,j,k) ) * soln_a(i,j,k+1);
536 cur_zmom(i,j,k) = stage_zmom(i,j,k) + soln_a(i,j,k);
541 if (l_rayleigh_impl_for_w) {
542 ParallelFor(bx_shrunk_in_k, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
544 Real damping_coeff = l_damp_coef * dtau * sinesq_stag_d[k];
545 cur_zmom(i,j,k) /= (
one + damping_coeff);
552 const Array4<Real>& prev_drho_w = Delta_rho_w.array(mfi);
553 ParallelFor(bx, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept
555 Real zflux_lo = beta_2 * soln_a(i,j,k ) + beta_1 * prev_drho_w(i,j,k );
556 Real zflux_hi = beta_2 * soln_a(i,j,k+1) + beta_1 * prev_drho_w(i,j,k+1);
558 avg_zmom_arr(i,j,k) += facinv*zflux_lo / (mf_mx(i,j,0) * mf_my(i,j,0));
560 (flx_arr[2])(i,j,k,0) = zflux_lo / (mf_mx(i,j,0) * mf_my(i,j,0));
561 (flx_arr[2])(i,j,k,1) = (flx_arr[2])(i,j,k,0) *
myhalf * (prim(i,j,k) + prim(i,j,k-1));
565 avg_zmom_arr(i,j,k+1) += facinv * zflux_hi / (mf_mx(i,j,0) * mf_my(i,j,0));
567 (flx_arr[2])(i,j,k+1,0) = zflux_hi / (mf_mx(i,j,0) * mf_my(i,j,0));
568 (flx_arr[2])(i,j,k+1,1) = (flx_arr[2])(i,j,k+1,0) *
myhalf * (prim(i,j,k) + prim(i,j,k+1));
573 temp_rhs_arr(i,j,k,
Rho_comp ) += dz_inv * ( zflux_hi - zflux_lo );
574 temp_rhs_arr(i,j,k,
RhoTheta_comp) +=
myhalf * dz_inv * ( zflux_hi * (prim(i,j,k) + prim(i,j,k+1))
575 - zflux_lo * (prim(i,j,k) + prim(i,j,k-1)) );
580 int strt_comp_reflux = 0;
582 int num_comp_reflux = 1;
583 if (level < finest_level) {
584 fr_as_crse->CrseAdd(mfi,
585 {{AMREX_D_DECL(&(flux[0]), &(flux[1]), &(flux[2]))}},
586 dx, dtau, strt_comp_reflux, strt_comp_reflux, num_comp_reflux, RunOn::Device);
589 fr_as_fine->FineAdd(mfi,
590 {{AMREX_D_DECL(&(flux[0]), &(flux[1]), &(flux[2]))}},
591 dx, dtau, strt_comp_reflux, strt_comp_reflux, num_comp_reflux, RunOn::Device);
597 Gpu::streamSynchronize();
604 #pragma omp parallel if (Gpu::notInLaunchRegion())
606 for ( MFIter mfi(S_stage_data[
IntVars::cons],TilingIfNotGPU()); mfi.isValid(); ++mfi)
608 const Box& bx = mfi.tilebox();
610 const Array4< Real>& cur_cons = S_data[
IntVars::cons].array(mfi);
611 const Array4<const Real>& prev_cons = S_prev[
IntVars::cons].const_array(mfi);
612 auto const& temp_rhs_arr = temp_rhs.const_array(mfi);
613 auto const& slow_rhs_cons = S_slow_rhs[
IntVars::cons].const_array(mfi);
614 const Array4<Real const>& cc_src_arr = cc_src.const_array(mfi);
617 ParallelFor(bx, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept
629 ParallelFor(bx, [=] AMREX_GPU_DEVICE (
int i,
int j,
int k) noexcept
643 const Array4<Real>& cur_xmom = S_data[
IntVars::xmom].array(mfi);
644 const Array4<Real>& cur_ymom = S_data[
IntVars::ymom].array(mfi);
646 const Array4<Real const>& temp_cur_xmom_arr = temp_cur_xmom.const_array(mfi);
647 const Array4<Real const>& temp_cur_ymom_arr = temp_cur_ymom.const_array(mfi);
649 Box tbx = surroundingNodes(bx,0);
650 Box tby = surroundingNodes(bx,1);
653 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
655 cur_xmom(i,j,k) = temp_cur_xmom_arr(i,j,k);
657 [=] AMREX_GPU_DEVICE (
int i,
int j,
int k)
659 cur_ymom(i,j,k) = temp_cur_ymom_arr(i,j,k);
constexpr amrex::Real RvoRd
Definition: ERF_Constants.H:43
constexpr amrex::Real R_d
Definition: ERF_Constants.H:34
constexpr amrex::Real Gamma
Definition: ERF_Constants.H:54
@ v_x
Definition: ERF_DataStruct.H:29
@ u_y
Definition: ERF_DataStruct.H:30
@ v_y
Definition: ERF_DataStruct.H:30
@ m_y
Definition: ERF_DataStruct.H:30
@ u_x
Definition: ERF_DataStruct.H:29
@ m_x
Definition: ERF_DataStruct.H:29
#define PrimQ1_comp
Definition: ERF_IndexDefines.H:61
#define Rho_comp
Definition: ERF_IndexDefines.H:39
#define RhoTheta_comp
Definition: ERF_IndexDefines.H:40
#define PrimTheta_comp
Definition: ERF_IndexDefines.H:58
amrex::GpuArray< Real, AMREX_SPACEDIM > dxInv
Definition: ERF_InitCustomPertVels_ParticleTests.H:17
const int klo
Definition: ERF_InitCustomPert_ABL.H:75
const Real dx
Definition: ERF_InitCustomPert_ABL.H:44
const int khi
Definition: ERF_InitCustomPert_Bubble.H:21
AMREX_ALWAYS_ASSERT(bx.length()[2]==khi+1)
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
constexpr amrex::Real one
Definition: ERF_NumericalConstants.H:30
constexpr amrex::Real zero
Definition: ERF_NumericalConstants.H:29
constexpr amrex::Real myhalf
Definition: ERF_NumericalConstants.H:34
amrex::Real Real
Definition: ERF_ShocInterface.H:19
AMREX_FORCE_INLINE amrex::IntVect TileNoZ()
Definition: ERF_TileNoZ.H:11
@ gpy
Definition: ERF_IndexDefines.H:225
@ gpx
Definition: ERF_IndexDefines.H:224
@ ymom
Definition: ERF_IndexDefines.H:234
@ cons
Definition: ERF_IndexDefines.H:232
@ zmom
Definition: ERF_IndexDefines.H:235
@ xmom
Definition: ERF_IndexDefines.H:233
@ qt
Definition: ERF_Kessler.H:30
@ qv
Definition: ERF_Kessler.H:31
@ q
Definition: ERF_WSM6.H:273