ERF
Energy Research and Forecasting: An Atmospheric Modeling Code
ERF_ComputeStress_T.cpp File Reference
Include dependency graph for ERF_ComputeStress_T.cpp:

Functions

void ComputeStressConsVisc_T (Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau21, Array4< Real > &tau13, Array4< Real > &tau31, Array4< Real > &tau23, Array4< Real > &tau32, const Array4< const Real > &er_arr, const Array4< const Real > &z_nd, const Array4< const Real > &detJ, const GpuArray< Real, AMREX_SPACEDIM > &dxInv, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, Array4< Real > &tau13i, Array4< Real > &tau23i, const bool implicit_metric)
 
void ComputeStressVarVisc_T (Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &mu_turb, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau21, Array4< Real > &tau13, Array4< Real > &tau31, Array4< Real > &tau23, Array4< Real > &tau32, const Array4< const Real > &er_arr, const Array4< const Real > &z_nd, const Array4< const Real > &detJ, const GpuArray< Real, AMREX_SPACEDIM > &dxInv, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, Array4< Real > &tau13i, Array4< Real > &tau23i, const bool implicit_metric)
 

Function Documentation

◆ ComputeStressConsVisc_T()

void ComputeStressConsVisc_T ( Box  bxcc,
Box  tbxxy,
Box  tbxxz,
Box  tbxyz,
Real  mu_eff,
const Array4< const Real > &  cell_data,
Array4< Real > &  tau11,
Array4< Real > &  tau22,
Array4< Real > &  tau33,
Array4< Real > &  tau12,
Array4< Real > &  tau21,
Array4< Real > &  tau13,
Array4< Real > &  tau31,
Array4< Real > &  tau23,
Array4< Real > &  tau32,
const Array4< const Real > &  er_arr,
const Array4< const Real > &  z_nd,
const Array4< const Real > &  detJ,
const GpuArray< Real, AMREX_SPACEDIM > &  dxInv,
const Array4< const Real > &  mf_mx,
const Array4< const Real > &  mf_ux,
const Array4< const Real > &  mf_vx,
const Array4< const Real > &  mf_my,
const Array4< const Real > &  mf_uy,
const Array4< const Real > &  mf_vy,
Array4< Real > &  tau13i,
Array4< Real > &  tau23i,
const bool  implicit_metric 
)

Function for computing the stress with constant viscosity and with terrain.

Parameters
[in]bxcccell center box for tau_ii
[in]tbxxynodal xy box for tau_12
[in]tbxxznodal xz box for tau_13
[in]tbxyznodal yz box for tau_23
[in]mu_effconstant molecular viscosity
[in]cell_datato access rho if ConstantAlpha
[in,out]tau1111 strain -> stress
[in,out]tau2222 strain -> stress
[in,out]tau3333 strain -> stress
[in,out]tau1212 strain -> stress
[in,out]tau1313 strain -> stress
[in,out]tau2121 strain -> stress
[in,out]tau2323 strain -> stress
[in,out]tau3131 strain -> stress
[in,out]tau3232 strain -> stress
[in]er_arrexpansion rate
[in]z_ndnodal array of physical z heights
[in]detJJacobian determinant
[in]dxInvinverse cell size array
[in]mf_mxx map factor at cell centers
[in]mf_uxx map factor at x-faces
[in]mf_vxx map factor at y-faces
[in]mf_myy map factor at cell centers
[in]mf_uyy map factor at x-faces
[in]mf_vyy map factor at y-faces
[in,out]tau13icontribution to stress from du/dz
[in,out]tau23icontribution to stress from dv/dz
[in]implicit_metricerf.implicit_terrain_metric: tau13i/tau23i also hold the compact terrain-metric term on the interior faces (see ERF_TerrainImplicitMetric.H)
60 {
61  // NOTE: mu_eff includes factor of 2
62 
63  // Handle constant alpha case, in which the provided mu_eff is actually
64  // "alpha" and the viscosity needs to be scaled by rho. This can be further
65  // optimized with if statements below instead of creating a new FAB,
66  // but this is implementation is cleaner.
67  FArrayBox temp;
68  Box gbx = bxcc; // Note: bxcc have been grown in x/y only.
69  gbx.grow(IntVect(0,0,1));
70  temp.resize(gbx,1, The_Async_Arena());
71  Array4<Real> rhoAlpha = temp.array();
72 
73  if (cell_data)
74  // constant alpha (stored in mu_eff)
75  {
76  ParallelFor(gbx,
77  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
78  rhoAlpha(i,j,k) = cell_data(i, j, k, Rho_comp) * mu_eff;
79  });
80  }
81  else
82  // constant mu_eff
83  {
84  ParallelFor(gbx,
85  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
86  rhoAlpha(i,j,k) = mu_eff;
87  });
88  }
89 
90  //***********************************************************************************
91  // NOTE: The first block computes (S-D).
92  // The second block computes JT*2mu*(S-D)
93  // Boxes are copied here for extrapolations in the second block operations
94  //***********************************************************************************
95  Box bxcc2 = bxcc;
96  bxcc2.grow(IntVect(-1,-1,0));
97 
98  // First block: compute S-D
99  //***********************************************************************************
100  Real OneThird = (one/three);
101  ParallelFor(bxcc, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
102 
103  tau11(i,j,k) -= OneThird*er_arr(i,j,k);
104  tau22(i,j,k) -= OneThird*er_arr(i,j,k);
105  tau33(i,j,k) -= OneThird*er_arr(i,j,k);
106  });
107 
108  // Second block: compute JT*2mu*(S-D)
109  //***********************************************************************************
110  // Fill tau33 first (no linear combination extrapolation)
111  //-----------------------------------------------------------------------------------
112  ParallelFor(bxcc2,
113  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
114  {
115  Real mfx = mf_mx(i,j,0);
116  Real mfy = mf_my(i,j,0);
117 
118  Real met_h_xi,met_h_eta;
119  met_h_xi = Compute_h_xi_AtCellCenter (i,j,k,dxInv,z_nd);
120  met_h_eta = Compute_h_eta_AtCellCenter (i,j,k,dxInv,z_nd);
121 
122  Real tau31bar = fourth * ( tau31(i , j , k ) + tau31(i+1, j , k )
123  + tau31(i , j , k+1) + tau31(i+1, j , k+1) );
124  Real tau32bar = fourth * ( tau32(i , j , k ) + tau32(i , j+1, k )
125  + tau32(i , j , k+1) + tau32(i , j+1, k+1) );
126  Real mu_tot = rhoAlpha(i,j,k);
127 
128  tau33(i,j,k) -= met_h_xi*mfx*tau31bar + met_h_eta*mfy*tau32bar;
129  tau33(i,j,k) *= -mu_tot;
130 
131  });
132 
133  // Second block: compute JT*2mu*(S-D)
134  //***********************************************************************************
135  // Fill tau13, tau23 next (linear combination extrapolation)
136  //-----------------------------------------------------------------------------------
137  // Extrapolate tau13 & tau23 to bottom
138  {
139  Box planexz = tbxxz; planexz.setBig(2, planexz.smallEnd(2) );
140  tbxxz.growLo(2,-1);
141  Box planeyz = tbxyz; planeyz.setBig(2, planeyz.smallEnd(2) );
142  tbxyz.growLo(2,-1);
143  ParallelFor(planexz,planeyz,
144  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
145  {
146  Real mfx = mf_ux(i,j,0);
147  Real mfy = mf_uy(i,j,0);
148 
149  Real met_h_xi,met_h_eta,met_h_zeta;
150  met_h_xi = Compute_h_xi_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
151  met_h_eta = Compute_h_eta_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
152  met_h_zeta = Compute_h_zeta_AtEdgeCenterJ(i,j,k,dxInv,z_nd);
153 
154  Real tau11lo = myhalf * ( tau11(i , j , k ) + tau11(i-1, j , k ) );
155  Real tau11hi = myhalf * ( tau11(i , j , k+1) + tau11(i-1, j , k+1) );
156  Real tau11bar = Real(1.5)*tau11lo - myhalf*tau11hi;
157 
158  Real tau12lo = myhalf * ( tau12(i , j , k ) + tau12(i , j+1, k ) );
159  Real tau12hi = myhalf * ( tau12(i , j , k+1) + tau12(i , j+1, k+1) );
160  Real tau12bar = Real(1.5)*tau12lo - myhalf*tau12hi;
161 
162  Real mu_tot = fourth*( rhoAlpha(i-1, j, k ) + rhoAlpha(i, j, k )
163  + rhoAlpha(i-1, j, k-1) + rhoAlpha(i, j, k-1) );
164 
165  tau13(i,j,k) -= met_h_xi*mfx*tau11bar + met_h_eta*mfy*tau12bar;
166  tau13(i,j,k) *= -mu_tot;
167  if (tau13i) { tau13i(i,j,k) *= -mu_tot; }
168 
169  tau31(i,j,k) *= -mu_tot*met_h_zeta/mfy;
170  },
171  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
172  {
173  Real mfx = mf_vx(i,j,0);
174  Real mfy = mf_vy(i,j,0);
175 
176  Real met_h_xi,met_h_eta,met_h_zeta;
177  met_h_xi = Compute_h_xi_AtEdgeCenterI (i,j,k,dxInv,z_nd);
178  met_h_eta = Compute_h_eta_AtEdgeCenterI (i,j,k,dxInv,z_nd);
179  met_h_zeta = Compute_h_zeta_AtEdgeCenterI(i,j,k,dxInv,z_nd);
180 
181  Real tau21lo = myhalf * ( tau21(i , j , k ) + tau21(i+1, j , k ) );
182  Real tau21hi = myhalf * ( tau21(i , j , k+1) + tau21(i+1, j , k+1) );
183  Real tau21bar = Real(1.5)*tau21lo - myhalf*tau21hi;
184 
185  Real tau22lo = myhalf * ( tau22(i , j , k ) + tau22(i , j-1, k ) );
186  Real tau22hi = myhalf * ( tau22(i , j , k+1) + tau22(i , j-1, k+1) );
187  Real tau22bar = Real(1.5)*tau22lo - myhalf*tau22hi;
188 
189  Real mu_tot = fourth*( rhoAlpha(i, j-1, k ) + rhoAlpha(i, j, k )
190  + rhoAlpha(i, j-1, k-1) + rhoAlpha(i, j, k-1) );
191 
192  tau23(i,j,k) -= met_h_xi*mfx*tau21bar + met_h_eta*mfy*tau22bar;
193  tau23(i,j,k) *= -mu_tot;
194  if (tau23i) { tau23i(i,j,k) *= -mu_tot; }
195 
196  tau32(i,j,k) *= -mu_tot*met_h_zeta/mfx;
197  });
198  }
199  // Extrapolate tau13 & tau23 to top
200  {
201  Box planexz = tbxxz; planexz.setSmall(2, planexz.bigEnd(2) );
202  tbxxz.growHi(2,-1);
203  Box planeyz = tbxyz; planeyz.setSmall(2, planeyz.bigEnd(2) );
204  tbxyz.growHi(2,-1);
205  ParallelFor(planexz,planeyz,
206  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
207  {
208  Real mfx = mf_ux(i,j,0);
209  Real mfy = mf_uy(i,j,0);
210 
211  Real met_h_xi,met_h_eta,met_h_zeta;
212  met_h_xi = Compute_h_xi_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
213  met_h_eta = Compute_h_eta_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
214  met_h_zeta = Compute_h_zeta_AtEdgeCenterJ(i,j,k,dxInv,z_nd);
215 
216  Real tau11lo = myhalf * ( tau11(i , j , k-2) + tau11(i-1, j , k-2) );
217  Real tau11hi = myhalf * ( tau11(i , j , k-1) + tau11(i-1, j , k-1) );
218  Real tau11bar = Real(1.5)*tau11hi - myhalf*tau11lo;
219 
220  Real tau12lo = myhalf * ( tau12(i , j , k-2) + tau12(i , j+1, k-2) );
221  Real tau12hi = myhalf * ( tau12(i , j , k-1) + tau12(i , j+1, k-1) );
222  Real tau12bar = Real(1.5)*tau12hi - myhalf*tau12lo;
223 
224  Real mu_tot = fourth*( rhoAlpha(i-1, j, k ) + rhoAlpha(i, j, k )
225  + rhoAlpha(i-1, j, k-1) + rhoAlpha(i, j, k-1) );
226 
227  tau13(i,j,k) -= met_h_xi*mfx*tau11bar + met_h_eta*mfy*tau12bar;
228  tau13(i,j,k) *= -mu_tot;
229  if (tau13i) { tau13i(i,j,k) *= -mu_tot; }
230 
231  tau31(i,j,k) *= -mu_tot*met_h_zeta/mfy;
232  },
233  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
234  {
235  Real mfx = mf_vx(i,j,0);
236  Real mfy = mf_vy(i,j,0);
237 
238  Real met_h_xi,met_h_eta,met_h_zeta;
239  met_h_xi = Compute_h_xi_AtEdgeCenterI (i,j,k,dxInv,z_nd);
240  met_h_eta = Compute_h_eta_AtEdgeCenterI (i,j,k,dxInv,z_nd);
241  met_h_zeta = Compute_h_zeta_AtEdgeCenterI(i,j,k,dxInv,z_nd);
242 
243  Real tau21lo = myhalf * ( tau21(i , j , k-2) + tau21(i+1, j , k-2) );
244  Real tau21hi = myhalf * ( tau21(i , j , k-1) + tau21(i+1, j , k-1) );
245  Real tau21bar = Real(1.5)*tau21hi - myhalf*tau21lo;
246 
247  Real tau22lo = myhalf * ( tau22(i , j , k-2) + tau22(i , j-1, k-2) );
248  Real tau22hi = myhalf * ( tau22(i , j , k-1) + tau22(i , j-1, k-1) );
249  Real tau22bar = Real(1.5)*tau22hi - myhalf*tau22lo;
250 
251  Real mu_tot = fourth*( rhoAlpha(i, j-1, k ) + rhoAlpha(i, j, k )
252  + rhoAlpha(i, j-1, k-1) + rhoAlpha(i, j, k-1) );
253 
254  tau23(i,j,k) -= met_h_xi*mfx*tau21bar + met_h_eta*mfy*tau22bar;
255  tau23(i,j,k) *= -mu_tot;
256  if (tau23i) { tau23i(i,j,k) *= -mu_tot; }
257 
258  tau32(i,j,k) *= -mu_tot*met_h_zeta/mfx;
259  });
260  }
261 
262  // Second block: compute JT*2mu*(S-D)
263  //***********************************************************************************
264  // Fill tau13, tau23 next (valid averaging region)
265  //-----------------------------------------------------------------------------------
266  ParallelFor(tbxxz,tbxyz,
267  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
268  {
269  Real mfx = mf_ux(i,j,0);
270  Real mfy = mf_uy(i,j,0);
271 
272  Real met_h_xi,met_h_eta,met_h_zeta;
273  met_h_xi = Compute_h_xi_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
274  met_h_eta = Compute_h_eta_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
275  met_h_zeta = Compute_h_zeta_AtEdgeCenterJ(i,j,k,dxInv,z_nd);
276 
277  Real tau11bar = fourth * ( tau11(i , j , k ) + tau11(i-1, j , k )
278  + tau11(i , j , k-1) + tau11(i-1, j , k-1) );
279  Real tau12bar = fourth * ( tau12(i , j , k ) + tau12(i , j+1, k )
280  + tau12(i , j , k-1) + tau12(i , j+1, k-1) );
281  Real mu_tot = fourth * ( rhoAlpha(i-1, j , k ) + rhoAlpha(i , j , k )
282  + rhoAlpha(i-1, j , k-1) + rhoAlpha(i , j , k-1) );
283 
284  tau13(i,j,k) -= met_h_xi*mfx*tau11bar + met_h_eta*mfy*tau12bar;
285  tau13(i,j,k) *= -mu_tot;
286  if (tau13i) {
287  // erf.implicit_terrain_metric: the implicit solve also takes the compact
288  // K_h*M*d/dz metric term on these interior faces, so tau13i holds it too
289  const Real metric = (implicit_metric) ?
290  TerrainMetricMomFactor(0, met_h_xi, met_h_eta, mfx, mfy) : zero;
291  tau13i(i,j,k) *= -(mu_tot + mu_tot*metric);
292  }
293 
294  tau31(i,j,k) *= -mu_tot*met_h_zeta/mfy;
295  },
296  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
297  {
298  Real mfx = mf_vx(i,j,0);
299  Real mfy = mf_vy(i,j,0);
300 
301  Real met_h_xi,met_h_eta,met_h_zeta;
302  met_h_xi = Compute_h_xi_AtEdgeCenterI (i,j,k,dxInv,z_nd);
303  met_h_eta = Compute_h_eta_AtEdgeCenterI (i,j,k,dxInv,z_nd);
304  met_h_zeta = Compute_h_zeta_AtEdgeCenterI(i,j,k,dxInv,z_nd);
305 
306  Real tau21bar = fourth * ( tau21(i , j , k ) + tau21(i+1, j , k )
307  + tau21(i , j , k-1) + tau21(i+1, j , k-1) );
308  Real tau22bar = fourth * ( tau22(i , j , k ) + tau22(i , j-1, k )
309  + tau22(i , j , k-1) + tau22(i , j-1, k-1) );
310  Real mu_tot = fourth * ( rhoAlpha(i , j-1, k ) + rhoAlpha(i , j , k )
311  + rhoAlpha(i , j-1, k-1) + rhoAlpha(i , j , k-1) );
312 
313  tau23(i,j,k) -= met_h_xi*mfx*tau21bar + met_h_eta*mfy*tau22bar;
314  tau23(i,j,k) *= -mu_tot;
315  if (tau23i) {
316  // erf.implicit_terrain_metric: the implicit solve also takes the compact
317  // K_h*M*d/dz metric term on these interior faces, so tau23i holds it too
318  const Real metric = (implicit_metric) ?
319  TerrainMetricMomFactor(1, met_h_xi, met_h_eta, mfx, mfy) : zero;
320  tau23i(i,j,k) *= -(mu_tot + mu_tot*metric);
321  }
322 
323  tau32(i,j,k) *= -mu_tot*met_h_zeta/mfx;
324  });
325 
326  // Fill the remaining components: tau11, tau22, tau12/21
327  //-----------------------------------------------------------------------------------
328  ParallelFor(bxcc,tbxxy,
329  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
330  {
331  Real mfx = mf_mx(i,j,0);
332  Real mfy = mf_my(i,j,0);
333 
334  Real met_h_zeta = detJ(i,j,k);
335  Real mu_tot = rhoAlpha(i,j,k);
336 
337  tau11(i,j,k) *= -mu_tot*met_h_zeta/mfy;
338  tau22(i,j,k) *= -mu_tot*met_h_zeta/mfx;
339  },
340  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
341  {
342  Real mfx = myhalf * (mf_ux(i,j,0) + mf_ux(i,j-1,0));
343  Real mfy = myhalf * (mf_vy(i,j,0) + mf_vy(i-1,j,0));
344 
345  Real met_h_zeta = Compute_h_zeta_AtEdgeCenterK(i,j,k,dxInv,z_nd);
346 
347  Real mu_tot = fourth*( rhoAlpha(i-1, j , k) + rhoAlpha(i, j , k)
348  + rhoAlpha(i-1, j-1, k) + rhoAlpha(i, j-1, k) );
349 
350  tau12(i,j,k) *= -mu_tot*met_h_zeta/mfx;
351  tau21(i,j,k) *= -mu_tot*met_h_zeta/mfy;
352  });
353 }
@ tau12
Definition: ERF_DataStruct.H:49
@ tau23
Definition: ERF_DataStruct.H:49
@ tau33
Definition: ERF_DataStruct.H:49
@ tau22
Definition: ERF_DataStruct.H:49
@ tau11
Definition: ERF_DataStruct.H:49
@ tau32
Definition: ERF_DataStruct.H:49
@ tau31
Definition: ERF_DataStruct.H:49
@ tau21
Definition: ERF_DataStruct.H:49
@ tau13
Definition: ERF_DataStruct.H:49
#define Rho_comp
Definition: ERF_IndexDefines.H:53
amrex::GpuArray< Real, AMREX_SPACEDIM > dxInv
Definition: ERF_InitCustomPertVels_ParticleTests.H:17
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
constexpr amrex::Real three
Definition: ERF_NumericalConstants.H:39
constexpr amrex::Real one
Definition: ERF_NumericalConstants.H:37
constexpr amrex::Real fourth
Definition: ERF_NumericalConstants.H:42
constexpr amrex::Real zero
Definition: ERF_NumericalConstants.H:36
constexpr amrex::Real myhalf
Definition: ERF_NumericalConstants.H:41
amrex::Real Real
Definition: ERF_ShocInterface.H:19
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE amrex::Real TerrainMetricMomFactor(const int stagdir, const amrex::Real h_xi, const amrex::Real h_eta, const amrex::Real mx, const amrex::Real my) noexcept
Definition: ERF_TerrainImplicitMetric.H:39
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_eta_AtEdgeCenterJ(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:620
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_xi_AtEdgeCenterJ(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:595
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_zeta_AtEdgeCenterJ(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:571
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_zeta_AtEdgeCenterK(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:496
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_zeta_AtEdgeCenterI(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:645
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_xi_AtCellCenter(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:226
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_eta_AtCellCenter(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:251
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_xi_AtEdgeCenterI(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:669
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_eta_AtEdgeCenterI(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:692

Referenced by erf_make_tau_terms().

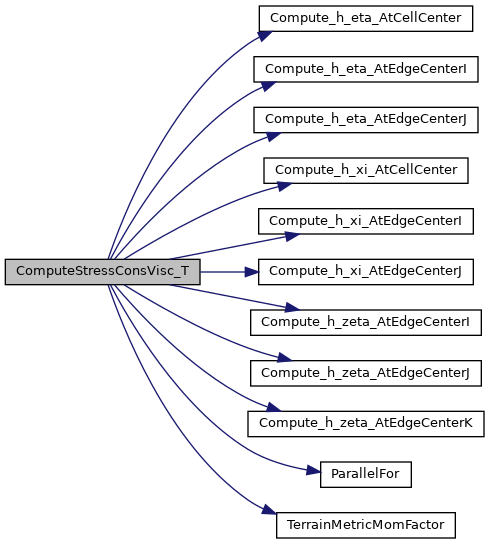
Here is the call graph for this function:
Here is the caller graph for this function:

◆ ComputeStressVarVisc_T()

void ComputeStressVarVisc_T ( Box  bxcc,
Box  tbxxy,
Box  tbxxz,
Box  tbxyz,
Real  mu_eff,
const Array4< const Real > &  mu_turb,
const Array4< const Real > &  cell_data,
Array4< Real > &  tau11,
Array4< Real > &  tau22,
Array4< Real > &  tau33,
Array4< Real > &  tau12,
Array4< Real > &  tau21,
Array4< Real > &  tau13,
Array4< Real > &  tau31,
Array4< Real > &  tau23,
Array4< Real > &  tau32,
const Array4< const Real > &  er_arr,
const Array4< const Real > &  z_nd,
const Array4< const Real > &  detJ,
const GpuArray< Real, AMREX_SPACEDIM > &  dxInv,
const Array4< const Real > &  mf_mx,
const Array4< const Real > &  mf_ux,
const Array4< const Real > &  mf_vx,
const Array4< const Real > &  mf_my,
const Array4< const Real > &  mf_uy,
const Array4< const Real > &  mf_vy,
Array4< Real > &  tau13i,
Array4< Real > &  tau23i,
const bool  implicit_metric 
)

Function for computing the stress with constant viscosity and with terrain.

Parameters
[in]bxcccell center box for tau_ii
[in]tbxxynodal xy box for tau_12
[in]tbxxznodal xz box for tau_13
[in]tbxyznodal yz box for tau_23
[in]mu_effconstant molecular viscosity
[in]mu_turbvariable turbulent viscosity
[in]cell_datato access rho if ConstantAlpha
[in,out]tau1111 strain -> stress
[in,out]tau2222 strain -> stress
[in,out]tau3333 strain -> stress
[in,out]tau1212 strain -> stress
[in,out]tau1313 strain -> stress
[in,out]tau2121 strain -> stress
[in,out]tau2323 strain -> stress
[in,out]tau3131 strain -> stress
[in,out]tau3232 strain -> stress
[in]er_arrexpansion rate
[in]z_ndnodal array of physical z heights
[in]detJJacobian determinant
[in]dxInvinverse cell size array
[in]mf_mxx map factor at cell centers
[in]mf_uxx map factor at x-faces
[in]mf_vxx map factor at y-faces
[in]mf_myy map factor at cell centers
[in]mf_uyy map factor at x-faces
[in]mf_vyy map factor at y-faces
[in,out]tau13icontribution to stress from du/dz
[in,out]tau23icontribution to stress from dv/dz
[in]implicit_metricerf.implicit_terrain_metric: tau13i/tau23i also hold the compact terrain-metric term on the interior faces (see ERF_TerrainImplicitMetric.H)

NOTE: The zeta-face stresses tau13/tau23 are the terrain-normal combination tau_i3 - h_xi*tau_i1 - h_eta*tau_i2. tau_i3 is a vertical stress and takes K_v (EddyDiff::Mom_v); tau_i1 and tau_i2 are horizontal stresses and take K_h (EddyDiff::Mom_h), as the h*Fx terms of the scalar fluxes do. Applying K_v to the projected terms makes the operator non-symmetric and, when K_h*h^2 > 2*K_v, anti-diffusive. The projected stresses K_h*S are formed at the cells and xy edges and averaged to the zeta edges. On a uniform slope with uniform dz this is the transpose of the metric term in S11/S22, so the strain part of the operator dissipates energy for any K_h and K_v (an edge-averaged K_h times averaged strains does not, where K_h varies from cell to cell). tau13i/tau23i (the part the implicit solve takes) are pure K_v terms.

422 {
423  // NOTE: mu_eff includes factor of 2
424 
425  // Handle constant alpha case, in which the provided mu_eff is actually
426  // "alpha" and the viscosity needs to be scaled by rho. This can be further
427  // optimized with if statements below instead of creating a new FAB,
428  // but this is implementation is cleaner.
429  FArrayBox temp;
430  Box gbx = bxcc; // Note: bxcc have been grown in x/y only.
431  gbx.grow(IntVect(0,0,1));
432  temp.resize(gbx,1, The_Async_Arena());
433  Array4<Real> rhoAlpha = temp.array();
434 
435  if (cell_data)
436  // constant alpha (stored in mu_eff)
437  {
438  ParallelFor(gbx,
439  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
440  rhoAlpha(i,j,k) = cell_data(i, j, k, Rho_comp) * mu_eff;
441  });
442  }
443  else
444  // constant mu_eff
445  {
446  ParallelFor(gbx,
447  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
448  rhoAlpha(i,j,k) = mu_eff;
449  });
450  }
451 
452  //***********************************************************************************
453  // NOTE: The first block computes (S-D).
454  // The second block computes JT*2K*(S-D)
455  // Boxes are copied here for extrapolations in the second block operations
456  //***********************************************************************************
457  Box bxcc2 = bxcc;
458  bxcc2.grow(IntVect(-1,-1,0));
459 
460  // First block: compute S-D
461  //***********************************************************************************
462  Real OneThird = (one/three);
463  ParallelFor(bxcc, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
464 
465  tau11(i,j,k) -= OneThird*er_arr(i,j,k);
466  tau22(i,j,k) -= OneThird*er_arr(i,j,k);
467  tau33(i,j,k) -= OneThird*er_arr(i,j,k);
468  });
469 
470  // Second block: compute JT*2K*(S-D)
471  //***********************************************************************************
472  // Fill tau33 first (no linear combination extrapolation)
473  //-----------------------------------------------------------------------------------
474  ParallelFor(bxcc2,
475  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
476  {
477  Real mfx = mf_mx(i,j,0);
478  Real mfy = mf_my(i,j,0);
479 
480  Real met_h_xi,met_h_eta;
481  met_h_xi = Compute_h_xi_AtCellCenter (i,j,k,dxInv,z_nd);
482  met_h_eta = Compute_h_eta_AtCellCenter (i,j,k,dxInv,z_nd);
483 
484  Real tau31bar = fourth * ( tau31(i , j , k ) + tau31(i+1, j , k )
485  + tau31(i , j , k+1) + tau31(i+1, j , k+1) );
486  Real tau32bar = fourth * ( tau32(i , j , k ) + tau32(i , j+1, k )
487  + tau32(i , j , k+1) + tau32(i , j+1, k+1) );
488 
489  Real mu_tot = rhoAlpha(i,j,k) + two*mu_turb(i, j, k, EddyDiff::Mom_v);
490 
491  tau33(i,j,k) -= met_h_xi*mfx*tau31bar + met_h_eta*mfy*tau32bar;
492  tau33(i,j,k) *= -mu_tot;
493 
494  });
495 
496  // The zeta-face stresses project the horizontal stresses K_h*S11, K_h*S12, K_h*S21 and
497  // K_h*S22 (see the NOTE above). Form them where they live -- at the cells and the xy
498  // edges, with the coefficients the tau11/tau22/tau12 kernels below apply -- and average
499  // the stresses to the zeta edges, as the scalar fluxes average K_h*grad. On a uniform
500  // slope with uniform dz that is the transpose of the metric term in S11/S22, which keeps
501  // the strain part of the operator dissipative for any K_h and K_v (see the NOTE above).
502  //-----------------------------------------------------------------------------------
503  // kh12 is read at (i,j+1) over tbxxz and kh21 at (i+1,j) over tbxyz. On a tile that is not
504  // the last in x or y the nodal tile box tbxxy stops one node short of those reads, so form
505  // them on the nodes the reads need; the strains are valid there (they are computed on the
506  // halo-grown boxes).
507  Box khxy = tbxxy;
508  khxy.setSmall(0, amrex::min(tbxxz.smallEnd(0), tbxyz.smallEnd(0)));
509  khxy.setSmall(1, amrex::min(tbxxz.smallEnd(1), tbxyz.smallEnd(1)));
510  khxy.setBig (0, amrex::max(tbxxz.bigEnd(0) , tbxyz.bigEnd(0)+1));
511  khxy.setBig (1, amrex::max(tbxxz.bigEnd(1)+1, tbxyz.bigEnd(1) ));
512  FArrayBox kh11_fab(bxcc,1,The_Async_Arena()), kh22_fab(bxcc,1,The_Async_Arena());
513  FArrayBox kh12_fab(khxy,1,The_Async_Arena()), kh21_fab(khxy,1,The_Async_Arena());
514  const Array4<Real> kh11 = kh11_fab.array();
515  const Array4<Real> kh22 = kh22_fab.array();
516  const Array4<Real> kh12 = kh12_fab.array();
517  const Array4<Real> kh21 = kh21_fab.array();
518  ParallelFor(bxcc, khxy,
519  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
520  {
521  Real mu_h_tot = rhoAlpha(i,j,k) + two*mu_turb(i, j, k, EddyDiff::Mom_h);
522  kh11(i,j,k) = mu_h_tot*tau11(i,j,k);
523  kh22(i,j,k) = mu_h_tot*tau22(i,j,k);
524  },
525  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
526  {
527  Real mu_bar = fourth * ( mu_turb(i-1, j , k, EddyDiff::Mom_h) + mu_turb(i, j , k, EddyDiff::Mom_h)
528  + mu_turb(i-1, j-1, k, EddyDiff::Mom_h) + mu_turb(i, j-1, k, EddyDiff::Mom_h) );
529  Real rhoAlpha_bar = fourth * ( rhoAlpha(i-1, j , k) + rhoAlpha(i, j , k)
530  + rhoAlpha(i-1, j-1, k) + rhoAlpha(i, j-1, k) );
531  Real mu_h_tot = rhoAlpha_bar + two*mu_bar;
532  kh12(i,j,k) = mu_h_tot*tau12(i,j,k);
533  kh21(i,j,k) = mu_h_tot*tau21(i,j,k);
534  });
535 
536  // Second block: compute JT*2K*(S-D)
537  //***********************************************************************************
538  // Fill tau13, tau23 next (linear combination extrapolation)
539  //-----------------------------------------------------------------------------------
540  // Extrapolate tau13 & tau23 to bottom
541  {
542  Box planexz = tbxxz; planexz.setBig(2, planexz.smallEnd(2) );
543  tbxxz.growLo(2,-1);
544  Box planeyz = tbxyz; planeyz.setBig(2, planeyz.smallEnd(2) );
545  tbxyz.growLo(2,-1);
546  ParallelFor(planexz,planeyz,
547  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
548  {
549  Real mfx = mf_ux(i,j,0);
550  Real mfy = mf_uy(i,j,0);
551 
552  Real met_h_xi,met_h_eta,met_h_zeta;
553  met_h_xi = Compute_h_xi_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
554  met_h_eta = Compute_h_eta_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
555  met_h_zeta = Compute_h_zeta_AtEdgeCenterJ(i,j,k,dxInv,z_nd);
556 
557  Real tau11lo = myhalf * ( kh11(i , j , k ) + kh11(i-1, j , k ) );
558  Real tau11hi = myhalf * ( kh11(i , j , k+1) + kh11(i-1, j , k+1) );
559  Real tau11bar = Real(1.5)*tau11lo - myhalf*tau11hi;
560 
561  Real tau12lo = myhalf * ( kh12(i , j , k ) + kh12(i , j+1, k ) );
562  Real tau12hi = myhalf * ( kh12(i , j , k+1) + kh12(i , j+1, k+1) );
563  Real tau12bar = Real(1.5)*tau12lo - myhalf*tau12hi;
564 
565  Real mu_bar = fourth * ( mu_turb(i-1, j, k , EddyDiff::Mom_v) + mu_turb(i, j, k , EddyDiff::Mom_v)
566  + mu_turb(i-1, j, k-1, EddyDiff::Mom_v) + mu_turb(i, j, k-1, EddyDiff::Mom_v) );
567  Real rhoAlpha_bar = fourth * ( rhoAlpha(i-1, j, k ) + rhoAlpha(i, j, k )
568  + rhoAlpha(i-1, j, k-1) + rhoAlpha(i, j, k-1) );
569  Real mu_tot = rhoAlpha_bar + two*mu_bar;
570 
571  // K_v on S13; the projected horizontal stresses carry K_h (see the NOTE above)
572  tau13(i,j,k) *= -mu_tot;
573  tau13(i,j,k) += met_h_xi*mfx*tau11bar + met_h_eta*mfy*tau12bar;
574  if (tau13i) { tau13i(i,j,k) *= -mu_tot; }
575 
576  tau31(i,j,k) *= -mu_tot*met_h_zeta/mfy;
577  },
578  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
579  {
580  Real mfx = mf_vx(i,j,0);
581  Real mfy = mf_vy(i,j,0);
582 
583  Real met_h_xi,met_h_eta,met_h_zeta;
584  met_h_xi = Compute_h_xi_AtEdgeCenterI (i,j,k,dxInv,z_nd);
585  met_h_eta = Compute_h_eta_AtEdgeCenterI (i,j,k,dxInv,z_nd);
586  met_h_zeta = Compute_h_zeta_AtEdgeCenterI(i,j,k,dxInv,z_nd);
587 
588  Real tau21lo = myhalf * ( kh21(i , j , k ) + kh21(i+1, j , k ) );
589  Real tau21hi = myhalf * ( kh21(i , j , k+1) + kh21(i+1, j , k+1) );
590  Real tau21bar = Real(1.5)*tau21lo - myhalf*tau21hi;
591 
592  Real tau22lo = myhalf * ( kh22(i , j , k ) + kh22(i , j-1, k ) );
593  Real tau22hi = myhalf * ( kh22(i , j , k+1) + kh22(i , j-1, k+1) );
594  Real tau22bar = Real(1.5)*tau22lo - myhalf*tau22hi;
595 
596  Real mu_bar = fourth * ( mu_turb(i, j-1, k , EddyDiff::Mom_v) + mu_turb(i, j, k , EddyDiff::Mom_v)
597  + mu_turb(i, j-1, k-1, EddyDiff::Mom_v) + mu_turb(i, j, k-1, EddyDiff::Mom_v) );
598  Real rhoAlpha_bar = fourth * ( rhoAlpha(i, j-1, k ) + rhoAlpha(i, j, k )
599  + rhoAlpha(i, j-1, k-1) + rhoAlpha(i, j, k-1) );
600  Real mu_tot = rhoAlpha_bar + two*mu_bar;
601 
602  // K_v on S23; the projected horizontal stresses carry K_h (see the NOTE above)
603  tau23(i,j,k) *= -mu_tot;
604  tau23(i,j,k) += met_h_xi*mfx*tau21bar + met_h_eta*mfy*tau22bar;
605  if (tau23i) { tau23i(i,j,k) *= -mu_tot; }
606 
607  tau32(i,j,k) *= -mu_tot*met_h_zeta/mfx;
608  });
609  }
610  // Extrapolate tau13 & tau23 to top
611  {
612  Box planexz = tbxxz; planexz.setSmall(2, planexz.bigEnd(2) );
613  tbxxz.growHi(2,-1);
614  Box planeyz = tbxyz; planeyz.setSmall(2, planeyz.bigEnd(2) );
615  tbxyz.growHi(2,-1);
616  ParallelFor(planexz,planeyz,
617  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
618  {
619  Real mfx = mf_ux(i,j,0);
620  Real mfy = mf_uy(i,j,0);
621 
622  Real met_h_xi,met_h_eta,met_h_zeta;
623  met_h_xi = Compute_h_xi_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
624  met_h_eta = Compute_h_eta_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
625  met_h_zeta = Compute_h_zeta_AtEdgeCenterJ(i,j,k,dxInv,z_nd);
626 
627  Real tau11lo = myhalf * ( kh11(i , j , k-2) + kh11(i-1, j , k-2) );
628  Real tau11hi = myhalf * ( kh11(i , j , k-1) + kh11(i-1, j , k-1) );
629  Real tau11bar = Real(1.5)*tau11hi - myhalf*tau11lo;
630 
631  Real tau12lo = myhalf * ( kh12(i , j , k-2) + kh12(i , j+1, k-2) );
632  Real tau12hi = myhalf * ( kh12(i , j , k-1) + kh12(i , j+1, k-1) );
633  Real tau12bar = Real(1.5)*tau12hi - myhalf*tau12lo;
634 
635  Real mu_bar = fourth * ( mu_turb(i-1, j, k , EddyDiff::Mom_v) + mu_turb(i, j, k , EddyDiff::Mom_v)
636  + mu_turb(i-1, j, k-1, EddyDiff::Mom_v) + mu_turb(i, j, k-1, EddyDiff::Mom_v) );
637  Real rhoAlpha_bar = fourth * ( rhoAlpha(i-1, j, k ) + rhoAlpha(i, j, k )
638  + rhoAlpha(i-1, j, k-1) + rhoAlpha(i, j, k-1) );
639  Real mu_tot = rhoAlpha_bar + two*mu_bar;
640 
641  // K_v on S13; the projected horizontal stresses carry K_h (see the NOTE above)
642  tau13(i,j,k) *= -mu_tot;
643  tau13(i,j,k) += met_h_xi*mfx*tau11bar + met_h_eta*mfy*tau12bar;
644  if (tau13i) { tau13i(i,j,k) *= -mu_tot; }
645 
646  tau31(i,j,k) *= -mu_tot*met_h_zeta/mfy;
647  },
648  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
649  {
650  Real mfx = mf_vx(i,j,0);
651  Real mfy = mf_vy(i,j,0);
652 
653  Real met_h_xi,met_h_eta,met_h_zeta;
654  met_h_xi = Compute_h_xi_AtEdgeCenterI (i,j,k,dxInv,z_nd);
655  met_h_eta = Compute_h_eta_AtEdgeCenterI (i,j,k,dxInv,z_nd);
656  met_h_zeta = Compute_h_zeta_AtEdgeCenterI(i,j,k,dxInv,z_nd);
657 
658  Real tau21lo = myhalf * ( kh21(i , j , k-2) + kh21(i+1, j , k-2) );
659  Real tau21hi = myhalf * ( kh21(i , j , k-1) + kh21(i+1, j , k-1) );
660  Real tau21bar = Real(1.5)*tau21hi - myhalf*tau21lo;
661 
662  Real tau22lo = myhalf * ( kh22(i , j , k-2) + kh22(i , j-1, k-2) );
663  Real tau22hi = myhalf * ( kh22(i , j , k-1) + kh22(i , j-1, k-1) );
664  Real tau22bar = Real(1.5)*tau22hi - myhalf*tau22lo;
665 
666  Real mu_bar = fourth * ( mu_turb(i, j-1, k , EddyDiff::Mom_v) + mu_turb(i, j, k , EddyDiff::Mom_v)
667  + mu_turb(i, j-1, k-1, EddyDiff::Mom_v) + mu_turb(i, j, k-1, EddyDiff::Mom_v) );
668  Real rhoAlpha_bar = fourth * ( rhoAlpha(i, j-1, k ) + rhoAlpha(i, j, k )
669  + rhoAlpha(i, j-1, k-1) + rhoAlpha(i, j, k-1) );
670  Real mu_tot = rhoAlpha_bar + two*mu_bar;
671 
672  // K_v on S23; the projected horizontal stresses carry K_h (see the NOTE above)
673  tau23(i,j,k) *= -mu_tot;
674  tau23(i,j,k) += met_h_xi*mfx*tau21bar + met_h_eta*mfy*tau22bar;
675  if (tau23i) { tau23i(i,j,k) *= -mu_tot; }
676 
677  tau32(i,j,k) *= -mu_tot*met_h_zeta/mfx;
678  });
679  }
680 
681  // Second block: compute JT*2K*(S-D)
682  //***********************************************************************************
683  // Fill tau13, tau23 next (valid averaging region)
684  //-----------------------------------------------------------------------------------
685  ParallelFor(tbxxz,tbxyz,
686  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
687  {
688  Real mfx = mf_ux(i,j,0);
689  Real mfy = mf_uy(i,j,0);
690 
691  Real met_h_xi,met_h_eta,met_h_zeta;
692  met_h_xi = Compute_h_xi_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
693  met_h_eta = Compute_h_eta_AtEdgeCenterJ (i,j,k,dxInv,z_nd);
694  met_h_zeta = Compute_h_zeta_AtEdgeCenterJ(i,j,k,dxInv,z_nd);
695 
696  Real tau11bar = fourth * ( kh11(i , j , k ) + kh11(i-1, j , k )
697  + kh11(i , j , k-1) + kh11(i-1, j , k-1) );
698  Real tau12bar = fourth * ( kh12(i , j , k ) + kh12(i , j+1, k )
699  + kh12(i , j , k-1) + kh12(i , j+1, k-1) );
700 
701  Real mu_bar = fourth * ( mu_turb(i-1, j , k , EddyDiff::Mom_v) + mu_turb(i , j , k , EddyDiff::Mom_v)
702  + mu_turb(i-1, j , k-1, EddyDiff::Mom_v) + mu_turb(i , j , k-1, EddyDiff::Mom_v) );
703  Real rhoAlpha_bar = fourth * ( rhoAlpha(i-1, j , k ) + rhoAlpha(i , j , k )
704  + rhoAlpha(i-1, j , k-1) + rhoAlpha(i , j , k-1) );
705  Real mu_tot = rhoAlpha_bar + two*mu_bar;
706 
707  // K_v on S13; the projected horizontal stresses carry K_h (see the NOTE above)
708  tau13(i,j,k) *= -mu_tot;
709  tau13(i,j,k) += met_h_xi*mfx*tau11bar + met_h_eta*mfy*tau12bar;
710  if (tau13i) {
711  // erf.implicit_terrain_metric: the implicit solve also takes the compact
712  // K_h*M*d/dz metric term on these interior faces, with K_h averaged to the edge
713  // as getRhoAlphaForFaces averages it there, so tau13i holds it too
714  Real metric_coef = zero;
715  if (implicit_metric) {
716  Real mu_h_bar = fourth * ( mu_turb(i-1, j , k , EddyDiff::Mom_h) + mu_turb(i , j , k , EddyDiff::Mom_h)
717  + mu_turb(i-1, j , k-1, EddyDiff::Mom_h) + mu_turb(i , j , k-1, EddyDiff::Mom_h) );
718  metric_coef = (rhoAlpha_bar + two*mu_h_bar)
719  * TerrainMetricMomFactor(0, met_h_xi, met_h_eta, mfx, mfy);
720  }
721  tau13i(i,j,k) *= -(mu_tot + metric_coef);
722  }
723 
724  tau31(i,j,k) *= -mu_tot*met_h_zeta/mfy;
725  },
726  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
727  {
728  Real mfx = mf_vx(i,j,0);
729  Real mfy = mf_vy(i,j,0);
730 
731  Real met_h_xi,met_h_eta,met_h_zeta;
732  met_h_xi = Compute_h_xi_AtEdgeCenterI (i,j,k,dxInv,z_nd);
733  met_h_eta = Compute_h_eta_AtEdgeCenterI (i,j,k,dxInv,z_nd);
734  met_h_zeta = Compute_h_zeta_AtEdgeCenterI(i,j,k,dxInv,z_nd);
735 
736  Real tau21bar = fourth * ( kh21(i , j , k ) + kh21(i+1, j , k )
737  + kh21(i , j , k-1) + kh21(i+1, j , k-1) );
738  Real tau22bar = fourth * ( kh22(i , j , k ) + kh22(i , j-1, k )
739  + kh22(i , j , k-1) + kh22(i , j-1, k-1) );
740 
741  Real mu_bar = fourth * ( mu_turb(i , j-1, k , EddyDiff::Mom_v) + mu_turb(i , j , k , EddyDiff::Mom_v)
742  + mu_turb(i , j-1, k-1, EddyDiff::Mom_v) + mu_turb(i , j , k-1, EddyDiff::Mom_v) );
743  Real rhoAlpha_bar = fourth * ( rhoAlpha(i , j-1, k ) + rhoAlpha(i , j , k )
744  + rhoAlpha(i , j-1, k-1) + rhoAlpha(i , j , k-1) );
745  Real mu_tot = rhoAlpha_bar + two*mu_bar;
746 
747  // K_v on S23; the projected horizontal stresses carry K_h (see the NOTE above)
748  tau23(i,j,k) *= -mu_tot;
749  tau23(i,j,k) += met_h_xi*mfx*tau21bar + met_h_eta*mfy*tau22bar;
750  if (tau23i) {
751  // erf.implicit_terrain_metric: the implicit solve also takes the compact
752  // K_h*M*d/dz metric term on these interior faces, with K_h averaged to the edge
753  // as getRhoAlphaForFaces averages it there, so tau23i holds it too
754  Real metric_coef = zero;
755  if (implicit_metric) {
756  Real mu_h_bar = fourth * ( mu_turb(i , j-1, k , EddyDiff::Mom_h) + mu_turb(i , j , k , EddyDiff::Mom_h)
757  + mu_turb(i , j-1, k-1, EddyDiff::Mom_h) + mu_turb(i , j , k-1, EddyDiff::Mom_h) );
758  metric_coef = (rhoAlpha_bar + two*mu_h_bar)
759  * TerrainMetricMomFactor(1, met_h_xi, met_h_eta, mfx, mfy);
760  }
761  tau23i(i,j,k) *= -(mu_tot + metric_coef);
762  }
763 
764  tau32(i,j,k) *= -mu_tot*met_h_zeta/mfx;
765  });
766 
767  // Fill the remaining components: tau11, tau22, tau12/21
768  //-----------------------------------------------------------------------------------
769  ParallelFor(bxcc,tbxxy,
770  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
771  {
772  Real mfx = mf_mx(i,j,0);
773  Real mfy = mf_my(i,j,0);
774 
775  Real met_h_zeta = detJ(i,j,k);
776 
777  Real mu_tot = rhoAlpha(i,j,k) + two*mu_turb(i, j, k, EddyDiff::Mom_h);
778 
779  tau11(i,j,k) *= -mu_tot*met_h_zeta/mfy;
780  tau22(i,j,k) *= -mu_tot*met_h_zeta/mfx;
781  },
782  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
783  {
784  Real mfx = myhalf * (mf_ux(i,j,0) + mf_ux(i,j-1,0));
785  Real mfy = myhalf * (mf_vy(i,j,0) + mf_vy(i-1,j,0));
786 
787  Real met_h_zeta = Compute_h_zeta_AtEdgeCenterK(i,j,k,dxInv,z_nd);
788 
789  Real mu_bar = fourth * ( mu_turb(i-1, j , k, EddyDiff::Mom_h) + mu_turb(i, j , k, EddyDiff::Mom_h)
790  + mu_turb(i-1, j-1, k, EddyDiff::Mom_h) + mu_turb(i, j-1, k, EddyDiff::Mom_h) );
791  Real rhoAlpha_bar = fourth * ( rhoAlpha(i-1, j , k) + rhoAlpha(i, j , k)
792  + rhoAlpha(i-1, j-1, k) + rhoAlpha(i, j-1, k) );
793  Real mu_tot = rhoAlpha_bar + two*mu_bar;
794 
795  tau12(i,j,k) *= -mu_tot*met_h_zeta/mfx;
796  tau21(i,j,k) *= -mu_tot*met_h_zeta/mfy;
797  });
798 }
constexpr amrex::Real two
Definition: ERF_NumericalConstants.H:38
@ Mom_h
Definition: ERF_IndexDefines.H:284
@ Mom_v
Definition: ERF_IndexDefines.H:289

Referenced by erf_make_tau_terms().

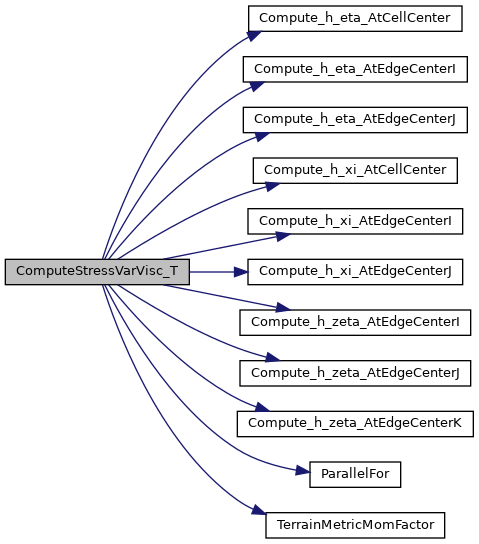
Here is the call graph for this function:
Here is the caller graph for this function: