ERF
Energy Research and Forecasting: An Atmospheric Modeling Code
ERF_MakeTauTerms.cpp File Reference
#include "AMReX_ArrayLim.H"
#include "AMReX_BCRec.H"
#include "AMReX_GpuContainers.H"
#include "ERF_TI_slow_headers.H"
#include "ERF_EOS.H"
#include "ERF_Utils.H"
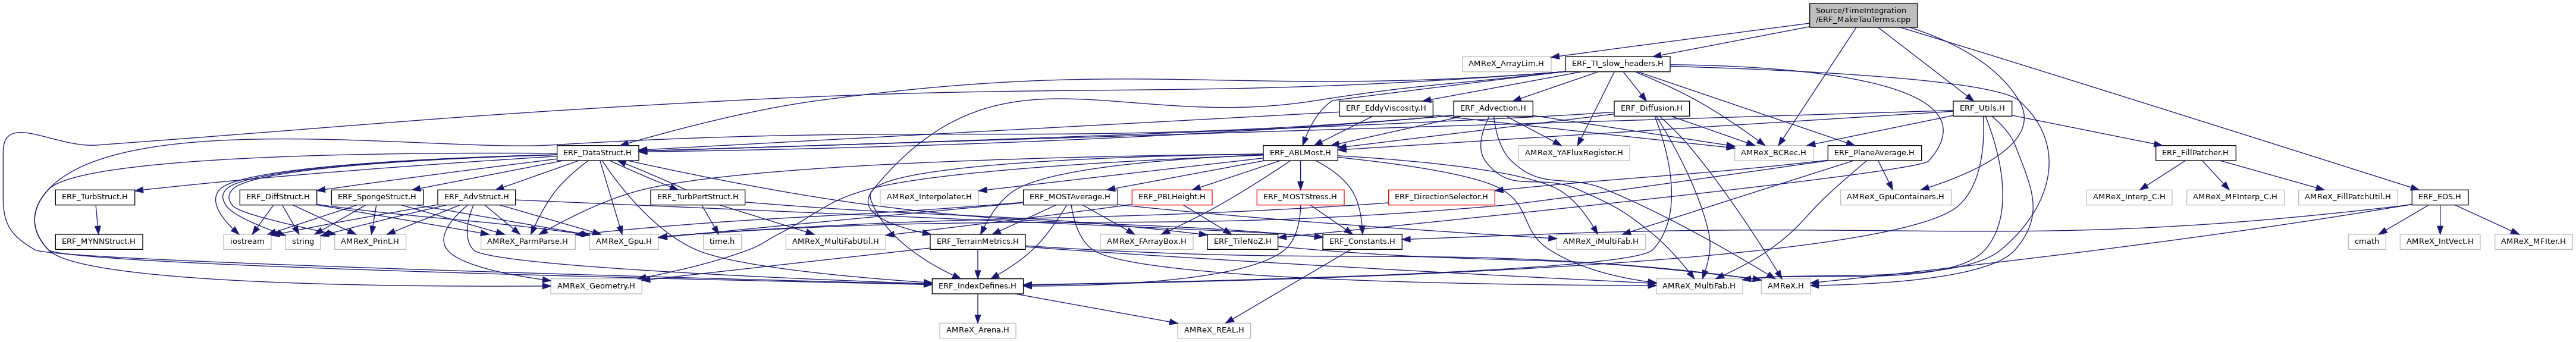
Include dependency graph for ERF_MakeTauTerms.cpp:
Functions

void erf_make_tau_terms (int level, int nrk, const Vector< BCRec > &domain_bcs_type_h, const MultiFab &z_phys_nd, Vector< MultiFab > &S_data, const MultiFab &xvel, const MultiFab &yvel, const MultiFab &zvel, Vector< std::unique_ptr< MultiFab >> &Tau_lev, Vector< std::unique_ptr< MultiFab >> &Tau_corr_lev, MultiFab *SmnSmn, MultiFab *eddyDiffs, const Geometry geom, const SolverChoice &solverChoice, const amrex::Vector< std::unique_ptr< SurfaceLayer >> &, Gpu::DeviceVector< Real > &stretched_dz_d, const MultiFab &detJ, Vector< std::unique_ptr< MultiFab >> &mapfac, const MultiFab &ax, const MultiFab &ay, const MultiFab &az, const eb_ &ebfact, const MultiFab *ib_wall_face13, const MultiFab *ib_wall_face23)
 
void copy_surface_tau_for_implicit (Vector< std::unique_ptr< MultiFab >> &Tau_lev, Vector< std::unique_ptr< MultiFab >> &Tau_corr_lev)
 

Function Documentation

◆ copy_surface_tau_for_implicit()

void copy_surface_tau_for_implicit ( Vector< std::unique_ptr< MultiFab >> &  Tau_lev,
Vector< std::unique_ptr< MultiFab >> &  Tau_corr_lev 
)
743 {
744  // This is only needed if we're using a surface layer, which overwrites the
745  // shear stresses at klo -- at the moment, this is for testing
746 
747  for ( MFIter mfi(*Tau_lev[TauType::tau11],TileNoZ()); mfi.isValid(); ++mfi)
748  {
749  Array4<Real> tau13 = Tau_lev[TauType::tau13]->array(mfi);
750  Array4<Real> tau23 = Tau_lev[TauType::tau23]->array(mfi);
751 
752  Array4<Real> tau13_corr = Tau_corr_lev[0]->array(mfi);
753  Array4<Real> tau23_corr = Tau_corr_lev[1]->array(mfi);
754 
755  const int klo{0};
756  Box bx = mfi.tilebox();
757  bx.makeSlab(2,klo);
758  Box bxx = surroundingNodes(bx,0);
759  Box bxy = surroundingNodes(bx,1);
760 
761  ParallelFor(bxx, bxy,
762  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
763  tau13_corr(i,j,k) = tau13(i,j,k);
764  },
765  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
766  tau23_corr(i,j,k) = tau23(i,j,k);
767  });
768  }
769 }
@ tau23
Definition: ERF_DataStruct.H:49
@ tau11
Definition: ERF_DataStruct.H:49
@ tau13
Definition: ERF_DataStruct.H:49
const int klo
Definition: ERF_InitCustomPert_KE.H:9
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
AMREX_FORCE_INLINE amrex::IntVect TileNoZ()
Definition: ERF_TileNoZ.H:11
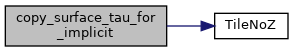
Here is the call graph for this function:
◆ erf_make_tau_terms()

void erf_make_tau_terms ( int  level,
int  nrk,
const Vector< BCRec > &  domain_bcs_type_h,
const MultiFab &  z_phys_nd,
Vector< MultiFab > &  S_data,
const MultiFab &  xvel,
const MultiFab &  yvel,
const MultiFab &  zvel,
Vector< std::unique_ptr< MultiFab >> &  Tau_lev,
Vector< std::unique_ptr< MultiFab >> &  Tau_corr_lev,
MultiFab *  SmnSmn,
MultiFab *  eddyDiffs,
const Geometry  geom,
const SolverChoice &  solverChoice,
const amrex::Vector< std::unique_ptr< SurfaceLayer >> &  ,
Gpu::DeviceVector< Real > &  stretched_dz_d,
const MultiFab &  detJ,
Vector< std::unique_ptr< MultiFab >> &  mapfac,
const MultiFab &  ax,
const MultiFab &  ay,
const MultiFab &  az,
const eb_ &  ebfact,
const MultiFab *  ib_wall_face13,
const MultiFab *  ib_wall_face23 
)
33 {
34  BL_PROFILE_REGION("erf_make_tau_terms()");
35 
36  const BCRec* bc_ptr_h = domain_bcs_type_h.data();
37 
38  DiffChoice dc = solverChoice.diffChoice;
39  TurbChoice tc = solverChoice.turbChoice[level];
40 
41  const bool l_use_terrain_fitted_coords = (solverChoice.mesh_type != MeshType::ConstantDz);
42  const bool l_moving_terrain = (solverChoice.terrain_type == TerrainType::MovingFittedMesh);
43  if (l_moving_terrain) AMREX_ALWAYS_ASSERT (l_use_terrain_fitted_coords);
44 
45 
46  const bool l_use_diff = ( (dc.molec_diff_type != MolecDiffType::None) || tc.use_kturb );
47  const bool l_use_constAlpha = ( dc.molec_diff_type == MolecDiffType::ConstantAlpha );
48  const bool l_use_turb = ( tc.les_type == LESType::Smagorinsky ||
49  tc.les_type == LESType::Deardorff ||
50  tc.rans_type == RANSType::kEqn ||
51  tc.pbl_type == PBLType::MYJ ||
52  tc.pbl_type == PBLType::MYNN25 ||
53  tc.pbl_type == PBLType::MYNNEDMF ||
54  tc.pbl_type == PBLType::YSU ||
55  tc.pbl_type == PBLType::YSUNew ||
56  tc.pbl_type == PBLType::MRF);
57 
58  const bool need_SmnSmn = (tc.les_type == LESType::Deardorff ||
59  tc.rans_type == RANSType::kEqn);
60 
61  const bool do_implicit = (solverChoice.vert_implicit_fac[level][nrk] > 0) && solverChoice.implicit_momentum_diffusion;
62  // erf.implicit_terrain_metric: the implicit solve also takes the compact terrain-metric
63  // term, so the explicit part it removes (Tau_corr) must hold it as well
64  const bool l_implicit_metric = do_implicit && solverChoice.implicit_terrain_metric;
65 
66  const Box& domain = geom.Domain();
67  const int domlo_z = domain.smallEnd(2);
68  const int domhi_z = domain.bigEnd(2);
69 
70  const GpuArray<Real, AMREX_SPACEDIM> dxInv = geom.InvCellSizeArray();
71 
72  // *****************************************************************************
73  // Pre-computed quantities
74  // *****************************************************************************
75  const BoxArray& ba = S_data[IntVars::cons].boxArray();
76  const DistributionMapping& dm = S_data[IntVars::cons].DistributionMap();
77 
78  std::unique_ptr<MultiFab> expr;
79 
80  if (l_use_diff) {
81  expr = std::make_unique<MultiFab>(ba, dm, 1, IntVect(1,1,1));
82 
83  // if using constant alpha (mu = rho * alpha), then first divide by the
84  // reference density -- mu_eff will be scaled by the instantaneous
85  // local density later when ComputeStress*Visc_*() is called
86  Real mu_eff = (l_use_constAlpha) ? two * dc.dynamic_viscosity / dc.rho0_trans
87  : two * dc.dynamic_viscosity;
88 
89  auto dz_ptr = stretched_dz_d.data();
90 
91 #ifdef _OPENMP
92 #pragma omp parallel if (Gpu::notInLaunchRegion())
93 #endif
94  for ( MFIter mfi(S_data[IntVars::cons],TileNoZ()); mfi.isValid(); ++mfi)
95  {
96  const Box& valid_bx = mfi.validbox();
97 
98  // Velocities
99  const Array4<const Real> & u = xvel.array(mfi);
100  const Array4<const Real> & v = yvel.array(mfi);
101  const Array4<const Real> & w = zvel.array(mfi);
102 
103  // Map factors
104  const Array4<const Real>& mf_mx = mapfac[MapFacType::m_x]->const_array(mfi);
105  const Array4<const Real>& mf_ux = mapfac[MapFacType::u_x]->const_array(mfi);
106  const Array4<const Real>& mf_vx = mapfac[MapFacType::v_x]->const_array(mfi);
107  const Array4<const Real>& mf_my = mapfac[MapFacType::m_y]->const_array(mfi);
108  const Array4<const Real>& mf_uy = mapfac[MapFacType::u_y]->const_array(mfi);
109  const Array4<const Real>& mf_vy = mapfac[MapFacType::v_y]->const_array(mfi);
110 
111  // Eddy viscosity
112  const Array4<Real const>& mu_turb = l_use_turb ? eddyDiffs->const_array(mfi) :
113  Array4<const Real>{};
114  const Array4<Real const>& cell_data = l_use_constAlpha ? S_data[IntVars::cons].const_array(mfi) :
115  Array4<const Real>{};
116 
117  // Terrain metrics
118  const Array4<const Real>& z_nd = z_phys_nd.const_array(mfi);
119  const Array4<const Real>& detJ_arr = detJ.const_array(mfi);
120 
121  // EB
122  Array4<const EBCellFlag> cflag{};
123  Array4<const Real> vfrac{};
124  Array4<const Real> apx{};
125  Array4<const Real> apy{};
126  Array4<const Real> apz{};
127  if (solverChoice.terrain_type == TerrainType::EB) {
128  auto const& eb_factory = ebfact.get_const_factory();
129  EBCellFlagFab const& cflag_fab = eb_factory->getMultiEBCellFlagFab()[mfi];
130  cflag = cflag_fab.const_array();
131  vfrac = eb_factory->getVolFrac().const_array(mfi);
132  if (cflag_fab.getType(valid_bx) == FabType::singlevalued) {
133  apx = eb_factory->getAreaFrac()[0]->const_array(mfi);
134  apy = eb_factory->getAreaFrac()[1]->const_array(mfi);
135  apz = eb_factory->getAreaFrac()[2]->const_array(mfi);
136  } else {
137  apx = ax.const_array(mfi);
138  apy = ay.const_array(mfi);
139  apz = az.const_array(mfi);
140  }
141  }
142 
143  //-------------------------------------------------------------------------------
144  // NOTE: Tile boxes with terrain are not intuitive. The linear combination of
145  // stress terms requires care. Create a tile box that intersects the
146  // valid box, then grow the box in x/y. Compute the strain on the local
147  // FAB over this grown tile box. Compute the stress over the tile box,
148  // except tau_ii which still needs the halo cells. Finally, write from
149  // the local FAB to the Tau MF but only on the tile box.
150  //-------------------------------------------------------------------------------
151 
152  //-------------------------------------------------------------------------------
153  // TODO: Avoid recomputing strain on the first RK stage. One could populate
154  // the FABs with tau_ij, compute stress, and then write to tau_ij. The
155  // problem with this approach is you will over-write the needed halo layer
156  // needed by subsequent tile boxes (particularly S_ii becomes Tau_ii).
157  //-------------------------------------------------------------------------------
158 
159  // Strain/Stress tile boxes
160  Box bx = mfi.tilebox();
161  Box bxcc = mfi.tilebox();
162  Box tbxxy = mfi.tilebox(IntVect(1,1,0));
163  Box tbxxz = mfi.tilebox(IntVect(1,0,1));
164  Box tbxyz = mfi.tilebox(IntVect(0,1,1));
165 
166  // We need a halo cell for terrain
167  bxcc.grow(IntVect(1,1,0));
168  tbxxy.grow(IntVect(1,1,0));
169  tbxxz.grow(IntVect(1,1,0));
170  tbxyz.grow(IntVect(1,1,0));
171 
172  if (bxcc.smallEnd(2) != domain.smallEnd(2)) {
173  bxcc.growLo(2,1);
174  tbxxy.growLo(2,1);
175  tbxxz.growLo(2,1);
176  tbxyz.growLo(2,1);
177  }
178 
179  if (bxcc.bigEnd(2) != domain.bigEnd(2)) {
180  bxcc.growHi(2,1);
181  tbxxy.growHi(2,1);
182  tbxxz.growHi(2,1);
183  tbxyz.growHi(2,1);
184  }
185 
186  // Expansion rate
187  Array4<Real> er_arr = expr->array(mfi);
188 
189  // Temporary storage for tiling/OMP
190  FArrayBox S11,S22,S33;
191  FArrayBox S12,S13,S23;
192 
193  // Symmetric strain/stresses
194  S11.resize( bxcc,1,The_Async_Arena()); S22.resize( bxcc,1,The_Async_Arena()); S33.resize( bxcc,1,The_Async_Arena());
195  S12.resize(tbxxy,1,The_Async_Arena()); S13.resize(tbxxz,1,The_Async_Arena()); S23.resize(tbxyz,1,The_Async_Arena());
196  Array4<Real> s11 = S11.array(); Array4<Real> s22 = S22.array(); Array4<Real> s33 = S33.array();
197  Array4<Real> s12 = S12.array(); Array4<Real> s13 = S13.array(); Array4<Real> s23 = S23.array();
198  Array4<Real> tau11 = Tau_lev[TauType::tau11]->array(mfi); Array4<Real> tau22 = Tau_lev[TauType::tau22]->array(mfi);
199  Array4<Real> tau33 = Tau_lev[TauType::tau33]->array(mfi); Array4<Real> tau12 = Tau_lev[TauType::tau12]->array(mfi);
200  Array4<Real> tau13 = Tau_lev[TauType::tau13]->array(mfi); Array4<Real> tau23 = Tau_lev[TauType::tau23]->array(mfi);
201 
202  // We cannot simply scale the tau3* terms since our implicit
203  // correction to vertical diffusion only applies to the
204  // second-order derivatives in the vertical and we don't want to
205  // touch the cross terms -- we save the terms here and
206  // manipulate them later.
207  FArrayBox S13_for_impl, S23_for_impl;
208  S13_for_impl.resize(tbxxz,1,The_Async_Arena());
209  S23_for_impl.resize(tbxyz,1,The_Async_Arena());
210  Array4<Real> s13_corr = (do_implicit) ? S13_for_impl.array() : Array4<Real>{};
211  Array4<Real> s23_corr = (do_implicit) ? S23_for_impl.array() : Array4<Real>{};
212  Array4<Real> tau13_corr = (do_implicit) ? Tau_corr_lev[0]->array(mfi) : Array4<Real>{};
213  Array4<Real> tau23_corr = (do_implicit) ? Tau_corr_lev[1]->array(mfi) : Array4<Real>{};
214 
215  // Calculate the magnitude of the strain-rate tensor squared if
216  // using Deardorff or k-eqn RANS. This contributes to the production
217  // term, included in diffusion source in slow RHS post and in the
218  // first RK stage (TKE tendencies constant for nrk>0, following WRF)
219  Array4<Real> SmnSmn_a = ((nrk==0) && need_SmnSmn) ? SmnSmn->array(mfi) : Array4<Real>{};
220 
221  // ****************************************************************
222  //
223  // These are the steps taken below...
224  //
225  // 1. Calculate expansion rate
226  // - will be added to the normal strain rates in ComputeStress
227  //
228  // 2. Call ComputeStrain
229  // - IMPLICIT path: s31_corr and s32_corr are modified in here
230  //
231  // 3. Call ComputeSmnSmn, if needed for turbulence model
232  //
233  // 4. Call ComputeStress
234  // - add expansion rates to terms on diagonal
235  // - multiply strain rates by diffusivities, with the total
236  // viscosity calculated as the sum of a constant viscosity (or
237  // constant alpha with mu = rho*alpha) and the eddy viscosity
238  // from the turbulence model
239  //
240  // 5. Copy temp Sij fabs into Tau_lev multifabs
241  // - stress tensor is symmetric if no terrain and no implicit diffusion
242  // - otherwise, stress tensor is asymmetric
243  //
244  // ****************************************************************
245 
246  if (solverChoice.mesh_type == MeshType::StretchedDz) {
247  // Terrain non-symmetric terms
248  FArrayBox S21,S31,S32;
249  S21.resize(tbxxy,1,The_Async_Arena()); S31.resize(tbxxz,1,The_Async_Arena()); S32.resize(tbxyz,1,The_Async_Arena());
250  Array4<Real> s21 = S21.array(); Array4<Real> s31 = S31.array(); Array4<Real> s32 = S32.array();
251  Array4<Real> tau21 = Tau_lev[TauType::tau21]->array(mfi);
252  Array4<Real> tau31 = Tau_lev[TauType::tau31]->array(mfi);
253  Array4<Real> tau32 = Tau_lev[TauType::tau32]->array(mfi);
254 
255  // *****************************************************************************
256  // Expansion rate compute terrain
257  // *****************************************************************************
258  {
259  BL_PROFILE("slow_rhs_making_er_S");
260  ParallelFor(bxcc, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
261  {
262  Real mfsq = mf_mx(i,j,0)*mf_my(i,j,0);
263  er_arr(i,j,k) = (u(i+1, j , k )/mf_uy(i+1,j,0) - u(i, j, k)/mf_uy(i,j,0))*dxInv[0] * mfsq + // == du / (dη/dy) * (1/dξ) * (dξ/dx)*(dη/dy) = du/dx
264  (v(i , j+1, k )/mf_vx(i,j+1,0) - v(i, j, k)/mf_vx(i,j,0))*dxInv[1] * mfsq + // == dv / (dξ/dx) * (1/dη) * (dξ/dx)*(dη/dy) = dv/dy
265  (w(i , j , k+1) - w(i, j, k) )/dz_ptr[k];
266  });
267  } // end profile
268 
269  // *****************************************************************************
270  // Strain tensor compute terrain
271  // *****************************************************************************
272  {
273  BL_PROFILE("slow_rhs_making_strain_S");
274  ComputeStrain_S(bxcc, tbxxy, tbxxz, tbxyz, domain,
275  u, v, w,
276  s11, s22, s33,
277  s12, s21,
278  s13, s31,
279  s23, s32,
280  stretched_dz_d, dxInv,
281  mf_mx, mf_ux, mf_vx,
282  mf_my, mf_uy, mf_vy, bc_ptr_h,
283  s13_corr, s23_corr);
284  } // end profile
285 
286  if (SmnSmn_a) {
287  ParallelFor(bx, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
288  {
289  SmnSmn_a(i,j,k) = ComputeSmnSmn(i,j,k,
290  s11,s22,s33,
291  s12,s13,s23);
292  });
293  }
294 
295  // *****************************************************************************
296  // Stress tensor compute terrain
297  // *****************************************************************************
298  {
299  BL_PROFILE("slow_rhs_making_stress_T");
300 
301  // Remove Halo cells just for tau_ij comps
302  tbxxy.grow(IntVect(-1,-1,0));
303  tbxxz.grow(IntVect(-1,-1,0));
304  tbxyz.grow(IntVect(-1,-1,0));
305 
306  if (!l_use_turb) {
307  ComputeStressConsVisc_S(bxcc, tbxxy, tbxxz, tbxyz, mu_eff,
308  cell_data,
309  s11, s22, s33,
310  s12, s21,
311  s13, s31,
312  s23, s32,
313  er_arr,
314  mf_mx, mf_ux, mf_vx,
315  mf_my, mf_uy, mf_vy,
316  s13_corr, s23_corr);
317  } else {
318  ComputeStressVarVisc_S(bxcc, tbxxy, tbxxz, tbxyz, mu_eff, mu_turb,
319  cell_data,
320  s11, s22, s33,
321  s12, s21,
322  s13, s31,
323  s23, s32,
324  er_arr,
325  mf_mx, mf_ux, mf_vx,
326  mf_my, mf_uy, mf_vy,
327  s13_corr, s23_corr);
328  }
329 
330  // Remove halo cells from tau_ii but extend across valid_box bdry
331  bxcc.grow(IntVect(-1,-1,0));
332  if (bxcc.smallEnd(0) == valid_bx.smallEnd(0)) bxcc.growLo(0, 1);
333  if (bxcc.bigEnd(0) == valid_bx.bigEnd(0)) bxcc.growHi(0, 1);
334  if (bxcc.smallEnd(1) == valid_bx.smallEnd(1)) bxcc.growLo(1, 1);
335  if (bxcc.bigEnd(1) == valid_bx.bigEnd(1)) bxcc.growHi(1, 1);
336 
337  // Copy from temp FABs back to tau
338  ParallelFor(bxcc,
339  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
340  tau11(i,j,k) = s11(i,j,k);
341  tau22(i,j,k) = s22(i,j,k);
342  tau33(i,j,k) = s33(i,j,k);
343  });
344 
345  ParallelFor(tbxxy, tbxxz, tbxyz,
346  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
347  tau12(i,j,k) = s12(i,j,k);
348  tau21(i,j,k) = s21(i,j,k);
349  },
350  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
351  tau13(i,j,k) = s13(i,j,k);
352  tau31(i,j,k) = s31(i,j,k);
353  if (tau13_corr) tau13_corr(i,j,k) = s13_corr(i,j,k);
354  },
355  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
356  tau23(i,j,k) = s23(i,j,k);
357  tau32(i,j,k) = s32(i,j,k);
358  if (tau23_corr) tau23_corr(i,j,k) = s23_corr(i,j,k);
359  });
360  } // end profile
361 
362  } else if (l_use_terrain_fitted_coords) {
363 
364  // Terrain non-symmetric terms
365  FArrayBox S21,S31,S32;
366  S21.resize(tbxxy,1,The_Async_Arena()); S31.resize(tbxxz,1,The_Async_Arena()); S32.resize(tbxyz,1,The_Async_Arena());
367  Array4<Real> s21 = S21.array(); Array4<Real> s31 = S31.array(); Array4<Real> s32 = S32.array();
368  Array4<Real> tau21 = Tau_lev[TauType::tau21]->array(mfi);
369  Array4<Real> tau31 = Tau_lev[TauType::tau31]->array(mfi);
370  Array4<Real> tau32 = Tau_lev[TauType::tau32]->array(mfi);
371 
372 
373  // *****************************************************************************
374  // Expansion rate compute terrain
375  // *****************************************************************************
376  {
377  BL_PROFILE("slow_rhs_making_er_T");
378  Box gbxo = surroundingNodes(bxcc,2);
379 
380  // We make a temporary container for contravariant velocity Omega here
381  // -- it is only used to compute er_arr below
382  FArrayBox Omega;
383  Omega.resize(gbxo,1,The_Async_Arena());
384 
385  // First create Omega using velocity (not momentum)
386  Array4<Real> omega_arr = Omega.array();
387  ParallelFor(gbxo, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
388  {
389  omega_arr(i,j,k) = (k == 0) ? zero : OmegaFromW(i,j,k,w(i,j,k),u,v,
390  mf_ux,mf_vy,z_nd,dxInv);
391  });
392 
393  ParallelFor(bxcc, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
394  {
395 
396  Real met_u_h_zeta_hi = Compute_h_zeta_AtIface(i+1, j , k, dxInv, z_nd);
397  Real met_u_h_zeta_lo = Compute_h_zeta_AtIface(i , j , k, dxInv, z_nd);
398 
399  Real met_v_h_zeta_hi = Compute_h_zeta_AtJface(i , j+1, k, dxInv, z_nd);
400  Real met_v_h_zeta_lo = Compute_h_zeta_AtJface(i , j , k, dxInv, z_nd);
401 
402  Real Omega_hi = omega_arr(i,j,k+1);
403  Real Omega_lo = omega_arr(i,j,k );
404 
405  Real mfsq = mf_mx(i,j,0)*mf_my(i,j,0);
406 
407  Real expansionRate = (u(i+1,j ,k)/mf_uy(i+1,j,0)*met_u_h_zeta_hi - u(i,j,k)/mf_uy(i,j,0)*met_u_h_zeta_lo)*dxInv[0]*mfsq +
408  (v(i ,j+1,k)/mf_vx(i,j+1,0)*met_v_h_zeta_hi - v(i,j,k)/mf_vx(i,j,0)*met_v_h_zeta_lo)*dxInv[1]*mfsq +
409  (Omega_hi - Omega_lo)*dxInv[2];
410 
411  er_arr(i,j,k) = expansionRate / detJ_arr(i,j,k);
412 
413  // Note:
414  // expansionRate ~ du / (dη/dy) * (dz/dζ) * (1/dξ) * (dξ/dx)*(dη/dy)
415  // + dv / (dξ/dx) * (dz/dζ) * (1/dη) * (dξ/dx)*(dη/dy)
416  // + dΩ/dζ
417  // ~ (du/dx)*(dz/dζ) + (dv/dy)*(dz/dζ) + dΩ/dζ
418  // Dividing by detJ==dz/dζ gives du/dx + dv/dy + dΩ/dz
419  });
420  } // end profile
421 
422  // *****************************************************************************
423  // Strain tensor compute terrain
424  // *****************************************************************************
425  {
426  BL_PROFILE("slow_rhs_making_strain_T");
427  ComputeStrain_T(bxcc, tbxxy, tbxxz, tbxyz, domain,
428  u, v, w,
429  s11, s22, s33,
430  s12, s21,
431  s13, s31,
432  s23, s32,
433  z_nd, detJ_arr, dxInv,
434  mf_mx, mf_ux, mf_vx,
435  mf_my, mf_uy, mf_vy, bc_ptr_h,
436  s13_corr, s23_corr);
437  } // end profile
438 
439  if (SmnSmn_a) {
440  ParallelFor(bx, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
441  {
442  SmnSmn_a(i,j,k) = ComputeSmnSmn(i,j,k,
443  s11,s22,s33,
444  s12,s13,s23);
445  });
446  }
447 
448  // *****************************************************************************
449  // Stress tensor compute terrain
450  // *****************************************************************************
451  {
452  BL_PROFILE("slow_rhs_making_stress_T");
453 
454  // Remove Halo cells just for tau_ij comps
455  tbxxy.grow(IntVect(-1,-1,0));
456  tbxxz.grow(IntVect(-1,-1,0));
457  tbxyz.grow(IntVect(-1,-1,0));
458 
459  if (!l_use_turb) {
460  ComputeStressConsVisc_T(bxcc, tbxxy, tbxxz, tbxyz, mu_eff,
461  cell_data,
462  s11, s22, s33,
463  s12, s21,
464  s13, s31,
465  s23, s32,
466  er_arr, z_nd, detJ_arr, dxInv,
467  mf_mx, mf_ux, mf_vx,
468  mf_my, mf_uy, mf_vy,
469  s13_corr, s23_corr,
470  l_implicit_metric);
471  } else {
472  ComputeStressVarVisc_T(bxcc, tbxxy, tbxxz, tbxyz, mu_eff, mu_turb,
473  cell_data,
474  s11, s22, s33,
475  s12, s21,
476  s13, s31,
477  s23, s32,
478  er_arr, z_nd, detJ_arr, dxInv,
479  mf_mx, mf_ux, mf_vx,
480  mf_my, mf_uy, mf_vy,
481  s13_corr, s23_corr,
482  l_implicit_metric);
483  }
484 
485  // Remove halo cells from tau_ii but extend across valid_box bdry
486  bxcc.grow(IntVect(-1,-1,0));
487  if (bxcc.smallEnd(0) == valid_bx.smallEnd(0)) bxcc.growLo(0, 1);
488  if (bxcc.bigEnd(0) == valid_bx.bigEnd(0)) bxcc.growHi(0, 1);
489  if (bxcc.smallEnd(1) == valid_bx.smallEnd(1)) bxcc.growLo(1, 1);
490  if (bxcc.bigEnd(1) == valid_bx.bigEnd(1)) bxcc.growHi(1, 1);
491 
492  // Copy from temp FABs back to tau
493  ParallelFor(bxcc,
494  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
495  tau11(i,j,k) = s11(i,j,k);
496  tau22(i,j,k) = s22(i,j,k);
497  tau33(i,j,k) = s33(i,j,k);
498  });
499 
500  ParallelFor(tbxxy, tbxxz, tbxyz,
501  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
502  tau12(i,j,k) = s12(i,j,k);
503  tau21(i,j,k) = s21(i,j,k);
504  },
505  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
506  tau13(i,j,k) = s13(i,j,k);
507  tau31(i,j,k) = s31(i,j,k);
508  if(tau13_corr) tau13_corr(i,j,k) = s13_corr(i,j,k);
509  },
510  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
511  tau23(i,j,k) = s23(i,j,k);
512  tau32(i,j,k) = s32(i,j,k);
513  if(tau23_corr) tau23_corr(i,j,k) = s23_corr(i,j,k);
514  });
515  } // end profile
516 
517  } else {
518 
519  // *****************************************************************************
520  // Expansion rate compute no terrain
521  // *****************************************************************************
522  {
523  BL_PROFILE("slow_rhs_making_er_N");
524  if (solverChoice.terrain_type != TerrainType::EB) {
525  ParallelFor(bxcc, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
526  Real mfsq = mf_mx(i,j,0)*mf_my(i,j,0);
527  er_arr(i,j,k) = (u(i+1, j , k )/mf_uy(i+1,j,0) - u(i, j, k)/mf_uy(i,j,0))*dxInv[0]*mfsq +
528  (v(i , j+1, k )/mf_vx(i,j+1,0) - v(i, j, k)/mf_vx(i,j,0))*dxInv[1]*mfsq +
529  (w(i , j , k+1) - w(i, j, k))*dxInv[2];
530  });
531  } else {
532  ParallelFor(bxcc, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
533  if (cflag(i,j,k).isSingleValued()) {
534  er_arr(i,j,k) = (one/vfrac(i,j,k)) * (
535  dxInv[0] * ( apx(i+1,j,k)*u(i+1,j,k) - apx(i,j,k)*u(i,j,k) )
536  + dxInv[1] * ( apy(i,j+1,k)*v(i,j+1,k) - apy(i,j,k)*v(i,j,k) )
537  + dxInv[2] * ( apz(i,j,k+1)*w(i,j,k+1) - apz(i,j,k)*w(i,j,k) ) );
538  } else if (cflag(i,j,k).isRegular()) {
539  er_arr(i,j,k) = (u(i+1, j , k ) - u(i, j, k))*dxInv[0] +
540  (v(i , j+1, k ) - v(i, j, k))*dxInv[1] +
541  (w(i , j , k+1) - w(i, j, k))*dxInv[2];
542  } else {
543  er_arr(i,j,k) = zero;
544  }
545  });
546  }
547  } // end profile
548 
549  // *****************************************************************************
550  // Strain tensor compute no terrain
551  // *****************************************************************************
552  {
553  BL_PROFILE("slow_rhs_making_strain_N");
554  if (solverChoice.terrain_type != TerrainType::EB) {
555  ComputeStrain_N(bxcc, tbxxy, tbxxz, tbxyz, domain,
556  u, v, w,
557  s11, s22, s33,
558  s12, s13, s23,
559  dxInv,
560  mf_mx, mf_ux, mf_vx,
561  mf_my, mf_uy, mf_vy, bc_ptr_h,
562  s13_corr, s23_corr);
563  } else {
564  ComputeStrain_EB(mfi, bxcc, tbxxy, tbxxz, tbxyz, domain,
565  u, v, w,
566  s11, s22, s33,
567  s12, s13, s23,
568  dxInv,
569  bc_ptr_h,
570  ebfact,
571  s13_corr, s23_corr);
572  }
573  } // end profile
574 
575  // Fraction-stress immersed wall law: the strain on the bottom face of the wall cell is
576  // the strain on the face above, as on the zlo face of flat ground, whose hoextrap ghost
577  // (2 u_0 - u_1) gives the first cell the gradient of the face above. The TKE production
578  // of the wall cell then does not see the solid below as a no-slip wall. (The stress on
579  // that face is zeroed below: the wall law supplies it.) One wall face per column, and
580  // the face above is never one, so the copy has no read/write overlap. The copy comes
581  // first, so the wall face carries the unscaled strain; the face above the wall cell
582  // is then scaled by the spacing factor of erf.if_wall_face_spacing.
583  if (ib_wall_face13 && ib_wall_face23) {
584  auto const m13 = ib_wall_face13->const_array(mfi);
585  auto const m23 = ib_wall_face23->const_array(mfi);
586  Box xz = tbxxz & ib_wall_face13->fabbox(mfi.index()); xz.growHi(2, -1);
587  Box yz = tbxyz & ib_wall_face23->fabbox(mfi.index()); yz.growHi(2, -1);
588  const Box xz_all = tbxxz & ib_wall_face13->fabbox(mfi.index());
589  const Box yz_all = tbxyz & ib_wall_face23->fabbox(mfi.index());
590  ParallelFor(xz, yz,
591  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
592  if (m13(i,j,k) == zero) {
593  s13(i,j,k) = s13(i,j,k+1);
594  if (s13_corr) s13_corr(i,j,k) = s13_corr(i,j,k+1);
595  }
596  },
597  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
598  if (m23(i,j,k) == zero) {
599  s23(i,j,k) = s23(i,j,k+1);
600  if (s23_corr) s23_corr(i,j,k) = s23_corr(i,j,k+1);
601  }
602  });
603  ParallelFor(xz_all, yz_all,
604  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
605  if (m13(i,j,k) != zero) {
606  s13(i,j,k) *= m13(i,j,k);
607  if (s13_corr) s13_corr(i,j,k) *= m13(i,j,k);
608  }
609  },
610  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
611  if (m23(i,j,k) != zero) {
612  s23(i,j,k) *= m23(i,j,k);
613  if (s23_corr) s23_corr(i,j,k) *= m23(i,j,k);
614  }
615  });
616  }
617 
618  if (SmnSmn_a) {
619  ParallelFor(bx, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
620  {
621  SmnSmn_a(i,j,k) = ComputeSmnSmn(i,j,k,
622  s11,s22,s33,
623  s12,s13,s23);
624  });
625  }
626 
627  // *****************************************************************************
628  // Stress tensor compute no terrain
629  // *****************************************************************************
630  {
631  BL_PROFILE("slow_rhs_making_stress_N");
632 
633  // Remove Halo cells just for tau_ij comps
634  tbxxy.grow(IntVect(-1,-1,0));
635  tbxxz.grow(IntVect(-1,-1,0));
636  tbxyz.grow(IntVect(-1,-1,0));
637  if (tbxxy.smallEnd(2) > domlo_z) {
638  tbxxy.growLo(2,-1);
639  tbxxz.growLo(2,-1);
640  tbxyz.growLo(2,-1);
641  }
642  if (tbxxy.bigEnd(2) < domhi_z) {
643  tbxxy.growHi(2,-1);
644  tbxxz.growHi(2,-1);
645  tbxyz.growHi(2,-1);
646  }
647 
648  if (!l_use_turb) {
649  if (solverChoice.terrain_type != TerrainType::EB) {
650  ComputeStressConsVisc_N(bxcc, tbxxy, tbxxz, tbxyz, mu_eff,
651  cell_data,
652  s11, s22, s33,
653  s12, s13, s23,
654  er_arr,
655  s13_corr, s23_corr);
656  } else {
657  ComputeStressConsVisc_EB(bxcc, tbxxy, tbxxz, tbxyz, mu_eff,
658  cell_data,
659  s11, s22, s33,
660  s12, s13, s23,
661  er_arr,
662  vfrac,
663  s13_corr, s23_corr);
664  }
665  } else {
666  if (solverChoice.terrain_type != TerrainType::EB) {
667  ComputeStressVarVisc_N(bxcc, tbxxy, tbxxz, tbxyz, mu_eff, mu_turb,
668  cell_data,
669  s11, s22, s33,
670  s12, s13, s23,
671  er_arr,
672  s13_corr, s23_corr);
673  } else {
674  ComputeStressVarVisc_EB(bxcc, tbxxy, tbxxz, tbxyz, mu_eff, mu_turb,
675  cell_data,
676  s11, s22, s33,
677  s12, s13, s23,
678  er_arr,
679  vfrac,
680  s13_corr, s23_corr);
681  }
682  }
683 
684  // Remove halo cells from tau_ii but extend across valid_box bdry
685  bxcc.grow(IntVect(-1,-1,0));
686  if (bxcc.smallEnd(0) == valid_bx.smallEnd(0)) bxcc.growLo(0, 1);
687  if (bxcc.bigEnd(0) == valid_bx.bigEnd(0)) bxcc.growHi(0, 1);
688  if (bxcc.smallEnd(1) == valid_bx.smallEnd(1)) bxcc.growLo(1, 1);
689  if (bxcc.bigEnd(1) == valid_bx.bigEnd(1)) bxcc.growHi(1, 1);
690 
691  // Copy from temp FABs back to tau
692  ParallelFor(bxcc,
693  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
694  tau11(i,j,k) = s11(i,j,k);
695  tau22(i,j,k) = s22(i,j,k);
696  tau33(i,j,k) = s33(i,j,k);
697  });
698  ParallelFor(tbxxy, tbxxz, tbxyz,
699  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
700  tau12(i,j,k) = s12(i,j,k);
701  },
702  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
703  tau13(i,j,k) = s13(i,j,k);
704  if (tau13_corr) tau13_corr(i,j,k) = s13_corr(i,j,k);
705  },
706  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
707  tau23(i,j,k) = s23(i,j,k);
708  if (tau23_corr) tau23_corr(i,j,k) = s23_corr(i,j,k);
709  });
710 
711  // Fraction-stress immersed wall law: no resolved flux through the wall face,
712  // the wall stress is a source in the wall cell (ERF_ImmersedWallCell.H)
713  if (ib_wall_face13 && ib_wall_face23) {
714  auto const m13 = ib_wall_face13->const_array(mfi);
715  auto const m23 = ib_wall_face23->const_array(mfi);
716  const Box xz = tbxxz & ib_wall_face13->fabbox(mfi.index());
717  const Box yz = tbxyz & ib_wall_face23->fabbox(mfi.index());
718  ParallelFor(xz, yz,
719  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
720  // the strain carries the spacing factor already: only close the wall face
721  if (m13(i,j,k) == zero) {
722  tau13(i,j,k) = zero;
723  if (tau13_corr) tau13_corr(i,j,k) = zero;
724  }
725  },
726  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
727  if (m23(i,j,k) == zero) {
728  tau23(i,j,k) = zero;
729  if (tau23_corr) tau23_corr(i,j,k) = zero;
730  }
731  });
732  }
733  } // end profile
734  } // no terrain
735  } // MFIter
736  } // l_use_diff
737 }
void ComputeStrain_EB(const MFIter &mfi, Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Box domain, const Array4< const Real > &u, const Array4< const Real > &v, const Array4< const Real > &w, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau13, Array4< Real > &tau23, const GpuArray< Real, AMREX_SPACEDIM > &dxInv, const BCRec *bc_ptr, const eb_ &ebfact, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStrain_EB.cpp:31
void ComputeStrain_N(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Box domain, const Array4< const Real > &u, const Array4< const Real > &v, const Array4< const Real > &w, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau13, Array4< Real > &tau23, const GpuArray< Real, AMREX_SPACEDIM > &dxInv, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, const BCRec *bc_ptr, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStrain_N.cpp:35
void ComputeStrain_S(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Box domain, const Array4< const Real > &u, const Array4< const Real > &v, const Array4< const Real > &w, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau21, Array4< Real > &tau13, Array4< Real > &tau31, Array4< Real > &tau23, Array4< Real > &tau32, const Gpu::DeviceVector< Real > &stretched_dz_d, const GpuArray< Real, AMREX_SPACEDIM > &dxInv, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, const BCRec *bc_ptr, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStrain_S.cpp:40
void ComputeStrain_T(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Box domain, const Array4< const Real > &u, const Array4< const Real > &v, const Array4< const Real > &w, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau21, Array4< Real > &tau13, Array4< Real > &tau31, Array4< Real > &tau23, Array4< Real > &tau32, const Array4< const Real > &z_nd, const Array4< const Real > &detJ, const GpuArray< Real, AMREX_SPACEDIM > &dxInv, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, const BCRec *bc_ptr, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStrain_T.cpp:41
void ComputeStressConsVisc_EB(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau13, Array4< Real > &tau23, const Array4< const Real > &er_arr, Array4< const Real > &vfrac, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStress_EB.cpp:26
void ComputeStressVarVisc_EB(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &mu_turb, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau13, Array4< Real > &tau23, const Array4< const Real > &er_arr, Array4< const Real > &vfrac, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStress_EB.cpp:177
void ComputeStressVarVisc_N(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &mu_turb, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau13, Array4< Real > &tau23, const Array4< const Real > &er_arr, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStress_N.cpp:121
void ComputeStressConsVisc_N(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau13, Array4< Real > &tau23, const Array4< const Real > &er_arr, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStress_N.cpp:25
void ComputeStressConsVisc_S(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau21, Array4< Real > &tau13, Array4< Real > &tau31, Array4< Real > &tau23, Array4< Real > &tau32, const Array4< const Real > &er_arr, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStress_S.cpp:35
void ComputeStressVarVisc_S(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &mu_turb, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau21, Array4< Real > &tau13, Array4< Real > &tau31, Array4< Real > &tau23, Array4< Real > &tau32, const Array4< const Real > &er_arr, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, Array4< Real > &tau13i, Array4< Real > &tau23i)
Definition: ERF_ComputeStress_S.cpp:166
void ComputeStressVarVisc_T(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &mu_turb, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau21, Array4< Real > &tau13, Array4< Real > &tau31, Array4< Real > &tau23, Array4< Real > &tau32, const Array4< const Real > &er_arr, const Array4< const Real > &z_nd, const Array4< const Real > &detJ, const GpuArray< Real, AMREX_SPACEDIM > &dxInv, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, Array4< Real > &tau13i, Array4< Real > &tau23i, const bool implicit_metric)
Definition: ERF_ComputeStress_T.cpp:402
void ComputeStressConsVisc_T(Box bxcc, Box tbxxy, Box tbxxz, Box tbxyz, Real mu_eff, const Array4< const Real > &cell_data, Array4< Real > &tau11, Array4< Real > &tau22, Array4< Real > &tau33, Array4< Real > &tau12, Array4< Real > &tau21, Array4< Real > &tau13, Array4< Real > &tau31, Array4< Real > &tau23, Array4< Real > &tau32, const Array4< const Real > &er_arr, const Array4< const Real > &z_nd, const Array4< const Real > &detJ, const GpuArray< Real, AMREX_SPACEDIM > &dxInv, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_ux, const Array4< const Real > &mf_vx, const Array4< const Real > &mf_my, const Array4< const Real > &mf_uy, const Array4< const Real > &mf_vy, Array4< Real > &tau13i, Array4< Real > &tau23i, const bool implicit_metric)
Definition: ERF_ComputeStress_T.cpp:41
@ tau12
Definition: ERF_DataStruct.H:49
@ tau33
Definition: ERF_DataStruct.H:49
@ tau22
Definition: ERF_DataStruct.H:49
@ tau32
Definition: ERF_DataStruct.H:49
@ tau31
Definition: ERF_DataStruct.H:49
@ tau21
Definition: ERF_DataStruct.H:49
@ v_x
Definition: ERF_DataStruct.H:38
@ u_y
Definition: ERF_DataStruct.H:39
@ v_y
Definition: ERF_DataStruct.H:39
@ m_y
Definition: ERF_DataStruct.H:39
@ u_x
Definition: ERF_DataStruct.H:38
@ m_x
Definition: ERF_DataStruct.H:38
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real ComputeSmnSmn(int &i, int &j, int &k, const amrex::Array4< amrex::Real const > &tau11, const amrex::Array4< amrex::Real const > &tau22, const amrex::Array4< amrex::Real const > &tau33, const amrex::Array4< amrex::Real const > &tau12, const amrex::Array4< amrex::Real const > &tau13, const amrex::Array4< amrex::Real const > &tau23)
Definition: ERF_EddyViscosity.H:133
amrex::GpuArray< Real, AMREX_SPACEDIM > dxInv
Definition: ERF_InitCustomPertVels_ParticleTests.H:17
AMREX_ALWAYS_ASSERT(bx.length()[2]==khi+1)
constexpr amrex::Real two
Definition: ERF_NumericalConstants.H:38
constexpr amrex::Real one
Definition: ERF_NumericalConstants.H:37
constexpr amrex::Real zero
Definition: ERF_NumericalConstants.H:36
Real w
Definition: ERF_Plotfile2DInterpolator.cpp:23
amrex::Real Real
Definition: ERF_ShocInterface.H:19
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real OmegaFromW(int &i, int &j, int &k, amrex::Real w, const amrex::Array4< const amrex::Real > &u_arr, const amrex::Array4< const amrex::Real > &v_arr, const amrex::Array4< const amrex::Real > &mf_u, const amrex::Array4< const amrex::Real > &mf_v, const amrex::Array4< const amrex::Real > &z_nd, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &dxInv)
Definition: ERF_TerrainMetrics.H:802
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_zeta_AtIface(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:280
AMREX_GPU_DEVICE AMREX_FORCE_INLINE amrex::Real Compute_h_zeta_AtJface(const int &i, const int &j, const int &k, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &z_nd)
Definition: ERF_TerrainMetrics.H:350
const std::unique_ptr< amrex::EBFArrayBoxFactory > & get_const_factory() const noexcept
Return the cell-centered EB factory.
Definition: ERF_EB.H:124
@ cons
Definition: ERF_IndexDefines.H:272
@ xvel
Definition: ERF_IndexDefines.H:255
@ zvel
Definition: ERF_IndexDefines.H:257
@ yvel
Definition: ERF_IndexDefines.H:256
Definition: ERF_DiffStruct.H:24
MolecDiffType molec_diff_type
Selected molecular transport model.
Definition: ERF_DiffStruct.H:96
amrex::Real dynamic_viscosity
Dynamic viscosity for momentum diffusion [kg/(m-s)].
Definition: ERF_DiffStruct.H:108
amrex::Real rho0_trans
Reference density used to compute dynamic diffusion coefficients [kg/m3].
Definition: ERF_DiffStruct.H:103
amrex::Vector< TurbChoice > turbChoice
Turbulence options for each AMR level.
Definition: ERF_DataStruct.H:2620
static MeshType mesh_type
Vertical mesh representation.
Definition: ERF_DataStruct.H:2604
amrex::Vector< amrex::Vector< amrex::Real > > vert_implicit_fac
Per-level, per-stage implicit vertical diffusion factors.
Definition: ERF_DataStruct.H:2657
bool implicit_terrain_metric
Whether the compact terrain-metric part of the vertical diffusion is solved implicitly.
Definition: ERF_DataStruct.H:2667
static TerrainType terrain_type
Terrain or immersed-boundary representation.
Definition: ERF_DataStruct.H:2589
DiffChoice diffChoice
Diffusion-related options.
Definition: ERF_DataStruct.H:2617
bool implicit_momentum_diffusion
Whether implicit vertical momentum diffusion is included.
Definition: ERF_DataStruct.H:2663
Definition: ERF_TurbStruct.H:119
RANSType rans_type
Selected RANS closure.
Definition: ERF_TurbStruct.H:877
LESType les_type
Selected LES closure.
Definition: ERF_TurbStruct.H:826
bool use_kturb
Whether any turbulence model is active.
Definition: ERF_TurbStruct.H:977
PBLType pbl_type
Selected PBL closure.
Definition: ERF_TurbStruct.H:909

Referenced by erf_slow_rhs_pre().

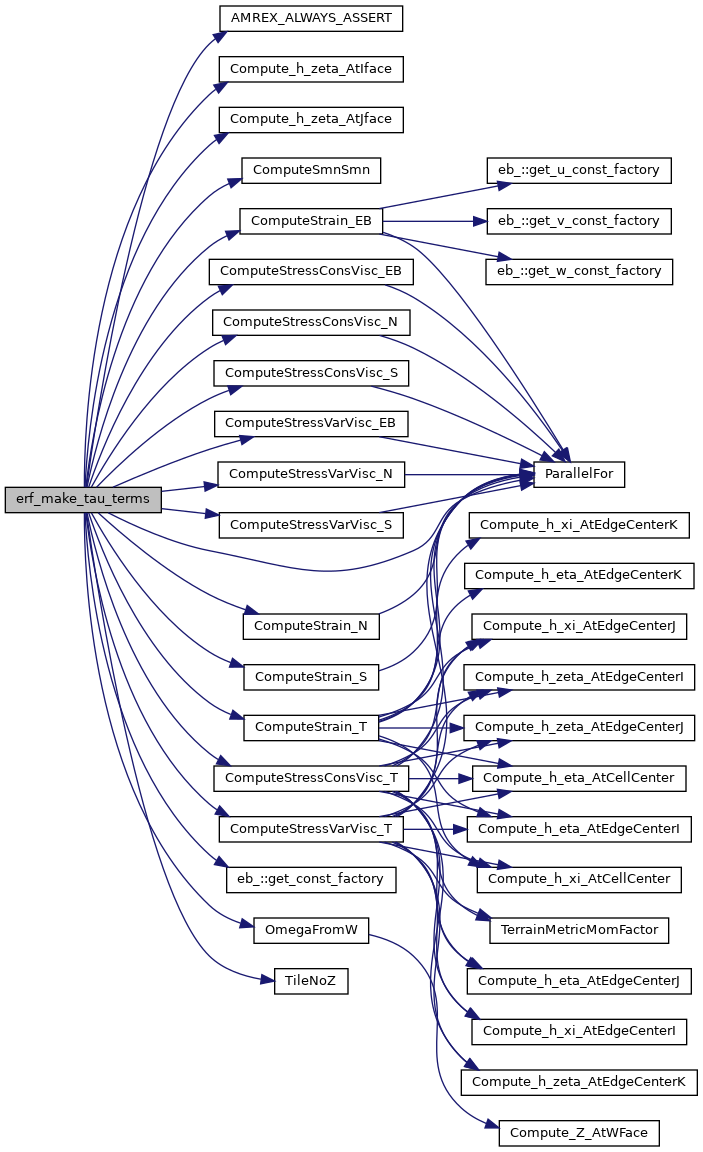
Here is the call graph for this function:
Here is the caller graph for this function: