ERF
Energy Research and Forecasting: An Atmospheric Modeling Code
ERF_ImplicitDiff_N.cpp File Reference
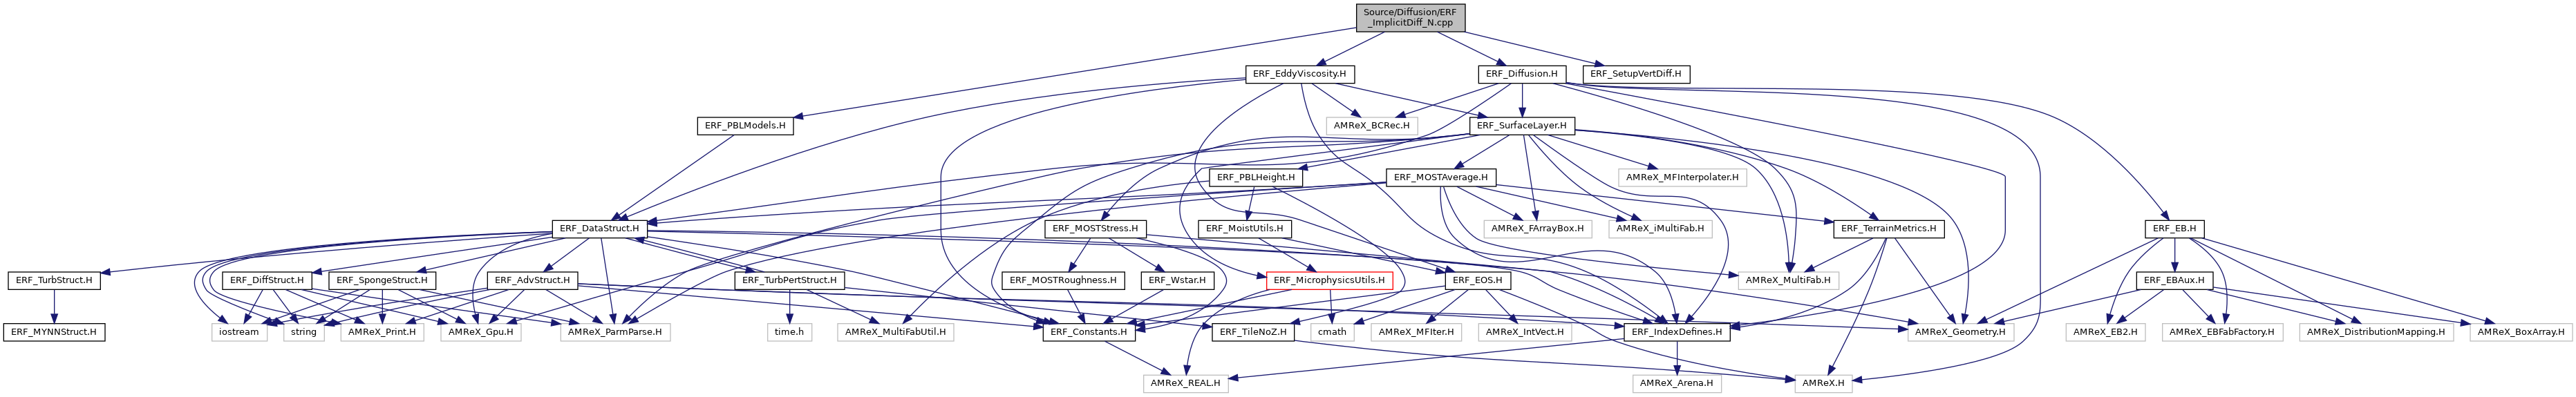
Include dependency graph for ERF_ImplicitDiff_N.cpp:
Macros

#define INSTANTIATE_IMPLICIT_DIFF_FOR_MOM_LU(STAGDIR)
 

Functions

void ImplicitDiffForStateLU_N (const Box &bx, const Box &domain, const int level, const int n, const double dt_d, const GpuArray< Real, AMREX_SPACEDIM *2 > &bc_neumann_vals, const Array4< Real > &cell_data, const GpuArray< Real, AMREX_SPACEDIM > &cellSizeInv, const Array4< const Real > &scalar_zflux, const Array4< const Real > &mu_turb, const SolverChoice &solverChoice, const BCRec *bc_ptr, const bool use_SurfLayer, const Real implicit_fac, const bool use_mrf_countergradient)
 
template<int stagdir>
void ImplicitDiffForMomLU_N (const Box &bx, const Box &domain, const int level, const double dt_d, const Array4< const int > &col_kext, const Array4< const Real > &cell_data, const Array4< Real > &face_data, const Array4< const Real > &tau, const Array4< const Real > &tau_corr, const GpuArray< Real, AMREX_SPACEDIM > &cellSizeInv, const Array4< const Real > &mu_turb, const SolverChoice &solverChoice, const BCRec *bc_ptr, const bool use_SurfLayer, const Real implicit_fac, const bool use_ysu_mom_countergradient)
 

Macro Definition Documentation

◆ INSTANTIATE_IMPLICIT_DIFF_FOR_MOM_LU

#define INSTANTIATE_IMPLICIT_DIFF_FOR_MOM_LU (   STAGDIR)
Value:
template void ImplicitDiffForMomLU_N<STAGDIR> ( \
const Box&, \
const Box&, \
const int, \
const double, \
const Array4<const int >&, \
const Array4<const Real>&, \
const Array4< Real>&, \
const Array4<const Real>&, \
const GpuArray<Real, AMREX_SPACEDIM>&, \
const Array4<const Real>&, \
const SolverChoice&, \
const BCRec*, \
const bool, \
const Real, \
const bool);
amrex::Real Real
Definition: ERF_ShocInterface.H:19
Definition: ERF_DataStruct.H:662

Function Documentation

◆ ImplicitDiffForMomLU_N()

template<int stagdir>
void ImplicitDiffForMomLU_N ( const Box &  bx,
const Box &  domain,
const int  level,
const double  dt_d,
const Array4< const int > &  col_kext,
const Array4< const Real > &  cell_data,
const Array4< Real > &  face_data,
const Array4< const Real > &  tau,
const Array4< const Real > &  tau_corr,
const GpuArray< Real, AMREX_SPACEDIM > &  cellSizeInv,
const Array4< const Real > &  mu_turb,
const SolverChoice solverChoice,
const BCRec *  bc_ptr,
const bool  use_SurfLayer,
const Real  implicit_fac,
const bool  use_ysu_mom_countergradient 
)

Function for computing the implicit contribution to the vertical diffusion of momentum, with a uniform grid and no terrain.

This function (explicitly instantiated below) handles staggering in x, y, or z through the template parameter, stagdir.

Parameters
[in]bxcell-centered box to loop over
[in]levelAMR level
[in]dt_dtime step
[in]cell_dataconserved cell-centered rho
[in,out]face_dataconserved momentum
[in]taustress contribution to momentum
[in]tau_corrstress contribution to momentum that will be corrected by the implicit solve
[in]cellSizeInvinverse cell size array
[in]mu_turbturbulent viscosity
[in]solverChoicecontainer of parameters
[in]bc_ptrcontainer with boundary conditions
[in]use_SurfLayerwhether we have turned on subgrid diffusion
[in]implicit_facif 1 then fully implicit; if 0 then fully explicit
[in]use_ysu_mom_countergradientwhether to include YSU momentum countergradient correction
289 {
290  BL_PROFILE_VAR("ImplicitDiffForMom_N()",ImplicitDiffForMom_N);
291 
292  Real dt = static_cast<Real>(dt_d);
293 
294  // setup quantities for getRhoAlphaAtFaces()
295  DiffChoice dc = solverChoice.diffChoice;
296  TurbChoice tc = solverChoice.turbChoice[level];
297  bool l_consA = (dc.molec_diff_type == MolecDiffType::ConstantAlpha);
298  bool l_turb = tc.use_kturb;
299  // The off-diagonal correction strains for u/v contain a factor of 1/2,
300  // while the diagonal correction strain for w does not.
301  constexpr Real molec_fac = (stagdir == 2) ? two : one;
302  Real mu_eff = (l_consA) ? molec_fac * dc.dynamic_viscosity / dc.rho0_trans
303  : molec_fac * dc.dynamic_viscosity;
304 
305  // g(S*) coefficient
306  // stagdir==0: tau_corr = myhalf * du/dz * mu_tot
307  // stagdir==1: tau_corr = myhalf * dv/dz * mu_tot
308  // stagdir==2: tau_corr = dw/dz * mu_tot
309  constexpr Real gfac = (stagdir == 2) ? two/three : one;
310 
311  // offsets used to average to faces
312  constexpr int ioff = (stagdir == 0) ? 1 : 0;
313  constexpr int joff = (stagdir == 1) ? 1 : 0;
314 
315  // Box bounds
316  int ilo = bx.smallEnd(0);
317  int ihi = bx.bigEnd(0);
318  int jlo = bx.smallEnd(1);
319  int jhi = bx.bigEnd(1);
320  int box_klo = bx.smallEnd(2);
321  int box_khi = bx.bigEnd(2);
322  amrex::ignore_unused(ilo, ihi, jlo, jhi);
323 
324  // Vertical staggering of this component, and the vertical extent of the domain for the
325  // faces we are solving on. A column whose top or bottom is not the domain boundary ends
326  // at a coarse/fine boundary instead, and must not be given a physical BC row.
327  constexpr int knodal = (stagdir == 2) ? 1 : 0;
328  const int dom_klo = domain.smallEnd(2);
329  const int dom_khi = domain.bigEnd(2) + knodal;
330 
331  // Temporary FABs for tridiagonal solve (allocated on column)
332  // A[k] * x[k-1] + B[k] * x[k] + C[k+1] = RHS[k]
333  amrex::FArrayBox RHS_fab, soln_fab, coeffG_fab;
334  RHS_fab.resize(bx,1, amrex::The_Async_Arena());
335  soln_fab.resize(bx,1, amrex::The_Async_Arena());
336  coeffG_fab.resize(bx,1, amrex::The_Async_Arena());
337  auto const& RHS_a = RHS_fab.array();
338  auto const& soln_a = soln_fab.array();
339  auto const& coeffG_a = coeffG_fab.array();
340 
341  Real dz_inv = cellSizeInv[2];
342 
343  int bc_comp = BCVars::xvel_bc + stagdir;
344  bool ext_dir_on_zlo = (bc_ptr[bc_comp].lo(2) == ERFBCType::ext_dir ||
345  bc_ptr[bc_comp].lo(2) == ERFBCType::ext_dir_prim);
346  bool ext_dir_on_zhi = (bc_ptr[bc_comp].hi(2) == ERFBCType::ext_dir ||
347  bc_ptr[bc_comp].hi(2) == ERFBCType::ext_dir_prim);
348  bool foextrap_on_zlo = (bc_ptr[bc_comp].lo(2) == ERFBCType::foextrap);
349  bool foextrap_on_zhi = (bc_ptr[bc_comp].hi(2) == ERFBCType::foextrap);
350  amrex::ignore_unused(foextrap_on_zlo,foextrap_on_zhi);
351 
352  AMREX_ASSERT_WITH_MESSAGE(foextrap_on_zlo || ext_dir_on_zlo || use_SurfLayer,
353  "Unexpected lower BC for momentum used with implicit vertical diffusion");
354  AMREX_ASSERT_WITH_MESSAGE(foextrap_on_zhi || ext_dir_on_zhi,
355  "Unexpected upper BC for momentum used with implicit vertical diffusion");
356 
357  Real Fact = implicit_fac * dt * dz_inv;
358 
359 #ifdef AMREX_USE_GPU
360  ParallelFor(makeSlab(bx,2,0), [=] AMREX_GPU_DEVICE (int i, int j, int)
361  {
362 #else
363  for (int j(jlo); j<=jhi; ++j) {
364  for (int i(ilo); i<=ihi; ++i) {
365 #endif
366 
367  // The face column at (i,j) is shared by the two cell columns on either side of it,
368  // and so by the box on either side of a grid seam. Solve only over the vertical
369  // range that both of those cell columns cover: the boxes on the two sides then
370  // build the same tridiagonal system and get the same answer, so the duplicated
371  // faces along the seam stay consistent. Faces outside that range sit on a lateral
372  // coarse/fine boundary and are set from the coarse level, so it is consistent to
373  // leave them to the explicit update.
374  const int klo = amrex::max(box_klo, col_kext(i-ioff,j-joff,0,0),
375  col_kext(i ,j ,0,0));
376  const int khi = amrex::min(box_khi, col_kext(i-ioff,j-joff,0,1)+knodal,
377  col_kext(i ,j ,0,1)+knodal);
378 
379  // Fewer than two faces in common -- nothing to invert, leave the column explicit
380 #ifdef AMREX_USE_GPU
381  if (khi <= klo) { return; }
382 #else
383  if (khi <= klo) { continue; }
384 #endif
385  // Notes:
386  //
387  // - In DiffusionSrcForMom (e.g., for x-mom)
388  //
389  // Real diffContrib = ...
390  // + (tau13(i,j,k+1) - tau13(i,j,k)) / dzinv
391  // rho_u_rhs(i,j,k) -= diffContrib; // note the negative sign
392  //
393  // - We need to scale the explicit _part_ of `tau13` (for x-mom) by (1 - implicit_fac)
394  // The part that needs to be scaled is stored in `tau_corr`.
395  // E.g., tau13 = 0.5 * (du/dz + dw/dx)
396  // tau13_corr = 0.5 * du/dz
397  //
398  // - The momentum (`face_data`) was set to `S_old + S_rhs * dt`
399  // prior to including "ERF_Implicit.H". Recall that S_rhs includes
400  // sources from advection and other forcings, not just diffusion.
401  //
402  // - To correct momentum, we need to subtract `implicit_fac * diffContrib_corr`
403  // from S_rhs to recover `(1 - implicit_fac) * diffContrib_corr`,
404  // where `diffContrib_corr = -d(tau_corr)/dz`. The negative sign
405  // comes from our convention for the RHS diffusion source.
406  //
407  // Subtracting a negative gives the += below; multiply by dt to
408  // get the intermediate momentum on the RHS of the tridiagonal
409  // system.
410  //
411  // - With a surface_layer BC, tau13/23 holds the vertical flux -d_z(k*u_i)
412  // directly. We must use tau at klo (not tau_corr) with SL BCs.
413  //
414  // - Finally, the terms ~ RHS += (tau_corr_hi - tau_corr_lo) / dz (below)
415  // essentially undo the explicit diffusion update that will be
416  // handled here implicitly.
417 
418  // Bottom boundary coefficients and RHS for L decomp
419  //===================================================
420  Real rhoface, rhoAlpha_lo, rhoAlpha_hi;
421  Real a_tmp, b_tmp, c_tmp, inv_b2_tmp;
422  {
423  rhoface = myhalf * (cell_data(i,j,klo,Rho_comp) + cell_data(i-ioff,j-joff,klo,Rho_comp));
424  getRhoAlphaForFaces(i, j, klo, ioff, joff, rhoAlpha_lo, rhoAlpha_hi,
425  cell_data, mu_turb, mu_eff,
426  l_consA, l_turb);
427 
428  a_tmp = zero;
429  c_tmp = -Fact * gfac * rhoAlpha_hi * dz_inv;
430 
431  RHS_a(i,j,klo) = face_data(i,j,klo); // NOTE: this is momenta; solution is velocity
432 
433  // BCs: Dirichlet (u_i = val), slip wall (w = 0), or surface layer (w = 0) --
434  // but only where the bottom of this column really is the domain boundary
435  if (klo != dom_klo) {
436  // Coarse/fine (or grid) boundary: close the system with the known face value
437  // below instead of imposing a physical BC at an interior height
438  a_tmp = -Fact * rhoAlpha_lo * dz_inv;
439  RHS_a(i,j,klo) += Fact * gfac * (tau_corr(i,j,klo+1) - tau_corr(i,j,klo));
440  const Real rho_below = myhalf * ( cell_data(i ,j ,klo-1,Rho_comp)
441  + cell_data(i-ioff,j-joff,klo-1,Rho_comp) );
442  RHS_a(i,j,klo) -= a_tmp * (face_data(i,j,klo-1) / rho_below);
443  } else if (ext_dir_on_zlo) {
444  RHS_a(i,j,klo) += Fact * gfac * (tau_corr(i,j,klo+1) - tau_corr(i,j,klo));
445  if (stagdir==2) {
446  c_tmp = zero;
447  RHS_a(i,j,klo) = zero;
448  } else {
449  // NOTE: wall is 1/2 dz away (2 dz_inv)
450  a_tmp = -two * Fact * rhoAlpha_lo * dz_inv;
451  const Real rho_wall = myhalf * ( cell_data(i ,j ,klo-1,Rho_comp)
452  + cell_data(i-ioff,j-joff,klo-1,Rho_comp) );
453  const Real wall_velocity = face_data(i,j,klo-1) / rho_wall;
454  RHS_a(i,j,klo) -= a_tmp * wall_velocity;
455  }
456  } else if (use_SurfLayer) {
457  // NOTE: tau = -mu*d_z(u_i) w/ SL
458  RHS_a(i,j,klo) += Fact * gfac * (tau_corr(i,j,klo+1) - tau(i,j,klo));
459  RHS_a(i,j,klo) += Fact * tau(i,j,klo);
460  } else {
461  // NOTE: FOEXTRAP has zero lower flux (nothing to add to RHS)
462  RHS_a(i,j,klo) += Fact * gfac * (tau_corr(i,j,klo+1) - tau_corr(i,j,klo));
463  }
464 
465  // Add YSU momentum countergradient correction at bottom boundary.
466  // NOTE: As for the scalars, the lower face at klo carries no
467  // countergradient flux -- the surface stress is supplied by the
468  // surface layer model or the wall BC above. Only the upper face
469  // contributes here.
470  // NOTE: The sign matches the scalar path: tau_i3 = -rho*K*(du_i/dz - gamma_i),
471  // so the countergradient piece of the flux is +rho*K*gamma_i and its
472  // divergence enters the RHS with a minus sign.
473  if (use_ysu_mom_countergradient && stagdir < 2) {
474  const int hgam_comp = (stagdir == 0) ? EddyDiff::HGAMU_v : EddyDiff::HGAMV_v;
475  // Average HGAM* to the staggered face
476  const Real gam_klo = myhalf * (mu_turb(i,j,klo ,hgam_comp) + mu_turb(i-ioff,j-joff,klo ,hgam_comp));
477  const Real gam_kp1 = myhalf * (mu_turb(i,j,klo+1,hgam_comp) + mu_turb(i-ioff,j-joff,klo+1,hgam_comp));
478  const Real gam_hi = myhalf * (gam_klo + gam_kp1);
479  RHS_a(i,j,klo) -= Fact * rhoAlpha_hi * gam_hi;
480  }
481 
482  b_tmp = rhoface - a_tmp - c_tmp;
483  inv_b2_tmp = one;
484 
485  RHS_a(i,j,klo) /= b_tmp; // NOTE: this is now "rho"
486  coeffG_a(i,j,klo) = c_tmp / b_tmp; // NOTE: this is now "gamma"
487  }
488 
489  // Build the coefficients and RHS for L decomp
490  //===================================================
491  for (int k(klo+1); k < khi; k++) {
492  rhoface = myhalf * (cell_data(i,j,k,Rho_comp) + cell_data(i-ioff,j-joff,k,Rho_comp));
493  getRhoAlphaForFaces(i, j, k, ioff, joff, rhoAlpha_lo, rhoAlpha_hi,
494  cell_data, mu_turb, mu_eff,
495  l_consA, l_turb);
496 
497  a_tmp = -Fact * rhoAlpha_lo * dz_inv;
498  c_tmp = -Fact * rhoAlpha_hi * dz_inv;
499  b_tmp = rhoface - a_tmp - c_tmp;
500  inv_b2_tmp = one/ (b_tmp - a_tmp * coeffG_a(i,j,k-1));
501 
502  RHS_a(i,j,k) = face_data(i,j,k); // NOTE: this is momenta; solution is velocity
503  RHS_a(i,j,k) += Fact * gfac * (tau_corr(i,j,k+1) - tau_corr(i,j,k));
504 
505  // Add YSU momentum countergradient correction
506  if (use_ysu_mom_countergradient && stagdir < 2) {
507  const int hgam_comp = (stagdir == 0) ? EddyDiff::HGAMU_v : EddyDiff::HGAMV_v;
508  // Average HGAM* to the staggered face
509  const Real gam_k = myhalf * (mu_turb(i,j,k ,hgam_comp) + mu_turb(i-ioff,j-joff,k ,hgam_comp));
510  const Real gam_km1 = myhalf * (mu_turb(i,j,k-1,hgam_comp) + mu_turb(i-ioff,j-joff,k-1,hgam_comp));
511  const Real gam_kp1 = myhalf * (mu_turb(i,j,k+1,hgam_comp) + mu_turb(i-ioff,j-joff,k+1,hgam_comp));
512  const Real gam_hi = myhalf * (gam_k + gam_kp1); // at k+1/2
513  const Real gam_lo = myhalf * (gam_k + gam_km1); // at k-1/2
514  RHS_a(i,j,k) -= Fact * (rhoAlpha_hi * gam_hi - rhoAlpha_lo * gam_lo);
515  }
516 
517  RHS_a(i,j,k) = (RHS_a(i,j,k) - a_tmp * RHS_a(i,j,k-1)) * inv_b2_tmp; // NOTE: This is now "rho"
518  coeffG_a(i,j,k) = c_tmp * inv_b2_tmp; // NOTE: this is now "gamma"
519  } // k
520 
521  // Top boundary coefficients and RHS for L decomp
522  //===================================================
523  {
524  rhoface = myhalf * (cell_data(i,j,khi,Rho_comp) + cell_data(i-ioff,j-joff,khi,Rho_comp));
525  getRhoAlphaForFaces(i, j, khi, ioff, joff, rhoAlpha_lo, rhoAlpha_hi,
526  cell_data, mu_turb, mu_eff,
527  l_consA, l_turb);
528 
529  a_tmp = -Fact * gfac * rhoAlpha_lo * dz_inv;
530  c_tmp = zero;
531 
532  RHS_a(i,j,khi) = face_data(i,j,khi); // NOTE: this is momenta; solution is velocity
533  RHS_a(i,j,khi) += Fact * gfac * (tau_corr(i,j,khi+1) - tau_corr(i,j,khi));
534 
535  // BCs: Dirichlet (u_i = val), slip wall (w = 0) --
536  // but only where the top of this column really is the domain boundary
537  if (khi != dom_khi) {
538  // Coarse/fine (or grid) boundary: close the system with the known face value
539  // above instead of imposing a physical BC at an interior height
540  c_tmp = -Fact * rhoAlpha_hi * dz_inv;
541  const Real rho_above = myhalf * ( cell_data(i ,j ,khi+1,Rho_comp)
542  + cell_data(i-ioff,j-joff,khi+1,Rho_comp) );
543  RHS_a(i,j,khi) -= c_tmp * (face_data(i,j,khi+1) / rho_above);
544  } else if (ext_dir_on_zhi) {
545  if (stagdir==2) {
546  a_tmp = zero;
547  RHS_a(i,j,khi) = zero;
548  } else {
549  // NOTE: wall is 1/2 dz away (2 dz_inv)
550  c_tmp = -two * Fact * rhoAlpha_hi * dz_inv;
551  const Real rho_wall = myhalf * ( cell_data(i ,j ,khi+1,Rho_comp)
552  + cell_data(i-ioff,j-joff,khi+1,Rho_comp) );
553  const Real wall_velocity = face_data(i,j,khi+1) / rho_wall;
554  RHS_a(i,j,khi) -= c_tmp * wall_velocity;
555  }
556  }
557 
558  b_tmp = rhoface - a_tmp - c_tmp;
559  inv_b2_tmp = one/ (b_tmp - a_tmp * coeffG_a(i,j,khi-1));
560 
561  // First solve
562  soln_a(i,j,khi) = (RHS_a(i,j,khi) - a_tmp * RHS_a(i,j,khi-1)) * inv_b2_tmp;
563  }
564 
565  // Back sweep the U decomp solution
566  //===================================================
567  for (int k(khi-1); k>=klo; --k) {
568  soln_a(i,j,k) = RHS_a(i,j,k) - coeffG_a(i,j,k) * soln_a(i,j,k+1);
569  }
570 
571  // Convert back to momenta
572  //===================================================
573  for (int k(klo); k<=khi; ++k) {
574  rhoface = myhalf * (cell_data(i,j,k,Rho_comp) + cell_data(i-ioff,j-joff,k,Rho_comp));
575  face_data(i,j,k) = rhoface * soln_a(i,j,k);
576  }
577 
578 #ifdef AMREX_USE_GPU
579  });
580 #else
581  } // i
582  } // j
583 #endif
584 }
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void getRhoAlphaForFaces(int i, int j, int k, int ioff, int joff, amrex::Real &rhoAlpha_lo, amrex::Real &rhoAlpha_hi, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &mu_turb, const amrex::Real mu_eff, bool l_consA, bool l_turb)
Definition: ERF_GetRhoAlphaForFaces.H:22
#define Rho_comp
Definition: ERF_IndexDefines.H:39
const int klo
Definition: ERF_InitCustomPert_ABL.H:75
const int khi
Definition: ERF_InitCustomPert_Bubble.H:21
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
constexpr amrex::Real three
Definition: ERF_NumericalConstants.H:32
constexpr amrex::Real two
Definition: ERF_NumericalConstants.H:31
constexpr amrex::Real one
Definition: ERF_NumericalConstants.H:30
constexpr amrex::Real zero
Definition: ERF_NumericalConstants.H:29
constexpr amrex::Real myhalf
Definition: ERF_NumericalConstants.H:34
AMREX_ASSERT_WITH_MESSAGE(wbar_cutoff_min > wbar_cutoff_max, "ERROR: wbar_cutoff_min < wbar_cutoff_max")
@ xvel_bc
Definition: ERF_IndexDefines.H:105
@ foextrap
Definition: ERF_IndexDefines.H:296
@ ext_dir
Definition: ERF_IndexDefines.H:297
@ ext_dir_prim
Definition: ERF_IndexDefines.H:300
@ HGAMU_v
Definition: ERF_IndexDefines.H:262
@ HGAMV_v
Definition: ERF_IndexDefines.H:263
Definition: ERF_DiffStruct.H:22
MolecDiffType molec_diff_type
Selected molecular transport model.
Definition: ERF_DiffStruct.H:94
amrex::Real dynamic_viscosity
Dynamic viscosity for momentum diffusion [kg/(m-s)].
Definition: ERF_DiffStruct.H:106
amrex::Real rho0_trans
Reference density used to compute dynamic diffusion coefficients [kg/m3].
Definition: ERF_DiffStruct.H:101
amrex::Vector< TurbChoice > turbChoice
Turbulence options for each AMR level.
Definition: ERF_DataStruct.H:1974
DiffChoice diffChoice
Diffusion-related options.
Definition: ERF_DataStruct.H:1971
Definition: ERF_TurbStruct.H:115
bool use_kturb
Whether any turbulence model is active.
Definition: ERF_TurbStruct.H:835
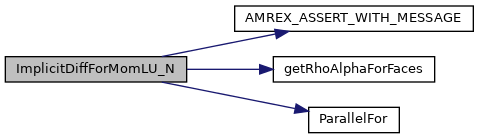
Here is the call graph for this function:
◆ ImplicitDiffForStateLU_N()

void ImplicitDiffForStateLU_N ( const Box &  bx,
const Box &  domain,
const int  level,
const int  n,
const double  dt_d,
const GpuArray< Real, AMREX_SPACEDIM *2 > &  bc_neumann_vals,
const Array4< Real > &  cell_data,
const GpuArray< Real, AMREX_SPACEDIM > &  cellSizeInv,
const Array4< const Real > &  scalar_zflux,
const Array4< const Real > &  mu_turb,
const SolverChoice solverChoice,
const BCRec *  bc_ptr,
const bool  use_SurfLayer,
const Real  implicit_fac,
const bool  use_mrf_countergradient 
)

Function for computing the implicit contribution to the vertical diffusion of theta, with a uniform grid, no terrain, and LU decomposition.

Parameters
[in]bxcell-centered box to loop over
[in]levelAMR level
[in]domainbox of the whole domain
[in]nconserved component index
[in]dt_dtime step
[in]bc_neumann_valsvalues of derivatives if bc_type == Neumann
[in,out]cell_dataconserved cell-centered rho, rho theta
[in]cellSizeInvinverse cell size array
[in]scalar_zfluxscalar vertical flux in z-dir
[in]mu_turbturbulent viscosity
[in]solverChoicecontainer of parameters
[in]bc_ptrcontainer with boundary conditions
[in]use_SurfLayerwhether we have turned on subgrid diffusion
[in]implicit_facif 1 then fully implicit; if 0 then fully explicit
[in]use_mrf_countergradientwhether to include MRF countergradient correction
46 {
47  BL_PROFILE_VAR("ImplicitDiffForState_N()",ImplicitDiffForState_N);
48 
49  Real dt = static_cast<Real>(dt_d);
50 
51  // setup quantities for getRhoAlpha()
52 #include "ERF_SetupVertDiff.H"
53  const int qty_index = n;
54  const int prim_index = qty_index - 1;
55  const int prim_scal_index = (qty_index >= RhoScalar_comp && qty_index < RhoScalar_comp+NSCALARS) ? PrimScalar_comp : prim_index;
56 
57  // Box bounds
58  int ilo = bx.smallEnd(0);
59  int ihi = bx.bigEnd(0);
60  int jlo = bx.smallEnd(1);
61  int jhi = bx.bigEnd(1);
62  int klo = bx.smallEnd(2);
63  int khi = bx.bigEnd(2);
64  amrex::ignore_unused(ilo, ihi, jlo, jhi);
65 
66  // Temporary FABs for tridiagonal solve (allocated on column)
67  // A[k] * x[k-1] + B[k] * x[k] + C[k+1] = RHS[k]
68 
69  // With LU decomposition, M * x = r is written as L * U * x = r with U * x = rho
70  // We then first have L * rho = r and U * x = rho
71  amrex::FArrayBox RHS_fab, soln_fab, coeffG_fab;
72  RHS_fab.resize(bx,1, amrex::The_Async_Arena());
73  soln_fab.resize(bx,1, amrex::The_Async_Arena());
74  coeffG_fab.resize(bx,1, amrex::The_Async_Arena());
75  auto const& RHS_a = RHS_fab.array();
76  auto const& soln_a = soln_fab.array();
77  auto const& coeffG_a = coeffG_fab.array();
78 
79  Real dz_inv = cellSizeInv[2];
80 
81  int bc_comp = qty_index;
82  bool foextrap_on_zlo = (bc_ptr[bc_comp].lo(2) == ERFBCType::foextrap);
83  bool foextrap_on_zhi = (bc_ptr[bc_comp].hi(2) == ERFBCType::foextrap);
84  bool neumann_on_zlo = (bc_ptr[bc_comp].lo(2) == ERFBCType::neumann);
85  bool neumann_on_zhi = (bc_ptr[bc_comp].hi(2) == ERFBCType::neumann);
86  amrex::ignore_unused(foextrap_on_zlo, foextrap_on_zhi);
87 
88  AMREX_ASSERT_WITH_MESSAGE(foextrap_on_zlo || neumann_on_zlo || use_SurfLayer,
89  "Unexpected lower BC for scalars used with implicit vertical diffusion");
90  AMREX_ASSERT_WITH_MESSAGE(foextrap_on_zhi || neumann_on_zhi,
91  "Unexpected upper BC for scalars used with implicit vertical diffusion");
92 
93  // k-eqn RANS with a Dirichlet wall value of k: the first cell is held at
94  // the value set by the surface layer, so its row reduces to x(klo) = phi(klo)
95  // and the row above sees it as a Dirichlet neighbour.
96  // NOTE: init_bcs requires zlo.type = surface_layer whenever dirichlet_k is set,
97  // so this matches the l_dirichlet_k pin in erf_slow_rhs_post, which also
98  // requires a surface layer. Do not relax one without the other.
99  const bool pin_klo = (qty_index == RhoKE_comp) && (klo == domain.smallEnd(2)) &&
100  (solverChoice.turbChoice[level].rans_type == RANSType::kEqn) &&
101  solverChoice.turbChoice[level].dirichlet_k;
102 
103  // A column whose bottom or top is not the domain boundary ends at a coarse/fine boundary
104  // instead. There the system must be closed with the value on the other side of that
105  // boundary rather than given a physical BC row at an interior height, so that the answer
106  // does not depend on where the grid happens to end in the vertical.
107  const bool at_zlo = (klo == domain.smallEnd(2));
108  const bool at_zhi = (khi == domain.bigEnd(2));
109 
110  Real Fact = implicit_fac * dt * dz_inv;
111 
112 #ifdef AMREX_USE_GPU
113  ParallelFor(makeSlab(bx,2,0), [=] AMREX_GPU_DEVICE (int i, int j, int)
114  {
115 #else
116  for (int j(jlo); j<=jhi; ++j) {
117  for (int i(ilo); i<=ihi; ++i) {
118 #endif
119  // Bottom boundary coefficients and RHS for L decomp
120  //===================================================
121  Real rhoAlpha_lo, rhoAlpha_hi;
122  Real a_tmp, b_tmp, c_tmp, inv_b2_tmp;
123  {
124  getRhoAlpha(i, j, klo, rhoAlpha_lo, rhoAlpha_hi,
125  cell_data, mu_turb, d_alpha_eff, d_eddy_diff_idz,
126  prim_index, prim_scal_index, l_consA, l_turb);
127 
128  a_tmp = zero;
129  if (!at_zlo) { a_tmp = -Fact * rhoAlpha_lo * dz_inv; }
130  c_tmp = (pin_klo) ? zero : -Fact * rhoAlpha_hi * dz_inv;
131  b_tmp = cell_data(i,j,klo,Rho_comp) - a_tmp - c_tmp;
132  inv_b2_tmp = one;
133 
134  RHS_a(i,j,klo) = cell_data(i,j,klo,n); // NOTE: this is rho*phi; solution is phi
135  if (!at_zlo) {
136  // Coarse/fine boundary: close the system with the known value below
137  RHS_a(i,j,klo) -= a_tmp * (cell_data(i,j,klo-1,n) / cell_data(i,j,klo-1,Rho_comp));
138  } else if (pin_klo) {
139  // Dirichlet row: no flux terms
140  } else if (use_SurfLayer && scalar_zflux) {
141  RHS_a(i,j,klo) += Fact * scalar_zflux(i,j,klo); // NOTE: scalar_zflux = -K*d_z(\phi)
142  } else if (neumann_on_zlo) {
143  RHS_a(i,j,klo) += -Fact * rhoAlpha_lo * bc_neumann_vals[2]; // NOTE: N_val = d_z(\phi)
144  }
145 
146  // Add countergradient correction to RHS at bottom boundary.
147  // NOTE: The lower face at klo carries no countergradient flux -- the
148  // total surface flux is supplied by the surface layer model or the
149  // Neumann BC, while gamma represents nonlocal transport interior to
150  // the PBL. Only the upper face contributes here.
151  if (use_mrf_countergradient && (n == RhoTheta_comp || n == RhoQ1_comp)) {
152  const int gam_comp = (n == RhoTheta_comp) ? EddyDiff::HGAMT_v : EddyDiff::HGAMQ_v;
153  const Real gam_hi = myhalf * (mu_turb(i, j, klo, gam_comp) + mu_turb(i, j, klo+1, gam_comp));
154  RHS_a(i,j,klo) -= Fact * rhoAlpha_hi * gam_hi;
155  if (!at_zlo) {
156  const Real gam_lo = myhalf * (mu_turb(i, j, klo, gam_comp) + mu_turb(i, j, klo-1, gam_comp));
157  RHS_a(i,j,klo) += Fact * rhoAlpha_lo * gam_lo;
158  }
159  }
160 
161  RHS_a(i,j,klo) /= b_tmp; // NOTE: this is now "rho"
162  coeffG_a(i,j,klo) = c_tmp / b_tmp; // NOTE: this is now "gamma"
163  }
164 
165  // Build the coefficients and RHS for L decomp
166  //===================================================
167  for (int k(klo+1); k < khi; k++) {
168  getRhoAlpha(i, j, k, rhoAlpha_lo, rhoAlpha_hi,
169  cell_data, mu_turb, d_alpha_eff, d_eddy_diff_idz,
170  prim_index, prim_scal_index, l_consA, l_turb);
171 
172  a_tmp = -Fact * rhoAlpha_lo * dz_inv;
173  c_tmp = -Fact * rhoAlpha_hi * dz_inv;
174  b_tmp = cell_data(i,j,k,Rho_comp) - a_tmp - c_tmp;
175  inv_b2_tmp = one / (b_tmp - a_tmp * coeffG_a(i,j,k-1));
176 
177  RHS_a(i,j,k) = cell_data(i,j,k,n); // NOTE: this is rho*phi; solution is phi
178 
179  // Add countergradient correction to RHS in interior
180  if (use_mrf_countergradient && (n == RhoTheta_comp || n == RhoQ1_comp)) {
181  const int gam_comp = (n == RhoTheta_comp) ? EddyDiff::HGAMT_v : EddyDiff::HGAMQ_v;
182  const Real gam_k = mu_turb(i, j, k, gam_comp);
183  const Real gam_km1 = mu_turb(i, j, k-1, gam_comp);
184  const Real gam_kp1 = mu_turb(i, j, k+1, gam_comp);
185  const Real gam_hi = myhalf * (gam_k + gam_kp1); // at k+½
186  const Real gam_lo = myhalf * (gam_k + gam_km1); // at k-½
187  // Countergradient flux divergence (implicit contribution to RHS):
188  // -Fact * [ρα_{k+½}·γ_{k+½} - ρα_{k-½}·γ_{k-½}]
189  RHS_a(i,j,k) -= Fact * (rhoAlpha_hi * gam_hi - rhoAlpha_lo * gam_lo);
190  }
191 
192  RHS_a(i,j,k) = (RHS_a(i,j,k) - a_tmp * RHS_a(i,j,k-1)) * inv_b2_tmp; // NOTE: This is now "rho"
193  coeffG_a(i,j,k) = c_tmp * inv_b2_tmp; // NOTE: this is now "gamma"
194  } // k
195 
196  // Top boundary coefficients and RHS for L decomp
197  //===================================================
198  {
199  getRhoAlpha(i, j, khi, rhoAlpha_lo, rhoAlpha_hi,
200  cell_data, mu_turb, d_alpha_eff, d_eddy_diff_idz,
201  prim_index, prim_scal_index, l_consA, l_turb);
202 
203  a_tmp = -Fact * rhoAlpha_lo * dz_inv;
204  c_tmp = zero;
205  if (!at_zhi) { c_tmp = -Fact * rhoAlpha_hi * dz_inv; }
206  b_tmp = cell_data(i,j,khi,Rho_comp) - a_tmp - c_tmp;
207  inv_b2_tmp = one / (b_tmp - a_tmp * coeffG_a(i,j,khi-1));
208 
209  RHS_a(i,j,khi) = cell_data(i,j,khi,n); // NOTE: this is rho*phi; solution is phi
210  if (!at_zhi) {
211  // Coarse/fine boundary: close the system with the known value above. The
212  // countergradient flux then passes through both faces, as it does in the
213  // interior, rather than only through the lower one.
214  RHS_a(i,j,khi) -= c_tmp * (cell_data(i,j,khi+1,n) / cell_data(i,j,khi+1,Rho_comp));
215  if (use_mrf_countergradient && (n == RhoTheta_comp || n == RhoQ1_comp)) {
216  const int gam_comp = (n == RhoTheta_comp) ? EddyDiff::HGAMT_v : EddyDiff::HGAMQ_v;
217  const Real gam_hi = myhalf * (mu_turb(i, j, khi, gam_comp) + mu_turb(i, j, khi+1, gam_comp));
218  const Real gam_lo = myhalf * (mu_turb(i, j, khi, gam_comp) + mu_turb(i, j, khi-1, gam_comp));
219  RHS_a(i,j,khi) -= Fact * (rhoAlpha_hi * gam_hi - rhoAlpha_lo * gam_lo);
220  }
221  } else if (neumann_on_zhi) {
222  RHS_a(i,j,khi) -= -Fact * rhoAlpha_hi * bc_neumann_vals[5]; // NOTE: N_val = d_z(\phi)
223  }
224 
225  // First solve
226  soln_a(i,j,khi) = (RHS_a(i,j,khi) - a_tmp * RHS_a(i,j,khi-1)) * inv_b2_tmp;
227  }
228 
229  // Back sweep the U decomp solution
230  //===================================================
231  for (int k(khi-1); k>=klo; --k) {
232  soln_a(i,j,k) = RHS_a(i,j,k) - coeffG_a(i,j,k) * soln_a(i,j,k+1);
233  }
234 
235  // Convert back to rho*theta
236  //===================================================
237  for (int k(klo); k<=khi; ++k) {
238  cell_data(i,j,k,n) = cell_data(i,j,k,Rho_comp) * soln_a(i,j,k);
239  }
240 
241 #ifdef AMREX_USE_GPU
242  });
243 #else
244  } // i
245  } // j
246 #endif
247 }
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void getRhoAlpha(int i, int j, int k, amrex::Real &rhoAlpha_lo, amrex::Real &rhoAlpha_hi, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &mu_turb, const amrex::Real *d_alpha_eff, const int *d_eddy_diff_idz, int prim_index, int prim_scal_index, bool l_consA, bool l_turb)
Definition: ERF_GetRhoAlpha.H:20
#define RhoScalar_comp
Definition: ERF_IndexDefines.H:43
#define RhoTheta_comp
Definition: ERF_IndexDefines.H:40
#define NSCALARS
Definition: ERF_IndexDefines.H:16
#define RhoQ1_comp
Definition: ERF_IndexDefines.H:45
#define PrimScalar_comp
Definition: ERF_IndexDefines.H:60
#define RhoKE_comp
Definition: ERF_IndexDefines.H:41
@ neumann
Definition: ERF_IndexDefines.H:302
@ HGAMQ_v
Definition: ERF_IndexDefines.H:261
@ HGAMT_v
Definition: ERF_IndexDefines.H:260
Here is the call graph for this function: