ERF
Energy Research and Forecasting: An Atmospheric Modeling Code
ERF_ImplicitDiff_S.cpp File Reference
Include dependency graph for ERF_ImplicitDiff_S.cpp:

Macros

#define INSTANTIATE_IMPLICIT_DIFF_FOR_MOM_LU(STAGDIR)
 

Functions

void ImplicitDiffForStateLU_S (const Box &bx, const Box &domain, const int level, const int n, const double dt_d, const GpuArray< Real, AMREX_SPACEDIM *2 > &bc_neumann_vals, const Array4< Real > &cell_data, const Gpu::DeviceVector< Real > &stretched_dz_d, const Array4< const Real > &scalar_zflux, const Array4< const Real > &mu_turb, const SolverChoice &solverChoice, const BCRec *bc_ptr, const bool use_SurfLayer, const Real implicit_fac, const bool use_mrf_countergradient)
 
template<int stagdir>
void ImplicitDiffForMomLU_S (const Box &bx, const Box &domain, const int level, const double dt_d, const Array4< const int > &col_kext, const Array4< const Real > &cell_data, const Array4< Real > &face_data, const Array4< const Real > &tau, const Array4< const Real > &tau_corr, const Gpu::DeviceVector< Real > &stretched_dz_d, const Array4< const Real > &mu_turb, const SolverChoice &solverChoice, const BCRec *bc_ptr, const bool use_SurfLayer, const Real implicit_fac, const bool use_ysu_mom_countergradient)
 
void ImplicitVerticalFluxForReflux_S (const Box &bx, const Box &domain, const int level, const int n, const Real implicit_fac, const Array4< const Real > &cell_data, const Gpu::DeviceVector< Real > &stretched_dz_d, const Array4< const Real > &mu_turb, const SolverChoice &solverChoice, const Array4< const Real > &mf_mx, const Array4< const Real > &mf_my, const bool use_mrf_countergradient, const Array4< Real > &zflux)
 

Macro Definition Documentation

◆ INSTANTIATE_IMPLICIT_DIFF_FOR_MOM_LU

#define INSTANTIATE_IMPLICIT_DIFF_FOR_MOM_LU (   STAGDIR)
Value:
template void ImplicitDiffForMomLU_S<STAGDIR> ( \
const Box&, \
const Box&, \
const int, \
const double, \
const Array4<const int >&, \
const Array4<const Real>&, \
const Array4< Real>&, \
const Array4<const Real>&, \
const Gpu::DeviceVector<Real>&, \
const Array4<const Real>&, \
const SolverChoice&, \
const BCRec*, \
const bool, \
const Real, \
const bool);
amrex::Real Real
Definition: ERF_ShocInterface.H:19
Definition: ERF_DataStruct.H:715

Function Documentation

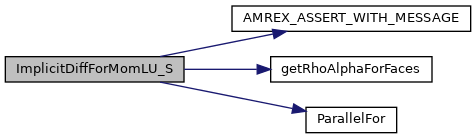
◆ ImplicitDiffForMomLU_S()

template<int stagdir>
void ImplicitDiffForMomLU_S ( const Box &  bx,
const Box &  domain,
const int  level,
const double  dt_d,
const Array4< const int > &  col_kext,
const Array4< const Real > &  cell_data,
const Array4< Real > &  face_data,
const Array4< const Real > &  tau,
const Array4< const Real > &  tau_corr,
const Gpu::DeviceVector< Real > &  stretched_dz_d,
const Array4< const Real > &  mu_turb,
const SolverChoice &  solverChoice,
const BCRec *  bc_ptr,
const bool  use_SurfLayer,
const Real  implicit_fac,
const bool  use_ysu_mom_countergradient 
)

Function for computing the implicit contribution to the vertical diffusion of momentum, with a vertically stretched grid over flat terrain.

This function (explicitly instantiated below) handles staggering in x or y through the template parameter, stagdir.

Parameters
[in]bxcell-centered box to loop over
[in]levelAMR level
[in]dt_dtime step
[in]cell_dataconserved cell-centered rho
[in,out]face_dataconserved momentum
[in]taustress contribution to momentum
[in]tau_corrstress contribution to momentum that will be corrected by the implicit solve
[in]stretched_dz_darray over z of dz[k]
[in]mu_turbturbulent viscosity
[in]solverChoicecontainer of parameters
[in]bc_ptrcontainer with boundary conditions
[in]use_SurfLayerwhether we have turned on subgrid diffusion
[in]implicit_facif 1 then fully implicit; if 0 then fully explicit
[in]use_ysu_mom_countergradientwhether to include YSU momentum countergradient correction
324 {
325  BL_PROFILE_VAR("ImplicitDiffForMom_S()",ImplicitDiffForMom_S);
326 
327  Real dt = static_cast<Real>(dt_d);
328 
329  // setup quantities for getRhoAlphaAtFaces()
330  DiffChoice dc = solverChoice.diffChoice;
331  TurbChoice tc = solverChoice.turbChoice[level];
332  bool l_consA = (dc.molec_diff_type == MolecDiffType::ConstantAlpha);
333  bool l_turb = tc.use_kturb;
334  // The correction strains for u/v contain a factor of 1/2, so mu_eff does not carry
335  // the factor of 2 of the stresses
336  Real mu_eff = (l_consA) ? dc.dynamic_viscosity / dc.rho0_trans
337  : dc.dynamic_viscosity;
338 
339  // offsets used to average to faces
340  constexpr int ioff = (stagdir == 0) ? 1 : 0;
341  constexpr int joff = (stagdir == 1) ? 1 : 0;
342 
343  // Box bounds
344  int ilo = bx.smallEnd(0);
345  int ihi = bx.bigEnd(0);
346  int jlo = bx.smallEnd(1);
347  int jhi = bx.bigEnd(1);
348  int box_klo = bx.smallEnd(2);
349  int box_khi = bx.bigEnd(2);
350  amrex::ignore_unused(ilo, ihi, jlo, jhi);
351 
352  // The vertical extent of the domain. A column whose top or bottom is not the domain
353  // boundary ends at a coarse/fine boundary instead, and must not be given a physical BC row.
354  const int dom_klo = domain.smallEnd(2);
355  const int dom_khi = domain.bigEnd(2);
356 
357  // Temporary FABs for tridiagonal solve (allocated on column)
358  // A[k] * x[k-1] + B[k] * x[k] + C[k+1] = RHS[k]
359  amrex::FArrayBox RHS_fab, soln_fab, coeffG_fab;
360  RHS_fab.resize(bx,1, amrex::The_Async_Arena());
361  soln_fab.resize(bx,1, amrex::The_Async_Arena());
362  coeffG_fab.resize(bx,1, amrex::The_Async_Arena());
363  auto const& RHS_a = RHS_fab.array();
364  auto const& soln_a = soln_fab.array();
365  auto const& coeffG_a = coeffG_fab.array();
366 
367  auto dz_ptr = stretched_dz_d.data();
368 
369  int bc_comp = BCVars::xvel_bc + stagdir;
370  bool ext_dir_on_zlo = (bc_ptr[bc_comp].lo(2) == ERFBCType::ext_dir ||
371  bc_ptr[bc_comp].lo(2) == ERFBCType::ext_dir_prim);
372  bool ext_dir_on_zhi = (bc_ptr[bc_comp].hi(2) == ERFBCType::ext_dir ||
373  bc_ptr[bc_comp].hi(2) == ERFBCType::ext_dir_prim);
374  bool foextrap_on_zlo = (bc_ptr[bc_comp].lo(2) == ERFBCType::foextrap);
375  bool foextrap_on_zhi = (bc_ptr[bc_comp].hi(2) == ERFBCType::foextrap);
376  amrex::ignore_unused(foextrap_on_zlo,foextrap_on_zhi);
377 
378  AMREX_ASSERT_WITH_MESSAGE(foextrap_on_zlo || ext_dir_on_zlo || use_SurfLayer,
379  "Unexpected lower BC for momentum used with implicit vertical diffusion");
380  AMREX_ASSERT_WITH_MESSAGE(foextrap_on_zhi || ext_dir_on_zhi,
381  "Unexpected upper BC for momentum used with implicit vertical diffusion");
382 
383  Real Fact = implicit_fac * dt;
384 
385 #ifdef AMREX_USE_GPU
386  ParallelFor(makeSlab(bx,2,0), [=] AMREX_GPU_DEVICE (int i, int j, int)
387  {
388 #else
389  for (int j(jlo); j<=jhi; ++j) {
390  for (int i(ilo); i<=ihi; ++i) {
391 #endif
392 
393  // The face column at (i,j) is shared by the two cell columns on either side of it,
394  // and so by the box on either side of a grid seam. Solve only over the vertical
395  // range that both of those cell columns cover: the boxes on the two sides then
396  // build the same tridiagonal system and get the same answer, so the duplicated
397  // faces along the seam stay consistent. Faces outside that range sit on a lateral
398  // coarse/fine boundary and are set from the coarse level, so it is consistent to
399  // leave them to the explicit update.
400  const int klo = amrex::max(box_klo, col_kext(i-ioff,j-joff,0,0),
401  col_kext(i ,j ,0,0));
402  const int khi = amrex::min(box_khi, col_kext(i-ioff,j-joff,0,1),
403  col_kext(i ,j ,0,1));
404 
405  // Fewer than two faces in common -- nothing to invert, leave the column explicit
406 #ifdef AMREX_USE_GPU
407  if (khi <= klo) { return; }
408 #else
409  if (khi <= klo) { continue; }
410 #endif
411  // Notes:
412  //
413  // - In DiffusionSrcForMom (e.g., for x-mom)
414  //
415  // Real diffContrib = ...
416  // + (tau13(i,j,k+1) - tau13(i,j,k)) / dzinv
417  // rho_u_rhs(i,j,k) -= diffContrib; // note the negative sign
418  //
419  // - We need to scale the explicit _part_ of `tau13` (for x-mom) by (1 - implicit_fac)
420  // The part that needs to be scaled is stored in `tau_corr`.
421  // E.g., tau13 = myhalf * (du/dz + dw/dx)
422  // tau13_corr = myhalf * du/dz
423  //
424  // - The momentum (`face_data`) was set to `S_old + S_rhs * dt`
425  // prior to including "ERF_Implicit.H". Recall that S_rhs includes
426  // sources from advection and other forcings, not just diffusion.
427  //
428  // - To correct momentum, we need to subtract `implicit_fac * diffContrib_corr`
429  // from S_rhs to recover `(1 - implicit_fac) * diffContrib_corr`,
430  // where `diffContrib_corr = -d(tau_corr)/dz`. The negative sign
431  // comes from our convention for the RHS diffusion source.
432  //
433  // Subtracting a negative gives the += below; multiply by dt to
434  // get the intermediate momentum on the RHS of the tridiagonal
435  // system.
436  //
437  // - With a surface_layer BC, tau13/23 holds the vertical flux -d_z(k*u_i)
438  // directly. We must use tau at klo (not tau_corr) with SL BCs.
439  //
440  // - Finally, the terms ~ RHS += (tau_corr_hi - tau_corr_lo) / dz (below)
441  // essentially undo the explicit diffusion update that will be
442  // handled here implicitly.
443 
444  // Bottom boundary coefficients and RHS for L decomp
445  //===================================================
446  Real rhoface, rhoAlpha_lo, rhoAlpha_hi;
447  Real dz_inv, dz_inv_lo, dz_inv_hi;
448  Real a_tmp, b_tmp, c_tmp, inv_b2_tmp;
449  {
450  rhoface = myhalf * (cell_data(i,j,klo,Rho_comp) + cell_data(i-ioff,j-joff,klo,Rho_comp));
451  getRhoAlphaForFaces(i, j, klo, ioff, joff, rhoAlpha_lo, rhoAlpha_hi,
452  cell_data, mu_turb, mu_eff,
453  l_consA, l_turb);
454 
455  dz_inv = one / dz_ptr[klo];
456  dz_inv_lo = dz_inv;
457  dz_inv_hi = two / (dz_ptr[klo] + dz_ptr[klo+1]);
458 
459  a_tmp = zero;
460  c_tmp = -Fact * rhoAlpha_hi * dz_inv_hi * dz_inv;
461 
462  RHS_a(i,j,klo) = face_data(i,j,klo); // NOTE: this is momenta; solution is velocity
463 
464  // BCs: Dirichlet (u_i = val), slip wall (w = 0), or surface layer (w = 0) --
465  // but only where the bottom of this column really is the domain boundary
466  if (klo != dom_klo) {
467  // Coarse/fine (or grid) boundary: close the system with the known face value
468  // below instead of imposing a physical BC at an interior height
469  dz_inv_lo = two / (dz_ptr[klo] + dz_ptr[klo-1]);
470  a_tmp = -Fact * rhoAlpha_lo * dz_inv_lo * dz_inv;
471  RHS_a(i,j,klo) += Fact * (tau_corr(i,j,klo+1) - tau_corr(i,j,klo)) * dz_inv;
472  const Real rho_below = myhalf * ( cell_data(i ,j ,klo-1,Rho_comp)
473  + cell_data(i-ioff,j-joff,klo-1,Rho_comp) );
474  RHS_a(i,j,klo) -= a_tmp * (face_data(i,j,klo-1) / rho_below);
475  } else if (ext_dir_on_zlo) {
476  RHS_a(i,j,klo) += Fact * (tau_corr(i,j,klo+1) - tau_corr(i,j,klo)) * dz_inv;
477  // Wall stress with the one-sided gradient of ComputeStrain_S,
478  // (c_wall u_wall + c_0 u_0 + c_1 u_1) / dz[klo]: a_tmp multiplies the
479  // wall value, and c_1 adds to the coupling with the cell above
480  const WallGradCoeffs wc = WallGradientCoeffs(dz_ptr[klo], dz_ptr[klo+1]);
481  const Real idz0 = one / dz_ptr[klo];
482  a_tmp = Fact * rhoAlpha_lo * idz0 * dz_inv * wc.c_wall;
483  c_tmp += Fact * rhoAlpha_lo * idz0 * dz_inv * wc.c_1;
484  const Real rho_wall = myhalf * ( cell_data(i ,j ,klo-1,Rho_comp)
485  + cell_data(i-ioff,j-joff,klo-1,Rho_comp) );
486  const Real wall_velocity = face_data(i,j,klo-1) / rho_wall;
487  RHS_a(i,j,klo) -= a_tmp * wall_velocity;
488  } else if (use_SurfLayer) {
489  // NOTE: tau = -mu*d_z(u_i) w/ SL
490  RHS_a(i,j,klo) += Fact * (tau_corr(i,j,klo+1) - tau(i,j,klo)) * dz_inv;
491  RHS_a(i,j,klo) += Fact * dz_inv * tau(i,j,klo);
492  } else {
493  // NOTE: FOEXTRAP has zero lower flux (nothing to add to RHS)
494  RHS_a(i,j,klo) += Fact * (tau_corr(i,j,klo+1) - tau_corr(i,j,klo)) * dz_inv;
495  }
496 
497  // Add YSU momentum countergradient correction at bottom boundary.
498  // NOTE: As for the scalars, the lower face at the domain bottom carries no
499  // countergradient flux -- the surface stress is supplied by the
500  // surface layer model or the wall BC above. At a coarse/fine boundary
501  // the lower face is an interior face and carries it, as in the
502  // interior rows (erf-model/ERF#4822).
503  // NOTE: The sign matches the scalar path: tau_i3 = -rho*K*(du_i/dz - gamma_i),
504  // so the countergradient piece of the flux is +rho*K*gamma_i and its
505  // divergence enters the RHS with a minus sign.
506  if (use_ysu_mom_countergradient) {
507  const int hgam_comp = (stagdir == 0) ? EddyDiff::HGAMU_v : EddyDiff::HGAMV_v;
508  // Average HGAM* to the staggered face
509  const Real gam_klo = myhalf * (mu_turb(i,j,klo ,hgam_comp) + mu_turb(i-ioff,j-joff,klo ,hgam_comp));
510  const Real gam_kp1 = myhalf * (mu_turb(i,j,klo+1,hgam_comp) + mu_turb(i-ioff,j-joff,klo+1,hgam_comp));
511  const Real gam_hi = myhalf * (gam_klo + gam_kp1);
512  RHS_a(i,j,klo) -= Fact * dz_inv * rhoAlpha_hi * gam_hi;
513  if (klo != dom_klo) {
514  const Real gam_km1 = myhalf * (mu_turb(i,j,klo-1,hgam_comp) + mu_turb(i-ioff,j-joff,klo-1,hgam_comp));
515  const Real gam_lo = myhalf * (gam_klo + gam_km1);
516  RHS_a(i,j,klo) += Fact * dz_inv * rhoAlpha_lo * gam_lo;
517  }
518  }
519 
520  b_tmp = rhoface - a_tmp - c_tmp;
521  inv_b2_tmp = one;
522 
523  RHS_a(i,j,klo) /= b_tmp; // NOTE: this is now "rho"
524  coeffG_a(i,j,klo) = c_tmp / b_tmp; // NOTE: this is now "gamma"
525  }
526 
527  // Build the coefficients and RHS for L decomp
528  //===================================================
529  for (int k(klo+1); k < khi; k++) {
530  rhoface = myhalf * (cell_data(i,j,k,Rho_comp) + cell_data(i-ioff,j-joff,k,Rho_comp));
531  getRhoAlphaForFaces(i, j, k, ioff, joff, rhoAlpha_lo, rhoAlpha_hi,
532  cell_data, mu_turb, mu_eff,
533  l_consA, l_turb);
534 
535  dz_inv = one / dz_ptr[k];
536  dz_inv_lo = two / (dz_ptr[k] + dz_ptr[k-1]);
537  dz_inv_hi = two / (dz_ptr[k] + dz_ptr[k+1]);
538 
539  a_tmp = -Fact * rhoAlpha_lo * dz_inv_lo * dz_inv;
540  c_tmp = -Fact * rhoAlpha_hi * dz_inv_hi * dz_inv;
541  b_tmp = rhoface - a_tmp - c_tmp;
542  inv_b2_tmp = one / (b_tmp - a_tmp * coeffG_a(i,j,k-1));
543 
544  RHS_a(i,j,k) = face_data(i,j,k); // NOTE: this is momenta; solution is velocity
545  RHS_a(i,j,k) += Fact * (tau_corr(i,j,k+1) - tau_corr(i,j,k)) * dz_inv;
546 
547  // Add YSU momentum countergradient correction
548  if (use_ysu_mom_countergradient) {
549  const int hgam_comp = (stagdir == 0) ? EddyDiff::HGAMU_v : EddyDiff::HGAMV_v;
550  // AverageHGAM* to the staggered face
551  const Real gam_k = myhalf * (mu_turb(i,j,k ,hgam_comp) + mu_turb(i-ioff,j-joff,k ,hgam_comp));
552  const Real gam_km1 = myhalf * (mu_turb(i,j,k-1,hgam_comp) + mu_turb(i-ioff,j-joff,k-1,hgam_comp));
553  const Real gam_kp1 = myhalf * (mu_turb(i,j,k+1,hgam_comp) + mu_turb(i-ioff,j-joff,k+1,hgam_comp));
554  const Real gam_hi = myhalf * (gam_k + gam_kp1); // at k+1/2
555  const Real gam_lo = myhalf * (gam_k + gam_km1); // at k-1/2
556  RHS_a(i,j,k) -= Fact * dz_inv * (rhoAlpha_hi * gam_hi - rhoAlpha_lo * gam_lo);
557  }
558 
559  RHS_a(i,j,k) = (RHS_a(i,j,k) - a_tmp * RHS_a(i,j,k-1)) * inv_b2_tmp; // NOTE: This is now "rho"
560  coeffG_a(i,j,k) = c_tmp * inv_b2_tmp; // NOTE: this is now "gamma"
561  } // k
562 
563  // Top boundary coefficients and RHS for L decomp
564  //===================================================
565  {
566  rhoface = myhalf * (cell_data(i,j,khi,Rho_comp) + cell_data(i-ioff,j-joff,khi,Rho_comp));
567  getRhoAlphaForFaces(i, j, khi, ioff, joff, rhoAlpha_lo, rhoAlpha_hi,
568  cell_data, mu_turb, mu_eff,
569  l_consA, l_turb);
570 
571  dz_inv = one / dz_ptr[khi];
572  dz_inv_lo = two / (dz_ptr[khi] + dz_ptr[khi-1]);
573  dz_inv_hi = dz_inv;
574 
575  a_tmp = -Fact * rhoAlpha_lo * dz_inv_lo * dz_inv;
576  c_tmp = zero;
577 
578  RHS_a(i,j,khi) = face_data(i,j,khi); // NOTE: this is momenta; solution is velocity
579  RHS_a(i,j,khi) += Fact * (tau_corr(i,j,khi+1) - tau_corr(i,j,khi)) * dz_inv;
580 
581  // BCs: Dirichlet (u_i = val), slip wall (w = 0) --
582  // but only where the top of this column really is the domain boundary
583  if (khi != dom_khi) {
584  // Coarse/fine (or grid) boundary: close the system with the known face value
585  // above instead of imposing a physical BC at an interior height
586  dz_inv_hi = two / (dz_ptr[khi] + dz_ptr[khi+1]);
587  c_tmp = -Fact * rhoAlpha_hi * dz_inv_hi * dz_inv;
588  const Real rho_above = myhalf * ( cell_data(i ,j ,khi+1,Rho_comp)
589  + cell_data(i-ioff,j-joff,khi+1,Rho_comp) );
590  RHS_a(i,j,khi) -= c_tmp * (face_data(i,j,khi+1) / rho_above);
591  } else if (ext_dir_on_zhi) {
592  // Wall stress with the one-sided gradient of ComputeStrain_S: c_tmp
593  // multiplies the wall value, and c_1 adds to the coupling with the
594  // cell below
595  const WallGradCoeffs wc = WallGradientCoeffs(dz_ptr[khi], dz_ptr[khi-1]);
596  const Real idz0 = one / dz_ptr[khi];
597  c_tmp = Fact * rhoAlpha_hi * idz0 * dz_inv * wc.c_wall;
598  a_tmp += Fact * rhoAlpha_hi * idz0 * dz_inv * wc.c_1;
599  const Real rho_wall = myhalf * ( cell_data(i ,j ,khi+1,Rho_comp)
600  + cell_data(i-ioff,j-joff,khi+1,Rho_comp) );
601  const Real wall_velocity = face_data(i,j,khi+1) / rho_wall;
602  RHS_a(i,j,khi) -= c_tmp * wall_velocity;
603  }
604 
605  // Add YSU momentum countergradient correction at top boundary.
606  // NOTE: The lower face at khi is the interior face shared with row khi-1, which
607  // has already taken this flux out of the cell below, so it always carries
608  // it; without it here the flux left the column (erf-model/ERF#4822). The
609  // upper face carries it only at a coarse/fine boundary -- the domain top
610  // is a lid for gamma, as for the scalars.
611  if (use_ysu_mom_countergradient) {
612  const int hgam_comp = (stagdir == 0) ? EddyDiff::HGAMU_v : EddyDiff::HGAMV_v;
613  // Average HGAM* to the staggered face
614  const Real gam_khi = myhalf * (mu_turb(i,j,khi ,hgam_comp) + mu_turb(i-ioff,j-joff,khi ,hgam_comp));
615  const Real gam_km1 = myhalf * (mu_turb(i,j,khi-1,hgam_comp) + mu_turb(i-ioff,j-joff,khi-1,hgam_comp));
616  const Real gam_lo = myhalf * (gam_khi + gam_km1);
617  RHS_a(i,j,khi) += Fact * dz_inv * rhoAlpha_lo * gam_lo;
618  if (khi != dom_khi) {
619  const Real gam_kp1 = myhalf * (mu_turb(i,j,khi+1,hgam_comp) + mu_turb(i-ioff,j-joff,khi+1,hgam_comp));
620  const Real gam_hi = myhalf * (gam_khi + gam_kp1);
621  RHS_a(i,j,khi) -= Fact * dz_inv * rhoAlpha_hi * gam_hi;
622  }
623  }
624 
625  b_tmp = rhoface - a_tmp - c_tmp;
626  inv_b2_tmp = one / (b_tmp - a_tmp * coeffG_a(i,j,khi-1));
627 
628  // First solve
629  soln_a(i,j,khi) = (RHS_a(i,j,khi) - a_tmp * RHS_a(i,j,khi-1)) * inv_b2_tmp;
630  }
631 
632  // Back sweep the U decomp solution
633  //===================================================
634  for (int k(khi-1); k>=klo; --k) {
635  soln_a(i,j,k) = RHS_a(i,j,k) - coeffG_a(i,j,k) * soln_a(i,j,k+1);
636  }
637 
638  // Convert back to momenta
639  //===================================================
640  for (int k(klo); k<=khi; ++k) {
641  rhoface = myhalf * (cell_data(i,j,k,Rho_comp) + cell_data(i-ioff,j-joff,k,Rho_comp));
642  face_data(i,j,k) = rhoface * soln_a(i,j,k);
643  }
644 
645 #ifdef AMREX_USE_GPU
646  });
647 #else
648  } // i
649  } // j
650 #endif
651 }
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void getRhoAlphaForFaces(int i, int j, int k, int ioff, int joff, amrex::Real &rhoAlpha_lo, amrex::Real &rhoAlpha_hi, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &mu_turb, const amrex::Real mu_eff, bool l_consA, bool l_turb, const int eddy_comp=EddyDiff::Mom_v)
Definition: ERF_GetRhoAlphaForFaces.H:23
#define Rho_comp
Definition: ERF_IndexDefines.H:53
const int khi
Definition: ERF_InitCustomPert_Bubble.H:25
const int klo
Definition: ERF_InitCustomPert_KE.H:9
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
constexpr amrex::Real two
Definition: ERF_NumericalConstants.H:38
constexpr amrex::Real one
Definition: ERF_NumericalConstants.H:37
constexpr amrex::Real zero
Definition: ERF_NumericalConstants.H:36
constexpr amrex::Real myhalf
Definition: ERF_NumericalConstants.H:41
AMREX_ASSERT_WITH_MESSAGE(wbar_cutoff_min > wbar_cutoff_max, "ERROR: wbar_cutoff_min < wbar_cutoff_max")
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE WallGradCoeffs WallGradientCoeffs(const amrex::Real dz0, const amrex::Real dz1) noexcept
Definition: ERF_WallGradientCoeffs.H:33
@ xvel_bc
Definition: ERF_IndexDefines.H:126
@ foextrap
Definition: ERF_IndexDefines.H:339
@ ext_dir
Definition: ERF_IndexDefines.H:340
@ ext_dir_prim
Definition: ERF_IndexDefines.H:343
@ HGAMU_v
Definition: ERF_IndexDefines.H:302
@ HGAMV_v
Definition: ERF_IndexDefines.H:303
Definition: ERF_DiffStruct.H:24
MolecDiffType molec_diff_type
Selected molecular transport model.
Definition: ERF_DiffStruct.H:96
amrex::Real dynamic_viscosity
Dynamic viscosity for momentum diffusion [kg/(m-s)].
Definition: ERF_DiffStruct.H:108
amrex::Real rho0_trans
Reference density used to compute dynamic diffusion coefficients [kg/m3].
Definition: ERF_DiffStruct.H:103
amrex::Vector< TurbChoice > turbChoice
Turbulence options for each AMR level.
Definition: ERF_DataStruct.H:2620
DiffChoice diffChoice
Diffusion-related options.
Definition: ERF_DataStruct.H:2617
Definition: ERF_TurbStruct.H:119
bool use_kturb
Whether any turbulence model is active.
Definition: ERF_TurbStruct.H:977
Definition: ERF_WallGradientCoeffs.H:25
amrex::Real c_wall
Definition: ERF_WallGradientCoeffs.H:26
amrex::Real c_1
Definition: ERF_WallGradientCoeffs.H:28
Here is the call graph for this function:

◆ ImplicitDiffForStateLU_S()

void ImplicitDiffForStateLU_S ( const Box &  bx,
const Box &  domain,
const int  level,
const int  n,
const double  dt_d,
const GpuArray< Real, AMREX_SPACEDIM *2 > &  bc_neumann_vals,
const Array4< Real > &  cell_data,
const Gpu::DeviceVector< Real > &  stretched_dz_d,
const Array4< const Real > &  scalar_zflux,
const Array4< const Real > &  mu_turb,
const SolverChoice &  solverChoice,
const BCRec *  bc_ptr,
const bool  use_SurfLayer,
const Real  implicit_fac,
const bool  use_mrf_countergradient 
)

Function for computing the implicit contribution to the vertical diffusion of theta, with a vertically stretched grid over flat terrain.

Parameters
[in]bxcell-centered box to loop over
[in]domainbox of the whole domain
[in]levelAMR level
[in]nconserved component index
[in]dt_dtime step
[in]bc_neumann_valsvalues of derivatives if bc_type == Neumann
[in,out]cell_dataconserved cell-centered rho, rho theta
[in]stretched_dz_darray over z of dz[k]
[in]scalar_zfluxscalar vertical flux in z-dir
[in]mu_turbturbulent viscosity
[in]solverChoicecontainer of parameters
[in]bc_ptrcontainer with boundary conditions
[in]use_SurfLayerwhether we have turned on subgrid diffusion
[in]implicit_facif 1 then fully implicit; if 0 then fully explicit
[in]use_mrf_countergradientwhether to include MRF countergradient correction
47 {
48  BL_PROFILE_VAR("ImplicitDiffForState_S()",ImplicitDiffForState_S);
49 
50  Real dt = static_cast<Real>(dt_d);
51 
52  // setup quantities for getRhoAlpha()
53 #include "ERF_SetupVertDiff.H"
54  const int qty_index = n;
55  const int prim_index = qty_index - 1;
56  const int prim_scal_index = (qty_index >= RhoScalar_comp && qty_index < RhoScalar_comp+NSCALARS) ? PrimScalar_comp : prim_index;
57 
58  // Box bounds
59  int ilo = bx.smallEnd(0);
60  int ihi = bx.bigEnd(0);
61  int jlo = bx.smallEnd(1);
62  int jhi = bx.bigEnd(1);
63  int klo = bx.smallEnd(2);
64  int khi = bx.bigEnd(2);
65  amrex::ignore_unused(ilo, ihi, jlo, jhi);
66 
67  // Temporary FABs for tridiagonal solve (allocated on column)
68  // A[k] * x[k-1] + B[k] * x[k] + C[k+1] = RHS[k]
69 
70  // With LU decomposition, M * x = r is written as L * U * x = r with U * x = rho
71  // We then first have L * rho = r and U * x = rho
72  amrex::FArrayBox RHS_fab, soln_fab, coeffG_fab;
73  RHS_fab.resize(bx,1, amrex::The_Async_Arena());
74  soln_fab.resize(bx,1, amrex::The_Async_Arena());
75  coeffG_fab.resize(bx,1, amrex::The_Async_Arena());
76  auto const& RHS_a = RHS_fab.array();
77  auto const& soln_a = soln_fab.array();
78  auto const& coeffG_a = coeffG_fab.array();
79 
80  auto dz_ptr = stretched_dz_d.data();
81 
82  // BC types are stored by BC variable, not by state component
83  const int bc_comp = ResolveNativeScalarDiffusionPolicy(qty_index, solverChoice.diffChoice).bc_comp;
84  bool foextrap_on_zlo = (bc_ptr[bc_comp].lo(2) == ERFBCType::foextrap);
85  bool foextrap_on_zhi = (bc_ptr[bc_comp].hi(2) == ERFBCType::foextrap);
86  bool neumann_on_zlo = (bc_ptr[bc_comp].lo(2) == ERFBCType::neumann);
87  bool neumann_on_zhi = (bc_ptr[bc_comp].hi(2) == ERFBCType::neumann);
88  amrex::ignore_unused(foextrap_on_zlo, foextrap_on_zhi);
89 
90  AMREX_ALWAYS_ASSERT_WITH_MESSAGE(foextrap_on_zlo || neumann_on_zlo || use_SurfLayer,
91  "Unexpected lower BC for scalars used with implicit vertical diffusion");
92  AMREX_ALWAYS_ASSERT_WITH_MESSAGE(foextrap_on_zhi || neumann_on_zhi,
93  "Unexpected upper BC for scalars used with implicit vertical diffusion");
94 
95  // k-eqn RANS with a Dirichlet wall value of k: the first cell is held at
96  // the value set by the surface layer, so its row reduces to x(klo) = phi(klo)
97  // and the row above sees it as a Dirichlet neighbour.
98  // NOTE: init_bcs requires zlo.type = surface_layer whenever dirichlet_k is set,
99  // so this matches the l_dirichlet_k pin in erf_slow_rhs_post, which also
100  // requires a surface layer. Do not relax one without the other.
101  const bool pin_klo = (qty_index == RhoKE_comp) && (klo == domain.smallEnd(2)) &&
102  (solverChoice.turbChoice[level].rans_type == RANSType::kEqn) &&
103  solverChoice.turbChoice[level].dirichlet_k;
104 
105  // A column whose bottom or top is not the domain boundary ends at a coarse/fine boundary
106  // instead. There the system must be closed with the value on the other side of that
107  // boundary rather than given a physical BC row at an interior height, so that the answer
108  // does not depend on where the grid happens to end in the vertical.
109  const bool at_zlo = (klo == domain.smallEnd(2));
110  const bool at_zhi = (khi == domain.bigEnd(2));
111 
112  Real Fact = implicit_fac * dt;
113 
114 #ifdef AMREX_USE_GPU
115  ParallelFor(makeSlab(bx,2,0), [=] AMREX_GPU_DEVICE (int i, int j, int)
116  {
117 #else
118  for (int j(jlo); j<=jhi; ++j) {
119  for (int i(ilo); i<=ihi; ++i) {
120 #endif
121  // Bottom boundary coefficients and RHS for L decomp
122  //===================================================
123  Real rhoAlpha_lo, rhoAlpha_hi;
124  Real dz_inv, dz_inv_lo, dz_inv_hi;
125  Real a_tmp, b_tmp, c_tmp, inv_b2_tmp;
126  {
127  getRhoAlpha(i, j, klo, rhoAlpha_lo, rhoAlpha_hi,
128  cell_data, mu_turb, d_alpha_eff, d_eddy_diff_idz,
129  prim_scal_index, l_consA, l_turb);
130 
131  dz_inv = one / dz_ptr[klo];
132  dz_inv_lo = dz_inv;
133  dz_inv_hi = two / (dz_ptr[klo] + dz_ptr[klo+1]);
134 
135  a_tmp = zero;
136  if (!at_zlo) {
137  dz_inv_lo = two / (dz_ptr[klo] + dz_ptr[klo-1]);
138  a_tmp = -Fact * rhoAlpha_lo * dz_inv_lo * dz_inv;
139  }
140  c_tmp = (pin_klo) ? zero : -Fact * rhoAlpha_hi * dz_inv_hi * dz_inv;
141  b_tmp = cell_data(i,j,klo,Rho_comp) - a_tmp - c_tmp;
142  inv_b2_tmp = one;
143 
144  RHS_a(i,j,klo) = cell_data(i,j,klo,n); // NOTE: this is rho*phi; solution is phi
145  if (!at_zlo) {
146  // Coarse/fine boundary: close the system with the known value below
147  RHS_a(i,j,klo) -= a_tmp * (cell_data(i,j,klo-1,n) / cell_data(i,j,klo-1,Rho_comp));
148  } else if (pin_klo) {
149  // Dirichlet row: no flux terms
150  } else if (use_SurfLayer && scalar_zflux) {
151  RHS_a(i,j,klo) += Fact * dz_inv * scalar_zflux(i,j,klo); // NOTE: scalar_zflux = -K*d_z(\phi)
152  } else if (neumann_on_zlo) {
153  RHS_a(i,j,klo) += -Fact * dz_inv * rhoAlpha_lo * bc_neumann_vals[2]; // NOTE: N_val = d_z(\phi)
154  }
155 
156  // Add countergradient correction to RHS at bottom boundary.
157  // NOTE: The lower face at klo carries no countergradient flux -- the
158  // total surface flux is supplied by the surface layer model or the
159  // Neumann BC, while gamma represents nonlocal transport interior to
160  // the PBL. Only the upper face contributes here.
161  if (use_mrf_countergradient && (n == RhoTheta_comp || n == RhoQ1_comp)) {
162  const int gam_comp = (n == RhoTheta_comp) ? EddyDiff::HGAMT_v : EddyDiff::HGAMQ_v;
163  const Real gam_hi = myhalf * (mu_turb(i, j, klo, gam_comp) + mu_turb(i, j, klo+1, gam_comp));
164  // rhoAlpha*gam is already a flux, so its divergence over cell klo
165  // is scaled by the *cell* spacing, not the face spacing
166  RHS_a(i,j,klo) -= Fact * dz_inv * rhoAlpha_hi * gam_hi;
167  if (!at_zlo) {
168  const Real gam_lo = myhalf * (mu_turb(i, j, klo, gam_comp) + mu_turb(i, j, klo-1, gam_comp));
169  RHS_a(i,j,klo) += Fact * dz_inv * rhoAlpha_lo * gam_lo;
170  }
171  }
172 
173  RHS_a(i,j,klo) /= b_tmp; // NOTE: this is now "rho"
174  coeffG_a(i,j,klo) = c_tmp / b_tmp; // NOTE: this is now "gamma"
175  }
176 
177  // Build the coefficients and RHS for L decomp
178  //===================================================
179  for (int k(klo+1); k < khi; k++) {
180  getRhoAlpha(i, j, k, rhoAlpha_lo, rhoAlpha_hi,
181  cell_data, mu_turb, d_alpha_eff, d_eddy_diff_idz,
182  prim_scal_index, l_consA, l_turb);
183 
184  dz_inv = one / dz_ptr[k];
185  dz_inv_lo = two / (dz_ptr[k] + dz_ptr[k-1]);
186  dz_inv_hi = two / (dz_ptr[k] + dz_ptr[k+1]);
187 
188  a_tmp = -Fact * rhoAlpha_lo * dz_inv_lo * dz_inv;
189  c_tmp = -Fact * rhoAlpha_hi * dz_inv_hi * dz_inv;
190  b_tmp = cell_data(i,j,k,Rho_comp) - a_tmp - c_tmp;
191  inv_b2_tmp = one / (b_tmp - a_tmp * coeffG_a(i,j,k-1));
192 
193  RHS_a(i,j,k) = cell_data(i,j,k,n); // NOTE: this is rho*phi; solution is phi
194 
195  // Add countergradient correction to RHS in interior
196  if (use_mrf_countergradient && (n == RhoTheta_comp || n == RhoQ1_comp)) {
197  const int gam_comp = (n == RhoTheta_comp) ? EddyDiff::HGAMT_v : EddyDiff::HGAMQ_v;
198  const Real gam_k = mu_turb(i, j, k, gam_comp);
199  const Real gam_km1 = mu_turb(i, j, k-1, gam_comp);
200  const Real gam_kp1 = mu_turb(i, j, k+1, gam_comp);
201  const Real gam_hi = myhalf * (gam_k + gam_kp1); // at k+½
202  const Real gam_lo = myhalf * (gam_k + gam_km1); // at k-½
203  // Countergradient flux divergence (implicit contribution to RHS):
204  // -Fact * dz_inv * [ρα_{k+½}·γ_{k+½} - ρα_{k-½}·γ_{k-½}]
205  // ρα·γ is already a flux, so differencing it across the cell is
206  // scaled by the *cell* spacing dz_inv. The face spacings
207  // dz_inv_hi/dz_inv_lo belong to the gradient in the diffusion
208  // coefficients above, not here; using them would leave a spurious
209  // tendency for a constant countergradient flux on a stretched grid.
210  RHS_a(i,j,k) -= Fact * dz_inv * (rhoAlpha_hi * gam_hi - rhoAlpha_lo * gam_lo);
211  }
212 
213  RHS_a(i,j,k) = (RHS_a(i,j,k) - a_tmp * RHS_a(i,j,k-1)) * inv_b2_tmp; // NOTE: This is now "rho"
214  coeffG_a(i,j,k) = c_tmp * inv_b2_tmp; // NOTE: this is now "gamma"
215  } // k
216 
217  // Top boundary coefficients and RHS for L decomp
218  //===================================================
219  {
220  getRhoAlpha(i, j, khi, rhoAlpha_lo, rhoAlpha_hi,
221  cell_data, mu_turb, d_alpha_eff, d_eddy_diff_idz,
222  prim_scal_index, l_consA, l_turb);
223 
224  dz_inv = one / dz_ptr[khi];
225  dz_inv_lo = two / (dz_ptr[khi] + dz_ptr[khi-1]);
226  dz_inv_hi = dz_inv;
227 
228  a_tmp = -Fact * rhoAlpha_lo * dz_inv_lo * dz_inv;
229  c_tmp = zero;
230  if (!at_zhi) {
231  dz_inv_hi = two / (dz_ptr[khi] + dz_ptr[khi+1]);
232  c_tmp = -Fact * rhoAlpha_hi * dz_inv_hi * dz_inv;
233  }
234  b_tmp = cell_data(i,j,khi,Rho_comp) - a_tmp - c_tmp;
235  inv_b2_tmp = one / (b_tmp - a_tmp * coeffG_a(i,j,khi-1));
236 
237  RHS_a(i,j,khi) = cell_data(i,j,khi,n); // NOTE: this is rho*phi; solution is phi
238  if (!at_zhi) {
239  // Coarse/fine boundary: close the system with the known value above
240  RHS_a(i,j,khi) -= c_tmp * (cell_data(i,j,khi+1,n) / cell_data(i,j,khi+1,Rho_comp));
241  } else if (neumann_on_zhi) {
242  RHS_a(i,j,khi) -= -Fact * dz_inv * rhoAlpha_hi * bc_neumann_vals[5]; // NOTE: N_val = d_z(\phi)
243  }
244 
245  // Add countergradient correction to RHS at top boundary.
246  // NOTE: The lower face at khi always carries the countergradient flux, which
247  // row khi-1 has already taken out of the cell below; without it here
248  // that flux would leave the column. The upper face carries it only at
249  // a coarse/fine boundary -- the domain top is a lid for gamma.
250  if (use_mrf_countergradient && (n == RhoTheta_comp || n == RhoQ1_comp)) {
251  const int gam_comp = (n == RhoTheta_comp) ? EddyDiff::HGAMT_v : EddyDiff::HGAMQ_v;
252  const Real gam_lo = myhalf * (mu_turb(i, j, khi, gam_comp) + mu_turb(i, j, khi-1, gam_comp));
253  RHS_a(i,j,khi) += Fact * dz_inv * rhoAlpha_lo * gam_lo;
254  if (!at_zhi) {
255  const Real gam_hi = myhalf * (mu_turb(i, j, khi, gam_comp) + mu_turb(i, j, khi+1, gam_comp));
256  RHS_a(i,j,khi) -= Fact * dz_inv * rhoAlpha_hi * gam_hi;
257  }
258  }
259 
260  // First solve
261  soln_a(i,j,khi) = (RHS_a(i,j,khi) - a_tmp * RHS_a(i,j,khi-1)) * inv_b2_tmp;
262  }
263 
264  // Back sweep the U decomp solution
265  //===================================================
266  for (int k(khi-1); k>=klo; --k) {
267  soln_a(i,j,k) = RHS_a(i,j,k) - coeffG_a(i,j,k) * soln_a(i,j,k+1);
268  }
269 
270  // Convert back to rho*theta
271  //===================================================
272  for (int k(klo); k<=khi; ++k) {
273  cell_data(i,j,k,n) = cell_data(i,j,k,Rho_comp) * soln_a(i,j,k);
274  }
275 
276 #ifdef AMREX_USE_GPU
277  });
278 #else
279  } // i
280  } // j
281 #endif
282 }
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void getRhoAlpha(int i, int j, int k, amrex::Real &rhoAlpha_lo, amrex::Real &rhoAlpha_hi, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &mu_turb, const amrex::Real *d_alpha_eff, const int *d_eddy_diff_idz, int prim_scal_index, bool l_consA, bool l_turb)
Definition: ERF_GetRhoAlpha.H:20
#define RhoScalar_comp
Definition: ERF_IndexDefines.H:57
#define RhoTheta_comp
Definition: ERF_IndexDefines.H:54
#define NSCALARS
Definition: ERF_IndexDefines.H:26
#define RhoQ1_comp
Definition: ERF_IndexDefines.H:66
#define PrimScalar_comp
Definition: ERF_IndexDefines.H:81
#define RhoKE_comp
Definition: ERF_IndexDefines.H:55
AMREX_ALWAYS_ASSERT_WITH_MESSAGE(axis >=0 &&axis< AMREX_SPACEDIM, "prob.axis must be 0, 1 or 2")
NativeScalarDiffusionPolicy ResolveNativeScalarDiffusionPolicy(const int qty_comp, const DiffChoice &choice)
Definition: ERF_NativeScalarDiffusion.H:26
@ neumann
Definition: ERF_IndexDefines.H:345
@ HGAMQ_v
Definition: ERF_IndexDefines.H:301
@ HGAMT_v
Definition: ERF_IndexDefines.H:300
int bc_comp
Definition: ERF_NativeScalarDiffusion.H:16
Here is the call graph for this function:

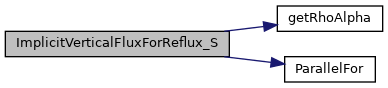
◆ ImplicitVerticalFluxForReflux_S()

void ImplicitVerticalFluxForReflux_S ( const Box &  bx,
const Box &  domain,
const int  level,
const int  n,
const Real  implicit_fac,
const Array4< const Real > &  cell_data,
const Gpu::DeviceVector< Real > &  stretched_dz_d,
const Array4< const Real > &  mu_turb,
const SolverChoice &  solverChoice,
const Array4< const Real > &  mf_mx,
const Array4< const Real > &  mf_my,
const bool  use_mrf_countergradient,
const Array4< Real > &  zflux 
)

The implicit part of the vertical diffusive flux of component n on the z faces of bx, as the matching ImplicitDiffForStateLU_S solve applied it, for refluxing: in the convention of the advective fluxes the flux registers hold (see AddScalarDiffusionRefluxFluxes_S), i.e. the vertical transfer divided by m_x m_y.

cell_data must hold the solution of that solve, including the ghost values a column that ends at a coarse/fine boundary was closed with. Faces on the domain boundary are set to zero: they are never refluxed.

Parameters
[in]bxcell-centered box
[in]domainbox of the whole domain
[in]levelAMR level
[in]nconserved component index
[in]implicit_facthe vert_implicit_fac the solve used
[in]cell_dataconserved state after the solve
[in]use_mrf_countergradientwhether the solve added the MRF countergradient flux
[out]zfluxface flux of component n, in component 0
708 {
709 #include "ERF_SetupVertDiff.H"
710  const int qty_index = n;
711  const int prim_index = qty_index - 1;
712  const int prim_scal_index = (qty_index >= RhoScalar_comp && qty_index < RhoScalar_comp+NSCALARS) ? PrimScalar_comp : prim_index;
713  const int khi = bx.bigEnd(2);
714  auto dz_ptr = stretched_dz_d.data();
715 
716  ParallelFor(surroundingNodes(bx,2), [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept
717  {
718  if (k == dom_lo.z || k == dom_hi.z+1) { zflux(i,j,k) = zero; return; }
719  // The coefficient on this face, from the cell above it (or below, at the top of bx)
720  Real rhoAlpha_lo, rhoAlpha_hi;
721  const int kc = (k <= khi) ? k : k-1;
722  getRhoAlpha(i, j, kc, rhoAlpha_lo, rhoAlpha_hi, cell_data, mu_turb, d_alpha_eff, d_eddy_diff_idz,
723  prim_scal_index, l_consA, l_turb);
724  const Real rhoAlpha = (k <= khi) ? rhoAlpha_lo : rhoAlpha_hi;
725  const Real dz_inv_face = two / (dz_ptr[k] + dz_ptr[k-1]);
726  const Real phi_hi = cell_data(i,j,k ,n) / cell_data(i,j,k ,Rho_comp);
727  const Real phi_lo = cell_data(i,j,k-1,n) / cell_data(i,j,k-1,Rho_comp);
728  Real G = -implicit_fac * rhoAlpha * dz_inv_face * (phi_hi - phi_lo);
729  // The countergradient flux the solve adds through the face, fac rho*alpha gamma
730  if (use_mrf_countergradient) {
731  const int gam_comp = (n == RhoTheta_comp) ? EddyDiff::HGAMT_v : EddyDiff::HGAMQ_v;
732  G += implicit_fac * rhoAlpha * myhalf * (mu_turb(i,j,k,gam_comp) + mu_turb(i,j,k-1,gam_comp));
733  }
734  zflux(i,j,k) = G / (mf_mx(i,j,0) * mf_my(i,j,0));
735  });
736 }
Here is the call graph for this function: