ERF
Energy Research and Forecasting: An Atmospheric Modeling Code
ERF_SlowRhsPost.cpp File Reference
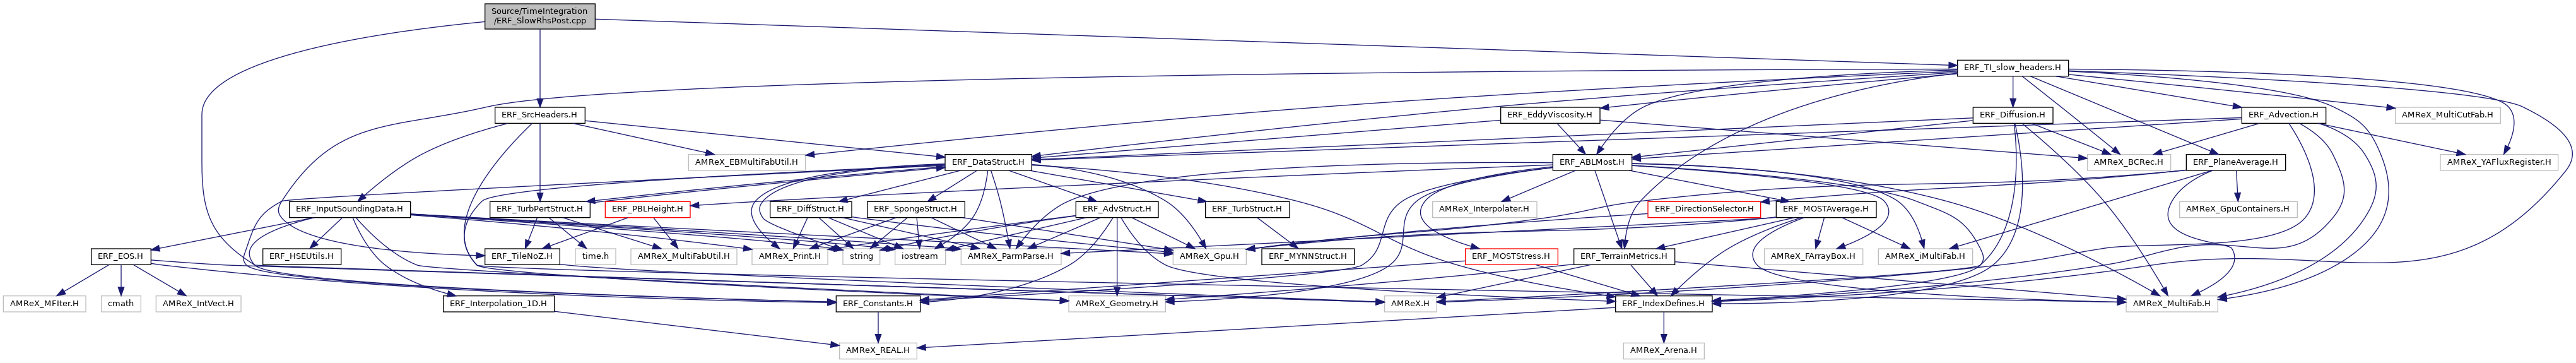
Include dependency graph for ERF_SlowRhsPost.cpp:
Functions

void erf_slow_rhs_post (int level, int finest_level, int nrk, double step_old_time, double input_time, double target_time, double dt_d, int n_qstate, Vector< MultiFab > &S_rhs, Vector< MultiFab > &S_old, Vector< MultiFab > &S_new, Vector< MultiFab > &S_data, const MultiFab &S_prim, MultiFab &avg_xmom, MultiFab &avg_ymom, MultiFab &avg_zmom, const MultiFab &xvel, const MultiFab &yvel, const MultiFab &zvel, const MultiFab &source, MultiFab *terrain_blank, MultiFab *terrain_blank_xface, MultiFab *terrain_blank_yface, MultiFab *terrain_blank_zface, const MultiFab *SmnSmn, const MultiFab *eddyDiffs, MultiFab *Hfx1, MultiFab *Hfx2, MultiFab *Hfx3, MultiFab *Q1fx1, MultiFab *Q1fx2, MultiFab *Q1fx3, MultiFab *Q2fx3, MultiFab *Diss, MultiFab *Tau13, MultiFab *Tau23, const Geometry geom, const SolverChoice &solverChoice, const Vector< std::unique_ptr< SurfaceLayer >> &SurfLayer, const Gpu::DeviceVector< BCRec > &domain_bcs_type_d, const Vector< BCRec > &domain_bcs_type_h, std::unique_ptr< MultiFab > &z_phys_nd, std::unique_ptr< MultiFab > &z_phys_cc, std::unique_ptr< MultiFab > &ax, std::unique_ptr< MultiFab > &ay, std::unique_ptr< MultiFab > &az, std::unique_ptr< MultiFab > &detJ, MultiFab *detJ_new, Gpu::DeviceVector< Real > &stretched_dz_d, Vector< std::unique_ptr< MultiFab >> &mapfac, const eb_ &ebfact, ShocDriver *native_shoc_lev, YAFluxRegister *fr_as_crse, YAFluxRegister *fr_as_fine, std::unique_ptr< ReadBndryPlanes > &m_r2d, const MultiFab *cloud_chamber_base_state, const erf_cloud_chamber::Config *cloud_chamber_config, CloudChamberBudget *cloud_budget, erf_auxiliary::AuxiliaryInertTracer *auxiliary_inert_tracer, erf_sbm::SBMStateManager *sbm_state_manager, erf_sbm::SBMTransport *sbm_transport, const MultiFab *ib_wall_face33, const MultiFab *ib_wall_ktarget)
 

Function Documentation

◆ erf_slow_rhs_post()

void erf_slow_rhs_post ( int  level,
int  finest_level,
int  nrk,
double  step_old_time,
double  input_time,
double  target_time,
double  dt_d,
int  n_qstate,
Vector< MultiFab > &  S_rhs,
Vector< MultiFab > &  S_old,
Vector< MultiFab > &  S_new,
Vector< MultiFab > &  S_data,
const MultiFab &  S_prim,
MultiFab &  avg_xmom,
MultiFab &  avg_ymom,
MultiFab &  avg_zmom,
const MultiFab &  xvel,
const MultiFab &  yvel,
const MultiFab &  zvel,
const MultiFab &  source,
MultiFab *  terrain_blank,
MultiFab *  terrain_blank_xface,
MultiFab *  terrain_blank_yface,
MultiFab *  terrain_blank_zface,
const MultiFab *  SmnSmn,
const MultiFab *  eddyDiffs,
MultiFab *  Hfx1,
MultiFab *  Hfx2,
MultiFab *  Hfx3,
MultiFab *  Q1fx1,
MultiFab *  Q1fx2,
MultiFab *  Q1fx3,
MultiFab *  Q2fx3,
MultiFab *  Diss,
MultiFab *  Tau13,
MultiFab *  Tau23,
const Geometry  geom,
const SolverChoice &  solverChoice,
const Vector< std::unique_ptr< SurfaceLayer >> &  SurfLayer,
const Gpu::DeviceVector< BCRec > &  domain_bcs_type_d,
const Vector< BCRec > &  domain_bcs_type_h,
std::unique_ptr< MultiFab > &  z_phys_nd,
std::unique_ptr< MultiFab > &  z_phys_cc,
std::unique_ptr< MultiFab > &  ax,
std::unique_ptr< MultiFab > &  ay,
std::unique_ptr< MultiFab > &  az,
std::unique_ptr< MultiFab > &  detJ,
MultiFab *  detJ_new,
Gpu::DeviceVector< Real > &  stretched_dz_d,
Vector< std::unique_ptr< MultiFab >> &  mapfac,
const eb_ &  ebfact,
ShocDriver *  native_shoc_lev,
YAFluxRegister *  fr_as_crse,
YAFluxRegister *  fr_as_fine,
std::unique_ptr< ReadBndryPlanes > &  m_r2d,
const MultiFab *  cloud_chamber_base_state,
const erf_cloud_chamber::Config *  cloud_chamber_config,
CloudChamberBudget *  cloud_budget,
erf_auxiliary::AuxiliaryInertTracer *  auxiliary_inert_tracer,
erf_sbm::SBMStateManager *  sbm_state_manager,
erf_sbm::SBMTransport *  sbm_transport,
const MultiFab *  ib_wall_face33,
const MultiFab *  ib_wall_ktarget 
)

Function for computing the slow RHS for the evolution equations for the scalars other than density or potential temperature

Parameters
[in]evellevel of resolution
[in]finest_levelfinest level of resolution
[in]nrkwhich RK stage
[in]dtslow time step
[out]S_rhsRHS computed here
[in]S_oldsolution at start of time step
[in]S_newsolution at end of current RK stage
[in]S_datacurrent solution
[in]S_primprimitive variables (i.e. conserved variables divided by density)
[in]avg_xmom
[in]avg_ymom
[in]avg_zmom
[in]xvelx-component of velocity
[in]yvely-component of velocity
[in]zvelz-component of velocity
[in]sourcesource terms for conserved variables
[in]terrain_blankimmersed forcing mask
[in]SmnSmnstrain rate magnitude
[in]eddyDiffsdiffusion coefficients for LES turbulence models
[in]Hfx3heat flux in z-dir
[in]Dissdissipation of turbulent kinetic energy
[in]Tau13rho<u'w'>, carrying the surface-layer stress on the zlo face
[in]Tau23rho<v'w'>, carrying the surface-layer stress on the zlo face
[in]geomContainer for geometric information
[in]solverChoiceContainer for solver parameters
[in]SurfLayerPointer to SurfaceLayer class for Monin-Obukhov Similarity Theory boundary condition
[in]domain_bcs_type_ddevice vector for domain boundary conditions
[in]z_phys_ndheight coordinate at nodes
[in]axarea fractions on x-faces
[in]ayarea fractions on y-faces
[in]azarea fractions on z-faces
[in]detJJacobian of the metric transformation at start of time step (= 1 if use_terrain is false)
[in]detJ_newJacobian of the metric transformation at new RK stage time (= 1 if use_terrain is false)
[in]mapfacmap factors
[in,out]fr_as_crseYAFluxRegister at level l at level l / l+1 interface
[in,out]fr_as_fineYAFluxRegister at level l at level l-1 / l interface
119 {
120  BL_PROFILE_REGION("erf_slow_rhs_post()");
121 
122  Real dt = static_cast<Real>(dt_d);
123 
124  const bool sbm_active = solverChoice.moisture_type == MoistureType::SBM;
125 
126  const BCRec* bc_ptr_d = domain_bcs_type_d.data();
127  const BCRec* bc_ptr_h = domain_bcs_type_h.data();
128 
129  AdvChoice ac = solverChoice.advChoice;
130  DiffChoice dc = solverChoice.diffChoice;
131  TurbChoice tc = solverChoice.turbChoice[level];
132 
133  const MultiFab* t_mean_mf = nullptr;
134  if (SurfLayer[Orientation(Direction::z, Orientation::low)]) { t_mean_mf = SurfLayer[Orientation(Direction::z, Orientation::low)]->get_mac_avg(level,3); }
135 
136  const bool l_use_terrain = (solverChoice.mesh_type != MeshType::ConstantDz);
137  const bool l_moving_terrain = (solverChoice.terrain_type == TerrainType::MovingFittedMesh);
138  if (l_moving_terrain) AMREX_ALWAYS_ASSERT(l_use_terrain);
139 
140  const bool l_anelastic = solverChoice.anelastic[level];
141  const bool l_anelastic_rk2 = (solverChoice.anelastic_type[level] == AnelasticType::RK2);
142 
143  // Add to the flux registers only in the stages whose fluxes the step's update applies,
144  // weighted as in that update (RefluxStageWeight)
145  const bool l_reflux = IsRefluxStage(solverChoice, level, finest_level, nrk);
146  const Real l_reflux_dt = RefluxStageWeight(solverChoice, level, finest_level, nrk) * dt;
147 
148  const bool l_use_KE = ( tc.use_tke );
149  const bool l_need_SmnSmn = ( tc.les_type == LESType::Deardorff ||
150  tc.rans_type == RANSType::kEqn );
151  // k-eqn RANS with a Dirichlet wall value: SurfaceLayer::update_fluxes
152  // writes AL01 Eq. 16 into the first cell of S_old at the start of the
153  // step; keep that value through every RK stage.
154  const bool l_dirichlet_k = ( tc.rans_type == RANSType::kEqn && tc.dirichlet_k &&
155  (SurfLayer[Orientation(Direction::z, Orientation::low)] != nullptr) );
156  // Implicit TKE dissipation: eps = c * (rho k)_new with c = diss_old / (rho k)_old,
157  // i.e. Cmu0^3 sqrt(k_old) / L; the source skips the explicit sink and the
158  // update divides by (1 + dt c).
159  const bool l_implicit_diss = ( tc.use_keqn && tc.implicit_tke_dissipation );
160  const bool l_advect_KE = ( tc.use_tke && tc.advect_tke );
161  const bool l_use_diff = ((dc.molec_diff_type != MolecDiffType::None) ||
162  (tc.les_type != LESType::None) ||
163  (tc.rans_type != RANSType::None) ||
164  (tc.pbl_type != PBLType::None) );
165  const bool l_use_turb = tc.use_kturb;
166  const bool l_rotate = (solverChoice.use_rotate_surface_flux);
167  const bool l_do_scalar = (solverChoice.transport_scalar);
168  const bool l_use_eb = (solverChoice.terrain_type == TerrainType::EB);
169 
170  auto any_SurfLayer = [&SurfLayer_ = SurfLayer]() -> bool {
171  for (auto it = SurfLayer_.begin(); it != SurfLayer_.end(); it++)
172  {
173  if (*it != nullptr) { return true; }
174  }
175  return false;
176  };
177 
178  amrex::ignore_unused(m_r2d);
179 
180  const Box& domain = geom.Domain();
181 
182  bool l_apply_surface_layer_fluxes_in_diffusion = any_SurfLayer();
183 #ifdef ERF_USE_EAMXX_SHOC
184  if (tc.uses_eamxx_shoc()) {
185  l_apply_surface_layer_fluxes_in_diffusion = false;
186  }
187 #endif
188  if (tc.uses_native_shoc()) {
189  AMREX_ALWAYS_ASSERT(native_shoc_lev != nullptr);
190  l_apply_surface_layer_fluxes_in_diffusion = false;
191  }
192 
193  const GpuArray<Real, AMREX_SPACEDIM> dxInv = geom.InvCellSizeArray();
194  const Real* dx = geom.CellSize();
195 
196  // *************************************************************************
197  // Set gravity as a vector
198  // *************************************************************************
199  const Array<Real,AMREX_SPACEDIM> grav{zero, zero, -solverChoice.gravity};
200  const GpuArray<Real,AMREX_SPACEDIM> grav_gpu{grav[0], grav[1], grav[2]};
201 
202  // *************************************************************************
203  // Pre-computed quantities
204  // *************************************************************************
205  int nvars = S_data[IntVars::cons].nComp();
206 
207  // The Q layout includes particle projections; only host-owned runs are transported.
208  const int n_qstate_total = nvars - RhoQ1_comp;
209 
210  const BoxArray& ba = S_data[IntVars::cons].boxArray();
211  const DistributionMapping& dm = S_data[IntVars::cons].DistributionMap();
212  const bool use_physical_chamber_wall_flux =
213  cloud_chamber_config != nullptr && cloud_chamber_base_state != nullptr &&
214  cloud_chamber_config->physical_initialization;
215  const erf_wall_thermodynamics::Boundary chamber_walls =
216  use_physical_chamber_wall_flux ? cloud_chamber_config->wall_boundary() :
218 
219  std::unique_ptr<MultiFab> dflux_x;
220  std::unique_ptr<MultiFab> dflux_y;
221  std::unique_ptr<MultiFab> dflux_z;
222 
223  if (l_use_diff) {
224  IntVect ng(0,0,1);
225  // The physical chamber needs one persistent component for each moist
226  // state even when budgets are disabled: qv and qc are corrected and
227  // retained independently. All other configurations retain ERF's
228  // established one-component reusable diffusion storage.
229  const int n_flux_components = use_physical_chamber_wall_flux ?
230  std::max(1, n_qstate_total) : 1;
231  dflux_x = std::make_unique<MultiFab>(convert(ba,IntVect(1,0,0)), dm, n_flux_components, ng);
232  dflux_y = std::make_unique<MultiFab>(convert(ba,IntVect(0,1,0)), dm, n_flux_components, ng);
233  dflux_z = std::make_unique<MultiFab>(convert(ba,IntVect(0,0,1)), dm, n_flux_components, 0);
234  // Every physical wall override reads the old face flux before
235  // replacing it; make that read deterministic regardless of budget
236  // diagnostics.
237  if (use_physical_chamber_wall_flux) {
238  dflux_x->setVal(0.0);
239  dflux_y->setVal(0.0);
240  dflux_z->setVal(0.0);
241  }
242  } else {
243  dflux_x = nullptr;
244  dflux_y = nullptr;
245  dflux_z = nullptr;
246  }
247 
248  // Valid vars
249  Vector<int> is_valid_slow_var; is_valid_slow_var.resize(RhoQ1_comp+1,0);
250  if (l_use_KE) { is_valid_slow_var[ RhoKE_comp] = 1; }
251  if (l_do_scalar) { is_valid_slow_var[RhoScalar_comp] = 1; }
252  if (solverChoice.moisture_type != MoistureType::None) {
253  is_valid_slow_var[RhoQ1_comp] = 1;
254  }
255 
256  // *************************************************************************
257  // Calculate cell-centered eddy viscosity & diffusivities
258  //
259  // Notes -- we fill all the data in ghost cells before calling this so
260  // that we can fill the eddy viscosity in the ghost regions and
261  // not have to call a boundary filler on this data itself
262  //
263  // LES - updates both horizontal and vertical eddy viscosityS_tmp components
264  // PBL - only updates vertical eddy viscosity components so horizontal
265  // components come from the LES model or are left as zero.
266  // *************************************************************************
267 
268  // Anelastic: the slow scalars are advected with the momenta (EB)AdvectionSrcForRho set in
269  // erf_slow_rhs_pre from the start of this stage (ax rho_u / mf_uy, ay rho_v / mf_vx,
270  // az Omega / (mf_mx mf_my); with EB the area fractions are applied to the fluxes instead),
271  // the same faces that advect theta. These momenta are already projected, by the previous
272  // stage or step.
273 
274  // M2 proof consumer: run after the stage carrier is final and before the
275  // caller copies S_data over S_new, preserving the predictor density view.
276  if (auxiliary_inert_tracer != nullptr) {
277  const auto method = !l_anelastic ? erf_auxiliary::HostIntegrator::CompressibleRK3 :
278  (solverChoice.anelastic_type[level] == AnelasticType::RK2 ?
281  auxiliary_inert_tracer->advance_stage(
282  level, method, nrk, step_old_time, input_time, target_time, dt_d,
283  S_old[IntVars::cons], S_new[IntVars::cons], S_data[IntVars::cons],
284  avg_xmom, avg_ymom, avg_zmom, solverChoice.advChoice, geom);
285  }
286 
287  // M3 advances the authoritative spectrum after the host carrier has been
288  // finalized and before the caller commits this stage's S_data into S_new.
289  // The compact qc/qr lanes are refreshed as a projection of the accepted
290  // spectrum at the same semantic target time.
291  if (sbm_active) {
292  AMREX_ALWAYS_ASSERT(sbm_state_manager != nullptr && sbm_transport != nullptr);
293  if (solverChoice.sbm_test_donor_cfl_fault) {
294  // Force an outgoing-demand violation at the production donor CFL gate.
295  avg_xmom.setVal(Real(1.0e8));
296  }
297  const auto method = !l_anelastic ? erf_auxiliary::HostIntegrator::CompressibleRK3 :
298  (solverChoice.anelastic_type[level] == AnelasticType::RK2 ?
301  const MultiFab& stage_cons_anchor = S_old[IntVars::cons];
302  const MultiFab& stage_cons_input = S_new[IntVars::cons];
303  MultiFab& stage_cons_target = S_data[IntVars::cons];
304  sbm_transport->advance_stage_from_host(
305  level, method, nrk, step_old_time, input_time, target_time, dt_d,
306  *sbm_state_manager, stage_cons_anchor, stage_cons_input,
307  stage_cons_target, avg_xmom, avg_ymom, avg_zmom, geom,
308  solverChoice.moisture_indices.qc, solverChoice.moisture_indices.qr);
309  }
310 
311  // *************************************************************************
312  // Define updates and fluxes in the current RK stage
313  // *************************************************************************
314 #ifdef _OPENMP
315 #pragma omp parallel if (Gpu::notInLaunchRegion())
316 #endif
317  {
318  std::array<FArrayBox,AMREX_SPACEDIM> flux;
319 
320  int start_comp;
321  int num_comp;
322 
323  // Cell-centered masks for EB (used for flux interpolation)
324  iMultiFab physbnd_mask;
325  bool already_on_centroids = false;
326  if (l_use_eb) {
327  physbnd_mask.define(S_data[IntVars::cons].boxArray(), S_data[IntVars::cons].DistributionMap(), 1, 1);
328  physbnd_mask.BuildMask(geom.Domain(), geom.periodicity(), 1, 1, 0, 1);
329  }
330 
331  // NOTE: this loop must NOT be tiled. It both reads and writes S_new[cons]:
332  // - the diffusion and PBL source routines below read new_cons with stencils
333  // that reach outside the box they are given (AddTurbKESources, for instance,
334  // forms a vertical theta_v gradient from k-1 and k+1);
335  // - "rhs_post_9" near the end of the loop writes new_cons = cur_cons over tbx.
336  //
337  // The better fix is to split this into two passes -- all the reads, then all the
338  // writes -- which would let tiling come back. Until then, do not restore
339  // TilingIfNotGPU() here without also moving the new_cons writes out.
340  for (MFIter mfi(S_data[IntVars::cons],false); mfi.isValid(); ++mfi)
341  {
342  Box tbx = mfi.tilebox();
343 
344  // *************************************************************************
345  // Define flux arrays for use in advection
346  // *************************************************************************
347  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
348  if (!l_use_eb) {
349  flux[dir].resize(surroundingNodes(tbx,dir),nvars,The_Async_Arena());
350  } else {
351  flux[dir].resize(surroundingNodes(tbx,dir).grow(1),nvars,The_Async_Arena());
352  }
353  flux[dir].setVal<RunOn::Device>(0);
354  }
355  const GpuArray<const Array4<Real>, AMREX_SPACEDIM>
356  flx_arr{{AMREX_D_DECL(flux[0].array(), flux[1].array(), flux[2].array())}};
357 
358  // In the stage whose fluxes are refluxed, the diffusion adds its face fluxes to flux[]
359  // too, so that the flux registers see the diffusive as well as the advective transport
360  // (EB diffusion does not do this). Nothing is counted twice: flux[] holds the faces of
361  // tbx alone and is zeroed above for each box, and the registers take each coarse/fine
362  // face once, from the box holding the cell on its coarse side (CrseAdd) or on its fine
363  // side (FineAdd), tiled or not.
364  const ScalarDiffusionRefluxViews* l_reflux_diffusion = (l_reflux && !l_use_eb) ? &flx_arr : nullptr;
365 
366  // *************************************************************************
367  // Define Array4's
368  // *************************************************************************
369  const Array4<const Real> & old_cons = S_old[IntVars::cons].array(mfi);
370  const Array4< Real> & cell_rhs = S_rhs[IntVars::cons].array(mfi);
371 
372  const Array4< Real> & new_cons = S_new[IntVars::cons].array(mfi);
373  const Array4< Real> & new_xmom = S_new[IntVars::xmom].array(mfi);
374  const Array4< Real> & new_ymom = S_new[IntVars::ymom].array(mfi);
375  const Array4< Real> & new_zmom = S_new[IntVars::zmom].array(mfi);
376 
377  const Array4< Real> & cur_cons = S_data[IntVars::cons].array(mfi);
378  const Array4<const Real> & cur_prim = S_prim.array(mfi);
379  const Array4< Real> & cur_xmom = S_data[IntVars::xmom].array(mfi);
380  const Array4< Real> & cur_ymom = S_data[IntVars::ymom].array(mfi);
381  const Array4< Real> & cur_zmom = S_data[IntVars::zmom].array(mfi);
382 
383  Array4<Real> avg_xmom_arr = avg_xmom.array(mfi);
384  Array4<Real> avg_ymom_arr = avg_ymom.array(mfi);
385  Array4<Real> avg_zmom_arr = avg_zmom.array(mfi);
386 
387  const Array4<const Real> & u = xvel.array(mfi);
388  const Array4<const Real> & v = yvel.array(mfi);
389  const Array4<const Real> & w = zvel.array(mfi);
390 
391  const Array4<const Real>& z_nd = z_phys_nd->const_array(mfi);
392  const Array4<const Real>& z_cc = z_phys_cc->const_array(mfi);
393  const Array4<const Real>& detJ_new_arr = l_moving_terrain ? detJ_new->const_array(mfi) : Array4<const Real>{};
394 
395  const Array4<const Real>& t_blank_arr = (terrain_blank) ? terrain_blank->const_array(mfi) :
396  Array4<const Real>{};
397  const Array4<const Real>& t_blank_xface_arr = (terrain_blank_xface) ? terrain_blank_xface->const_array(mfi) :
398  Array4<const Real>{};
399  const Array4<const Real>& t_blank_yface_arr = (terrain_blank_yface) ? terrain_blank_yface->const_array(mfi) :
400  Array4<const Real>{};
401  const Array4<const Real>& t_blank_zface_arr = (terrain_blank_zface) ? terrain_blank_zface->const_array(mfi) :
402  Array4<const Real>{};
403 
404  // Map factors
405  const Array4<const Real>& mf_mx = mapfac[MapFacType::m_x]->const_array(mfi);
406  const Array4<const Real>& mf_ux = mapfac[MapFacType::u_x]->const_array(mfi);
407  const Array4<const Real>& mf_vx = mapfac[MapFacType::v_x]->const_array(mfi);
408  const Array4<const Real>& mf_my = mapfac[MapFacType::m_y]->const_array(mfi);
409  const Array4<const Real>& mf_uy = mapfac[MapFacType::u_y]->const_array(mfi);
410  const Array4<const Real>& mf_vy = mapfac[MapFacType::v_y]->const_array(mfi);
411 
412  // SmnSmn for KE src with Deardorff or k-eqn RANS
413  const Array4<const Real>& SmnSmn_a = l_need_SmnSmn ? SmnSmn->const_array(mfi) : Array4<const Real>{};
414 
415  // **************************************************************************
416  // Here we fill the "current" data with "new" data because that is the result of the previous RK stage
417  // **************************************************************************
418  int nsv = S_old[IntVars::cons].nComp() - 2;
419  const GpuArray<int, IntVars::NumTypes> scomp_slow = { 2,0,0,0};
420  const GpuArray<int, IntVars::NumTypes> ncomp_slow = {nsv,0,0,0};
421  const bool copy_sbm_active = sbm_active;
422  const int copy_sbm_qc = solverChoice.moisture_indices.qc;
423  const int copy_sbm_qr = solverChoice.moisture_indices.qr;
424 
425  // **************************************************************************
426  // Note that here we do copy only the "slow" variables, not (rho) or (rho theta)
427  // **************************************************************************
428  ParallelFor(tbx, ncomp_slow[IntVars::cons],
429  [=] AMREX_GPU_DEVICE (int i, int j, int k, int nn) {
430  const int n = scomp_slow[IntVars::cons] + nn;
432  cur_cons, new_cons, i, j, k, n, copy_sbm_active,
433  copy_sbm_qc, copy_sbm_qr);
434  });
435 
436  // **************************************************************************
437  // Define updates in the RHS of continuity, temperature, and scalar equations
438  // **************************************************************************
439  bool l_eb_terrain_cc = false; // EB terrain on cell-centered grid
440  Array4<const int> mask_arr{};
441  Array4<const EBCellFlag> cfg_arr{};
442  Array4<const Real> ax_arr{};
443  Array4<const Real> ay_arr{};
444  Array4<const Real> az_arr{};
445  Array4<const Real> fcx_arr{};
446  Array4<const Real> fcy_arr{};
447  Array4<const Real> fcz_arr{};
448  Array4<const Real> detJ_arr{};
449  Array4<const Real> barea_arr{};
450  Array4<const Real> bcent_arr{};
451 
452  if (l_use_eb) {
453  EBFArrayBoxFactory const& ebfact_cc = *(ebfact.get_const_factory());
454  EBCellFlagFab const& cfg = ebfact_cc.getMultiEBCellFlagFab()[mfi];
455  cfg_arr = cfg.const_array();
456  if (cfg.getType(tbx) == FabType::singlevalued) {
457  l_eb_terrain_cc = true;
458  ax_arr = ebfact_cc.getAreaFrac()[0]->const_array(mfi);
459  ay_arr = ebfact_cc.getAreaFrac()[1]->const_array(mfi);
460  az_arr = ebfact_cc.getAreaFrac()[2]->const_array(mfi);
461  fcx_arr = ebfact_cc.getFaceCent()[0]->const_array(mfi);
462  fcy_arr = ebfact_cc.getFaceCent()[1]->const_array(mfi);
463  fcz_arr = ebfact_cc.getFaceCent()[2]->const_array(mfi);
464  detJ_arr = ebfact_cc.getVolFrac().const_array(mfi);
465  mask_arr = physbnd_mask.const_array(mfi);
466  barea_arr = ebfact_cc.getBndryArea().const_array(mfi);
467  bcent_arr = ebfact_cc.getBndryCent().const_array(mfi);
468  } else {
469  ax_arr = ax->const_array(mfi);
470  ay_arr = ay->const_array(mfi);
471  az_arr = az->const_array(mfi);
472  detJ_arr = detJ->const_array(mfi);
473  }
474  } else {
475  ax_arr = ax->const_array(mfi);
476  ay_arr = ay->const_array(mfi);
477  az_arr = az->const_array(mfi);
478  detJ_arr = detJ->const_array(mfi);
479  }
480 
481  AdvType horiz_adv_type, vert_adv_type;
482  Real horiz_upw_frac, vert_upw_frac;
483 
484  Array4<Real> diffflux_x, diffflux_y, diffflux_z;
485  Array4<Real> hfx_x, hfx_y, hfx_z, diss;
486  Array4<Real> q1fx_x, q1fx_y, q1fx_z, q2fx_z;
487  Array4<Real> hfx_EB{};
488 
489  // The surface-layer stresses on the zlo face, consumed by the MYNN QKE
490  // source at k = klo (see ERF_TurbKESources.H)
491  Array4<const Real> tau13, tau23;
492 
493  if (l_use_diff) {
494  if (Tau13) { tau13 = Tau13->const_array(mfi); }
495  if (Tau23) { tau23 = Tau23->const_array(mfi); }
496  diffflux_x = dflux_x->array(mfi);
497  diffflux_y = dflux_y->array(mfi);
498  diffflux_z = dflux_z->array(mfi);
499 
500  hfx_x = Hfx1->array(mfi);
501  hfx_y = Hfx2->array(mfi);
502  hfx_z = Hfx3->array(mfi);
503  diss = Diss->array(mfi);
504 
505  if (Q1fx1) q1fx_x = Q1fx1->array(mfi);
506  if (Q1fx2) q1fx_y = Q1fx2->array(mfi);
507  if (Q1fx3) q1fx_z = Q1fx3->array(mfi);
508  if (Q2fx3) q2fx_z = Q2fx3->array(mfi);
509  }
510 
511  if (l_use_diff && l_use_turb) {
513  eddyDiffs != nullptr,
514  "erf_slow_rhs_post: active turbulence requires non-null eddyDiffs");
515  }
516  const Array4<const Real>& mu_turb =
517  l_use_turb ? eddyDiffs->const_array(mfi) : Array4<const Real>{};
518 
519  for (int ivar(RhoKE_comp); ivar<= RhoQ1_comp; ++ivar)
520  {
521 
522  if (is_valid_slow_var[ivar])
523  {
524  start_comp = ivar;
525  num_comp = 1;
526 
527  if (ivar == RhoQ1_comp) {
528  horiz_adv_type = ac.moistscal_horiz_adv_type;
529  vert_adv_type = ac.moistscal_vert_adv_type;
530  horiz_upw_frac = ac.moistscal_horiz_upw_frac;
531  vert_upw_frac = ac.moistscal_vert_upw_frac;
532 
533  if (ac.use_efficient_advection){
534  horiz_adv_type = EfficientAdvType(nrk,ac.moistscal_horiz_adv_type);
535  vert_adv_type = EfficientAdvType(nrk,ac.moistscal_vert_adv_type);
536  }
537 
538  num_comp = n_qstate_total;
539  if (sbm_active) {
540  // Keep vapor on the normal path. The test fault widens
541  // the actual range so the ownership guard is exercised
542  // before native advection can write projected liquid.
543  num_comp = solverChoice.sbm_test_native_qc_write_fault ? 2 : 1;
544  }
545 
546  } else {
547  horiz_adv_type = ac.dryscal_horiz_adv_type;
548  vert_adv_type = ac.dryscal_vert_adv_type;
549  horiz_upw_frac = ac.dryscal_horiz_upw_frac;
550  vert_upw_frac = ac.dryscal_vert_upw_frac;
551 
552  if (ac.use_efficient_advection){
553  horiz_adv_type = EfficientAdvType(nrk,ac.dryscal_horiz_adv_type);
554  vert_adv_type = EfficientAdvType(nrk,ac.dryscal_vert_adv_type);
555  }
556 
557  if (ivar == RhoScalar_comp) {
558  num_comp = NSCALARS;
559  }
560  }
561 
562  const int group_end = start_comp + num_comp;
563  for (int run_start = start_comp; run_start < group_end; ) {
564  if (!dc.host_transports(run_start)) {
565  const int diagnostic_comp = run_start;
566  ParallelFor(tbx, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
567  cell_rhs(i,j,k,diagnostic_comp) = zero;
568  });
569  ++run_start;
570  continue;
571  }
572  start_comp = run_start;
573  num_comp = 1;
574  while (start_comp + num_comp < group_end &&
575  dc.host_transports(start_comp + num_comp)) {
576  ++num_comp;
577  }
578  run_start += num_comp;
579 
580  if (( ivar != RhoKE_comp ) ||
581  ((ivar == RhoKE_comp) && l_advect_KE))
582  {
583  if (!l_eb_terrain_cc){
584  if (sbm_active && ivar == RhoQ1_comp) {
586  true, start_comp, num_comp, erf_sbm::HostWritePath::Advection);
587  }
588  AdvectionSrcForScalars(tbx, start_comp, num_comp,
589  avg_xmom_arr, avg_ymom_arr, avg_zmom_arr,
590  cur_prim, cell_rhs,
591  detJ_arr, dxInv, mf_mx, mf_my,
592  horiz_adv_type, vert_adv_type,
593  horiz_upw_frac, vert_upw_frac,
594  flx_arr, domain, bc_ptr_h);
595  } else {
596  if (sbm_active && ivar == RhoQ1_comp) {
598  true, start_comp, num_comp, erf_sbm::HostWritePath::Advection);
599  }
600  EBAdvectionSrcForScalars(tbx, start_comp, num_comp,
601  avg_xmom_arr, avg_ymom_arr, avg_zmom_arr,
602  cur_prim, cell_rhs,
603  mask_arr, cfg_arr, ax_arr, ay_arr, az_arr,
604  fcx_arr, fcy_arr, fcz_arr,
605  detJ_arr, dxInv, mf_mx, mf_my,
606  horiz_adv_type, vert_adv_type,
607  horiz_upw_frac, vert_upw_frac,
608  flx_arr, domain, bc_ptr_h,
609  already_on_centroids);
610  }
611  }
612 
613  if (l_use_diff)
614  {
615  // Allow for implicit moisture diffusion
617  if ( (ivar == RhoKE_comp && solverChoice.implicit_ke_diffusion ) ||
618  (ivar == RhoQ1_comp && solverChoice.implicit_moisture_diffusion) ) {
619  l_vert_implicit_fac = solverChoice.vert_implicit_fac[level][nrk];
620  }
621 
622  // Only the physical chamber needs separate qv/qc calls:
623  // its wall correction must be applied to distinct flux
624  // components. Generic moisture models retain the
625  // established multi-component diffusion call.
626  const bool componentwise_moisture =
627  use_physical_chamber_wall_flux && ivar == RhoQ1_comp;
628  const int n_diff_calls = componentwise_moisture ? n_qstate_total : 1;
629  for (int qstate = 0; qstate < n_diff_calls; ++qstate) {
630  const int state_comp = componentwise_moisture ?
631  RhoQ1_comp + qstate : start_comp;
632  const int diffusion_start = state_comp;
633  const int diffusion_num = componentwise_moisture ? 1 : num_comp;
635  sbm_active, diffusion_start, diffusion_num,
637  const int flux_comp = componentwise_moisture ? qstate : 0;
638  AMREX_ALWAYS_ASSERT(state_comp >= 0 && state_comp < nvars);
639  AMREX_ALWAYS_ASSERT(flux_comp < dflux_x->nComp());
640  AMREX_ALWAYS_ASSERT(flux_comp < dflux_y->nComp());
641  AMREX_ALWAYS_ASSERT(flux_comp < dflux_z->nComp());
642  const Array4<Real> diffusion_x = dflux_x->array(mfi, flux_comp);
643  const Array4<Real> diffusion_y = dflux_y->array(mfi, flux_comp);
644  const Array4<Real> diffusion_z = dflux_z->array(mfi, flux_comp);
645 
646  if (solverChoice.mesh_type == MeshType::StretchedDz) {
647  DiffusionSrcForState_S(tbx, domain, diffusion_start, diffusion_num,
648  new_cons, cur_prim, cell_rhs,
649  diffusion_x, diffusion_y, diffusion_z,
650  stretched_dz_d, dxInv,
651  mf_mx, mf_ux, mf_vx,
652  mf_my, mf_uy, mf_vy,
653  hfx_x, hfx_y, hfx_z, q1fx_x, q1fx_y, q1fx_z,q2fx_z,
654  mu_turb, solverChoice, level,
655  bc_ptr_d,
656  l_apply_surface_layer_fluxes_in_diffusion, SurfLayer, l_vert_implicit_fac,
657  l_reflux_diffusion);
658  } else if (l_use_terrain) {
659  DiffusionSrcForState_T(tbx, domain, diffusion_start, diffusion_num, l_rotate,
660  new_cons, cur_prim, cell_rhs,
661  diffusion_x, diffusion_y, diffusion_z,
662  z_nd, z_cc, ax_arr, ay_arr, az_arr,
663  detJ_arr, dxInv,
664  mf_mx, mf_ux, mf_vx,
665  mf_my, mf_uy, mf_vy,
666  hfx_x, hfx_y, hfx_z, q1fx_x, q1fx_y, q1fx_z,q2fx_z,
667  mu_turb, solverChoice, level,
668  bc_ptr_d, bc_ptr_h,
669  l_apply_surface_layer_fluxes_in_diffusion, SurfLayer, l_vert_implicit_fac,
670  l_reflux_diffusion);
671  } else if (l_use_eb) {
672  DiffusionSrcForState_EB(tbx, domain, diffusion_start, diffusion_num, u, v,
673  new_cons, cur_prim, cell_rhs,
674  diffusion_x, diffusion_y, diffusion_z,
675  cfg_arr, ax_arr, ay_arr, az_arr, detJ_arr,
676  barea_arr, bcent_arr,
677  dx, dxInv,
678  hfx_z, q1fx_z, q2fx_z, hfx_EB,
679  mu_turb, solverChoice, level,
680  bc_ptr_d, l_apply_surface_layer_fluxes_in_diffusion, SurfLayer);
681  } else {
682  DiffusionSrcForState_N(tbx, domain, diffusion_start, diffusion_num, u, v,
683  new_cons, cur_prim, cell_rhs,
684  diffusion_x, diffusion_y, diffusion_z, dxInv,
685  mf_mx, mf_ux, mf_vx,
686  mf_my, mf_uy, mf_vy,
687  hfx_x, hfx_y, hfx_z, q1fx_x, q1fx_y, q1fx_z, q2fx_z,
688  mu_turb, solverChoice, level,
689  bc_ptr_d,
690  l_apply_surface_layer_fluxes_in_diffusion, SurfLayer, l_vert_implicit_fac,
691  l_reflux_diffusion,
692  (ib_wall_face33) ? ib_wall_face33->const_array(mfi) : Array4<const Real>{});
693  }
694  if (use_physical_chamber_wall_flux) {
695  // Apply the physical wall correction immediately to
696  // the flux component just computed. This keeps the
697  // q-state diffusion path identical with budgets on
698  // and off and guarantees no stale flux is consumed.
699  // The diffusion views are component-shifted; the
700  // wall helper receives the unshifted views and the
701  // explicit flux component index.
703  tbx, domain, state_comp, flux_comp, new_cons, cur_prim,
704  cloud_chamber_base_state->const_array(mfi), u, v, w, cell_rhs,
705  diffflux_x, diffflux_y, diffflux_z, dxInv,
706  chamber_walls, dc.alpha_T, dc.alpha_C,
707  solverChoice.rdOcp, cloud_chamber_config->has_moisture);
708  }
709  }
710  } // use_diff
711  } // host-transported run
712  } // valid slow var
713  } // loop ivar
714 
715  // **************************************************************************
716  // TKE / QKE production and dissipation. These consume the face fluxes of
717  // this stage's scalar diffusion (theta in erf_slow_rhs_pre, qv above), so
718  // they are added only once every scalar has been diffused.
719  // **************************************************************************
720  if (l_use_diff && is_valid_slow_var[RhoKE_comp])
721  {
722  const Array4<const Real> tm_arr = t_mean_mf ? t_mean_mf->const_array(mfi) : Array4<const Real>{};
723 
724  if (solverChoice.mesh_type == MeshType::StretchedDz) {
725  const PBLDerivativeDzInv_S pbl_dz_inv{stretched_dz_d.data(),
726  domain.smallEnd(2), domain.bigEnd(2)};
727  AddTurbKESources(tbx, domain, u, v, new_cons, cur_prim, cell_rhs,
728  SmnSmn_a, hfx_z, q1fx_z, diss, tau13, tau23, mu_turb,
729  solverChoice, level, tm_arr, grav_gpu, bc_ptr_d,
730  l_apply_surface_layer_fluxes_in_diffusion, SurfLayer, pbl_dz_inv);
731  } else if (l_use_terrain) {
732  const PBLDerivativeDzInv_T pbl_dz_inv{z_cc};
733  AddTurbKESources(tbx, domain, u, v, new_cons, cur_prim, cell_rhs,
734  SmnSmn_a, hfx_z, q1fx_z, diss, tau13, tau23, mu_turb,
735  solverChoice, level, tm_arr, grav_gpu, bc_ptr_d,
736  l_apply_surface_layer_fluxes_in_diffusion, SurfLayer, pbl_dz_inv);
737  } else if (!l_use_eb) {
738  const PBLDerivativeDzInv_N pbl_dz_inv{dxInv[2]};
739  AddTurbKESources(tbx, domain, u, v, new_cons, cur_prim, cell_rhs,
740  SmnSmn_a, hfx_z, q1fx_z, diss, tau13, tau23, mu_turb,
741  solverChoice, level, tm_arr, grav_gpu, bc_ptr_d,
742  l_apply_surface_layer_fluxes_in_diffusion, SurfLayer, pbl_dz_inv);
743  }
744  }
745 
746 #ifdef ERF_USE_EAMXX_SHOC
747  if (tc.uses_eamxx_shoc() && eamxx_shoc_lev) {
748  eamxx_shoc_lev->add_slow_tend(mfi,tbx,cell_rhs);
749  }
750 #endif
751  // This updates just the "slow" conserved variables
752  {
753  BL_PROFILE("rhs_post_8");
754 
756 
757  auto const& src_arr = source.const_array(mfi);
758 
759  for (int ivar(RhoKE_comp); ivar<= RhoQ1_comp; ++ivar)
760  {
761  if (is_valid_slow_var[ivar])
762  {
763  start_comp = ivar;
764  num_comp = 1;
765  if (ivar == RhoQ1_comp) {
766  num_comp = n_qstate_total;
767  if (sbm_active) {
768  // The host update applies source terms (positivity
769  // clipping is applied afterward in ERF_ScalarLimitPost.H
770  // with the same restriction). Keep both projected liquid lanes out of
771  // that write path; they are refreshed from the spectrum
772  // after the no-op microphysics handoff.
773  num_comp = 1;
774  }
775  } else if (ivar == RhoScalar_comp) {
776  num_comp = NSCALARS;
777  }
778 
779  if (l_moving_terrain)
780  {
782  sbm_active, start_comp, num_comp, erf_sbm::HostWritePath::Positivity);
783  ParallelFor(tbx, num_comp,
784  [=] AMREX_GPU_DEVICE (int i, int j, int k, int nn) noexcept {
785  const int n = start_comp + nn;
786  if (!dc.host_transports(n)) { return; }
787  cell_rhs(i,j,k,n) += src_arr(i,j,k,n);
788  Real temp_val = detJ_arr(i,j,k) * old_cons(i,j,k,n) + dt * detJ_arr(i,j,k) * cell_rhs(i,j,k,n);
789  cur_cons(i,j,k,n) = temp_val / detJ_new_arr(i,j,k);
790  if (ivar == RhoKE_comp && l_implicit_diss) {
791  cur_cons(i,j,k,n) /= (one + dt * diss(i,j,k) / amrex::max(old_cons(i,j,k,n), eps));
792  }
793  });
794 
795  } else if (l_anelastic && l_anelastic_rk2 && (nrk == 1)) { // not moving and ( (anelastic) and second RK stage) )
796 
798  sbm_active, start_comp, num_comp, erf_sbm::HostWritePath::Positivity);
799  ParallelFor(tbx, num_comp,
800  [=] AMREX_GPU_DEVICE (int i, int j, int k, int nn) noexcept {
801  const int n = start_comp + nn;
802  if (!dc.host_transports(n)) { return; }
803  cell_rhs(i,j,k,n) += src_arr(i,j,k,n);
804 
805  // Re-construct the cell_rhs used in the first RK stage
806  Real dt_times_old_cell_rhs = cur_cons(i,j,k,n) - old_cons(i,j,k,n);
807 
808  // Add the time-averaged RHS to the old state
809  cur_cons(i,j,k,n) = old_cons(i,j,k,n) + myhalf * (dt_times_old_cell_rhs + dt * cell_rhs(i,j,k,n));
810 
811  if (ivar == RhoKE_comp && l_implicit_diss) {
812  // stage 1 of the trapezoidal update: half the step is implicit
813  cur_cons(i,j,k,n) /= (one + myhalf * dt * diss(i,j,k) / amrex::max(old_cons(i,j,k,n), eps));
814  }
815  });
816 
817  } else { // not moving and ( (not anelastic) or (first RK stage) )
818 
820  sbm_active, start_comp, num_comp, erf_sbm::HostWritePath::Positivity);
821  ParallelFor(tbx, num_comp,
822  [=] AMREX_GPU_DEVICE (int i, int j, int k, int nn) noexcept {
823  const int n = start_comp + nn;
824  if (!dc.host_transports(n)) { return; }
825  cell_rhs(i,j,k,n) += src_arr(i,j,k,n);
826  cur_cons(i,j,k,n) = old_cons(i,j,k,n) + dt * cell_rhs(i,j,k,n);
827  if (ivar == RhoKE_comp && l_implicit_diss) {
828  cur_cons(i,j,k,n) /= (one + dt * diss(i,j,k) / amrex::max(old_cons(i,j,k,n), eps));
829  }
830  });
831 
832  } // moving, anelastic or neither?
833 
834  } // is_valid
835  } // ivar
836 
837  // Fraction-stress immersed wall law with erf.if_wall_tke_time_factor = 1: hold the wall
838  // cell of each column at its wall value (ib_wall::wall_tke), as erf.dirichlet_k holds the
839  // first cell over flat ground. ib_wall_ktarget is -1 outside the wall cells.
840  if (ib_wall_ktarget && solverChoice.if_wall_tke_time_factor <= one && is_valid_slow_var[RhoKE_comp]) {
841  const Array4<const Real>& kt = ib_wall_ktarget->const_array(mfi);
842  ParallelFor(tbx, [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
843  if (kt(i,j,k) >= zero) {
844  cur_cons(i,j,k,RhoKE_comp) = cur_cons(i,j,k,Rho_comp) * kt(i,j,k);
845  }
846  });
847  }
848 
849  // Re-impose the Dirichlet wall value of k (first cell above the wall)
850  if (l_dirichlet_k && is_valid_slow_var[RhoKE_comp]) {
851  const int klo = domain.smallEnd(2);
852  if (tbx.smallEnd(2) <= klo && tbx.bigEnd(2) >= klo) {
853  ParallelFor(makeSlab(tbx,2,klo), [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
854  // Hold k, not rho*k. Eq. 16 defines the primitive wall value, and
855  // cur_cons(Rho_comp) has already been updated for this stage (and,
856  // with moving terrain, rescaled by detJ/detJ_new along with RhoKE),
857  // so copying the conserved variable straight across would let the
858  // wall value drift by the first-cell density change every step.
859  // Both states carry the same detJ convention, so the ratio is exact.
860  cur_cons(i,j,k,RhoKE_comp) = cur_cons(i,j,k,Rho_comp) *
861  ( old_cons(i,j,k,RhoKE_comp) / old_cons(i,j,k,Rho_comp) );
862  });
863  }
864  }
865  } // profile
866 
867  {
868  BL_PROFILE("rhs_post_9");
869  // This updates all the conserved variables (not just the "slow" ones)
870  int num_comp_all = S_data[IntVars::cons].nComp();
871  ParallelFor(tbx, num_comp_all,
872  [=] AMREX_GPU_DEVICE (int i, int j, int k, int n) noexcept {
873  new_cons(i,j,k,n) = cur_cons(i,j,k,n);
874  });
875  } // end profile
876 
877  Box xtbx = mfi.nodaltilebox(0);
878  Box ytbx = mfi.nodaltilebox(1);
879  Box ztbx = mfi.nodaltilebox(2);
880 
881  {
882  BL_PROFILE("rhs_post_10()");
883  if (l_anelastic && terrain_blank) { // explicitly set fully immersed cells to have 0 velocities for anelastic (unstable for fully compressible).
884  // With erf.if_implicit_projection the drag of the solid is inside the projection, which
885  // already left these momenta divergence free; zeroing the faces between solid cells here
886  // would leave the surface faces unbalanced (a mass sink in the solid cells next to them,
887  // under a terrain surface or behind building walls and roofs).
888  const bool l_freeze_mom = !solverChoice.if_implicit_projection;
889  ParallelFor(xtbx, ytbx, ztbx,
890  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
891  // Use face-centered terrain_blanking if available, otherwise average from cell centers
892  Real t_blank = (t_blank_xface_arr) ? t_blank_xface_arr(i, j, k) :
893  myhalf * (t_blank_arr(i, j, k) + t_blank_arr(i-1, j, k));
894  if (l_freeze_mom && t_blank == one) {
895  new_xmom(i,j,k) = zero;
896  } else {
897  new_xmom(i,j,k) = cur_xmom(i,j,k);
898  }
899  },
900  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
901  // Use face-centered terrain_blanking if available, otherwise average from cell centers
902  Real t_blank = (t_blank_yface_arr) ? t_blank_yface_arr(i, j, k) :
903  myhalf * (t_blank_arr(i, j, k) + t_blank_arr(i, j-1, k));
904  if (l_freeze_mom && t_blank == one) {
905  new_ymom(i,j,k) = zero;
906  } else {
907  new_ymom(i,j,k) = cur_ymom(i,j,k);
908  }
909  },
910  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
911  // Use face-centered terrain_blanking if available, otherwise average from cell centers
912  Real t_blank = (t_blank_zface_arr) ? t_blank_zface_arr(i, j, k) :
913  myhalf * (t_blank_arr(i, j, k) + t_blank_arr(i, j, k-1));
914  if (l_freeze_mom && t_blank == one) {
915  new_zmom(i,j,k) = zero;
916  } else {
917  new_zmom(i,j,k) = cur_zmom(i,j,k);
918  }
919  });
920  ParallelFor(tbx,
921  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
922  Real t_blank = t_blank_arr(i, j, k );
923  if (t_blank == one) { // don't update rho and theta for fully immersed cells
924  new_cons(i, j, k, Rho_comp) = old_cons(i, j, k, Rho_comp);
925  new_cons(i, j, k, RhoTheta_comp) = old_cons(i, j, k, RhoTheta_comp);
926  }
927  });
928  } else {
929  ParallelFor(xtbx, ytbx, ztbx,
930  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
931  new_xmom(i,j,k) = cur_xmom(i,j,k);
932  },
933  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
934  new_ymom(i,j,k) = cur_ymom(i,j,k);
935  },
936  [=] AMREX_GPU_DEVICE (int i, int j, int k) noexcept {
937  new_zmom(i,j,k) = cur_zmom(i,j,k);
938  });
939  }
940  } // end profile
941 
942  {
943  BL_PROFILE("rhs_post_10");
944  // Only in the stages RefluxStageWeight weights
945  if (l_reflux) {
946  int strt_comp_reflux = RhoTheta_comp + 1;
947  int num_comp_reflux = nvars - strt_comp_reflux;
948  if (level < finest_level) {
949  fr_as_crse->CrseAdd(mfi,
950  {{AMREX_D_DECL(&(flux[0]), &(flux[1]), &(flux[2]))}},
951  dx, l_reflux_dt, strt_comp_reflux, strt_comp_reflux, num_comp_reflux, RunOn::Device);
952  }
953  if (level > 0) {
954  fr_as_fine->FineAdd(mfi,
955  {{AMREX_D_DECL(&(flux[0]), &(flux[1]), &(flux[2]))}},
956  dx, l_reflux_dt, strt_comp_reflux, strt_comp_reflux, num_comp_reflux, RunOn::Device);
957  }
958 
959  // This is necessary here so we don't go on to the next FArrayBox without
960  // having finished copying the fluxes into the FluxRegisters (since the fluxes
961  // are stored in temporary FArrayBox's)
962  Gpu::streamSynchronize();
963 
964  } // two-way coupling
965  } // end profile
966  } // mfi
967  } // OMP
968  if (cloud_budget && l_use_diff && n_qstate > 0) {
969  bool use_trapezoidal = (!l_anelastic || l_anelastic_rk2);
970  for (int qstate = 0; qstate < n_qstate; ++qstate) {
971  MultiFab qflux_x(*dflux_x, make_alias, qstate, 1);
972  MultiFab qflux_y(*dflux_y, make_alias, qstate, 1);
973  MultiFab qflux_z(*dflux_z, make_alias, qstate, 1);
974  cloud_budget->capture_stage(
976  nrk, static_cast<Real>(dt_d), qflux_x, qflux_y, qflux_z, geom,
977  0, use_trapezoidal);
978  }
979  }
980 }
void AdvectionSrcForScalars(const amrex::Box &bx, const int icomp, const int ncomp, const amrex::Array4< const amrex::Real > &avg_xmom, const amrex::Array4< const amrex::Real > &avg_ymom, const amrex::Array4< const amrex::Real > &avg_zmom, const amrex::Array4< const amrex::Real > &cell_prim, const amrex::Array4< amrex::Real > &src, const amrex::Array4< const amrex::Real > &vf_arr, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &mf_mx, const amrex::Array4< const amrex::Real > &mf_my, const AdvType horiz_adv_type, const AdvType vert_adv_type, const amrex::Real horiz_upw_frac, const amrex::Real vert_upw_frac, const amrex::GpuArray< const amrex::Array4< amrex::Real >, AMREX_SPACEDIM > &flx_arr, const amrex::Box &domain, const amrex::BCRec *bc_ptr_h)
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE AdvType EfficientAdvType(int nrk, AdvType adv_type)
Definition: ERF_Advection.H:467
@ tau23
Definition: ERF_DataStruct.H:49
@ tau13
Definition: ERF_DataStruct.H:49
@ nvars
Definition: ERF_DataStruct.H:207
@ v_x
Definition: ERF_DataStruct.H:38
@ u_y
Definition: ERF_DataStruct.H:39
@ v_y
Definition: ERF_DataStruct.H:39
@ m_y
Definition: ERF_DataStruct.H:39
@ u_x
Definition: ERF_DataStruct.H:38
@ m_x
Definition: ERF_DataStruct.H:38
void DiffusionSrcForState_S(const amrex::Box &bx, const amrex::Box &domain, int start_comp, int num_comp, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &cell_prim, const amrex::Array4< amrex::Real > &cell_rhs, const amrex::Array4< amrex::Real > &xflux, const amrex::Array4< amrex::Real > &yflux, const amrex::Array4< amrex::Real > &zflux, const amrex::Gpu::DeviceVector< amrex::Real > &stretched_dz_d, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &dxInv, const amrex::Array4< const amrex::Real > &mf_mx, const amrex::Array4< const amrex::Real > &mf_ux, const amrex::Array4< const amrex::Real > &mf_vx, const amrex::Array4< const amrex::Real > &mf_my, const amrex::Array4< const amrex::Real > &mf_uy, const amrex::Array4< const amrex::Real > &mf_vy, amrex::Array4< amrex::Real > &hfx_x, amrex::Array4< amrex::Real > &hfx_y, amrex::Array4< amrex::Real > &hfx_z, amrex::Array4< amrex::Real > &qfx1_x, amrex::Array4< amrex::Real > &qfx1_y, amrex::Array4< amrex::Real > &qfx1_z, amrex::Array4< amrex::Real > &qfx2_z, const amrex::Array4< const amrex::Real > &mu_turb, const SolverChoice &solverChoice, const int level, const amrex::BCRec *bc_ptr, const bool use_SurfLayer, const amrex::Vector< std::unique_ptr< SurfaceLayer >> &SurfLayer, const amrex::Real implicit_fac, const ScalarDiffusionRefluxViews *reflux_flx=nullptr)
Native adapter for regular scalar diffusion on a vertically stretched grid.
void DiffusionSrcForState_EB(const amrex::Box &bx, const amrex::Box &domain, int start_comp, int num_comp, const amrex::Array4< const amrex::Real > &u, const amrex::Array4< const amrex::Real > &v, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &cell_prim, const amrex::Array4< amrex::Real > &cell_rhs, const amrex::Array4< amrex::Real > &xflux, const amrex::Array4< amrex::Real > &yflux, const amrex::Array4< amrex::Real > &zflux, const amrex::Array4< const amrex::EBCellFlag > &cfg_arr, const amrex::Array4< const amrex::Real > &ax_arr, const amrex::Array4< const amrex::Real > &ay_arr, const amrex::Array4< const amrex::Real > &az_arr, const amrex::Array4< const amrex::Real > &detJ, const amrex::Array4< const amrex::Real > &barea_arr, const amrex::Array4< const amrex::Real > &bcent_arr, const amrex::Real *dx_arr, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, amrex::Array4< amrex::Real > &hfx_z, amrex::Array4< amrex::Real > &qfx1_z, amrex::Array4< amrex::Real > &qfx2_z, amrex::Array4< amrex::Real > &hfx_EB, const amrex::Array4< const amrex::Real > &mu_turb, const SolverChoice &solverChoice, const int level, const amrex::BCRec *bc_ptr, const bool use_SurfLayer, const amrex::Vector< std::unique_ptr< SurfaceLayer >> &SurfLayer)
Add state diffusion source terms for embedded-boundary cells.
void DiffusionSrcForState_N(const amrex::Box &bx, const amrex::Box &domain, int start_comp, int num_comp, const amrex::Array4< const amrex::Real > &u, const amrex::Array4< const amrex::Real > &v, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &cell_prim, const amrex::Array4< amrex::Real > &cell_rhs, const amrex::Array4< amrex::Real > &xflux, const amrex::Array4< amrex::Real > &yflux, const amrex::Array4< amrex::Real > &zflux, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &mf_mx, const amrex::Array4< const amrex::Real > &mf_ux, const amrex::Array4< const amrex::Real > &mf_vx, const amrex::Array4< const amrex::Real > &mf_my, const amrex::Array4< const amrex::Real > &mf_uy, const amrex::Array4< const amrex::Real > &mf_vy, amrex::Array4< amrex::Real > &hfx_x, amrex::Array4< amrex::Real > &hfx_y, amrex::Array4< amrex::Real > &hfx_z, amrex::Array4< amrex::Real > &qfx1_x, amrex::Array4< amrex::Real > &qfx1_y, amrex::Array4< amrex::Real > &qfx1_z, amrex::Array4< amrex::Real > &qfx2_z, const amrex::Array4< const amrex::Real > &mu_turb, const SolverChoice &solverChoice, const int level, const amrex::BCRec *bc_ptr, const bool use_SurfLayer, const amrex::Vector< std::unique_ptr< SurfaceLayer >> &SurfLayer, const amrex::Real implicit_fac, const ScalarDiffusionRefluxViews *reflux_flx=nullptr, const amrex::Array4< const amrex::Real > &wall_face33=amrex::Array4< const amrex::Real >{}, const amrex::Array4< const amrex::Real > &wall_hfx=amrex::Array4< const amrex::Real >{})
Add regular-grid state diffusion on a uniform grid without terrain.
void DiffusionSrcForState_T(const amrex::Box &bx, const amrex::Box &domain, int start_comp, int num_comp, const bool &rotate, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &cell_prim, const amrex::Array4< amrex::Real > &cell_rhs, const amrex::Array4< amrex::Real > &xflux, const amrex::Array4< amrex::Real > &yflux, const amrex::Array4< amrex::Real > &zflux, const amrex::Array4< const amrex::Real > &z_nd, const amrex::Array4< const amrex::Real > &z_cc, const amrex::Array4< const amrex::Real > &ax, const amrex::Array4< const amrex::Real > &ay, const amrex::Array4< const amrex::Real > &az, const amrex::Array4< const amrex::Real > &detJ, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &dxInv, const amrex::Array4< const amrex::Real > &mf_mx, const amrex::Array4< const amrex::Real > &mf_ux, const amrex::Array4< const amrex::Real > &mf_vx, const amrex::Array4< const amrex::Real > &mf_my, const amrex::Array4< const amrex::Real > &mf_uy, const amrex::Array4< const amrex::Real > &mf_vy, amrex::Array4< amrex::Real > &hfx_x, amrex::Array4< amrex::Real > &hfx_y, amrex::Array4< amrex::Real > &hfx_z, amrex::Array4< amrex::Real > &qfx1_x, amrex::Array4< amrex::Real > &qfx1_y, amrex::Array4< amrex::Real > &qfx1_z, amrex::Array4< amrex::Real > &qfx2_z, const amrex::Array4< const amrex::Real > &mu_turb, const SolverChoice &solverChoice, const int level, const amrex::BCRec *bc_ptr, const amrex::BCRec *bc_ptr_h, const bool use_SurfLayer, const amrex::Vector< std::unique_ptr< SurfaceLayer >> &SurfLayer, const amrex::Real implicit_fac, const ScalarDiffusionRefluxViews *reflux_flx=nullptr)
Native adapter for regular scalar diffusion on terrain-following coordinates.
void EBAdvectionSrcForScalars(const amrex::Box &bx, const int icomp, const int ncomp, const amrex::Array4< const amrex::Real > &avg_xmom, const amrex::Array4< const amrex::Real > &avg_ymom, const amrex::Array4< const amrex::Real > &avg_zmom, const amrex::Array4< const amrex::Real > &cell_prim, const amrex::Array4< amrex::Real > &src, const amrex::Array4< const int > &mask_arr, const amrex::Array4< const amrex::EBCellFlag > &cfg_arr, const amrex::Array4< const amrex::Real > &ax_arr, const amrex::Array4< const amrex::Real > &ay_arr, const amrex::Array4< const amrex::Real > &az_arr, const amrex::Array4< const amrex::Real > &fcx_arr, const amrex::Array4< const amrex::Real > &fcy_arr, const amrex::Array4< const amrex::Real > &fcz_arr, const amrex::Array4< const amrex::Real > &vf_arr, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &cellSizeInv, const amrex::Array4< const amrex::Real > &mf_mx, const amrex::Array4< const amrex::Real > &mf_my, const AdvType horiz_adv_type, const AdvType vert_adv_type, const amrex::Real horiz_upw_frac, const amrex::Real vert_upw_frac, const amrex::GpuArray< const amrex::Array4< amrex::Real >, AMREX_SPACEDIM > &flx_arr, const amrex::Box &domain, const amrex::BCRec *bc_ptr_h, bool already_on_centroids)
Compute EB advection tendency for scalars other than density.
const Real l_vert_implicit_fac
Definition: ERF_ImplicitPost.H:6
#define RhoScalar_comp
Definition: ERF_IndexDefines.H:57
#define Rho_comp
Definition: ERF_IndexDefines.H:53
#define RhoTheta_comp
Definition: ERF_IndexDefines.H:54
#define NSCALARS
Definition: ERF_IndexDefines.H:26
#define RhoQ1_comp
Definition: ERF_IndexDefines.H:66
AdvType
Definition: ERF_IndexDefines.H:352
#define RhoKE_comp
Definition: ERF_IndexDefines.H:55
amrex::GpuArray< Real, AMREX_SPACEDIM > dxInv
Definition: ERF_InitCustomPertVels_ParticleTests.H:17
const Real dx
Definition: ERF_InitCustomPert_ABL.H:44
AMREX_ALWAYS_ASSERT_WITH_MESSAGE(axis >=0 &&axis< AMREX_SPACEDIM, "prob.axis must be 0, 1 or 2")
AMREX_ALWAYS_ASSERT(bx.length()[2]==khi+1)
const int klo
Definition: ERF_InitCustomPert_KE.H:9
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
constexpr amrex::Real one
Definition: ERF_NumericalConstants.H:37
constexpr amrex::Real zero
Definition: ERF_NumericalConstants.H:36
constexpr amrex::Real myhalf
Definition: ERF_NumericalConstants.H:41
Real w
Definition: ERF_Plotfile2DInterpolator.cpp:23
amrex::GpuArray< const amrex::Array4< amrex::Real >, AMREX_SPACEDIM > ScalarDiffusionRefluxViews
Definition: ERF_ScalarDiffusion.H:1581
const bool l_dirichlet_k
Definition: ERF_ScalarLimitPost.H:21
amrex::Real Real
Definition: ERF_ShocInterface.H:19
bool IsRefluxStage(const SolverChoice &solverChoice, int level, int finest_level, int nrk)
Definition: ERF_TI_slow_headers.H:85
amrex::Real RefluxStageWeight(const SolverChoice &solverChoice, int level, int finest_level, int nrk)
Definition: ERF_TI_slow_headers.H:72
void AddTurbKESources(const amrex::Box &bx, const amrex::Box &domain, const amrex::Array4< const amrex::Real > &u, const amrex::Array4< const amrex::Real > &v, const amrex::Array4< const amrex::Real > &cell_data, const amrex::Array4< const amrex::Real > &cell_prim, const amrex::Array4< amrex::Real > &cell_rhs, const amrex::Array4< const amrex::Real > &SmnSmn_a, const amrex::Array4< const amrex::Real > &hfx_z, const amrex::Array4< const amrex::Real > &qfx1_z, const amrex::Array4< const amrex::Real > &diss, const amrex::Array4< const amrex::Real > &tau13, const amrex::Array4< const amrex::Real > &tau23, const amrex::Array4< const amrex::Real > &mu_turb, const SolverChoice &solverChoice, const int level, const amrex::Array4< const amrex::Real > &tm_arr, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > grav_gpu, const amrex::BCRec *bc_ptr, const bool use_SurfLayer, const amrex::Vector< std::unique_ptr< SurfaceLayer >> &SurfLayer, const PBLDerivativeDzInvFunctor &pbl_derivative_dz_inv)
Definition: ERF_TurbKESources.H:47
void capture_stage(int scalar, int nrk, amrex::Real dt, const amrex::MultiFab &xflux, const amrex::MultiFab &yflux, const amrex::MultiFab &zflux, const amrex::Geometry &geom, int flux_comp=0, bool trapezoidal=true)
Definition: ERF_CloudChamberBudget.H:94
@ RhoQv
Definition: ERF_CloudChamberBudget.H:33
@ RhoQc
Definition: ERF_CloudChamberBudget.H:33
const std::unique_ptr< amrex::EBFArrayBoxFactory > & get_const_factory() const noexcept
Return the cell-centered EB factory.
Definition: ERF_EB.H:124
void advance_stage(int level, HostIntegrator method, int stage, double step_old_time, double input_time, double target_time, double host_stage_interval, const amrex::MultiFab &conserved_anchor, const amrex::MultiFab &conserved_input, const amrex::MultiFab &conserved_target, const amrex::MultiFab &avg_xmom, const amrex::MultiFab &avg_ymom, const amrex::MultiFab &avg_zmom, const AdvChoice &advection, const amrex::Geometry &geometry)
Definition: ERF_AuxiliaryInertTracer.cpp:136
void advance_stage_from_host(int level, erf_auxiliary::HostIntegrator method, int stage, double step_old_time, double input_time, double target_time, double host_stage_interval, SBMStateManager &state_manager, const amrex::MultiFab &S_old_cons, const amrex::MultiFab &S_new_cons, amrex::MultiFab &S_data_cons, const amrex::MultiFab &avg_xmom, const amrex::MultiFab &avg_ymom, const amrex::MultiFab &avg_zmom, const amrex::Geometry &geometry, int qc_component, int qr_component)
Definition: ERF_SBMTransport.cpp:595
@ ymom
Definition: ERF_IndexDefines.H:274
@ cons
Definition: ERF_IndexDefines.H:272
@ zmom
Definition: ERF_IndexDefines.H:275
@ xmom
Definition: ERF_IndexDefines.H:273
@ None
Definition: ERF_LSM_Types.H:6
@ ng
Definition: ERF_Morrison.H:51
@ nn
Definition: ERF_WDM6.H:33
@ xvel
Definition: ERF_IndexDefines.H:255
@ zvel
Definition: ERF_IndexDefines.H:257
@ yvel
Definition: ERF_IndexDefines.H:256
void apply(const amrex::Box &bx, const amrex::Box &domain, const int quantity, const int flux_comp, const amrex::Array4< const amrex::Real > &state, const amrex::Array4< const amrex::Real > &prim, const amrex::Array4< const amrex::Real > &base_state, const amrex::Array4< const amrex::Real > &u, const amrex::Array4< const amrex::Real > &v, const amrex::Array4< const amrex::Real > &w, const amrex::Array4< amrex::Real > &rhs, const amrex::Array4< amrex::Real > &xflux, const amrex::Array4< amrex::Real > &yflux, const amrex::Array4< amrex::Real > &zflux, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &dx_inv, const erf_wall_thermodynamics::Boundary &walls, const amrex::Real alpha_T, const amrex::Real alpha_C, const amrex::Real rdOcp, const bool cloudy=false)
Definition: ERF_CloudChamberWallFlux.H:1037
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void copy_host_slow_component(const amrex::Array4< amrex::Real > &current, const amrex::Array4< const amrex::Real > &predictor, const int i, const int j, const int k, const int component, const bool sbm_active, const int qc_component, const int qr_component) noexcept
Definition: ERF_SBMStageOwnership.H:11
void require_host_write_range_allowed(const bool sbm_active, const int start_component, const int num_components, const HostWritePath path)
Definition: ERF_SBMOwnership.cpp:47
amrex::GpuArray< FaceWall, 2 *AMREX_SPACEDIM > Boundary
Definition: ERF_WallThermodynamics.H:70
real(c_double), parameter epsilon
Definition: ERF_module_model_constants.F90:12
real(c_double), private ac
Definition: ERF_module_mp_morr_two_moment.F90:181
Definition: ERF_AdvStruct.H:19
Definition: ERF_DiffStruct.H:24
MolecDiffType molec_diff_type
Selected molecular transport model.
Definition: ERF_DiffStruct.H:96
amrex::Real alpha_C
Kinematic scalar diffusivity [m2/s].
Definition: ERF_DiffStruct.H:100
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE bool host_transports(int n) const noexcept
Definition: ERF_DiffStruct.H:121
amrex::Real alpha_T
Kinematic temperature diffusivity [m2/s].
Definition: ERF_DiffStruct.H:99
int qr
rain
Definition: ERF_DataStruct.H:265
int qc
cloud liquid water
Definition: ERF_DataStruct.H:263
Functor for inverse vertical spacings with constant grid spacing.
Definition: ERF_PBLModels.H:624
Functor for inverse vertical spacings for stretched grids using a spacing array.
Definition: ERF_PBLModels.H:642
Functor for inverse vertical spacings for terrain-following grids using cell-center heights.
Definition: ERF_PBLModels.H:668
amrex::Vector< TurbChoice > turbChoice
Turbulence options for each AMR level.
Definition: ERF_DataStruct.H:2620
amrex::Real gravity
Effective gravitational acceleration.
Definition: ERF_DataStruct.H:2736
bool implicit_moisture_diffusion
Whether implicit vertical moisture diffusion is included.
Definition: ERF_DataStruct.H:2661
MoistureType moisture_type
Moisture or microphysics model.
Definition: ERF_DataStruct.H:2942
bool sbm_test_native_qc_write_fault
Definition: ERF_DataStruct.H:2946
bool use_rotate_surface_flux
Whether MOST surface fluxes are rotated with terrain.
Definition: ERF_DataStruct.H:2784
bool implicit_ke_diffusion
Whether implicit vertical TKE diffusion is included.
Definition: ERF_DataStruct.H:2662
bool if_implicit_projection
Definition: ERF_DataStruct.H:2704
amrex::Real if_wall_tke_time_factor
1 (the default) pins the wall cell after every stage and in the implicit TKE solve; a larger value re...
Definition: ERF_DataStruct.H:2717
amrex::Real rdOcp
Ratio of dry-air gas constant to c_p.
Definition: ERF_DataStruct.H:2738
static MeshType mesh_type
Vertical mesh representation.
Definition: ERF_DataStruct.H:2604
AdvChoice advChoice
Advection-related options.
Definition: ERF_DataStruct.H:2616
amrex::Vector< int > anelastic
Per-level flag selecting anelastic dynamics.
Definition: ERF_DataStruct.H:2629
amrex::Vector< AnelasticType > anelastic_type
Per-level two-stage scheme used by the anelastic integrator.
Definition: ERF_DataStruct.H:2630
amrex::Vector< amrex::Vector< amrex::Real > > vert_implicit_fac
Per-level, per-stage implicit vertical diffusion factors.
Definition: ERF_DataStruct.H:2657
bool transport_scalar
Whether the passive scalar component is transported.
Definition: ERF_DataStruct.H:2795
static TerrainType terrain_type
Terrain or immersed-boundary representation.
Definition: ERF_DataStruct.H:2589
bool sbm_test_donor_cfl_fault
Definition: ERF_DataStruct.H:2947
DiffChoice diffChoice
Diffusion-related options.
Definition: ERF_DataStruct.H:2617
MoistureComponentIndices moisture_indices
Index map of the moisture data carried by the active scheme: conserved-state components for the speci...
Definition: ERF_DataStruct.H:2993
Definition: ERF_TurbStruct.H:119
bool advect_tke
Whether TKE/QKE is advected.
Definition: ERF_TurbStruct.H:1065
bool implicit_tke_dissipation
Definition: ERF_TurbStruct.H:888
bool use_tke
Whether any TKE or QKE closure is active.
Definition: ERF_TurbStruct.H:983
RANSType rans_type
Selected RANS closure.
Definition: ERF_TurbStruct.H:877
bool use_keqn
Whether a microscale TKE closure is active.
Definition: ERF_TurbStruct.H:978
bool uses_eamxx_shoc() const noexcept
Query whether this level uses the EAMxx SHOC PBL scheme.
Definition: ERF_TurbStruct.H:915
bool uses_native_shoc() const noexcept
Query whether this level uses the native SHOC PBL scheme.
Definition: ERF_TurbStruct.H:924
bool dirichlet_k
Whether TKE uses Dirichlet boundary treatment.
Definition: ERF_TurbStruct.H:879
LESType les_type
Selected LES closure.
Definition: ERF_TurbStruct.H:826
bool use_kturb
Whether any turbulence model is active.
Definition: ERF_TurbStruct.H:977
PBLType pbl_type
Selected PBL closure.
Definition: ERF_TurbStruct.H:909
erf_wall_thermodynamics::Boundary wall_boundary() const noexcept
Collect thermodynamic boundary conditions for all chamber walls.
Definition: ERF_CloudChamber.H:62
bool has_moisture
Definition: ERF_CloudChamber.H:43
bool physical_initialization
Definition: ERF_CloudChamber.H:44
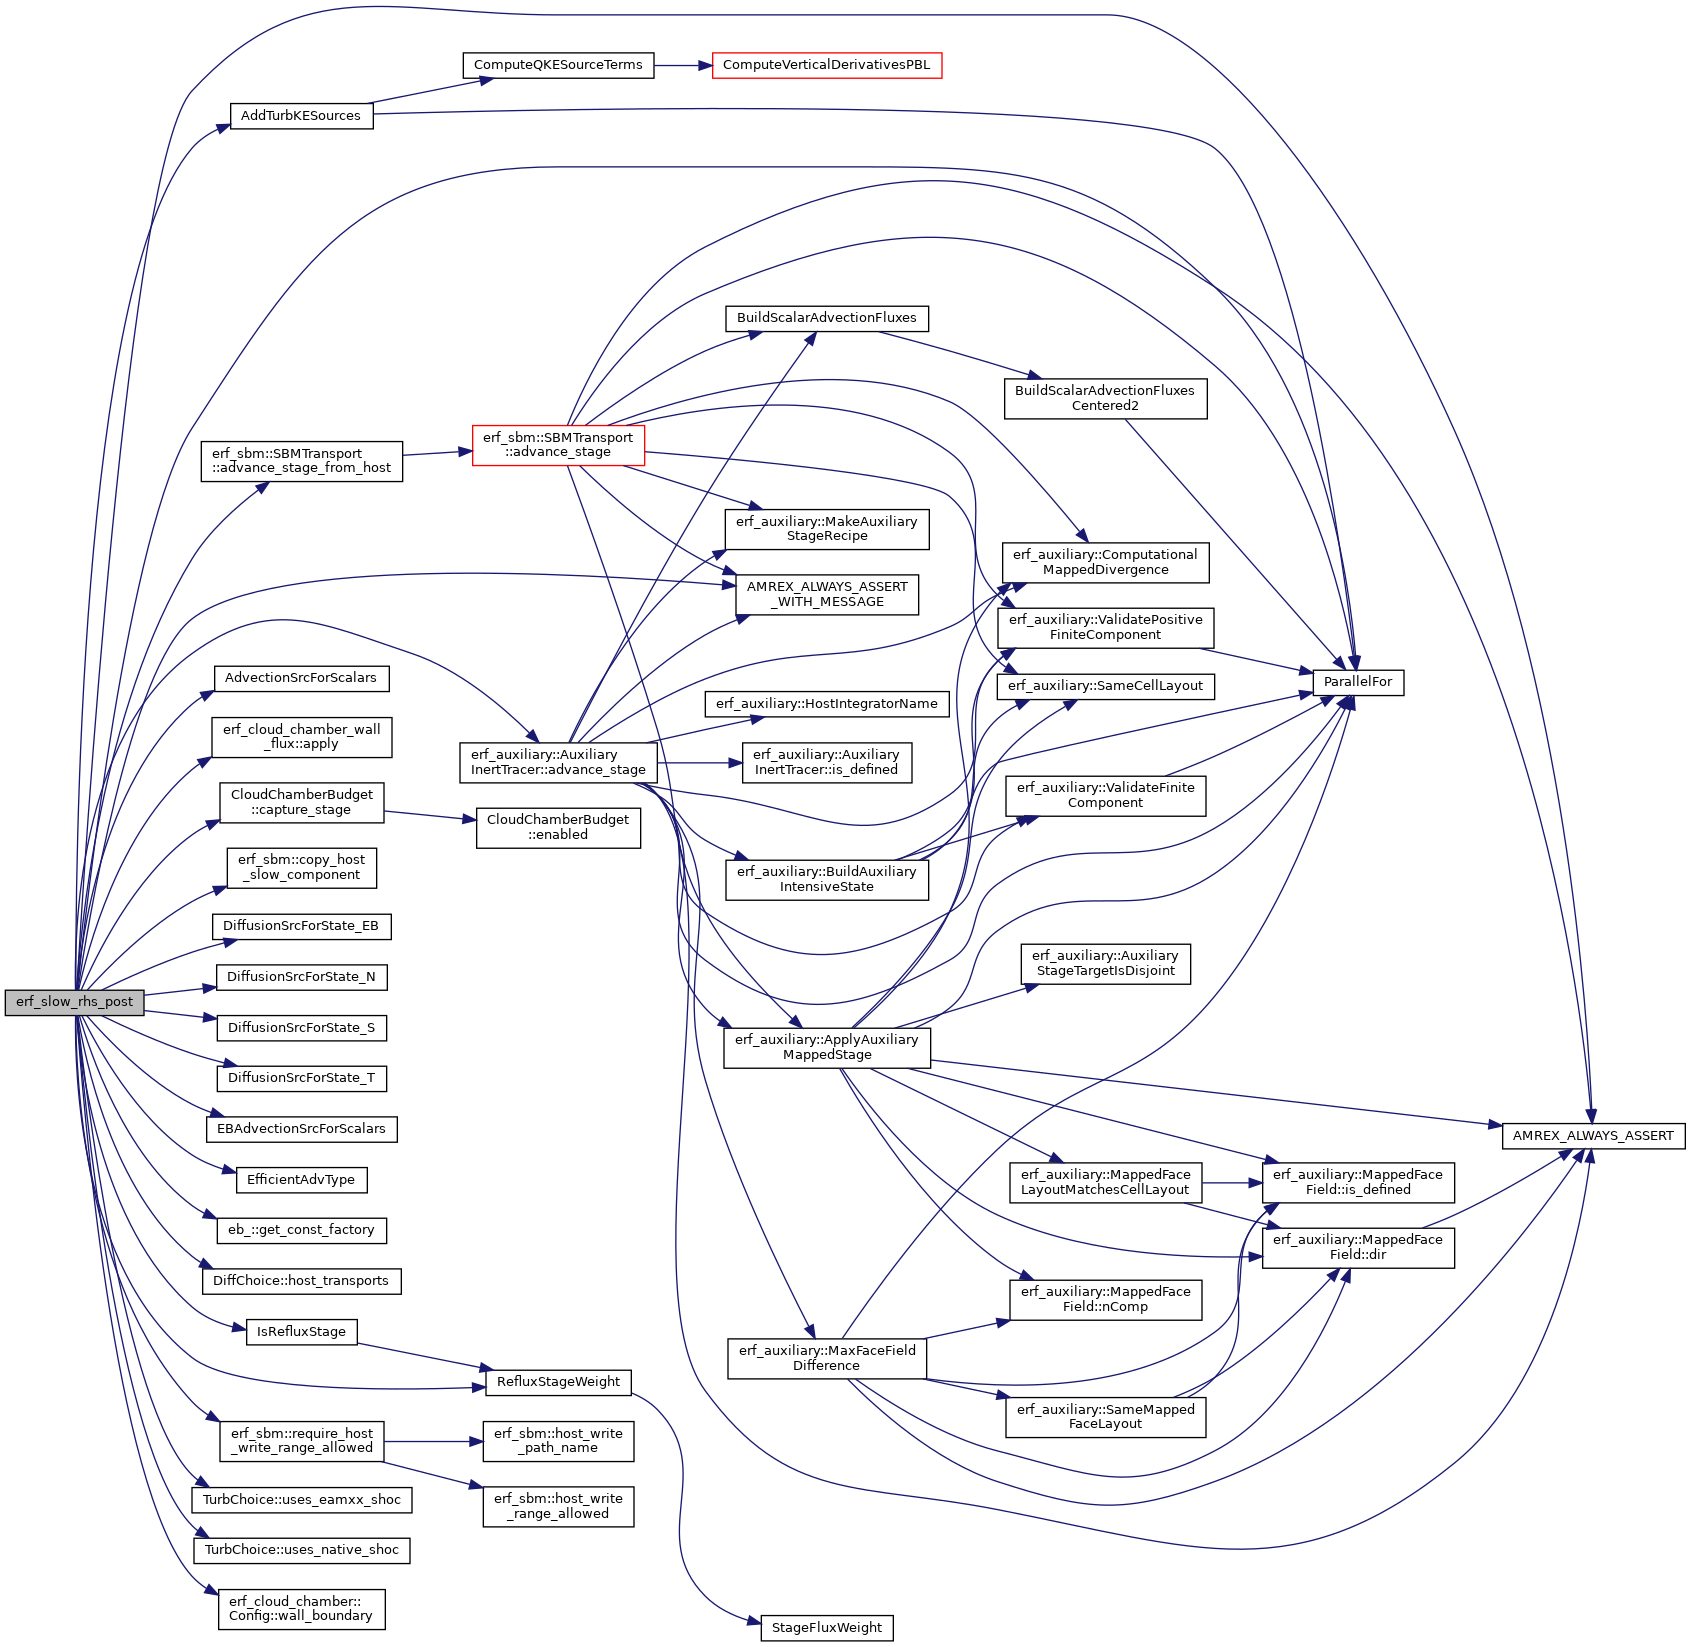
Here is the call graph for this function: