ERF
Energy Research and Forecasting: An Atmospheric Modeling Code
WDM6 Class Reference

#include <ERF_WDM6.H>

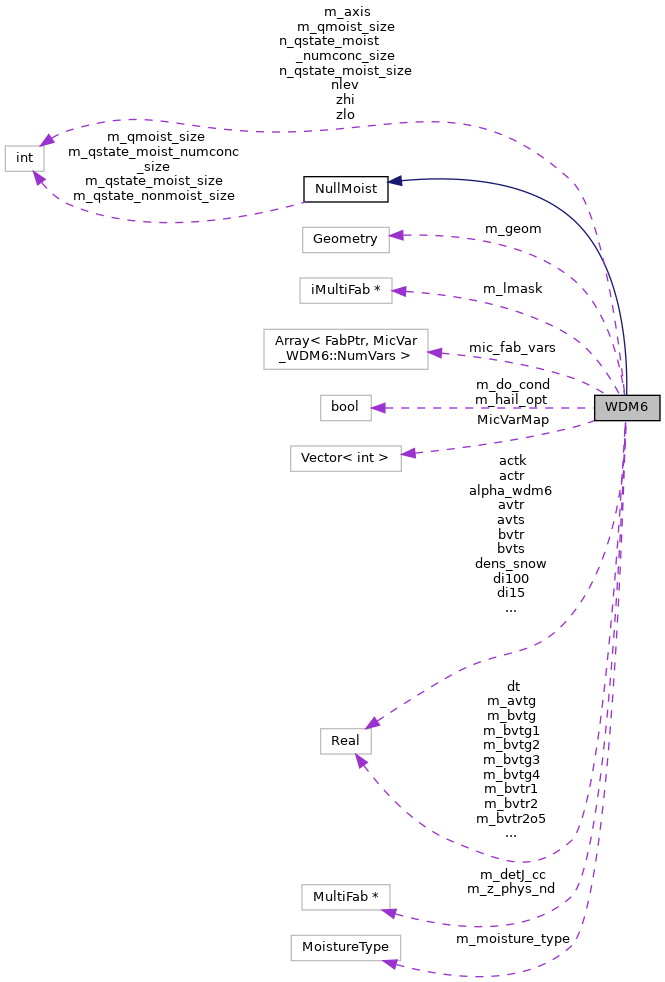
Inheritance diagram for WDM6:
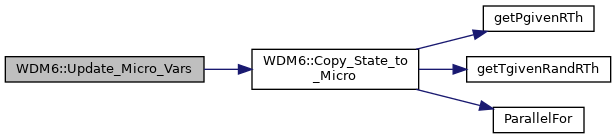
Collaboration diagram for WDM6:

Public Member Functions

 WDM6 ()
 
virtual ~WDM6 ()=default
 
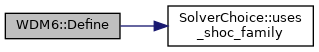
void Define (SolverChoice &sc) override
 
void Init (const amrex::MultiFab &cons_in, const amrex::BoxArray &grids, const amrex::Geometry &geom, const amrex::Real &dt_advance, std::unique_ptr< amrex::MultiFab > &z_phys_nd, std::unique_ptr< amrex::MultiFab > &detJ_cc) override
 
void Set_dzmin (const amrex::Real dz_min) override
 
void Set_Lmask (amrex::iMultiFab *lmask) override
 Import ERF's land/water mask. Only schemes whose physics branches on land vs water need to override this. More...
 
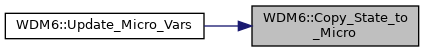
void Copy_State_to_Micro (const amrex::MultiFab &cons_in) override
 
void Copy_State_to_Micro (const amrex::MultiFab &cons_in, const amrex::MultiFab *base_state)
 
void Copy_Micro_to_State (amrex::MultiFab &cons_in) override
 
void Update_Micro_Vars (amrex::MultiFab &cons_in, const amrex::MultiFab *base_state) override
 
void Update_Micro_Vars (amrex::MultiFab &cons_in) override
 
void Update_State_Vars (amrex::MultiFab &cons_in, const amrex::MultiFab &) override
 
void Advance (const amrex::Real &dt_advance, const SolverChoice &solverChoice) override
 
const SedimentationFlux * Sed_Flux () const override
 The sedimentation face fluxes of the most recent Advance, or null for a scheme that does not sediment (see ERF_SedimentationFlux.H) More...
 
amrex::MultiFab * Qmoist_Ptr (const int &varIdx) override
 
int Qmoist_Size () override
 
int Qstate_Moist_Size () override
 
int Qstate_Moist_NumConc_Size () override
 
void Qmoist_Restart_Vars (const SolverChoice &, std::vector< int > &a_idx, std::vector< std::string > &a_names) const override
 
SurfacePrecipAccumulationSources Get_Surface_Precip_Accumulation_Ptrs (const int &) const override
 
void AdvanceColumns (const amrex::Real &dt_advance, const SolverChoice &sc)
 
- Public Member Functions inherited from NullMoist
 NullMoist ()
 
virtual ~NullMoist ()=default
 
virtual int Qstate_NonMoist_Size ()
 
virtual void GetPlotVarNames (amrex::Vector< std::string > &a_vec) const
 
virtual void GetPlotVar (const std::string &, amrex::MultiFab &) const
 
virtual void GetPlotVar (const std::string &a_name, amrex::MultiFab &a_mf, const int) const
 
virtual void SetCurrentLevel (const int &lev)
 
virtual void InitLevel (const int, const amrex::MultiFab &)
 
virtual int getDiagnosticsInterval () const
 
virtual void Set_Sed_Inflow (const amrex::MultiFab *inflow)
 The inflow through the top of a fine patch for the next Advance, or null (see ERF_SedimentationFlux.H); the caller keeps it alive for that Advance. More...
 
virtual void Set_RealWidth (const int)
 

Static Public Attributes

static constexpr amrex::Real dtcldcr = wdm6_literal(120.0)
 
static constexpr amrex::Real n0r = wdm6_literal(8.0e6)
 
static constexpr amrex::Real avtr = wdm6_literal(841.9)
 
static constexpr amrex::Real bvtr = wdm6_literal(0.8)
 
static constexpr amrex::Real r0 = wdm6_literal(0.8e-5)
 
static constexpr amrex::Real peaut = wdm6_literal(0.55)
 
static constexpr amrex::Real xncr = wdm6_literal(3.0e8)
 
static constexpr amrex::Real xncr0 = wdm6_literal(5.0e7)
 
static constexpr amrex::Real xncr1 = wdm6_literal(5.0e8)
 
static constexpr amrex::Real xmyu = wdm6_literal(1.718e-5)
 
static constexpr amrex::Real avts = wdm6_literal(11.72)
 
static constexpr amrex::Real bvts = wdm6_literal(0.41)
 
static constexpr amrex::Real lamdarmax = wdm6_literal(5.0e4)
 
static constexpr amrex::Real lamdarmin = wdm6_literal(2.0e3)
 
static constexpr amrex::Real lamdasmax = wdm6_literal(1.0e5)
 
static constexpr amrex::Real lamdacmax = wdm6_literal(5.0e5)
 
static constexpr amrex::Real lamdacmin = wdm6_literal(2.0e4)
 
static constexpr amrex::Real dicon = wdm6_literal(11.9)
 
static constexpr amrex::Real dimax = wdm6_literal(500.0e-6)
 
static constexpr amrex::Real pfrz1 = wdm6_literal(100.0)
 
static constexpr amrex::Real pfrz2 = wdm6_literal(0.66)
 
static constexpr amrex::Real qcrmin = wdm6_literal(1.0e-9)
 
static constexpr amrex::Real ncmin = wdm6_literal(1.0e1)
 
static constexpr amrex::Real nrmin = wdm6_literal(1.0e-2)
 
static constexpr amrex::Real eacrc = wdm6_literal(1.0)
 
static constexpr amrex::Real dens_snow = wdm6_literal(100.0)
 
static constexpr amrex::Real qs0 = wdm6_literal(6.0e-4)
 
static constexpr amrex::Real n0smax = wdm6_literal(1.0e11)
 
static constexpr amrex::Real n0s = wdm6_literal(2.0e6)
 
static constexpr amrex::Real alpha_wdm6 = wdm6_literal(0.12)
 
static constexpr amrex::Real satmax = wdm6_literal(1.0048)
 
static constexpr amrex::Real actk = wdm6_literal(0.6)
 
static constexpr amrex::Real actr = wdm6_literal(1.5)
 
static constexpr amrex::Real ncrk1 = wdm6_literal(3.03e3)
 
static constexpr amrex::Real ncrk2 = wdm6_literal(2.59e15)
 
static constexpr amrex::Real di100 = wdm6_literal(1.0e-4)
 
static constexpr amrex::Real di600 = wdm6_literal(6.0e-4)
 
static constexpr amrex::Real di2000 = wdm6_literal(2000.0e-6)
 
static constexpr amrex::Real di82 = wdm6_literal(82.0e-6)
 
static constexpr amrex::Real di15 = wdm6_literal(15.0e-6)
 

Private Types

using FabPtr = std::shared_ptr< amrex::MultiFab >
 

Private Member Functions

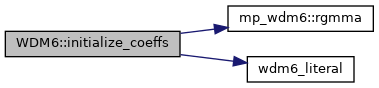
void initialize_coeffs ()
 

Private Attributes

int m_qmoist_size = 4
 
int n_qstate_moist_size = 9
 
int n_qstate_moist_numconc_size = 3
 
amrex::Vector< int > MicVarMap
 
amrex::Geometry m_geom
 
amrex::Real dt {0.0}
 
amrex::Real m_dzmin {0.0}
 
amrex::Real m_ccn0 {100.0e6}
 
int nlev {0}
 
int zlo {0}
 
int zhi {0}
 
int m_axis {2}
 
bool m_do_cond {true}
 
amrex::Real m_rdOcp {RdoCp}
 
MoistureType m_moisture_type {MoistureType::None}
 
amrex::MultiFab * m_z_phys_nd {nullptr}
 
amrex::MultiFab * m_detJ_cc {nullptr}
 
amrex::iMultiFab * m_lmask {nullptr}
 
amrex::Array< FabPtr, MicVar_WDM6::NumVars > mic_fab_vars
 
MicrophysicsColumns m_columns
 
SedimentationFlux m_sed
 
bool m_hail_opt {false}
 
amrex::Real m_n0g {0}
 
amrex::Real m_deng {0}
 
amrex::Real m_avtg {0}
 
amrex::Real m_bvtg {0}
 
amrex::Real m_lamdagmax {0}
 
amrex::Real m_pi_wdm6 {0}
 
amrex::Real m_xlv1 {0}
 
amrex::Real m_qc0 {0}
 
amrex::Real m_qc1 {0}
 
amrex::Real m_qck1 {0}
 
amrex::Real m_pidnc {0}
 
amrex::Real m_bvtr1 {0}
 
amrex::Real m_bvtr2 {0}
 
amrex::Real m_bvtr3 {0}
 
amrex::Real m_bvtr4 {0}
 
amrex::Real m_bvtr5 {0}
 
amrex::Real m_bvtr6 {0}
 
amrex::Real m_bvtr7 {0}
 
amrex::Real m_bvtr2o5 {0}
 
amrex::Real m_bvtr3o5 {0}
 
amrex::Real m_g1pbr {0}
 
amrex::Real m_g2pbr {0}
 
amrex::Real m_g3pbr {0}
 
amrex::Real m_g4pbr {0}
 
amrex::Real m_g5pbr {0}
 
amrex::Real m_g6pbr {0}
 
amrex::Real m_g7pbr {0}
 
amrex::Real m_g5pbro2 {0}
 
amrex::Real m_g7pbro2 {0}
 
amrex::Real m_pvtr {0}
 
amrex::Real m_pvtrn {0}
 
amrex::Real m_eacrr {0}
 
amrex::Real m_pacrr {0}
 
amrex::Real m_precr1 {0}
 
amrex::Real m_precr2 {0}
 
amrex::Real m_xmmax {0}
 
amrex::Real m_roqimax {0}
 
amrex::Real m_pidn0r {0}
 
amrex::Real m_pidnr {0}
 
amrex::Real m_bvts1 {0}
 
amrex::Real m_bvts2 {0}
 
amrex::Real m_bvts3 {0}
 
amrex::Real m_bvts4 {0}
 
amrex::Real m_g1pbs {0}
 
amrex::Real m_g3pbs {0}
 
amrex::Real m_g4pbs {0}
 
amrex::Real m_g5pbso2 {0}
 
amrex::Real m_pvts {0}
 
amrex::Real m_pacrs {0}
 
amrex::Real m_precs1 {0}
 
amrex::Real m_precs2 {0}
 
amrex::Real m_pidn0s {0}
 
amrex::Real m_pacrc {0}
 
amrex::Real m_bvtg1 {0}
 
amrex::Real m_bvtg2 {0}
 
amrex::Real m_bvtg3 {0}
 
amrex::Real m_bvtg4 {0}
 
amrex::Real m_g1pbg {0}
 
amrex::Real m_g3pbg {0}
 
amrex::Real m_g4pbg {0}
 
amrex::Real m_g5pbgo2 {0}
 
amrex::Real m_pvtg {0}
 
amrex::Real m_pacrg {0}
 
amrex::Real m_precg1 {0}
 
amrex::Real m_precg2 {0}
 
amrex::Real m_pidn0g {0}
 
amrex::Real m_rslopecmax {0}
 
amrex::Real m_rslopec2max {0}
 
amrex::Real m_rslopec3max {0}
 
amrex::Real m_rslopermax {0}
 
amrex::Real m_rslopesmax {0}
 
amrex::Real m_rslopegmax {0}
 
amrex::Real m_rsloperbmax {0}
 
amrex::Real m_rslopesbmax {0}
 
amrex::Real m_rslopegbmax {0}
 
amrex::Real m_rsloper2max {0}
 
amrex::Real m_rslopes2max {0}
 
amrex::Real m_rslopeg2max {0}
 
amrex::Real m_rsloper3max {0}
 
amrex::Real m_rslopes3max {0}
 
amrex::Real m_rslopeg3max {0}
 

Additional Inherited Members

- Protected Member Functions inherited from NullMoist
void set_anelastic_reference_pressure_mode (const SolverChoice &sc)
 
void assert_base_state_available (const amrex::MultiFab *base_state) const
 
- Protected Attributes inherited from NullMoist
const amrex::MultiFab * m_sed_inflow = nullptr
 
int m_level {0}
 
bool m_use_anelastic_reference_pressure {false}
 

Member Typedef Documentation

◆ FabPtr

using WDM6::FabPtr = std::shared_ptr<amrex::MultiFab>
private

Constructor & Destructor Documentation

◆ WDM6()

WDM6::WDM6 ( )
inline
119 {}

◆ ~WDM6()

virtual WDM6::~WDM6 ( )
virtualdefault

Member Function Documentation

◆ Advance()

void WDM6::Advance ( const amrex::Real &  dt_advance,
const SolverChoice &  solverChoice 
)
overridevirtual

Reimplemented from NullMoist.

663 {
664  m_sed.reset(dt_advance);
665 
666  if (!m_columns.needs_gather()) {
667  AdvanceColumns(dt_advance, solverChoice);
668  return;
669  }
670 
671  // Some column is split between boxes stacked in z. Sedimentation treats each box's
672  // k range as the whole column, so run on a copy of the fields in which every column
673  // lies in one box, then copy the result back.
674  amrex::Array<FabPtr, MicVar_WDM6::NumVars> saved;
675  m_columns.gather(mic_fab_vars, saved);
676  MultiFab* z_phys_nd_saved = m_z_phys_nd;
677  auto z_phys_nd_col = m_columns.gather_nodal(m_z_phys_nd);
678  m_z_phys_nd = z_phys_nd_col.get();
679  iMultiFab* lmask_saved = m_lmask;
680  auto lmask_col = m_columns.gather_2d(m_lmask);
681  m_lmask = lmask_col.get();
682  auto sed_saved = m_sed.down;
683  m_sed.down = m_columns.gather_one(*sed_saved);
684  const MultiFab* inflow_saved = m_sed_inflow;
685  auto inflow_col = (m_sed_inflow) ? m_columns.gather_one(*m_sed_inflow) : nullptr;
686  m_sed_inflow = inflow_col.get();
687 
688  AdvanceColumns(dt_advance, solverChoice);
689 
690  m_sed_inflow = inflow_saved;
691  sed_saved->ParallelCopy(*m_sed.down);
692  m_sed.down = sed_saved;
693  m_lmask = lmask_saved;
694  m_z_phys_nd = z_phys_nd_saved;
696 }
void gather(std::array< FabPtr, N > &vars, std::array< FabPtr, N > &saved) const
Swap each non-null field for a copy on the column layout; the originals go to saved.
Definition: ERF_MicrophysicsColumns.H:48
FabPtr gather_one(const amrex::MultiFab &src) const
Copy of a field (cell-centered or z-face; with its ghost cells) on the column layout.
Definition: ERF_MicrophysicsColumns.cpp:100
void scatter(std::array< FabPtr, N > &vars, std::array< FabPtr, N > &saved) const
Copy the column-layout fields back into the originals and restore them.
Definition: ERF_MicrophysicsColumns.H:58
std::unique_ptr< amrex::MultiFab > gather_nodal(const amrex::MultiFab *src) const
Copy of a nodal field (e.g. z_phys_nd) on the column layout, or null for null input.
Definition: ERF_MicrophysicsColumns.cpp:116
bool needs_gather() const
True when some column is split between boxes, so the fields must be gathered.
Definition: ERF_MicrophysicsColumns.H:41
std::unique_ptr< amrex::iMultiFab > gather_2d(const amrex::iMultiFab *src) const
Copy of a 2D (z-flattened) integer field (e.g. lmask) on the column layout, or null.
Definition: ERF_MicrophysicsColumns.cpp:128
const amrex::MultiFab * m_sed_inflow
Definition: ERF_NullMoist.H:168
amrex::iMultiFab * m_lmask
Definition: ERF_WDM6.H:305
void AdvanceColumns(const amrex::Real &dt_advance, const SolverChoice &sc)
Definition: ERF_AdvanceWDM6.cpp:698
amrex::Array< FabPtr, MicVar_WDM6::NumVars > mic_fab_vars
Definition: ERF_WDM6.H:307
MicrophysicsColumns m_columns
Definition: ERF_WDM6.H:310
amrex::MultiFab * m_z_phys_nd
Definition: ERF_WDM6.H:303
SedimentationFlux m_sed
Definition: ERF_WDM6.H:313
std::shared_ptr< amrex::MultiFab > down
Definition: ERF_SedimentationFlux.H:39
void reset(amrex::Real a_dt)
Zero the fluxes at the start of an Advance of length a_dt.
Definition: ERF_SedimentationFlux.H:57

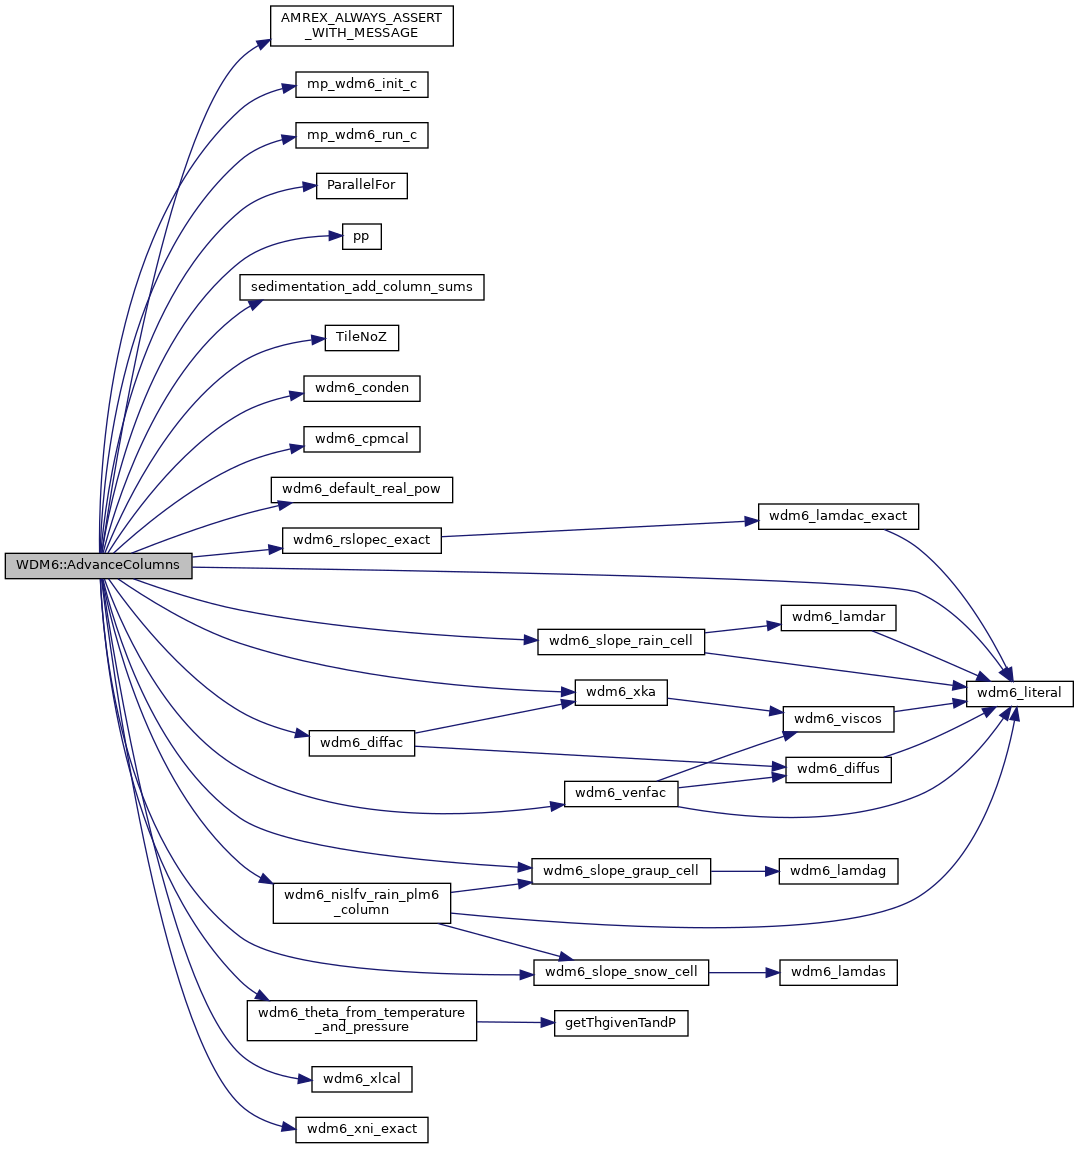
◆ AdvanceColumns()

void WDM6::AdvanceColumns ( const amrex::Real &  dt_advance,
const SolverChoice &  sc 
)
700 {
701  // ---------------------------------------------------------------
702  // Dual-mode implementation following WSM6 pattern:
703  // - With ERF_USE_WDM6_FORT: Call Fortran bridge (CPU-only)
704  // - Without: Use C++ GPU kernels (not yet implemented)
705  // ---------------------------------------------------------------
706 
707 #ifdef ERF_USE_WDM6_FORT
708  static int call_count = 0;
709  call_count++;
710  [[maybe_unused]] const bool first_call = (call_count == 1);
711 
712  // Fortran bridge mode - initialize once
713  static bool wdm6_inited = false;
714  if (!wdm6_inited) {
715  constexpr double den0 = 1.28; // Standard dry-air density (kg/m^3)
716  constexpr double denr = static_cast<double>(rhoh2o);
717  constexpr double dens = static_cast<double>(rhos);
718  constexpr double cl = static_cast<double>(Cp_l);
719  constexpr double cpv = static_cast<double>(Cp_v);
720  const double ccn0 = static_cast<double>(m_ccn0);
721  // Honour wdm6.hail_opt on this leg too. m_hail_opt is resolved in Init
722  // from the same input the native coefficients branch on, so the two
723  // legs cannot disagree about the regime. The bool maps back to {0,1}
724  // losslessly with respect to the Fortran, whose only test is
725  // `hail_opt .eq. 1` (ERF_module_mp_wdm6.F90:3259).
726  const int hail_opt = m_hail_opt ? 1 : 0;
727  mp_wdm6_init_c(den0, denr, dens, cl, cpv, ccn0, hail_opt);
728  wdm6_inited = true;
729  if (first_call) {
730  amrex::Print() << "WDM6 Fortran bridge initialized\n";
731  }
732  }
733 #endif
734 
735  int microphysics_debug = 0;
736  std::vector<int> micro_diag_target_column;
737  {
738  amrex::ParmParse pp("erf");
739  pp.queryAdd("microphysics_debug", microphysics_debug);
740  pp.queryarr("micro_diag_target_column", micro_diag_target_column);
741  }
742  microphysics_debug = std::max(0, std::min(2, microphysics_debug));
743 #ifdef ERF_USE_WDM6_FORT
744  bool use_wdm6_cpp_answer = false;
745  {
746  amrex::ParmParse pp("erf");
747  pp.queryAdd("use_wdm6_cpp_answer", use_wdm6_cpp_answer);
748  }
749  const bool run_wdm6_fort = !use_wdm6_cpp_answer;
750 
751  // The Fortran bridge takes each box's k range as the whole column (the box top as the
752  // model top, its bottom as the ground), so it needs boxes that do span it.
754  "WDM6: the Fortran bridge (erf.use_wdm6_cpp_answer = false) requires every box to span "
755  "the domain in z (no grids split in z, and no refined levels short of the domain top or bottom)");
756 #endif
757 
758  // Physical constants
759  [[maybe_unused]] constexpr double g = static_cast<double>(CONST_GRAV);
760  constexpr double cpd = static_cast<double>(Cp_d);
761  constexpr double cpv = static_cast<double>(Cp_v);
762  [[maybe_unused]] constexpr double rd = static_cast<double>(R_d);
763  constexpr double rv = static_cast<double>(R_v);
764  constexpr double t0c = 273.15;
765  [[maybe_unused]] constexpr double ep1 = static_cast<double>(R_v / R_d - one);
766  constexpr double ep2 = static_cast<double>(R_d / R_v);
767  constexpr double qmin = 1.0e-12;
768  constexpr double xls = static_cast<double>(lsub);
769  constexpr double xlv0 = static_cast<double>(lat_vap);
770  constexpr double xlf0 = static_cast<double>(lat_ice);
771  constexpr double den0 = 1.28;
772  constexpr double denr = static_cast<double>(rhoh2o);
773  constexpr double dens = static_cast<double>(rhos);
774  constexpr double cliq = static_cast<double>(Cp_l);
775  constexpr double cice = 2106.0;
776  constexpr double psat = 610.78;
777  // Only the Fortran bridge consumes these; the native C++ path below derives
778  // its own. Mirrors ERF_AdvanceWSM6.cpp.
779  amrex::ignore_unused(g, rd, ep1);
780  [[maybe_unused]] const double ccn0 = static_cast<double>(m_ccn0);
781 
782  for (MFIter mfi(*mic_fab_vars[MicVar_WDM6::qv], TileNoZ()); mfi.isValid(); ++mfi) {
783  const Box box = mfi.tilebox();
784  const Box fab_box = mfi.fabbox();
785 
786  // Get array pointers for all WDM6 variables
787  auto const& t_arr = mic_fab_vars[MicVar_WDM6::tabs]->array(mfi);
788  auto const& qv_arr = mic_fab_vars[MicVar_WDM6::qv]->array(mfi);
789  auto const& qc_arr = mic_fab_vars[MicVar_WDM6::qc]->array(mfi);
790  auto const& qi_arr = mic_fab_vars[MicVar_WDM6::qi]->array(mfi);
791  auto const& qr_arr = mic_fab_vars[MicVar_WDM6::qr]->array(mfi);
792  auto const& qs_arr = mic_fab_vars[MicVar_WDM6::qs]->array(mfi);
793  auto const& qg_arr = mic_fab_vars[MicVar_WDM6::qg]->array(mfi);
794  auto const& nn_arr = mic_fab_vars[MicVar_WDM6::nn]->array(mfi); // Aerosol number
795  auto const& nc_arr = mic_fab_vars[MicVar_WDM6::nc]->array(mfi); // Cloud droplet number
796  auto const& nr_arr = mic_fab_vars[MicVar_WDM6::nr]->array(mfi); // Rain drop number
797  auto const& den_arr = mic_fab_vars[MicVar_WDM6::rho]->array(mfi);
798  auto const& p_arr = mic_fab_vars[MicVar_WDM6::pres]->array(mfi);
799  auto rain_arr = mic_fab_vars[MicVar_WDM6::rain_accum]->array(mfi);
800  auto snow_arr = mic_fab_vars[MicVar_WDM6::snow_accum]->array(mfi);
801  auto graupel_arr = mic_fab_vars[MicVar_WDM6::graupel_accum]->array(mfi);
802  auto precip_arr = mic_fab_vars[MicVar_WDM6::precip_accum]->array(mfi);
803  auto const& sed_arr = m_sed.down->array(mfi);
804 
805  const int ilo = box.smallEnd(0);
806  const int ihi = box.bigEnd(0);
807  const int jlo = box.smallEnd(1);
808  const int jhi = box.bigEnd(1);
809  const int klo = box.smallEnd(2);
810  const int khi = box.bigEnd(2);
811 
812  [[maybe_unused]] const int imlo = fab_box.smallEnd(0);
813  [[maybe_unused]] const int imhi = fab_box.bigEnd(0);
814  [[maybe_unused]] const int jmlo = fab_box.smallEnd(1);
815  [[maybe_unused]] const int jmhi = fab_box.bigEnd(1);
816  [[maybe_unused]] const int kmlo = fab_box.smallEnd(2);
817  [[maybe_unused]] const int kmhi = fab_box.bigEnd(2);
818  const bool has_target_override = (micro_diag_target_column.size() == 2);
819  const int diag_i = has_target_override ? micro_diag_target_column[0] : ilo;
820  const int diag_j = has_target_override ? micro_diag_target_column[1] : jlo;
821 
822  auto const& w1_theta = mic_fab_vars[MicVar_WDM6::theta]->array(mfi);
823 
824 #if defined(ERF_USE_WDM6_FORT) && defined(AMREX_USE_GPU)
825  Arena* Arena_Used = run_wdm6_fort ? The_Pinned_Arena() : The_Async_Arena();
826 #else
827  Arena* Arena_Used = The_Async_Arena();
828 #endif
829 
830 #ifdef ERF_USE_WDM6_FORT
831  if (run_wdm6_fort) {
832  // Fortran bridge path
833  // Create delz array (cell thickness). Uniform dz over the storage box,
834  // then the physical thickness over the valid tile where a terrain /
835  // stretched-mesh nodal height field exists. Mirrors the WSM6 delz_arr
836  // fill (ERF_AdvanceWSM6.cpp:948-961) including the four-corner average.
837  // The ghost entries keep dz_val because the isohelper repacks delz only
838  // over its:ite / kts:kte (ERF_module_mp_wdm6_isohelper.F90:140), so no
839  // ghost value ever reaches the Fortran.
840  const Real dz_val = m_geom.CellSize(2);
841  FArrayBox delz_fab(fab_box, 1, Arena_Used);
842  auto const& delz_arr = delz_fab.array();
843  ParallelFor(fab_box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
844  delz_arr(i,j,k) = dz_val;
845  });
846 
847  const Array4<const Real> z_arr = (m_z_phys_nd) ? m_z_phys_nd->const_array(mfi) : Array4<const Real> {};
848  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
849  delz_arr(i,j,k) = (z_arr) ? Real(0.25) * ( (z_arr(i ,j ,k+1) - z_arr(i ,j ,k))
850  + (z_arr(i+1,j ,k+1) - z_arr(i+1,j ,k))
851  + (z_arr(i ,j+1,k+1) - z_arr(i ,j+1,k))
852  + (z_arr(i+1,j+1,k+1) - z_arr(i+1,j+1,k)) ) : dz_val;
853  });
854 
855  // Surface slabs are anchored at klo, NOT at k = 0. The 2D buffers below
856  // are addressed with the ParallelFor's own k, while the 3D accumulation
857  // fields (rain_arr and friends, allocated on cons_in.boxArray()) are
858  // addressed at klo. Collapsing the slab to 0 makes those two agree only
859  // when klo happens to be 0, which is every case ERF can currently run
860  // because ERF_InitCustomPert_Bubble.H asserts each box spans the whole
861  // column. Anchoring at klo makes the correspondence hold by
862  // construction, and is bit-identical wherever klo == 0.
863  Box box2d(box);
864  box2d.makeSlab(2, klo);
865  Box fab_box2d(fab_box);
866  fab_box2d.makeSlab(2, klo);
867 
868  // Create landmask array in the WRF xland encoding: 1 = land, 2 = water.
869  // xland is handed to wdm62D's slmsk dummy unconverted (see the comment
870  // in mp_wdm6_run), and its only consumer is the maritime/continental
871  // autoconversion threshold at ERF_module_mp_wdm6.F90:628-633, which
872  // tests `slmsk .eq. 2`.
873  //
874  // ERF's lmask uses a DIFFERENT encoding -- 0 = water, 1 = land,
875  // 2 = building (ERF_MakeNewArrays.cpp:488 and :804) -- so the two
876  // cannot be passed through unmapped. Only lmask == 0 is water; a
877  // building cell is land as far as CCN is concerned.
878  FArrayBox xland_fab(fab_box2d, 1, Arena_Used);
879  auto const& xland_arr = xland_fab.array();
880  if (m_lmask != nullptr) {
881  auto const& lmask_arr = m_lmask->const_array(mfi);
882  ParallelFor(fab_box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
883  xland_arr(i,j,k) = (lmask_arr(i,j,0) == 0) ? Real(2.0) : Real(1.0);
884  });
885  } else {
886  // No mask wired (e.g. a restart path that has not set it): land.
887  ParallelFor(fab_box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
888  xland_arr(i,j,k) = Real(1.0);
889  });
890  }
891 
892  // Create 2D accumulation arrays
893  // Fortran bridge uses ims:ime, jms:jme storage bounds; these buffers must
894  // therefore be allocated on fab_box extents even if C++ kernels only
895  // update the valid tile slab (box2d).
896  FArrayBox rainacc_fab(fab_box2d, 1, Arena_Used);
897  FArrayBox rainncv_fab(fab_box2d, 1, Arena_Used);
898  FArrayBox sr_fab(fab_box2d, 1, Arena_Used);
899  FArrayBox snowacc_fab(fab_box2d, 1, Arena_Used);
900  FArrayBox snowncv_fab(fab_box2d, 1, Arena_Used);
901  FArrayBox graupacc_fab(fab_box2d, 1, Arena_Used);
902  FArrayBox graupelncv_fab(fab_box2d, 1, Arena_Used);
903  FArrayBox rainonly_fab(fab_box2d, 1, Arena_Used);
904  FArrayBox snowonly_fab(fab_box2d, 1, Arena_Used);
905 
906  auto const& rainacc_arr = rainacc_fab.array();
907  auto const& rainncv_arr = rainncv_fab.array();
908  auto const& sr_arr = sr_fab.array();
909  auto const& snowacc_arr = snowacc_fab.array();
910  auto const& snowncv_arr = snowncv_fab.array();
911  auto const& graupacc_arr = graupacc_fab.array();
912  auto const& graupelncv_arr = graupelncv_fab.array();
913  auto const& rainonly_arr = rainonly_fab.array();
914  auto const& snowonly_arr = snowonly_fab.array();
915 
916  // Initialize 2D arrays to zero over the full storage slab so the Fortran
917  // bridge never reads ghost entries that were never written.
918  ParallelFor(fab_box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
919  rainacc_arr(i,j,k) = Real(0.0);
920  rainncv_arr(i,j,k) = Real(0.0);
921  sr_arr(i,j,k) = Real(0.0);
922  snowacc_arr(i,j,k) = Real(0.0);
923  snowncv_arr(i,j,k) = Real(0.0);
924  graupacc_arr(i,j,k) = Real(0.0);
925  graupelncv_arr(i,j,k) = Real(0.0);
926  rainonly_arr(i,j,k) = Real(0.0);
927  snowonly_arr(i,j,k) = Real(0.0);
928  });
929 
930  // (Tile-based diagnostics removed - using global diagnostics instead)
931 
932  // Host-only Fortran reads mic_fab_vars and the buffers filled above via
933  // dataPtr(), so the GPU writes must complete before crossing the
934  // language boundary. Without this the Fortran can read delz, xland and
935  // the zeroed accumulators while their kernels are still in flight.
936  // Mirrors ERF_AdvanceWSM6.cpp.
937  Gpu::streamSynchronize();
938 
939  // Call Fortran WDM6
941  t_arr.dataPtr(),
942  qv_arr.dataPtr(), qc_arr.dataPtr(), qi_arr.dataPtr(),
943  qr_arr.dataPtr(), qs_arr.dataPtr(), qg_arr.dataPtr(),
944  nn_arr.dataPtr(), nc_arr.dataPtr(), nr_arr.dataPtr(), // WDM6 number concentrations
945  den_arr.dataPtr(), p_arr.dataPtr(), delz_arr.dataPtr(),
946  static_cast<double>(dt_advance), g, cpd, cpv, rd, rv, t0c, ep1, ep2, qmin,
947  xls, xlv0, xlf0, den0, denr, cliq, cice, psat,
948  ccn0, xland_arr.dataPtr(), // WDM6 parameters
949  rainacc_arr.dataPtr(), rainncv_arr.dataPtr(), sr_arr.dataPtr(),
950  snowacc_arr.dataPtr(), snowncv_arr.dataPtr(),
951  graupacc_arr.dataPtr(), graupelncv_arr.dataPtr(),
952  rainonly_arr.dataPtr(), snowonly_arr.dataPtr(),
953  imlo, imhi, jmlo, jmhi, kmlo, kmhi,
954  ilo, ihi, jlo, jhi, klo, khi,
955  microphysics_debug, diag_i, diag_j);
956 
957  // CRITICAL: Convert updated temperature back to potential temperature
958  // The Fortran WDM6 modifies t_arr (absolute temperature) due to latent heating/cooling
959  // from condensation, evaporation, freezing, melting, etc.
960  // ERF stores theta (potential temperature), so we must convert back: theta = T / exner
961  // This matches WRF's conversion: th(i,k,j) = t(i,k) / pii(i,k,j)
962  auto const& theta_arr = mic_fab_vars[MicVar_WDM6::theta]->array(mfi);
963  const Real configured_rdOcp = m_rdOcp;
964  const bool use_anelastic_reference_pressure =
966  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
967  // Use the same held pressure that was passed to WDM6. In
968  // anelastic mode this is the BaseState p0; in compressible mode
969  // it is the pressure diagnosed from the incoming state.
970  theta_arr(i,j,k) = wdm6_theta_from_temperature_and_pressure(
971  t_arr(i,j,k), p_arr(i,j,k), configured_rdOcp,
972  use_anelastic_reference_pressure);
973  });
974 
975  // (Tile-based precipitation diagnostics removed - using global diagnostics instead)
976 
977  // Accumulate precipitation: rainacc is the total that fell this step and
978  // snowacc the snow plus cloud ice, as in WRF, so the rain and snow alone
979  // come from their own buffers
980  ParallelFor(box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
981  rain_arr(i,j,k) += rainonly_arr(i,j,k);
982  snow_arr(i,j,k) += snowonly_arr(i,j,k);
983  graupel_arr(i,j,k) += graupacc_arr(i,j,k);
984  precip_arr(i,j,k) += rainacc_arr(i,j,k);
985  });
986  } else {
987 #endif
988  // ===================================================================
989  // WDM6 C++ GPU kernel path (adapted from WSM6 with double-moment)
990  // ===================================================================
991 
992  // Working FABs (similar to WSM6 but with WDM6-specific additions)
993  // 3D working arrays
994  const Real dz_val = m_geom.CellSize(2);
995  // Nodal physical heights, when a terrain / stretched mesh supplies them.
996  // Consumed in the delz_arr fill below; kept identical to the bridge
997  // leg's four-corner average so the two legs see the same thickness.
998  const Array4<const Real> z_arr = (m_z_phys_nd) ? m_z_phys_nd->const_array(mfi) : Array4<const Real> {};
999  FArrayBox delz_fab(fab_box,1, Arena_Used);
1000  FArrayBox denfac_fab(fab_box,1, Arena_Used);
1001  FArrayBox xni_fab(fab_box,1, Arena_Used);
1002  FArrayBox rslopec_fab(fab_box,1, Arena_Used);
1003  FArrayBox rslopec2_fab(fab_box,1, Arena_Used);
1004  FArrayBox rslopec3_fab(fab_box,1, Arena_Used);
1005  FArrayBox rslope_fab(fab_box,3, Arena_Used);
1006  FArrayBox rslopeb_fab(fab_box,3, Arena_Used);
1007  FArrayBox rslope2_fab(fab_box,3, Arena_Used);
1008  FArrayBox rslope3_fab(fab_box,3, Arena_Used);
1009  FArrayBox work1_fab(fab_box,3, Arena_Used);
1010  FArrayBox workn_fab(fab_box,1, Arena_Used);
1011  FArrayBox work2_fab(fab_box,1, Arena_Used); // Ventilation factor for diffusion (G11+)
1012  // Anchored at klo, not 0. mstep/numdt/sr/fallc/fall/delqi all live on this
1013  // slab and are written with the ParallelFor's own k, while the G9
1014  // accumulation block reads them back at klo alongside the 3D surface
1015  // fields (rain_arr, delz_arr). With the slab at 0 those two
1016  // conventions only coincide when klo == 0; sr_arr(i,j,klo) and
1017  // fallc_arr(i,j,klo) were otherwise out of bounds on this FAB.
1018  Box box2d(IntVect(ilo,jlo,klo), IntVect(ihi,jhi,klo));
1019  IArrayBox mstep_fab(box2d,1, Arena_Used);
1020  IArrayBox numdt_fab(box2d,1, Arena_Used);
1021  FArrayBox sr_fab(box2d, 1, Arena_Used); // Snow ratio for G9 output
1022  FArrayBox cpm_fab(fab_box,1, Arena_Used);
1023  FArrayBox xl_fab(fab_box,1, Arena_Used);
1024  FArrayBox qsatw_fab(fab_box,1, Arena_Used);
1025  FArrayBox qsati_fab(fab_box,1, Arena_Used);
1026  FArrayBox rhw_fab(fab_box,1, Arena_Used);
1027  FArrayBox rhi_fab(fab_box,1, Arena_Used);
1028  FArrayBox qcr_fab(fab_box,1, Arena_Used);
1029  FArrayBox sed_cell_scratch_fab(fab_box, WDM6SedCellScratch::NumComps, Arena_Used);
1030  Box sed_node_box = amrex::surroundingNodes(fab_box, 2);
1031  FArrayBox sed_node_scratch_fab(sed_node_box, WDM6SedNodeScratch::NumComps, Arena_Used);
1032 
1033  // Process rate arrays
1034  FArrayBox praut_fab(fab_box,1, Arena_Used);
1035  FArrayBox pracw_fab(fab_box,1, Arena_Used);
1036  FArrayBox prevp_fab(fab_box,1, Arena_Used);
1037  FArrayBox pidep_fab(fab_box,1, Arena_Used);
1038  FArrayBox psdep_fab(fab_box,1, Arena_Used);
1039  FArrayBox pgdep_fab(fab_box,1, Arena_Used);
1040  FArrayBox pigen_fab(fab_box,1, Arena_Used);
1041  FArrayBox psaut_fab(fab_box,1, Arena_Used);
1042  FArrayBox pgaut_fab(fab_box,1, Arena_Used);
1043  FArrayBox pcact_fab(fab_box,1, Arena_Used);
1044  FArrayBox pcond_fab(fab_box,1, Arena_Used);
1045  FArrayBox praci_fab(fab_box,1, Arena_Used);
1046  FArrayBox piacr_fab(fab_box,1, Arena_Used);
1047  FArrayBox niacr_fab(fab_box,1, Arena_Used);
1048  FArrayBox psaci_fab(fab_box,1, Arena_Used);
1049  FArrayBox pgaci_fab(fab_box,1, Arena_Used);
1050  FArrayBox psacw_fab(fab_box,1, Arena_Used);
1051  FArrayBox nsacw_fab(fab_box,1, Arena_Used);
1052  FArrayBox pgacw_fab(fab_box,1, Arena_Used);
1053  FArrayBox ngacw_fab(fab_box,1, Arena_Used);
1054  FArrayBox paacw_fab(fab_box,1, Arena_Used);
1055  FArrayBox naacw_fab(fab_box,1, Arena_Used);
1056  FArrayBox pracs_fab(fab_box,1, Arena_Used);
1057  FArrayBox psacr_fab(fab_box,1, Arena_Used);
1058  FArrayBox nsacr_fab(fab_box,1, Arena_Used);
1059  FArrayBox pgacr_fab(fab_box,1, Arena_Used);
1060  FArrayBox ngacr_fab(fab_box,1, Arena_Used);
1061  FArrayBox pgacs_fab(fab_box,1, Arena_Used);
1062  FArrayBox pseml_fab(fab_box,1, Arena_Used);
1063  FArrayBox nseml_fab(fab_box,1, Arena_Used);
1064  FArrayBox pgeml_fab(fab_box,1, Arena_Used);
1065  FArrayBox ngeml_fab(fab_box,1, Arena_Used);
1066  FArrayBox psevp_fab(fab_box,1, Arena_Used);
1067  FArrayBox pgevp_fab(fab_box,1, Arena_Used);
1068 
1069  // Number concentration process rates (WDM6-specific)
1070  FArrayBox ncauto_fab(fab_box,1, Arena_Used); // nc lost to autoconversion
1071  FArrayBox ncaccr_fab(fab_box,1, Arena_Used); // nc lost to accretion by rain
1072  FArrayBox nrauto_fab(fab_box,1, Arena_Used); // nr gained from autoconversion
1073  FArrayBox nraccr_fab(fab_box,1, Arena_Used); // nr gained from accretion
1074  FArrayBox nrevp_fab(fab_box,1, Arena_Used); // nr lost to evaporation
1075  FArrayBox ncact_fab(fab_box,1, Arena_Used); // nn -> nc activation rate
1076  FArrayBox act_ratio_fab(fab_box,1, Arena_Used);
1077  FArrayBox act_fraction_fab(fab_box,1, Arena_Used);
1078  FArrayBox act_raw_fab(fab_box,1, Arena_Used);
1079  FArrayBox act_cap_fab(fab_box,1, Arena_Used);
1080  FArrayBox nccol_fab(fab_box,1, Arena_Used); // cloud self-collection number sink
1081  FArrayBox nrcol_fab(fab_box,1, Arena_Used); // rain self-collection number sink
1082 
1083  // G6 temporary arrays for slope_wdm6 call
1084  FArrayBox qrs_tmp_fab(fab_box,3, Arena_Used); // Temporary qr, qs, qg (components 0,1,2)
1085  FArrayBox ncr_tmp_fab(fab_box,1, Arena_Used); // Temporary nr
1086 
1087  // G11 arrays (particle diameter work array)
1088  FArrayBox avedia_fab(fab_box,2, Arena_Used); // avedia(:,:,1:2) for rain and cloud slopes
1089 
1090  // G8 ice sedimentation arrays
1091  FArrayBox work1c_fab(fab_box,1, Arena_Used); // Ice crystal fall speed
1092  FArrayBox fallc_fab(box2d,1, Arena_Used); // Ice fallout (2D surface)
1093  FArrayBox delqi_fab(box2d,1, Arena_Used); // Ice precipitation at bottom (2D)
1094 
1095  // Rain/snow/graupel fallout through the bottom face (2D surface), the Fortran's
1096  // fall(i,kts,1..3). Kept apart from work1, which holds fall speeds and is
1097  // overwritten by the second slope_wdm6 call (G6) before G9 reads the fallout.
1098  FArrayBox fall_fab(box2d,3, Arena_Used);
1099 
1100  auto const& delz_arr = delz_fab.array();
1101  auto const& denfac_arr = denfac_fab.array();
1102  auto const& xni_arr = xni_fab.array();
1103  auto const& rslopec_arr = rslopec_fab.array();
1104  auto const& rslopec2_arr = rslopec2_fab.array();
1105  auto const& rslopec3_arr = rslopec3_fab.array();
1106  auto const& rslope_arr = rslope_fab.array();
1107  auto const& rslopeb_arr = rslopeb_fab.array();
1108  auto const& rslope2_arr = rslope2_fab.array();
1109  auto const& rslope3_arr = rslope3_fab.array();
1110  auto const& work1_arr = work1_fab.array();
1111  auto const& workn_arr = workn_fab.array();
1112  auto const& work2_arr = work2_fab.array(); // Ventilation factor for diffusion
1113  auto const& mstep_arr = mstep_fab.array();
1114  auto const& numdt_arr = numdt_fab.array();
1115  auto const& sr_arr = sr_fab.array(); // Snow ratio for G9
1116  auto const& cpm_arr = cpm_fab.array();
1117  auto const& xl_arr = xl_fab.array();
1118  auto const& qsatw_arr = qsatw_fab.array();
1119  auto const& qsati_arr = qsati_fab.array();
1120  auto const& rhw_arr = rhw_fab.array();
1121  auto const& rhi_arr = rhi_fab.array();
1122  auto const& qcr_arr = qcr_fab.array();
1123  auto const& sed_cell_scratch_arr = sed_cell_scratch_fab.array();
1124  auto const& sed_node_scratch_arr = sed_node_scratch_fab.array();
1125  auto const& praut_arr = praut_fab.array();
1126  auto const& pracw_arr = pracw_fab.array();
1127  auto const& prevp_arr = prevp_fab.array();
1128  auto const& pidep_arr = pidep_fab.array();
1129  auto const& psdep_arr = psdep_fab.array();
1130  auto const& pgdep_arr = pgdep_fab.array();
1131  auto const& pigen_arr = pigen_fab.array();
1132  auto const& psaut_arr = psaut_fab.array();
1133  auto const& pgaut_arr = pgaut_fab.array();
1134  auto const& pcact_arr = pcact_fab.array();
1135  auto const& pcond_arr = pcond_fab.array();
1136  auto const& praci_arr = praci_fab.array();
1137  auto const& piacr_arr = piacr_fab.array();
1138  auto const& niacr_arr = niacr_fab.array();
1139  auto const& psaci_arr = psaci_fab.array();
1140  auto const& pgaci_arr = pgaci_fab.array();
1141  auto const& psacw_arr = psacw_fab.array();
1142  auto const& nsacw_arr = nsacw_fab.array();
1143  auto const& pgacw_arr = pgacw_fab.array();
1144  auto const& ngacw_arr = ngacw_fab.array();
1145  auto const& paacw_arr = paacw_fab.array();
1146  auto const& naacw_arr = naacw_fab.array();
1147  auto const& pracs_arr = pracs_fab.array();
1148  auto const& psacr_arr = psacr_fab.array();
1149  auto const& nsacr_arr = nsacr_fab.array();
1150  auto const& pgacr_arr = pgacr_fab.array();
1151  auto const& ngacr_arr = ngacr_fab.array();
1152  auto const& pgacs_arr = pgacs_fab.array();
1153  auto const& pseml_arr = pseml_fab.array();
1154  auto const& nseml_arr = nseml_fab.array();
1155  auto const& pgeml_arr = pgeml_fab.array();
1156  auto const& ngeml_arr = ngeml_fab.array();
1157  auto const& psevp_arr = psevp_fab.array();
1158  auto const& pgevp_arr = pgevp_fab.array();
1159  auto const& ncauto_arr = ncauto_fab.array();
1160  auto const& ncaccr_arr = ncaccr_fab.array();
1161  auto const& nrauto_arr = nrauto_fab.array();
1162  auto const& nraccr_arr = nraccr_fab.array();
1163  auto const& nrevp_arr = nrevp_fab.array();
1164  auto const& ncact_arr = ncact_fab.array();
1165  auto const& act_ratio_arr = act_ratio_fab.array();
1166  auto const& act_fraction_arr = act_fraction_fab.array();
1167  auto const& act_raw_arr = act_raw_fab.array();
1168  auto const& act_cap_arr = act_cap_fab.array();
1169  auto const& nccol_arr = nccol_fab.array();
1170  auto const& nrcol_arr = nrcol_fab.array();
1171  auto const& qrs_tmp_arr = qrs_tmp_fab.array(); // G6: temporary qr, qs, qg
1172  auto const& ncr_tmp_arr = ncr_tmp_fab.array(); // G6: temporary nr
1173  auto const& avedia_arr = avedia_fab.array(); // G11: particle diameter work array
1174 
1175  // G8 array references
1176  auto const& work1c_arr = work1c_fab.array(); // Ice crystal fall speed
1177  auto const& fallc_arr = fallc_fab.array(); // Ice fallout (2D)
1178  auto const& fall_arr = fall_fab.array(); // Rain/snow/graupel fallout (2D)
1179  auto const& delqi_arr = delqi_fab.array(); // Ice precip at bottom (2D)
1180 
1181  // Clamp negative values and enforce minimums
1182  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1183  delz_arr(i,j,k) = (z_arr) ? Real(0.25) * ( (z_arr(i ,j ,k+1) - z_arr(i ,j ,k))
1184  + (z_arr(i+1,j ,k+1) - z_arr(i+1,j ,k))
1185  + (z_arr(i ,j+1,k+1) - z_arr(i ,j+1,k))
1186  + (z_arr(i+1,j+1,k+1) - z_arr(i+1,j+1,k)) ) : dz_val;
1187  qc_arr(i,j,k) = amrex::max(qc_arr(i,j,k), Real(0.0));
1188  qr_arr(i,j,k) = amrex::max(qr_arr(i,j,k), Real(0.0));
1189  qi_arr(i,j,k) = amrex::max(qi_arr(i,j,k), Real(0.0));
1190  qs_arr(i,j,k) = amrex::max(qs_arr(i,j,k), Real(0.0));
1191  qg_arr(i,j,k) = amrex::max(qg_arr(i,j,k), Real(0.0));
1192 
1193  // Match Fortran pre-G3 behavior: nc is non-negative here, but not floored to ncmin yet.
1194  nc_arr(i,j,k) = amrex::max(nc_arr(i,j,k), Real(0.0));
1195  nr_arr(i,j,k) = amrex::max(nr_arr(i,j,k), Real(0.0));
1196  // CCN is clamped into [1.e8, 2.e10], not merely floored at zero:
1197  // ncr(i,k,1) = min(max(ncr(i,k,1),1.e8),2.e10)
1198  // at ERF_module_mp_wdm6.F90:604. This re-seeds the aerosol field to
1199  // the background concentration at the top of every macro timestep,
1200  // so activation depletion never carries across steps. A plain
1201  // max(.,0) is a no-op on step 1, where Init() has just set nn to
1202  // ccn0 = 1.e8 everywhere, and only diverges from step 2 onward once
1203  // activation has drawn nn below the floor. Both literals are exact
1204  // in float32, so the precision contract is satisfied either way.
1205  nn_arr(i,j,k) = amrex::min(amrex::max(nn_arr(i,j,k), wdm6_literal(1.0e8)),
1206  wdm6_literal(2.0e10));
1207  });
1208 
1209  // Compute cpm and xl once from initial state
1210  const Real xlv1_loc = m_xlv1;
1211  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1212  cpm_arr(i,j,k) = wdm6_cpmcal(qv_arr(i,j,k), Real(qmin), Real(cpd), Real(cpv));
1213  xl_arr(i,j,k) = wdm6_xlcal(t_arr(i,j,k), Real(xlv0), xlv1_loc, Real(t0c));
1214  });
1215 
1216  // Minor timestep loop (match WSM6 structure)
1217  const int wdm6_loops = std::max(
1218  static_cast<int>(std::round(dt_advance / Real(120.0))), 1); // dtcldcr = 120s
1219  const Real dtcld = dt_advance / static_cast<Real>(wdm6_loops);
1220 
1221  // Extract WDM6 coefficients
1222  const Real qc0_loc = m_qc0;
1223  const Real qc1_loc = m_qc1;
1224  const Real qck1_loc = m_qck1;
1225  const Real pidnc_loc = m_pidnc;
1226  const Real pidnr_loc = m_pidnr;
1227  const Real pvtr_loc = m_pvtr;
1228  const Real pvtrn_loc = m_pvtrn;
1229  const Real pvts_loc = m_pvts;
1230  const Real pvtg_loc = m_pvtg;
1231  const Real slope_bvtg_loc = m_bvtg;
1232  const Real pidn0s_loc = m_pidn0s;
1233  const Real pidn0g_loc = m_pidn0g;
1234  const Real rslopermax_loc = m_rslopermax;
1235  const Real rsloperbmax_loc = m_rsloperbmax;
1236  const Real rsloper2max_loc = m_rsloper2max;
1237  const Real rsloper3max_loc = m_rsloper3max;
1238  const Real rslopesmax_loc = m_rslopesmax;
1239  const Real rslopesbmax_loc = m_rslopesbmax;
1240  const Real rslopes2max_loc = m_rslopes2max;
1241  const Real rslopes3max_loc = m_rslopes3max;
1242  const Real rslopegmax_loc = m_rslopegmax;
1243  const Real rslopegbmax_loc = m_rslopegbmax;
1244  const Real rslopeg2max_loc = m_rslopeg2max;
1245  const Real rslopeg3max_loc = m_rslopeg3max;
1246  const Real rslopecmax_loc = m_rslopecmax;
1247  const Real rslopec2max_loc = m_rslopec2max;
1248  const Real rslopec3max_loc = m_rslopec3max;
1249  const Real precs1_loc = m_precs1;
1250  const Real precs2_loc = m_precs2;
1251  const Real precg1_loc = m_precg1;
1252  const Real precg2_loc = m_precg2;
1253  const Real precr1_loc = m_precr1;
1254  const Real precr2_loc = m_precr2;
1255  const Real n0g_loc = m_n0g;
1256  const Real pi_wdm6_loc = m_pi_wdm6;
1257  const Real pacrc_loc = m_pacrc;
1258  const Real pacrg_loc = m_pacrg;
1259  const Real g4pbr_loc = m_g4pbr;
1260  const Real g7pbr_loc = m_g7pbr;
1261  constexpr Real pfrz1_loc = pfrz1;
1262  constexpr Real pfrz2_loc = pfrz2;
1263  const int diag_k = klo;
1264 
1265  // Maritime/continental autoconversion threshold. The Fortran selects on
1266  // `slmsk .eq. 2` (ERF_module_mp_wdm6.F90:628-633) where slmsk is xland
1267  // in the WRF encoding, so 2 means WATER and picks qc0. ERF's lmask
1268  // encodes water as 0, not 2 (ERF_MakeNewArrays.cpp:488, :804), so the
1269  // test must be against 0 here. Testing == 2 would select maritime for
1270  // building cells and would disagree with the bridge leg, which maps
1271  // lmask == 0 to xland = 2.0.
1272  if (m_lmask != nullptr) {
1273  auto const& lmask_arr = m_lmask->const_array(mfi);
1274  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1275  qcr_arr(i,j,k) = (lmask_arr(i,j,0) == 0) ? qc0_loc : qc1_loc;
1276  });
1277  } else {
1278  // Match the bridge leg's no-mask posture: default to land.
1279  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1280  qcr_arr(i,j,k) = qc1_loc;
1281  });
1282  }
1283 
1284  // At the top of a fine patch, rain, snow, ... come in from the coarse level: add
1285  // each minor step's share of it to the top cell before that step, so it falls with
1286  // what is already there, and record it on the top face.
1287  const auto inflow_arr = (m_sed_inflow) ? m_sed_inflow->const_array(mfi)
1288  : Array4<const Real>{};
1289  const Real inflow_share = Real(1) / static_cast<Real>(wdm6_loops);
1290 
1291  for (int loop = 0; loop < wdm6_loops; ++loop) {
1292  if (inflow_arr) {
1293  ParallelFor(box2d, [=] AMREX_GPU_DEVICE (int i, int j, int) {
1294  if (inflow_arr(i,j,khi+1,WDM6Sed::NumComps) < Real(0.5)) { return; }
1295  const Real fac = inflow_share / (den_arr(i,j,khi) * delz_arr(i,j,khi));
1296  qi_arr(i,j,khi) += inflow_arr(i,j,khi+1,WDM6Sed::qi) * fac;
1297  qr_arr(i,j,khi) += inflow_arr(i,j,khi+1,WDM6Sed::qr) * fac;
1298  qs_arr(i,j,khi) += inflow_arr(i,j,khi+1,WDM6Sed::qs) * fac;
1299  qg_arr(i,j,khi) += inflow_arr(i,j,khi+1,WDM6Sed::qg) * fac;
1300  nr_arr(i,j,khi) += inflow_arr(i,j,khi+1,WDM6Sed::nr) * fac;
1301  for (int n = 0; n < WDM6Sed::NumComps; ++n) {
1302  sed_arr(i,j,khi+1,n) += inflow_arr(i,j,khi+1,n) * inflow_share;
1303  }
1304  });
1305  }
1306  // ============================================================
1307  // Step 1: Density factor (G1b / DENFAC)
1308  // ============================================================
1309 
1310  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1311  denfac_arr(i,j,k) = std::sqrt(Real(den0) / den_arr(i,j,k));
1312  });
1313 
1314 
1315  // ============================================================
1316  // Step 2: Saturation calculations (G1c / QSAT)
1317  // ============================================================
1318  {
1319  const Real ttp = Real(t0c) + wdm6_literal(0.01);
1320  const Real dldt = Real(cpv) - Real(cliq);
1321  const Real xa = -dldt / Real(rv);
1322  const Real xb = xa + Real(xlv0) / (Real(rv) * ttp);
1323  const Real dldti = Real(cpv) - Real(cice);
1324  const Real xai = -dldti / Real(rv);
1325  const Real xbi = xai + Real(xls) / (Real(rv) * ttp);
1326 
1327 
1328  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1329  const Real tr = ttp / t_arr(i,j,k);
1330 
1331  // Saturation over water
1332  Real qsw = Real(psat) * std::exp(std::log(tr) * xa) * std::exp(xb * (Real(1.0) - tr));
1333  qsw = amrex::min(qsw, wdm6_literal(0.99) * p_arr(i,j,k));
1334  qsw = Real(ep2) * qsw / (p_arr(i,j,k) - qsw);
1335  qsw = amrex::max(qsw, Real(qmin));
1336  qsatw_arr(i,j,k) = qsw;
1337  rhw_arr(i,j,k) = amrex::max(qv_arr(i,j,k) / qsw, Real(qmin));
1338 
1339  // Saturation over ice
1340  Real qsi = (t_arr(i,j,k) < ttp)
1341  ? Real(psat) * std::exp(std::log(tr) * xai) * std::exp(xbi * (Real(1.0) - tr))
1342  : Real(psat) * std::exp(std::log(tr) * xa) * std::exp(xb * (Real(1.0) - tr));
1343  qsi = amrex::min(qsi, wdm6_literal(0.99) * p_arr(i,j,k));
1344  qsi = Real(ep2) * qsi / (p_arr(i,j,k) - qsi);
1345  qsi = amrex::max(qsi, Real(qmin));
1346  qsati_arr(i,j,k) = qsi;
1347  rhi_arr(i,j,k) = amrex::max(qv_arr(i,j,k) / qsi, Real(qmin));
1348  });
1349  }
1350 
1351 
1352  // ============================================================
1353  // Step 3: Zero process rates (G2 / RATES_ZERO)
1354  // ============================================================
1355 
1356  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1357  praut_arr(i,j,k) = Real(0.0);
1358  pracw_arr(i,j,k) = Real(0.0);
1359  prevp_arr(i,j,k) = Real(0.0);
1360  pidep_arr(i,j,k) = Real(0.0);
1361  psdep_arr(i,j,k) = Real(0.0);
1362  pgdep_arr(i,j,k) = Real(0.0);
1363  pigen_arr(i,j,k) = Real(0.0);
1364  psaut_arr(i,j,k) = Real(0.0);
1365  pgaut_arr(i,j,k) = Real(0.0);
1366  pcact_arr(i,j,k) = Real(0.0);
1367  pcond_arr(i,j,k) = Real(0.0);
1368  praci_arr(i,j,k) = Real(0.0);
1369  piacr_arr(i,j,k) = Real(0.0);
1370  niacr_arr(i,j,k) = Real(0.0);
1371  psaci_arr(i,j,k) = Real(0.0);
1372  pgaci_arr(i,j,k) = Real(0.0);
1373  psacw_arr(i,j,k) = Real(0.0);
1374  nsacw_arr(i,j,k) = Real(0.0);
1375  pgacw_arr(i,j,k) = Real(0.0);
1376  ngacw_arr(i,j,k) = Real(0.0);
1377  paacw_arr(i,j,k) = Real(0.0);
1378  naacw_arr(i,j,k) = Real(0.0);
1379  pracs_arr(i,j,k) = Real(0.0);
1380  psacr_arr(i,j,k) = Real(0.0);
1381  nsacr_arr(i,j,k) = Real(0.0);
1382  pgacr_arr(i,j,k) = Real(0.0);
1383  ngacr_arr(i,j,k) = Real(0.0);
1384  pgacs_arr(i,j,k) = Real(0.0);
1385  pseml_arr(i,j,k) = Real(0.0);
1386  nseml_arr(i,j,k) = Real(0.0);
1387  pgeml_arr(i,j,k) = Real(0.0);
1388  ngeml_arr(i,j,k) = Real(0.0);
1389  psevp_arr(i,j,k) = Real(0.0);
1390  pgevp_arr(i,j,k) = Real(0.0);
1391  ncauto_arr(i,j,k) = Real(0.0);
1392  ncaccr_arr(i,j,k) = Real(0.0);
1393  nrauto_arr(i,j,k) = Real(0.0);
1394  nraccr_arr(i,j,k) = Real(0.0);
1395  nrevp_arr(i,j,k) = Real(0.0);
1396  ncact_arr(i,j,k) = Real(0.0);
1397  act_ratio_arr(i,j,k) = Real(0.0);
1398  act_fraction_arr(i,j,k) = Real(0.0);
1399  act_raw_arr(i,j,k) = Real(0.0);
1400  act_cap_arr(i,j,k) = Real(0.0);
1401  nccol_arr(i,j,k) = Real(0.0);
1402  nrcol_arr(i,j,k) = Real(0.0);
1403  });
1404 
1405 
1406  // ============================================================
1407  // Step 3b: CLOUD_SETUP (G3)
1408  // Exact port of the frozen Fortran block:
1409  // - cloud droplet slope parameter rslopec{,2,3}
1410  // - ice number concentration xni
1411  // ============================================================
1412  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1413  if (qc_arr(i,j,k) <= Real(qmin) || nc_arr(i,j,k) <= Real(1.e1)) {
1414  rslopec_arr(i,j,k) = rslopecmax_loc;
1415  rslopec2_arr(i,j,k) = rslopec2max_loc;
1416  rslopec3_arr(i,j,k) = rslopec3max_loc;
1417  } else {
1418  rslopec_arr(i,j,k) = wdm6_rslopec_exact(qc_arr(i,j,k), den_arr(i,j,k),
1419  nc_arr(i,j,k), pidnc_loc);
1420  rslopec2_arr(i,j,k) = rslopec_arr(i,j,k) * rslopec_arr(i,j,k);
1421  rslopec3_arr(i,j,k) = rslopec2_arr(i,j,k) * rslopec_arr(i,j,k);
1422  }
1423  xni_arr(i,j,k) = wdm6_xni_exact(qi_arr(i,j,k), den_arr(i,j,k), Real(qmin));
1424  });
1425 
1426 
1427  // ============================================================
1428  // Step 3c: SLOPE1 (G4)
1429  // Exact first packed slope_wdm6 surface for rain/snow/graupel.
1430  // ============================================================
1431  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1432  Real rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3, rain_vt, rain_vtn;
1433  Real snow_rslope, snow_rslopeb, snow_rslope2, snow_rslope3, snow_vt, snow_n0sfac;
1434  Real graup_rslope, graup_rslopeb, graup_rslope2, graup_rslope3, graup_vt;
1435 
1436  wdm6_slope_rain_cell(qr_arr(i,j,k), nr_arr(i,j,k), den_arr(i,j,k), denfac_arr(i,j,k),
1437  Real(qcrmin), Real(nrmin),
1438  rslopermax_loc, rsloperbmax_loc, rsloper2max_loc, rsloper3max_loc,
1439  Real(bvtr), pvtr_loc, pvtrn_loc, pidnr_loc,
1440  rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3,
1441  rain_vt, rain_vtn);
1442  wdm6_slope_snow_cell(qs_arr(i,j,k), den_arr(i,j,k), denfac_arr(i,j,k), t_arr(i,j,k),
1443  pidn0s_loc, Real(alpha_wdm6), Real(n0smax), Real(n0s),
1445  rslopesmax_loc, rslopesbmax_loc, rslopes2max_loc, rslopes3max_loc,
1446  Real(bvts), pvts_loc,
1447  snow_rslope, snow_rslopeb, snow_rslope2, snow_rslope3, snow_vt,
1448  snow_n0sfac);
1449  wdm6_slope_graup_cell(qg_arr(i,j,k), den_arr(i,j,k), denfac_arr(i,j,k),
1450  pidn0g_loc, Real(qcrmin),
1451  rslopegmax_loc, rslopegbmax_loc, rslopeg2max_loc, rslopeg3max_loc,
1452  slope_bvtg_loc, pvtg_loc,
1453  graup_rslope, graup_rslopeb, graup_rslope2, graup_rslope3, graup_vt);
1454 
1455  rslope_arr(i,j,k,0) = rain_rslope;
1456  rslope_arr(i,j,k,1) = snow_rslope;
1457  rslope_arr(i,j,k,2) = graup_rslope;
1458  rslopeb_arr(i,j,k,0) = rain_rslopeb;
1459  rslopeb_arr(i,j,k,1) = snow_rslopeb;
1460  rslopeb_arr(i,j,k,2) = graup_rslopeb;
1461  rslope2_arr(i,j,k,0) = rain_rslope2;
1462  rslope2_arr(i,j,k,1) = snow_rslope2;
1463  rslope2_arr(i,j,k,2) = graup_rslope2;
1464  rslope3_arr(i,j,k,0) = rain_rslope3;
1465  rslope3_arr(i,j,k,1) = snow_rslope3;
1466  rslope3_arr(i,j,k,2) = graup_rslope3;
1467  work1_arr(i,j,k,0) = rain_vt;
1468  work1_arr(i,j,k,1) = snow_vt;
1469  work1_arr(i,j,k,2) = graup_vt;
1470  workn_arr(i,j,k) = rain_vtn;
1471  });
1472 
1473  // ============================================================
1474  // Step 3d: Rain sedimentation setup (G5a)
1475  // Determine rain/number substep count from normalized work1/workn.
1476  // ============================================================
1477  ParallelFor(box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1478  mstep_arr(i,j,k) = 1;
1479  numdt_arr(i,j,k) = 1;
1480  sr_arr(i,j,k) = Real(0.0); // Initialize snow ratio to zero
1481  fall_arr(i,j,k,0) = Real(0.0);
1482  fall_arr(i,j,k,1) = Real(0.0);
1483  fall_arr(i,j,k,2) = Real(0.0);
1484  });
1485  ParallelFor(box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1486  int mstep_loc = 1;
1487  int numdt_loc = 1;
1488  for (int kk = khi; kk >= klo; --kk) {
1489  work1_arr(i,j,kk,0) = work1_arr(i,j,kk,0) / delz_arr(i,j,kk);
1490  workn_arr(i,j,kk) = workn_arr(i,j,kk) / delz_arr(i,j,kk);
1491  numdt_loc = amrex::max(static_cast<int>(amrex::max(work1_arr(i,j,kk,0),
1492  workn_arr(i,j,kk)) * dtcld + Real(0.5)),
1493  1);
1494  if (numdt_loc >= mstep_loc) {
1495  mstep_loc = numdt_loc;
1496  }
1497  }
1498  mstep_arr(i,j,k) = mstep_loc;
1499  numdt_arr(i,j,k) = numdt_loc;
1500  });
1501  ReduceOps<ReduceOpMax> reduce_op;
1502  ReduceData<int> reduce_data(reduce_op);
1503  reduce_op.eval(box2d, reduce_data,
1504  [=] AMREX_GPU_DEVICE (int i, int j, int k) -> GpuTuple<int> {
1505  return {mstep_arr(i,j,k)};
1506  });
1507  int mstepmax = amrex::get<0>(reduce_data.value());
1508  amrex::ignore_unused(mstepmax);
1509 
1510  // ============================================================
1511  // Step 3e: Rain sedimentation substeps (G5b)
1512  // Match the bounded top-down rain/nr transport loop and
1513  // slope_rain refresh that immediately follows G5a in Fortran.
1514  // ============================================================
1515  ParallelFor(box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1516  amrex::ignore_unused(k);
1517  const int col_mstep = mstep_arr(i,j,klo);
1518 
1519  // The face fluxes are what the cells above each face lose: add the
1520  // top-down sums of rho*q*dz now, and subtract them after the substeps.
1521  sedimentation_add_column_sums(sed_arr, WDM6Sed::qr, i, j, klo, khi, Real(1.0),
1522  [&](int kk) { return den_arr(i,j,kk) * qr_arr(i,j,kk) * delz_arr(i,j,kk); });
1523  sedimentation_add_column_sums(sed_arr, WDM6Sed::nr, i, j, klo, khi, Real(1.0),
1524  [&](int kk) { return den_arr(i,j,kk) * nr_arr(i,j,kk) * delz_arr(i,j,kk); });
1525 
1526  for (int n = 1; n <= mstepmax; ++n) {
1527  if (n > col_mstep) {
1528  continue;
1529  }
1530 
1531  const int kk_top = khi;
1532  const Real top_flux_qr = den_arr(i,j,kk_top) * qr_arr(i,j,kk_top)
1533  * work1_arr(i,j,kk_top,0) / static_cast<Real>(col_mstep);
1534  const Real top_flux_nr = nr_arr(i,j,kk_top)
1535  * workn_arr(i,j,kk_top) / static_cast<Real>(col_mstep);
1536  // fall(i,k,1) = fall(i,k,1)+falk(i,k,1); only the bottom face is used (G9)
1537  if (kk_top == klo) { fall_arr(i,j,klo,0) += top_flux_qr; }
1538 
1539  qr_arr(i,j,kk_top) = amrex::max(
1540  qr_arr(i,j,kk_top) - top_flux_qr * dtcld / den_arr(i,j,kk_top),
1541  Real(0.0));
1542  nr_arr(i,j,kk_top) = amrex::max(
1543  nr_arr(i,j,kk_top) - top_flux_nr * dtcld,
1544  Real(0.0));
1545 
1546  Real flux_qr_above = top_flux_qr;
1547  Real flux_nr_above = top_flux_nr;
1548  for (int kk = khi - 1; kk >= klo; --kk) {
1549  const Real flux_qr = den_arr(i,j,kk) * qr_arr(i,j,kk)
1550  * work1_arr(i,j,kk,0) / static_cast<Real>(col_mstep);
1551  const Real flux_nr = nr_arr(i,j,kk)
1552  * workn_arr(i,j,kk) / static_cast<Real>(col_mstep);
1553  if (kk == klo) { fall_arr(i,j,klo,0) += flux_qr; }
1554 
1555  const Real dqr_self = amrex::min(
1556  flux_qr * dtcld / den_arr(i,j,kk),
1557  qr_arr(i,j,kk));
1558  const Real dqr_from_above = amrex::min(
1559  flux_qr_above * delz_arr(i,j,kk+1) / delz_arr(i,j,kk)
1560  * dtcld / den_arr(i,j,kk),
1561  qr_arr(i,j,kk+1));
1562  const Real dnr_self = amrex::min(
1563  flux_nr * dtcld,
1564  nr_arr(i,j,kk));
1565  const Real dnr_from_above = amrex::min(
1566  flux_nr_above * delz_arr(i,j,kk+1) / delz_arr(i,j,kk)
1567  * dtcld,
1568  nr_arr(i,j,kk+1));
1569 
1570  qr_arr(i,j,kk) = amrex::max(
1571  qr_arr(i,j,kk) - dqr_self + dqr_from_above,
1572  Real(0.0));
1573  nr_arr(i,j,kk) = amrex::max(
1574  nr_arr(i,j,kk) - dnr_self + dnr_from_above,
1575  Real(0.0));
1576 
1577  flux_qr_above = flux_qr;
1578  flux_nr_above = flux_nr;
1579  }
1580 
1581  for (int kk = klo; kk <= khi; ++kk) {
1582  Real rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3;
1583  Real rain_vt, rain_vtn;
1585  qr_arr(i,j,kk), nr_arr(i,j,kk),
1586  den_arr(i,j,kk), denfac_arr(i,j,kk),
1587  Real(qcrmin), Real(nrmin),
1588  rslopermax_loc, rsloperbmax_loc,
1589  rsloper2max_loc, rsloper3max_loc,
1590  Real(bvtr), pvtr_loc, pvtrn_loc, pidnr_loc,
1591  rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3,
1592  rain_vt, rain_vtn);
1593  rslope_arr(i,j,kk,0) = rain_rslope;
1594  rslopeb_arr(i,j,kk,0) = rain_rslopeb;
1595  rslope2_arr(i,j,kk,0) = rain_rslope2;
1596  rslope3_arr(i,j,kk,0) = rain_rslope3;
1597  work1_arr(i,j,kk,0) = rain_vt / delz_arr(i,j,kk);
1598  workn_arr(i,j,kk) = rain_vtn / delz_arr(i,j,kk);
1599  }
1600  }
1601 
1602  sedimentation_add_column_sums(sed_arr, WDM6Sed::qr, i, j, klo, khi, Real(-1.0),
1603  [&](int kk) { return den_arr(i,j,kk) * qr_arr(i,j,kk) * delz_arr(i,j,kk); });
1604  sedimentation_add_column_sums(sed_arr, WDM6Sed::nr, i, j, klo, khi, Real(-1.0),
1605  [&](int kk) { return den_arr(i,j,kk) * nr_arr(i,j,kk) * delz_arr(i,j,kk); });
1606  });
1607 
1608  // ============================================================
1609  // Step 3f: Snow/graupel sedimentation (G5c)
1610  // Exact bounded NISLFV_SG slice plus lower-boundary slab fall.
1611  // ============================================================
1612 
1613  ParallelFor(box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1614  amrex::ignore_unused(k);
1615  const int km = khi - klo + 1;
1616  auto dz_col = [&](int kk) -> amrex::Real& {
1617  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::dz);
1618  };
1619  auto den_col = [&](int kk) -> amrex::Real& {
1620  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::den);
1621  };
1622  auto denfac_col = [&](int kk) -> amrex::Real& {
1623  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::denfac);
1624  };
1625  auto tk_col = [&](int kk) -> amrex::Real& {
1626  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::tk);
1627  };
1628  auto work_col = [&](int kk) -> amrex::Real& {
1629  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::work_col);
1630  };
1631  auto rq_col = [&](int kk) -> amrex::Real& {
1632  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::rq_col);
1633  };
1634  auto rq2_col = [&](int kk) -> amrex::Real& {
1635  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::rq2_col);
1636  };
1637  for (int kk = 0; kk < km; ++kk) {
1638  const int k3 = klo + kk;
1639  dz_col(kk) = delz_arr(i,j,k3);
1640  den_col(kk) = den_arr(i,j,k3);
1641  denfac_col(kk) = denfac_arr(i,j,k3);
1642  tk_col(kk) = t_arr(i,j,k3);
1643  rq_col(kk) = den_col(kk) * qs_arr(i,j,k3);
1644  rq2_col(kk) = den_col(kk) * qg_arr(i,j,k3);
1645  const Real qsum = amrex::max(qs_arr(i,j,k3) + qg_arr(i,j,k3), wdm6_literal(1.0e-15));
1646  work_col(kk) = (qsum > wdm6_literal(1.0e-15))
1647  ? (work1_arr(i,j,k3,1) * qs_arr(i,j,k3) + work1_arr(i,j,k3,2) * qg_arr(i,j,k3)) / qsum
1648  : Real(0.0);
1649  }
1650 
1651  // Face fluxes, as for rain: the top-down sums before, minus those after
1652  sedimentation_add_column_sums(sed_arr, WDM6Sed::qs, i, j, klo, khi, Real(1.0),
1653  [&](int kk) { return den_arr(i,j,kk) * qs_arr(i,j,kk) * delz_arr(i,j,kk); });
1654  sedimentation_add_column_sums(sed_arr, WDM6Sed::qg, i, j, klo, khi, Real(1.0),
1655  [&](int kk) { return den_arr(i,j,kk) * qg_arr(i,j,kk) * delz_arr(i,j,kk); });
1656 
1657  Real delqrs2 = Real(0.0);
1658  Real delqrs3 = Real(0.0);
1660  km, &delqrs2, &delqrs3, dtcld, 1,
1661  pidn0s_loc, pidn0g_loc, Real(qcrmin), Real(alpha_wdm6), Real(n0smax), Real(n0s), wdm6_slope_t0c,
1662  rslopesmax_loc, rslopesbmax_loc, rslopes2max_loc, rslopes3max_loc, Real(bvts), pvts_loc,
1663  rslopegmax_loc, rslopegbmax_loc, rslopeg2max_loc, rslopeg3max_loc, slope_bvtg_loc, pvtg_loc,
1664  sed_cell_scratch_arr, sed_node_scratch_arr, i, j, klo);
1665 
1666  for (int kk = 0; kk < km; ++kk) {
1667  const int k3 = klo + kk;
1668  qs_arr(i,j,k3) = amrex::max(rq_col(kk) / den_col(kk), Real(0.0));
1669  qg_arr(i,j,k3) = amrex::max(rq2_col(kk) / den_col(kk), Real(0.0));
1670  }
1671  sedimentation_add_column_sums(sed_arr, WDM6Sed::qs, i, j, klo, khi, Real(-1.0),
1672  [&](int kk) { return den_arr(i,j,kk) * qs_arr(i,j,kk) * delz_arr(i,j,kk); });
1673  sedimentation_add_column_sums(sed_arr, WDM6Sed::qg, i, j, klo, khi, Real(-1.0),
1674  [&](int kk) { return den_arr(i,j,kk) * qg_arr(i,j,kk) * delz_arr(i,j,kk); });
1675 
1676  fall_arr(i,j,klo,1) = delqrs2 / dz_col(0) / dtcld; // fall(i,1,2)
1677  fall_arr(i,j,klo,2) = delqrs3 / dz_col(0) / dtcld; // fall(i,1,3)
1678  });
1679 
1680 
1681  // ============================================================
1682  // Step 3g: Second slope_wdm6 call after sedimentation (G6)
1683  // Recompute slope parameters for all species after G5c sed.
1684  // ============================================================
1685 
1686  // Copy current state to temporary arrays (qrs_tmp, ncr_tmp)
1687  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1688  qrs_tmp_arr(i,j,k,0) = qr_arr(i,j,k); // Fortran qrs(:,:,1)
1689  qrs_tmp_arr(i,j,k,1) = qs_arr(i,j,k); // Fortran qrs(:,:,2)
1690  qrs_tmp_arr(i,j,k,2) = qg_arr(i,j,k); // Fortran qrs(:,:,3)
1691  ncr_tmp_arr(i,j,k) = nr_arr(i,j,k); // Fortran ncr(:,:,3)
1692  });
1693 
1694  // Call slope_wdm6: compute slope parameters for rain/snow/graupel
1695  // This parallels the Fortran call: slope_wdm6(qrs_tmp,ncr_tmp,...)
1696  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1697  Real rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3, rain_vt, rain_vtn;
1698  Real snow_rslope, snow_rslopeb, snow_rslope2, snow_rslope3, snow_vt, snow_n0sfac;
1699  Real graup_rslope, graup_rslopeb, graup_rslope2, graup_rslope3, graup_vt;
1700 
1701  // Compute slope parameters using temporary (post-sedimentation) values
1702  wdm6_slope_rain_cell(qrs_tmp_arr(i,j,k,0), ncr_tmp_arr(i,j,k), den_arr(i,j,k), denfac_arr(i,j,k),
1703  Real(qcrmin), Real(nrmin),
1704  rslopermax_loc, rsloperbmax_loc, rsloper2max_loc, rsloper3max_loc,
1705  Real(bvtr), pvtr_loc, pvtrn_loc, pidnr_loc,
1706  rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3,
1707  rain_vt, rain_vtn);
1708  wdm6_slope_snow_cell(qrs_tmp_arr(i,j,k,1), den_arr(i,j,k), denfac_arr(i,j,k), t_arr(i,j,k),
1709  pidn0s_loc, Real(alpha_wdm6), Real(n0smax), Real(n0s),
1711  rslopesmax_loc, rslopesbmax_loc, rslopes2max_loc, rslopes3max_loc,
1712  Real(bvts), pvts_loc,
1713  snow_rslope, snow_rslopeb, snow_rslope2, snow_rslope3, snow_vt,
1714  snow_n0sfac);
1715  wdm6_slope_graup_cell(qrs_tmp_arr(i,j,k,2), den_arr(i,j,k), denfac_arr(i,j,k),
1716  pidn0g_loc, Real(qcrmin),
1717  rslopegmax_loc, rslopegbmax_loc, rslopeg2max_loc, rslopeg3max_loc,
1718  slope_bvtg_loc, pvtg_loc,
1719  graup_rslope, graup_rslopeb, graup_rslope2, graup_rslope3, graup_vt);
1720 
1721  // Store results in output slope arrays
1722  rslope_arr(i,j,k,0) = rain_rslope;
1723  rslope_arr(i,j,k,1) = snow_rslope;
1724  rslope_arr(i,j,k,2) = graup_rslope;
1725  rslopeb_arr(i,j,k,0) = rain_rslopeb;
1726  rslopeb_arr(i,j,k,1) = snow_rslopeb;
1727  rslopeb_arr(i,j,k,2) = graup_rslopeb;
1728  rslope2_arr(i,j,k,0) = rain_rslope2;
1729  rslope2_arr(i,j,k,1) = snow_rslope2;
1730  rslope2_arr(i,j,k,2) = graup_rslope2;
1731  rslope3_arr(i,j,k,0) = rain_rslope3;
1732  rslope3_arr(i,j,k,1) = snow_rslope3;
1733  rslope3_arr(i,j,k,2) = graup_rslope3;
1734  work1_arr(i,j,k,0) = rain_vt;
1735  work1_arr(i,j,k,1) = snow_vt;
1736  work1_arr(i,j,k,2) = graup_vt;
1737  workn_arr(i,j,k) = rain_vtn;
1738  });
1739 
1740 
1741  // ============================================================
1742  // WDM6-CPP_PRE_G7
1743  // ============================================================
1744 
1745  // ============================================================
1746  // Step 3h: G7 warm-phase snow/graupel melting
1747  // ============================================================
1748  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1749  // Warm-phase snow and graupel melting (t > t0c)
1750  if (t_arr(i,j,k) > t0c) {
1751  const Real supcol = t0c - t_arr(i,j,k);
1752  const Real n0sfac = amrex::max(
1753  amrex::min(std::exp(Real(alpha_wdm6) * supcol),
1754  Real(n0smax) / Real(n0s)),
1755  Real(1.0));
1756 
1757  const Real xlf = xlf0;
1758  const Real work2 = wdm6_venfac(p_arr(i,j,k), t_arr(i,j,k),
1759  den_arr(i,j,k), Real(den0));
1760 
1761  // --- Snow melting: psmlt ---
1762  if (qs_arr(i,j,k) > Real(0.0)) {
1763  const Real coeres_s = rslope2_arr(i,j,k,1) *
1764  std::sqrt(rslope_arr(i,j,k,1) * rslopeb_arr(i,j,k,1));
1765 
1766  Real psmlt = wdm6_xka(t_arr(i,j,k), den_arr(i,j,k)) / xlf *
1767  (t0c - t_arr(i,j,k)) * pi_wdm6_loc * Real(0.5) * n0sfac *
1768  (precs1_loc * rslope2_arr(i,j,k,1) +
1769  precs2_loc * work2 * coeres_s) / den_arr(i,j,k);
1770 
1771  psmlt = amrex::min(amrex::max(psmlt * dtcld, -qs_arr(i,j,k)),
1772  Real(0.0));
1773 
1774  if (qs_arr(i,j,k) > Real(qcrmin)) {
1775  const Real sfac = rslope_arr(i,j,k,1) * Real(n0s) * n0sfac /
1776  qs_arr(i,j,k);
1777  nr_arr(i,j,k) = amrex::max(nr_arr(i,j,k) - sfac * psmlt, Real(0.0));
1778  }
1779 
1780  qs_arr(i,j,k) += psmlt;
1781  qr_arr(i,j,k) -= psmlt;
1782  t_arr(i,j,k) += xlf / cpm_arr(i,j,k) * psmlt;
1783  }
1784 
1785  // --- Graupel melting: pgmlt ---
1786  if (qg_arr(i,j,k) > Real(0.0)) {
1787  const Real coeres_g = rslope2_arr(i,j,k,2) *
1788  std::sqrt(rslope_arr(i,j,k,2) * rslopeb_arr(i,j,k,2));
1789 
1790  Real pgmlt = wdm6_xka(t_arr(i,j,k), den_arr(i,j,k)) / xlf *
1791  (t0c - t_arr(i,j,k)) *
1792  (precg1_loc * rslope2_arr(i,j,k,2) +
1793  precg2_loc * work2 * coeres_g) / den_arr(i,j,k);
1794 
1795  pgmlt = amrex::min(amrex::max(pgmlt * dtcld, -qg_arr(i,j,k)),
1796  Real(0.0));
1797 
1798  if (qg_arr(i,j,k) > Real(qcrmin)) {
1799  const Real gfac = rslope_arr(i,j,k,2) * n0g_loc /
1800  qg_arr(i,j,k);
1801  nr_arr(i,j,k) = amrex::max(nr_arr(i,j,k) - gfac * pgmlt, Real(0.0));
1802  }
1803 
1804  qg_arr(i,j,k) += pgmlt;
1805  qr_arr(i,j,k) -= pgmlt;
1806  t_arr(i,j,k) += xlf / cpm_arr(i,j,k) * pgmlt;
1807  }
1808  }
1809  });
1810 
1811  // ============================================================
1812  // WDM6-CPP_POST_G7
1813  // ============================================================
1814 
1815  // ============================================================
1816  // Step 3i: G8 ice fall speed + ice sedimentation
1817  // VICE: Ice crystal terminal velocity + nislfv_rain_plmr
1818  // ============================================================
1819 
1820  // Compute ice crystal fall speed (work1c). Fortran:
1821  // xmi = den*qci(:,:,2)/xni
1822  // diameter = max(min(dicon*sqrt(xmi),dimax),1.e-25)
1823  // work1c = 1.49e4*exp(log(diameter)*(1.31))
1824  // dicon and dimax are the CLASS constants, already routed through
1825  // wdm6_literal. This block previously declared its own locals that
1826  // shadowed them, and both were wrong: dicon was 11.45e-9 against the
1827  // Fortran's 11.9, nine orders of magnitude small, which collapsed the
1828  // ice fall speed to ~5e-13 m/s so the native path effectively did not
1829  // sediment ice at all; and dimax was a true double, reintroducing at
1830  // this site exactly the literal-precision defect already closed in
1831  // G13e. Hoisted out of the lambda in the established _loc style so no
1832  // capture of `this` is needed on device.
1833  constexpr Real dicon_loc = dicon;
1834  constexpr Real dimax_loc = dimax;
1835  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1836  Real work1c = Real(0.0);
1837  if (qi_arr(i,j,k) > Real(0.0)) {
1838  const Real xni_safe = amrex::max(xni_arr(i,j,k), Real(1.0e-30));
1839  const Real xmi = den_arr(i,j,k) * qi_arr(i,j,k) / xni_safe;
1840  const Real diameter = amrex::max(amrex::min(dicon_loc * std::sqrt(xmi), dimax_loc),
1841  wdm6_literal(1.0e-25));
1842  work1c = wdm6_literal(1.49e4) * std::exp(std::log(diameter) * wdm6_literal(1.31));
1843  }
1844  work1c_arr(i,j,k) = work1c;
1845  });
1846 
1847  // Ice sedimentation via simplified PLM6 scheme
1848  ParallelFor(box2d, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1849  amrex::ignore_unused(k);
1850  const int km = khi - klo + 1;
1851  auto dz_col = [&](int kk) -> amrex::Real& {
1852  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::dz);
1853  };
1854  auto den_col = [&](int kk) -> amrex::Real& {
1855  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::den);
1856  };
1857  auto denfac_col = [&](int kk) -> amrex::Real& {
1858  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::denfac);
1859  };
1860  auto tk_col = [&](int kk) -> amrex::Real& {
1861  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::tk);
1862  };
1863  auto work_col = [&](int kk) -> amrex::Real& {
1864  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::work_col);
1865  };
1866  auto rq_col = [&](int kk) -> amrex::Real& {
1867  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::rq_col);
1868  };
1869  auto rq2_col = [&](int kk) -> amrex::Real& {
1870  return sed_cell_scratch_arr(i, j, klo + kk, WDM6SedCellScratch::rq2_col);
1871  };
1872 
1873  // Fill column arrays
1874  for (int kk = 0; kk < km; ++kk) {
1875  const int k3 = klo + kk;
1876  dz_col(kk) = delz_arr(i,j,k3);
1877  den_col(kk) = den_arr(i,j,k3);
1878  denfac_col(kk) = denfac_arr(i,j,k3);
1879  tk_col(kk) = t_arr(i,j,k3);
1880  work_col(kk) = work1c_arr(i,j,k3);
1881  rq_col(kk) = den_col(kk) * qi_arr(i,j,k3);
1882  rq2_col(kk) = den_col(kk) * qi_arr(i,j,k3);
1883  }
1884 
1885  // Face fluxes: the top-down sums before, minus those after
1886  sedimentation_add_column_sums(sed_arr, WDM6Sed::qi, i, j, klo, khi, Real(1.0),
1887  [&](int kk) { return den_arr(i,j,kk) * qi_arr(i,j,kk) * delz_arr(i,j,kk); });
1888 
1889  Real delqi_col = Real(0.0);
1890  Real delqi2_col = Real(0.0);
1891 
1892  // Ice sedimentation. ITER MUST BE 0 HERE. The Fortran calls
1893  // nislfv_rain_plmr(...,work1c,denqci,denqci,delqi,dtcld,1,0,0)
1894  // whose trailing arguments are dt, id, iter, rid -- so id=1 and
1895  // iter=0. This helper's signature has no id parameter and reads
1896  // (..., dt, iter, ...), so passing the Fortran's id of 1 in that
1897  // slot silently set iter=1 and ran the velocity-iteration block
1898  // that G8 is supposed to skip, recomputing the ICE fall speed
1899  // from the snow and graupel slope routines. Contrast G5c, which
1900  // genuinely passes iter=1 (Fortran :1122 ends dtcld,1,1).
1901  // This was verified against the Fortran bridge by tracing every
1902  // input with prints archived on a branch: qi, xni, den, xmi,
1903  // dicon, diameter and work1c are all bitwise equal at every k in
1904  // the 85..100 window, so the kernel invocation was the only
1905  // remaining candidate.
1907  km, &delqi_col, &delqi2_col, dtcld, 0,
1908  pidn0s_loc, pidn0g_loc, Real(qcrmin), Real(alpha_wdm6), Real(n0smax), Real(n0s), wdm6_slope_t0c,
1909  rslopesmax_loc, rslopesbmax_loc, rslopes2max_loc, rslopes3max_loc, Real(bvts), pvts_loc,
1910  rslopegmax_loc, rslopegbmax_loc, rslopeg2max_loc, rslopeg3max_loc, slope_bvtg_loc, pvtg_loc,
1911  sed_cell_scratch_arr, sed_node_scratch_arr, i, j, klo);
1912 
1913  // Update ice concentrations from sedimented state
1914  for (int kk = 0; kk < km; ++kk) {
1915  const int k3 = klo + kk;
1916  qi_arr(i,j,k3) = amrex::max(rq_col(kk) / den_col(kk), Real(0.0));
1917  }
1918  sedimentation_add_column_sums(sed_arr, WDM6Sed::qi, i, j, klo, khi, Real(-1.0),
1919  [&](int kk) { return den_arr(i,j,kk) * qi_arr(i,j,kk) * delz_arr(i,j,kk); });
1920 
1921  // Ice fallout at surface. Indexed at klo to match the G9 block
1922  // below, which reads fallc_arr(i,j,klo); this lambda discards
1923  // its own k (see ignore_unused above), so spelling the index
1924  // out keeps the two sites textually identical.
1925  fallc_arr(i,j,klo) = delqi_col / dz_col(0) / dtcld;
1926  delqi_arr(i,j,klo) = delqi_col;
1927  });
1928 
1929 
1930  // ============================================================
1931  // Step 3h: G9 Surface precipitation accumulation and sr update
1932  // ============================================================
1933 
1934  // Surface precipitation accumulation from sedimentation fallout. Only a
1935  // column standing on the domain bottom has a ground to accumulate it on.
1936  const bool reaches_ground = (klo == m_geom.Domain().smallEnd(2));
1937  ParallelFor(box2d, [=] AMREX_GPU_DEVICE (int i, int j, int) noexcept
1938  {
1939  if (!reaches_ground) { return; }
1940 
1941  const Real fall_r = fall_arr(i,j,klo,0); // rain fallout
1942  const Real fall_s = fall_arr(i,j,klo,1); // snow fallout
1943  const Real fall_g = fall_arr(i,j,klo,2); // graupel fallout
1944  const Real fall_c = fallc_arr(i,j,klo); // ice fallout
1945 
1946  const Real fallsum = fall_r + fall_s + fall_g + fall_c;
1947  const Real fallsum_qsi = fall_s + fall_c;
1948  const Real fallsum_qg = fall_g;
1949 
1950  const Real conv = delz_arr(i,j,klo) / Real(rhoh2o) * dtcld * Real(1000.0);
1951 
1952  // Each species alone, and the total, which also holds the cloud ice
1953  rain_arr(i,j,klo) += fall_r * conv;
1954  snow_arr(i,j,klo) += fall_s * conv;
1955  graupel_arr(i,j,klo) += fallsum_qg * conv;
1956  precip_arr(i,j,klo) += fallsum * conv;
1957 
1958  // The frozen share of what fell this step, as WRF's sr
1959  if (fallsum > Real(0.0)) {
1960  sr_arr(i,j,klo) = (fallsum_qsi + fallsum_qg)
1961  / (fallsum + wdm6_literal(1.0e-12));
1962  }
1963  });
1964 
1965 
1966  // ============================================================
1967  // Step 3j: G10a Cloud-Ice Melt to Cloud Water
1968  // Exact port of bounded Fortran block (lines 1189-1197)
1969  // ============================================================
1970 
1971  // ================================================================
1972  // G10a-G10d FUSED, matching the Fortran's single loop nest.
1973  //
1974  // ERF_module_mp_wdm6.F90:1420-1421 opens one do k / do i nest and
1975  // computes supcol (:1422) and xlf (:1423-1424) ONCE per cell; all
1976  // four phase blocks then reuse them while t is progressively
1977  // updated by latent heat (:1432 cools, :1459 warms, :1495 warms).
1978  // This path previously ran the four blocks as four separate
1979  // ParallelFor kernels, each recomputing supcol and xlf from the
1980  // already-updated t_arr. That made pgfrz consume a fresher supcol
1981  // than the Fortran does: measured 1.048787e-06 on supcolt at
1982  // (107,3,46), amplified to 4.908569e-06 in expterm by the pfrz2
1983  // factor and inherited by pfrzdtr.
1984  //
1985  // xlf is the more dangerous of the two because it is set by a
1986  // BRANCH on supcol. Melting cools and freezing warms, so t crossing
1987  // t0c mid-section is exactly what this code does, and a per-kernel
1988  // re-evaluation would flip the branch where the Fortran does not.
1989  // Note G10b did not even carry the branch, only xlf = xls - xl.
1990  //
1991  // The group-boundary tags stay at their group boundaries per
1992  // Rule 30; they are emitted per cell from inside the kernel now
1993  // rather than from a column sweep afterwards. For these purely
1994  // per-cell blocks that is the same state, and it is strictly closer
1995  // to the "immediate process-group boundary" the rule asks for.
1996  // ================================================================
1997  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
1998  const Real supcol = t0c - t_arr(i,j,k);
1999  Real xlf = xls - xl_arr(i,j,k);
2000  if (supcol < Real(0.0)) xlf = xlf0;
2001 
2002  // Cloud-ice melt to cloud water (T > t0c)
2003  if (supcol < Real(0.0) && qi_arr(i,j,k) > Real(0.0)) {
2004  const Real qim = qi_arr(i,j,k); // preserve old ice amount
2005 
2006  qc_arr(i,j,k) += qim; // qci(:,:,1) += qci(:,:,2)
2007  if (qim > Real(qmin)) {
2008  nc_arr(i,j,k) += xni_arr(i,j,k); // ncr(:,:,2) += xni
2009  }
2010  t_arr(i,j,k) -= xlf / cpm_arr(i,j,k) * qim; // latent heat release
2011  qi_arr(i,j,k) = Real(0.0); // zero out ice
2012  }
2013 
2014 
2015 
2016  // ============================================================
2017  // Step 3k: G10b Cloud-Water Homogeneous Freezing
2018  // Exact port of bounded Fortran block (lines 1215-1224)
2019  // ============================================================
2020 
2021 
2022  // Homogeneous freezing of cloud water when supcol > 40K (T < -40C)
2023  if (supcol > Real(40.0) && qc_arr(i,j,k) > Real(0.0)) {
2024  const Real qc_old = qc_arr(i,j,k);
2025 
2026  qi_arr(i,j,k) += qc_old;
2027 
2028  if (nc_arr(i,j,k) > Real(0.0)) {
2029  nc_arr(i,j,k) = Real(0.0);
2030  }
2031 
2032  t_arr(i,j,k) += xlf / cpm_arr(i,j,k) * qc_old;
2033  qc_arr(i,j,k) = Real(0.0);
2034  }
2035 
2036 
2037  // ============================================================
2038  // Step 3l: G10c Cloud-Water Heterogeneous Freezing
2039  // Exact port of bounded Fortran block (pihtf, lines 1241-1258)
2040  // ============================================================
2041 
2042  // Latent heat of FUSION, per the Fortran's per-k prologue:
2043  // xlf = xls-xl(i,k) ; if(supcol.lt.0.) xlf = xlf0
2044  // shared by G10a-G10d. Freezing releases xlf, not xl.
2045 
2046  // Heterogeneous freezing (Biggs, contact/immersion): 0 > T > -40C
2047  // Trigger: supcol > 0 (T < T0c) AND qc > qmin
2048  if (supcol > Real(0.0) && qc_arr(i,j,k) > Real(qmin)) {
2049  const Real supcolt = amrex::min(supcol, Real(70.0));
2050  const Real expterm = std::exp(pfrz2_loc * supcolt) - Real(1.0);
2051 
2052  // Use the stored rslopec3, as the Fortran does: in the
2053  // rslopecmax branch it is the precomputed rslopec3max
2054  // constant, which need not equal rslopecmax cubed.
2055  const Real rs3 = rslopec3_arr(i,j,k);
2056 
2057  // pfrzdtc = min(pi*pi*pfrz1*(exp(pfrz2*supcolt)-1.)*denr/den
2058  // *ncr(:,:,2)*rslopec3*rslopec3/18.*dtcld, qci(:,:,1))
2059  // rslopec3 appears TWICE. Using it once left the rate about
2060  // 1/rslopec3 too large -- roughly 8e12 for a typical cloud
2061  // droplet slope -- so pfrzdtc always saturated at its qc cap
2062  // and every cell below freezing lost all its cloud water to
2063  // ice in a single substep. Factor order follows the Fortran
2064  // left to right so the roundings agree.
2065  Real pfrzdtc = pi_wdm6_loc * pi_wdm6_loc * pfrz1_loc * expterm
2066  * denr / den_arr(i,j,k) * nc_arr(i,j,k) * rs3 * rs3
2067  / Real(18.0) * dtcld;
2068  pfrzdtc = amrex::min(pfrzdtc, qc_arr(i,j,k));
2069 
2070  // nfrzdtc = min(pi*pfrz1*(exp(pfrz2*supcolt)-1.)*ncr(:,:,2)
2071  // *rslopec3/6.*dtcld, ncr(:,:,2)) -- one factor here.
2072  Real nfrzdtc = pi_wdm6_loc * pfrz1_loc * expterm
2073  * nc_arr(i,j,k) * rs3
2074  / Real(6.0) * dtcld;
2075  nfrzdtc = amrex::min(nfrzdtc, nc_arr(i,j,k));
2076 
2077  // Apply number loss (only if nc > ncmin)
2078  if (nc_arr(i,j,k) > Real(ncmin)) {
2079  nc_arr(i,j,k) -= nfrzdtc;
2080  }
2081 
2082  // Apply mass and temperature updates
2083  qi_arr(i,j,k) += pfrzdtc;
2084  t_arr(i,j,k) += xlf / cpm_arr(i,j,k) * pfrzdtc;
2085  qc_arr(i,j,k) -= pfrzdtc;
2086  }
2087 
2088 
2089  // ============================================================
2090  // Step 3m: G10d Rain-to-Graupel Freezing
2091  // Exact port of bounded Fortran block (pgfrz, rain freezing)
2092  // ============================================================
2093 
2094  // Latent heat of fusion, as in G10a-G10c above.
2095 
2096  // Rain freezing to graupel: trigger when T < t0c and qr > 0
2097  if (supcol > Real(0.0) && qr_arr(i,j,k) > Real(0.0)) {
2098  const Real supcolt = amrex::min(supcol, Real(70.0));
2099  const Real expterm = std::exp(pfrz2_loc * supcolt) - Real(1.0);
2100 
2101  // Rain slope cubed (from G4/G6 computation)
2102  const Real rs3 = rslope3_arr(i,j,k,0);
2103 
2104  // pfrzdtr = min(140.*(pi*pi)*pfrz1*ncr(:,:,3)*denr/den
2105  // *(exp(pfrz2*supcolt)-1.)*rslope3*rslope3*dtcld, qrs(:,:,1))
2106  // Factor order follows the Fortran left to right.
2107  Real pfrzdtr = Real(140.0) * (pi_wdm6_loc * pi_wdm6_loc)
2108  * pfrz1_loc * nr_arr(i,j,k)
2109  * denr / den_arr(i,j,k)
2110  * expterm * rs3 * rs3 * dtcld;
2111  pfrzdtr = amrex::min(pfrzdtr, qr_arr(i,j,k));
2112 
2113 
2114  // Number freezing rate (conditional on nr > nrmin)
2115  if (nr_arr(i,j,k) > Real(nrmin)) {
2116  Real nfrzdtr = Real(4.0) * pi_wdm6_loc * pfrz1_loc
2117  * nr_arr(i,j,k) * expterm * rs3 * dtcld;
2118  nfrzdtr = amrex::min(nfrzdtr, nr_arr(i,j,k));
2119  nr_arr(i,j,k) -= nfrzdtr;
2120  }
2121 
2122  // Apply mass and temperature updates
2123  qg_arr(i,j,k) += pfrzdtr;
2124  t_arr(i,j,k) += xlf / cpm_arr(i,j,k) * pfrzdtr;
2125  qr_arr(i,j,k) -= pfrzdtr;
2126  }
2127  });
2128 
2129 
2130  // ============================================================
2131  // Step 3k: G10e Phase cleanup — clamp number concentrations non-negative
2132  // ============================================================
2133 
2134  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2135  nc_arr(i,j,k) = amrex::max(nc_arr(i,j,k), Real(0.0));
2136  nr_arr(i,j,k) = amrex::max(nr_arr(i,j,k), Real(0.0));
2137  });
2138 
2139 
2140  // ============================================================
2141  // G11: SLOPE3 — Third slope_wdm6 call + avedia/rslopec recompute
2142  // ============================================================
2143 
2144 
2145  // G11(a): Repack fields for slope recomputation (Fortran qrs_tmp/ncr_tmp)
2146  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2147  qrs_tmp_arr(i,j,k,0) = qr_arr(i,j,k); // qrs(:,:,1)
2148  qrs_tmp_arr(i,j,k,1) = qs_arr(i,j,k); // qrs(:,:,2)
2149  qrs_tmp_arr(i,j,k,2) = qg_arr(i,j,k); // qrs(:,:,3)
2150  ncr_tmp_arr(i,j,k) = nr_arr(i,j,k); // ncr(:,:,3)
2151  });
2152 
2153  // G11(b): slope_wdm6-equivalent recompute for rain/snow/graupel
2154  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2155  Real rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3, rain_vt, rain_vtn;
2156  Real snow_rslope, snow_rslopeb, snow_rslope2, snow_rslope3, snow_vt, snow_n0sfac;
2157  Real graup_rslope, graup_rslopeb, graup_rslope2, graup_rslope3, graup_vt;
2158 
2159  // Compute slope parameters using qrs_tmp/ncr_tmp values
2160  wdm6_slope_rain_cell(qrs_tmp_arr(i,j,k,0), ncr_tmp_arr(i,j,k), den_arr(i,j,k), denfac_arr(i,j,k),
2161  Real(qcrmin), Real(nrmin),
2162  rslopermax_loc, rsloperbmax_loc, rsloper2max_loc, rsloper3max_loc,
2163  Real(bvtr), pvtr_loc, pvtrn_loc, pidnr_loc,
2164  rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3,
2165  rain_vt, rain_vtn);
2166  wdm6_slope_snow_cell(qrs_tmp_arr(i,j,k,1), den_arr(i,j,k), denfac_arr(i,j,k), t_arr(i,j,k),
2167  pidn0s_loc, Real(alpha_wdm6), Real(n0smax), Real(n0s),
2169  rslopesmax_loc, rslopesbmax_loc, rslopes2max_loc, rslopes3max_loc,
2170  Real(bvts), pvts_loc,
2171  snow_rslope, snow_rslopeb, snow_rslope2, snow_rslope3, snow_vt,
2172  snow_n0sfac);
2173  wdm6_slope_graup_cell(qrs_tmp_arr(i,j,k,2), den_arr(i,j,k), denfac_arr(i,j,k),
2174  pidn0g_loc, Real(qcrmin),
2175  rslopegmax_loc, rslopegbmax_loc, rslopeg2max_loc, rslopeg3max_loc,
2176  slope_bvtg_loc, pvtg_loc,
2177  graup_rslope, graup_rslopeb, graup_rslope2, graup_rslope3, graup_vt);
2178 
2179  // Store results in output slope arrays
2180  rslope_arr(i,j,k,0) = rain_rslope;
2181  rslope_arr(i,j,k,1) = snow_rslope;
2182  rslope_arr(i,j,k,2) = graup_rslope;
2183  rslopeb_arr(i,j,k,0) = rain_rslopeb;
2184  rslopeb_arr(i,j,k,1) = snow_rslopeb;
2185  rslopeb_arr(i,j,k,2) = graup_rslopeb;
2186  rslope2_arr(i,j,k,0) = rain_rslope2;
2187  rslope2_arr(i,j,k,1) = snow_rslope2;
2188  rslope2_arr(i,j,k,2) = graup_rslope2;
2189  rslope3_arr(i,j,k,0) = rain_rslope3;
2190  rslope3_arr(i,j,k,1) = snow_rslope3;
2191  rslope3_arr(i,j,k,2) = graup_rslope3;
2192  work1_arr(i,j,k,0) = rain_vt;
2193  work1_arr(i,j,k,1) = snow_vt;
2194  work1_arr(i,j,k,2) = graup_vt;
2195  workn_arr(i,j,k) = rain_vtn;
2196  });
2197 
2198  // G11(c): avedia + rslopec/2/3 recompute (lamdac fallback branch)
2199  const Real cbrt24 = wdm6_default_real_pow(24.0, 0.3333333);
2200  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2201  // avedia component from rain slope: avedia(:,:,2) = rslope(:,:,1) * (24.)^(1/3)
2202  avedia_arr(i,j,k,1) = rslope_arr(i,j,k,0) * cbrt24;
2203 
2204  // Cloud water slope parameters: rslopec = 1/lamdac(qci(:,:,1), den, ncr(:,:,2))
2205  // Fortran gate: if (qci(:,:,1) <= qmin or ncr(:,:,2) <= ncmin) use maxima, else use lamdac
2206  const Real qci_for_lamdac = qc_arr(i,j,k);
2207  const Real nc_for_lamdac = nc_arr(i,j,k);
2208 
2209  if (qci_for_lamdac <= Real(qmin) || nc_for_lamdac <= Real(ncmin)) {
2210  rslopec_arr(i,j,k) = rslopecmax_loc;
2211  rslopec2_arr(i,j,k) = rslopec2max_loc;
2212  rslopec3_arr(i,j,k) = rslopec3max_loc;
2213  } else {
2214  // Same expression as G3; share the one exact port. The
2215  // previous wdm6_lamdac() here differed from the Fortran on
2216  // three counts: it cancelled den out of the argument, it
2217  // used std::pow with a true 1/3 rather than exp/log with the
2218  // unsuffixed .33333333, and it carried a qc/nc guard of its
2219  // own that fired inside this block's own gate.
2220  const Real rslc = wdm6_rslopec_exact(qci_for_lamdac, den_arr(i,j,k),
2221  nc_for_lamdac, pidnc_loc);
2222  rslopec_arr(i,j,k) = rslc;
2223  rslopec2_arr(i,j,k) = rslc * rslc;
2224  rslopec3_arr(i,j,k) = rslopec2_arr(i,j,k) * rslc;
2225  }
2226 
2227  // avedia component from cloud slope: avedia(:,:,1) = rslopec(:,:)
2228  avedia_arr(i,j,k,0) = rslopec_arr(i,j,k);
2229  });
2230 
2231  // G11(d): work arrays recompute via diffac/venfac
2232  // work1(:,:,1) = diffac(xl, p, t, den, qs(:,:,1), rv)
2233  // work1(:,:,2) = diffac(xls, p, t, den, qs(:,:,2), rv)
2234  // work2(:,:) = venfac(p, t, den, den0) [stored for G13a warm-rain rates]
2235  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2236  // Recompute work1 diffusion coefficients using current state
2237  if (i == diag_i && j == diag_j && k == diag_k) {
2238  }
2239  work1_arr(i,j,k,0) = wdm6_diffac(xl_arr(i,j,k), p_arr(i,j,k), t_arr(i,j,k),
2240  den_arr(i,j,k), qsatw_arr(i,j,k), Real(rv)); // qs(:,:,1)
2241  if (i == diag_i && j == diag_j && k == diag_k) {
2242  }
2243  if (i == diag_i && j == diag_j && k == diag_k) {
2244  }
2245  work1_arr(i,j,k,1) = wdm6_diffac(Real(xls), p_arr(i,j,k), t_arr(i,j,k),
2246  den_arr(i,j,k), qsati_arr(i,j,k), Real(rv)); // qs(:,:,2)
2247  if (i == diag_i && j == diag_j && k == diag_k) {
2248  }
2249  // Compute work2 ventilation factor for diffusion (used in G13a warm-rain rates)
2250  work2_arr(i,j,k) = wdm6_venfac(p_arr(i,j,k), t_arr(i,j,k), den_arr(i,j,k), Real(den0));
2251  });
2252 
2253 
2254 
2255 
2256  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2257  const Real supsat = amrex::max(qv_arr(i,j,k), Real(qmin)) - qsatw_arr(i,j,k);
2258  const Real satdt = supsat / dtcld;
2259  const Real lencon = wdm6_literal(2.7e-2) * den_arr(i,j,k) * qc_arr(i,j,k)
2260  * (wdm6_literal(1.0e20/16.0) * rslopec2_arr(i,j,k) * rslopec2_arr(i,j,k)
2261  - wdm6_literal(0.4));
2262  const Real lenconcr = amrex::max(wdm6_literal(1.2) * lencon, Real(qcrmin));
2263 
2264  if (qc_arr(i,j,k) > qcr_arr(i,j,k) && nc_arr(i,j,k) > Real(ncmin)) {
2265  // Fortran :1889
2266  // praut(i,k) = qck1*qci(i,k,1)**(7./3.)*ncr(i,k,2)**(-1./3.)
2267  // Both exponents are unsuffixed, so they are float32 values
2268  // widened, not true thirds: 7./3. is 2.3333332538604736
2269  // against 2.3333333333333335, and 1./3. is 0.3333333432674408
2270  // against 0.33333333333333331. Exponents amplify: the error
2271  // enters as ln(base)*delta, and with qc about 1.6e-02 and nc
2272  // about 1.8e+08 those logs are -4.2 and +19.0, which is why a
2273  // 3e-08 exponent difference produced 1.86e-07 on praut.
2274  praut_arr(i,j,k) = qck1_loc * std::pow(qc_arr(i,j,k), wdm6_literal(7.0/3.0))
2275  * std::pow(nc_arr(i,j,k), wdm6_literal(-1.0/3.0));
2276  praut_arr(i,j,k) = amrex::min(praut_arr(i,j,k), qc_arr(i,j,k) / dtcld);
2277 
2278  nrauto_arr(i,j,k) = Real(3.5e9) * den_arr(i,j,k) * praut_arr(i,j,k);
2279  if (qr_arr(i,j,k) > lenconcr) {
2280  nrauto_arr(i,j,k) = nr_arr(i,j,k) / qr_arr(i,j,k) * praut_arr(i,j,k);
2281  }
2282  nrauto_arr(i,j,k) = amrex::min(nrauto_arr(i,j,k), nc_arr(i,j,k) / dtcld);
2283  }
2284 
2285  if (qr_arr(i,j,k) >= lenconcr) {
2286  if (avedia_arr(i,j,k,1) >= Real(di100)) {
2287  nraccr_arr(i,j,k) = amrex::min(
2288  Real(ncrk1) * nc_arr(i,j,k) * nr_arr(i,j,k)
2289  * (rslopec3_arr(i,j,k) + Real(24.0) * rslope3_arr(i,j,k,0)),
2290  nc_arr(i,j,k) / dtcld);
2291  pracw_arr(i,j,k) = amrex::min(
2292  pi_wdm6_loc / Real(6.0) * (Real(denr) / den_arr(i,j,k))
2293  * Real(ncrk1) * nc_arr(i,j,k) * nr_arr(i,j,k)
2294  * rslopec3_arr(i,j,k)
2295  * (Real(2.0) * rslopec3_arr(i,j,k) + Real(24.0) * rslope3_arr(i,j,k,0)),
2296  qc_arr(i,j,k) / dtcld);
2297  } else {
2298  nraccr_arr(i,j,k) = amrex::min(
2299  Real(ncrk2) * nc_arr(i,j,k) * nr_arr(i,j,k)
2300  * (Real(2.0) * rslopec3_arr(i,j,k) * rslopec3_arr(i,j,k)
2301  + Real(5040.0) * rslope3_arr(i,j,k,0) * rslope3_arr(i,j,k,0)),
2302  nc_arr(i,j,k) / dtcld);
2303  pracw_arr(i,j,k) = amrex::min(
2304  pi_wdm6_loc / Real(6.0) * (Real(denr) / den_arr(i,j,k))
2305  * Real(ncrk2) * nc_arr(i,j,k) * nr_arr(i,j,k)
2306  * rslopec3_arr(i,j,k)
2307  * (Real(6.0) * rslopec3_arr(i,j,k) * rslopec3_arr(i,j,k)
2308  + Real(5040.0) * rslope3_arr(i,j,k,0) * rslope3_arr(i,j,k,0)),
2309  qc_arr(i,j,k) / dtcld);
2310  }
2311  }
2312 
2313  if (avedia_arr(i,j,k,0) >= Real(di100)) {
2314  nccol_arr(i,j,k) = Real(ncrk1) * nc_arr(i,j,k) * nc_arr(i,j,k) * rslopec3_arr(i,j,k);
2315  } else {
2316  nccol_arr(i,j,k) = Real(2.0) * Real(ncrk2) * nc_arr(i,j,k) * nc_arr(i,j,k)
2317  * rslopec3_arr(i,j,k) * rslopec3_arr(i,j,k);
2318  }
2319 
2320  if (qr_arr(i,j,k) >= lenconcr) {
2321  if (avedia_arr(i,j,k,1) < Real(di100)) {
2322  nrcol_arr(i,j,k) = Real(5040.0) * Real(ncrk2) * nr_arr(i,j,k) * nr_arr(i,j,k)
2323  * rslope3_arr(i,j,k,0) * rslope3_arr(i,j,k,0);
2324  } else if (avedia_arr(i,j,k,1) < Real(di600)) {
2325  nrcol_arr(i,j,k) = Real(24.0) * Real(ncrk1) * nr_arr(i,j,k) * nr_arr(i,j,k)
2326  * rslope3_arr(i,j,k,0);
2327  } else if (avedia_arr(i,j,k,1) < Real(di2000)) {
2328  const Real coecol = -Real(2.5e3) * (avedia_arr(i,j,k,1) - Real(di600));
2329  nrcol_arr(i,j,k) = Real(24.0) * std::exp(coecol) * Real(ncrk1)
2330  * nr_arr(i,j,k) * nr_arr(i,j,k) * rslope3_arr(i,j,k,0);
2331  } else {
2332  nrcol_arr(i,j,k) = Real(0.0);
2333  }
2334  }
2335 
2336  if (qr_arr(i,j,k) > Real(0.0)) {
2337  const Real coeres = rslope_arr(i,j,k,0)
2338  * std::sqrt(rslope_arr(i,j,k,0) * rslopeb_arr(i,j,k,0));
2339  prevp_arr(i,j,k) = (rhw_arr(i,j,k) - Real(1.0)) * nr_arr(i,j,k)
2340  * (precr1_loc * rslope_arr(i,j,k,0) + precr2_loc * work2_arr(i,j,k) * coeres)
2341  / work1_arr(i,j,k,0);
2342  if (prevp_arr(i,j,k) < Real(0.0)) {
2343  prevp_arr(i,j,k) = amrex::max(prevp_arr(i,j,k), -qr_arr(i,j,k) / dtcld);
2344  prevp_arr(i,j,k) = amrex::max(prevp_arr(i,j,k), satdt / Real(2.0));
2345 
2346  if (prevp_arr(i,j,k) == -qr_arr(i,j,k) / dtcld) {
2347  nn_arr(i,j,k) = nn_arr(i,j,k) + nr_arr(i,j,k);
2348  nr_arr(i,j,k) = Real(0.0);
2349  }
2350  } else if (prevp_arr(i,j,k) == Real(0.0)) {
2351  // A zero kinetic rate must not become evaporation
2352  // through a negative saturation-rate limiter.
2353  prevp_arr(i,j,k) = Real(0.0);
2354  } else {
2355  prevp_arr(i,j,k) = amrex::min(prevp_arr(i,j,k), satdt / Real(2.0));
2356  }
2357  }
2358  });
2359 
2360 
2361 
2362  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2363  const Real supcol = Real(t0c) - t_arr(i,j,k);
2364  const Real n0sfac = amrex::max(
2365  amrex::min(std::exp(Real(alpha_wdm6) * supcol),
2366  Real(n0smax) / Real(n0s)),
2367  Real(1.0));
2368  const Real supsat = amrex::max(qv_arr(i,j,k), Real(qmin)) - qsati_arr(i,j,k);
2369  amrex::ignore_unused(supsat);
2370  const Real satdt = supsat / dtcld;
2371  amrex::ignore_unused(satdt);
2372 
2373  const Real qi_val = qi_arr(i,j,k);
2374  if (!(supcol > Real(0.0) && qi_val > Real(qmin))) {
2375  return;
2376  }
2377 
2378  Real temp = den_arr(i,j,k) * amrex::max(qi_val, Real(qmin));
2379  temp = std::sqrt(std::sqrt(temp * temp * temp));
2380  xni_arr(i,j,k) = amrex::min(amrex::max(Real(5.38e7) * temp, Real(1.e3)), Real(1.e6));
2381 
2382  // Fortran :2021 eacrs = exp(0.07*(-supcol)); 0.07 is unsuffixed
2383  // so it carries the float assumption. Verified by tracing psaci's
2384  // inputs: eacrs diverged 1.03e-08 to 1.14e-08 relative across
2385  // k=89..95, matching delta(0.07)*(-supcol).
2386  const Real eacrs = std::exp(wdm6_literal(0.07) * (-supcol));
2387  const Real xni_safe = amrex::max(xni_arr(i,j,k), Real(1.0e-30));
2388  const Real xmi = den_arr(i,j,k) * qi_val / xni_safe;
2389  const Real diameter = amrex::min(Real(dicon) * std::sqrt(xmi), Real(dimax));
2390  // Fortran :2025 vt2i = 1.49e4*diameter**1.31. 1.49e4 is exactly
2391  // representable in float32 so it needs no routing, but the 1.31
2392  // EXPONENT does, and exponents amplify: the error enters as
2393  // ln(diameter)*delta, and with diameter at the dimax cap of
2394  // 5e-4 that is ln(5e-4) = -7.60 times -5.722e-08, i.e. 4.349e-07.
2395  // Measured: exactly 4.349270e-07 on vt2i across k=91..95.
2396  // It then amplifies again through the |vt2ave - vt2i|
2397  // cancellation in psaci: at k=89 vt2diff is 0.139 against vt2i
2398  // 0.681, a 4.90x factor giving the observed 2.14e-06.
2399  const Real vt2i = Real(1.49e4) * std::pow(diameter, wdm6_literal(1.31));
2400  const Real vt2r = pvtr_loc * rslopeb_arr(i,j,k,0) * denfac_arr(i,j,k);
2401  const Real vt2s = pvts_loc * rslopeb_arr(i,j,k,1) * denfac_arr(i,j,k);
2402  const Real vt2g = pvtg_loc * rslopeb_arr(i,j,k,2) * denfac_arr(i,j,k);
2403  // The 1.e-15 qsum floor is unsuffixed in the Fortran (:1110, :2072,
2404  // :2223, :3979), so it is float32(1e-15) = 1.0000000036274937e-15,
2405  // which is LARGER than the exact double by 3.63e-09 relative.
2406  //
2407  // It was previously judged inert because the floor and the gate use
2408  // the same literal, so a floored qsum can never pass `> literal`.
2409  // That reasoning holds WITHIN a leg but misses the cross-leg case:
2410  // the THRESHOLD itself differed between legs, so a cell with
2411  // qs+qg in (1e-15, 1.0000000036274937e-15) took the branch on the
2412  // port and skipped it on the oracle. A narrow window, but a branch
2413  // divergence rather than a rounding difference, so it is routed
2414  // rather than argued about.
2415  const Real qsum = amrex::max(qs_arr(i,j,k) + qg_arr(i,j,k), wdm6_literal(1.0e-15));
2416  const Real vt2ave = (qsum > wdm6_literal(1.0e-15))
2417  ? (vt2s * qs_arr(i,j,k) + vt2g * qg_arr(i,j,k)) / qsum
2418  : Real(0.0);
2419 
2420  if (qr_arr(i,j,k) > Real(qcrmin)) {
2421  const Real acrfac = Real(6.0) * rslope2_arr(i,j,k,0)
2422  + Real(4.0) * diameter * rslope_arr(i,j,k,0)
2423  + diameter * diameter;
2424  praci_arr(i,j,k) = pi_wdm6_loc * qi_val * nr_arr(i,j,k)
2425  * std::abs(vt2r - vt2i) * acrfac / Real(4.0);
2426  praci_arr(i,j,k) *= std::pow(
2427  amrex::min(amrex::max(Real(0.0), qr_arr(i,j,k) / qi_val), Real(1.0)),
2428  Real(2.0));
2429  praci_arr(i,j,k) = amrex::min(praci_arr(i,j,k), qi_val / dtcld);
2430 
2431  piacr_arr(i,j,k) = pi_wdm6_loc * pi_wdm6_loc * Real(WDM6::avtr)
2432  * nr_arr(i,j,k) * Real(denr) * xni_arr(i,j,k) * denfac_arr(i,j,k)
2433  * g7pbr_loc * rslope3_arr(i,j,k,0) * rslope2_arr(i,j,k,0)
2434  * rslopeb_arr(i,j,k,0) / (Real(24.0) * den_arr(i,j,k));
2435  piacr_arr(i,j,k) *= std::pow(
2436  amrex::min(amrex::max(Real(0.0), qi_val / qr_arr(i,j,k)), Real(1.0)),
2437  Real(2.0));
2438  piacr_arr(i,j,k) = amrex::min(piacr_arr(i,j,k), qr_arr(i,j,k) / dtcld);
2439  }
2440 
2441  if (nr_arr(i,j,k) > Real(nrmin)) {
2442  niacr_arr(i,j,k) = pi_wdm6_loc * Real(WDM6::avtr) * nr_arr(i,j,k)
2443  * xni_arr(i,j,k) * denfac_arr(i,j,k) * g4pbr_loc
2444  * rslope2_arr(i,j,k,0) * rslopeb_arr(i,j,k,0) / Real(4.0);
2445  niacr_arr(i,j,k) *= std::pow(
2446  amrex::min(amrex::max(Real(0.0), qi_val / qr_arr(i,j,k)), Real(1.0)),
2447  Real(2.0));
2448  niacr_arr(i,j,k) = amrex::min(niacr_arr(i,j,k), nr_arr(i,j,k) / dtcld);
2449  }
2450 
2451  if (qs_arr(i,j,k) > Real(qcrmin)) {
2452  const Real acrfac = Real(2.0) * rslope3_arr(i,j,k,1)
2453  + Real(2.0) * diameter * rslope2_arr(i,j,k,1)
2454  + diameter * diameter * rslope_arr(i,j,k,1);
2455  psaci_arr(i,j,k) = pi_wdm6_loc * qi_val * eacrs * Real(n0s) * n0sfac
2456  * std::abs(vt2ave - vt2i) * acrfac / Real(4.0);
2457  psaci_arr(i,j,k) = amrex::min(psaci_arr(i,j,k), qi_val / dtcld);
2458 
2459  }
2460 
2461  if (qg_arr(i,j,k) > Real(qcrmin)) {
2462  // Fortran :2114, the same unsuffixed 0.07 as eacrs above.
2463  // pgaci reads bitwise-equal in the current column only
2464  // because the branch is inactive there; routed for the same
2465  // reason, not on separate evidence.
2466  const Real egi = std::exp(wdm6_literal(0.07) * (-supcol));
2467  const Real acrfac = Real(2.0) * rslope3_arr(i,j,k,2)
2468  + Real(2.0) * diameter * rslope2_arr(i,j,k,2)
2469  + diameter * diameter * rslope_arr(i,j,k,2);
2470  pgaci_arr(i,j,k) = pi_wdm6_loc * egi * qi_val * n0g_loc
2471  * std::abs(vt2ave - vt2i) * acrfac / Real(4.0);
2472  pgaci_arr(i,j,k) = amrex::min(pgaci_arr(i,j,k), qi_val / dtcld);
2473  }
2474  });
2475 
2476 
2477 
2478  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2479  const Real supcol = Real(t0c) - t_arr(i,j,k);
2480  const Real n0sfac = amrex::max(
2481  amrex::min(std::exp(Real(alpha_wdm6) * supcol),
2482  Real(n0smax) / Real(n0s)),
2483  Real(1.0));
2484  const Real qs_val = qs_arr(i,j,k);
2485  const Real qg_val = qg_arr(i,j,k);
2486  const Real qc_val = qc_arr(i,j,k);
2487  const Real nc_val = nc_arr(i,j,k);
2488 
2489  // The Fortran (:2143, :2152) writes these ratios UNGUARDED:
2490  // min(max(0.0, qrs(i,k,2)/qci(i,k,1)), 1.)
2491  // so when qc == 0 and qs > 0 the division yields IEEE +Inf,
2492  // max(0,Inf) is Inf, and the clamp returns 1.0. Returning 0.0
2493  // for that case instead -- as a defensive divide-by-zero guard
2494  // naturally does -- lands on the OPPOSITE end of the clamp and
2495  // silently changes the physics.
2496  //
2497  // It hides in psacw, which is gated on qc > qmin and so never
2498  // sees qc == 0, but nsacw is gated on nc > ncmin, which passes
2499  // with qc == 0, and there the ratio is load-bearing. Measured
2500  // at (199,3,88) from a bitwise-identical PRE_G13C with qc = 0,
2501  // qs = 1.935e-02 and nc = 1.048e+06: the bridge produced
2502  // nsacw = 9.6929949510183156e+04 and the native leg exactly 0.
2503  // That single term is the entire step-6 nn discontinuity.
2504  //
2505  // The division is still avoided rather than allowed to produce
2506  // Inf, so builds with FP-exception trapping stay clean. The
2507  // qc == 0 and qs == 0 case cannot be reached by any consumer --
2508  // every use is gated on qs > qcrmin, qg > qcrmin or qc > qmin --
2509  // and 0.0 is returned there only for definiteness. The divisor
2510  // is never zero either: an optimised build may divide before it
2511  // tests qc, and with qs = qc = 0 the 0/0 trips
2512  // amrex.fpe_trap_invalid although the result is not used. For
2513  // qc >= the smallest normal number the divisor is qc itself.
2514  constexpr Real tiny_qc = std::numeric_limits<Real>::min();
2515  const Real qc_div = amrex::max(qc_val, tiny_qc);
2516  const Real ratio_s = (qc_val > Real(0.0))
2517  ? amrex::min(amrex::max(Real(0.0), qs_val / qc_div), Real(1.0))
2518  : (qs_val > Real(0.0) ? Real(1.0) : Real(0.0));
2519  // Same treatment as ratio_s above, and for the same reason. This
2520  // was MISSED when ratio_s was fixed: that edit replaced only the
2521  // ratio_s else-branch while its comment claimed both, so ngacw
2522  // kept returning 0 where the Fortran returns 1.0. Surfaced at
2523  // step 8 on ngacw, at relative error exactly 1.0: bridge
2524  // 8.85033631487811001e-02 against native 0, which was the whole
2525  // remaining nn residual at 10 steps.
2526  const Real ratio_g = (qc_val > Real(0.0))
2527  ? amrex::min(amrex::max(Real(0.0), qg_val / qc_div), Real(1.0))
2528  : (qg_val > Real(0.0) ? Real(1.0) : Real(0.0));
2529 
2530  if (qs_val > Real(qcrmin) && qc_val > Real(qmin)) {
2531  psacw_arr(i,j,k) = amrex::min(
2532  pacrc_loc * n0sfac * rslope3_arr(i,j,k,1) * rslopeb_arr(i,j,k,1)
2533  * ratio_s * ratio_s * qc_val * denfac_arr(i,j,k),
2534  qc_val / dtcld);
2535  }
2536  if (qs_val > Real(qcrmin) && nc_val > Real(ncmin)) {
2537  nsacw_arr(i,j,k) = amrex::min(
2538  pacrc_loc * n0sfac * rslope3_arr(i,j,k,1) * rslopeb_arr(i,j,k,1)
2539  * ratio_s * ratio_s * nc_val * denfac_arr(i,j,k),
2540  nc_val / dtcld);
2541  }
2542  if (qg_val > Real(qcrmin) && qc_val > Real(qmin)) {
2543  pgacw_arr(i,j,k) = amrex::min(
2544  pacrg_loc * rslope3_arr(i,j,k,2) * rslopeb_arr(i,j,k,2)
2545  * qc_val * ratio_g * ratio_g * denfac_arr(i,j,k),
2546  qc_val / dtcld);
2547  }
2548  if (qg_val > Real(qcrmin) && nc_val > Real(ncmin)) {
2549  ngacw_arr(i,j,k) = amrex::min(
2550  pacrg_loc * rslope3_arr(i,j,k,2) * rslopeb_arr(i,j,k,2)
2551  * nc_val * ratio_g * ratio_g * denfac_arr(i,j,k),
2552  nc_val / dtcld);
2553  }
2554 
2555  const Real qsum = amrex::max(qs_val + qg_val, wdm6_literal(1.0e-15));
2556  if (qsum > wdm6_literal(1.0e-15)) {
2557  paacw_arr(i,j,k) = (qs_val * psacw_arr(i,j,k) + qg_val * pgacw_arr(i,j,k)) / qsum;
2558  naacw_arr(i,j,k) = (qs_val * nsacw_arr(i,j,k) + qg_val * ngacw_arr(i,j,k)) / qsum;
2559  }
2560  });
2561 
2562 
2563 
2564  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2565  const Real supcol = Real(t0c) - t_arr(i,j,k);
2566  const Real n0sfac = amrex::max(
2567  amrex::min(std::exp(Real(alpha_wdm6) * supcol),
2568  Real(n0smax) / Real(n0s)),
2569  Real(1.0));
2570  const Real qr_val = qr_arr(i,j,k);
2571  const Real qs_val = qs_arr(i,j,k);
2572  const Real qg_val = qg_arr(i,j,k);
2573  const Real nr_val = nr_arr(i,j,k);
2574  const Real vt2r = pvtr_loc * rslopeb_arr(i,j,k,0) * denfac_arr(i,j,k);
2575  const Real vt2s = pvts_loc * rslopeb_arr(i,j,k,1) * denfac_arr(i,j,k);
2576  const Real vt2g = pvtg_loc * rslopeb_arr(i,j,k,2) * denfac_arr(i,j,k);
2577  const Real qsum = qs_val + qg_val;
2578  const Real vt2ave = (qsum > Real(0.0))
2579  ? (vt2s * qs_val + vt2g * qg_val) / qsum
2580  : Real(0.0);
2581 
2582  if (qs_val > Real(qcrmin) && qr_val > Real(qcrmin)) {
2583  if (supcol > Real(0.0)) {
2584  const Real acrfac =
2585  Real(5.0) * rslope3_arr(i,j,k,1) * rslope3_arr(i,j,k,1)
2586  + Real(4.0) * rslope3_arr(i,j,k,1) * rslope2_arr(i,j,k,1)
2587  * rslope_arr(i,j,k,0)
2588  + Real(1.5) * rslope2_arr(i,j,k,1) * rslope2_arr(i,j,k,1)
2589  * rslope2_arr(i,j,k,0);
2590  pracs_arr(i,j,k) = pi_wdm6_loc * pi_wdm6_loc * nr_val * Real(n0s)
2591  * n0sfac * std::abs(vt2r - vt2ave)
2592  * (Real(dens) / den_arr(i,j,k)) * acrfac;
2593  const Real ratio = amrex::min(
2594  amrex::max(Real(0.0), qr_val / qs_val), Real(1.0));
2595  pracs_arr(i,j,k) *= ratio * ratio;
2596  pracs_arr(i,j,k) = amrex::min(pracs_arr(i,j,k), qs_val / dtcld);
2597  }
2598 
2599  const Real acrfac =
2600  Real(30.0) * rslope3_arr(i,j,k,0) * rslope2_arr(i,j,k,0)
2601  * rslope_arr(i,j,k,1)
2602  + Real(10.0) * rslope2_arr(i,j,k,0) * rslope2_arr(i,j,k,0)
2603  * rslope2_arr(i,j,k,1)
2604  + Real(2.0) * rslope3_arr(i,j,k,0) * rslope3_arr(i,j,k,1);
2605  psacr_arr(i,j,k) = pi_wdm6_loc * pi_wdm6_loc * nr_val * Real(n0s)
2606  * n0sfac * std::abs(vt2ave - vt2r)
2607  * (Real(denr) / den_arr(i,j,k)) * acrfac;
2608  const Real ratio = amrex::min(
2609  amrex::max(Real(0.0), qs_val / qr_val), Real(1.0));
2610  psacr_arr(i,j,k) *= ratio * ratio;
2611  psacr_arr(i,j,k) = amrex::min(psacr_arr(i,j,k), qr_val / dtcld);
2612  }
2613 
2614  if (qs_val > Real(qcrmin) && nr_val > Real(nrmin)) {
2615  const Real acrfac =
2616  Real(1.5) * rslope2_arr(i,j,k,0) * rslope_arr(i,j,k,1)
2617  + rslope_arr(i,j,k,0) * rslope2_arr(i,j,k,1)
2618  + Real(0.5) * rslope3_arr(i,j,k,1);
2619  nsacr_arr(i,j,k) = pi_wdm6_loc * nr_val * Real(n0s) * n0sfac
2620  * std::abs(vt2ave - vt2r) * acrfac;
2621  const Real ratio = amrex::min(
2622  amrex::max(Real(0.0), qs_val / qr_val), Real(1.0));
2623  nsacr_arr(i,j,k) *= ratio * ratio;
2624  nsacr_arr(i,j,k) = amrex::min(nsacr_arr(i,j,k), nr_val / dtcld);
2625  }
2626 
2627  if (qg_val > Real(qcrmin) && qr_val > Real(qcrmin)) {
2628  const Real acrfac =
2629  Real(30.0) * rslope3_arr(i,j,k,0) * rslope2_arr(i,j,k,0)
2630  * rslope_arr(i,j,k,2)
2631  + Real(10.0) * rslope2_arr(i,j,k,0) * rslope2_arr(i,j,k,0)
2632  * rslope2_arr(i,j,k,2)
2633  + Real(2.0) * rslope3_arr(i,j,k,0) * rslope3_arr(i,j,k,2);
2634  pgacr_arr(i,j,k) = pi_wdm6_loc * pi_wdm6_loc * nr_val * n0g_loc
2635  * std::abs(vt2ave - vt2r) * (Real(denr) / den_arr(i,j,k))
2636  * acrfac;
2637  const Real ratio = amrex::min(
2638  amrex::max(Real(0.0), qg_val / qr_val), Real(1.0));
2639  pgacr_arr(i,j,k) *= ratio * ratio;
2640  pgacr_arr(i,j,k) = amrex::min(pgacr_arr(i,j,k), qr_val / dtcld);
2641  }
2642 
2643  if (qg_val > Real(qcrmin) && nr_val > Real(nrmin)) {
2644  const Real acrfac =
2645  Real(1.5) * rslope2_arr(i,j,k,0) * rslope_arr(i,j,k,2)
2646  + rslope_arr(i,j,k,0) * rslope2_arr(i,j,k,2)
2647  + Real(0.5) * rslope3_arr(i,j,k,2);
2648  ngacr_arr(i,j,k) = pi_wdm6_loc * nr_val * n0g_loc
2649  * std::abs(vt2ave - vt2r) * acrfac;
2650  const Real ratio = amrex::min(
2651  amrex::max(Real(0.0), qg_val / qr_val), Real(1.0));
2652  ngacr_arr(i,j,k) *= ratio * ratio;
2653  ngacr_arr(i,j,k) = amrex::min(ngacr_arr(i,j,k), nr_val / dtcld);
2654  }
2655 
2656  if (qg_val > Real(qcrmin) && qs_val > Real(qcrmin)) {
2657  pgacs_arr(i,j,k) = Real(0.0);
2658  }
2659 
2660  if (supcol <= Real(0.0)) {
2661  const Real xlf = Real(xlf0);
2662  if (qs_val > Real(0.0)) {
2663  pseml_arr(i,j,k) = amrex::min(
2664  amrex::max(
2665  Real(cliq) * supcol
2666  * (paacw_arr(i,j,k) + psacr_arr(i,j,k)) / xlf,
2667  -qs_val / dtcld),
2668  Real(0.0));
2669  }
2670  if (qs_val > Real(qcrmin)) {
2671  const Real sfac = rslope_arr(i,j,k,1) * Real(n0s) * n0sfac / qs_val;
2672  nseml_arr(i,j,k) = -sfac * pseml_arr(i,j,k);
2673  }
2674 
2675  if (qg_val > Real(0.0)) {
2676  pgeml_arr(i,j,k) = amrex::min(
2677  amrex::max(
2678  Real(cliq) * supcol
2679  * (paacw_arr(i,j,k) + pgacr_arr(i,j,k)) / xlf,
2680  -qg_val / dtcld),
2681  Real(0.0));
2682  }
2683  if (qg_val > Real(qcrmin)) {
2684  const Real gfac = rslope_arr(i,j,k,2) * n0g_loc / qg_val;
2685  ngeml_arr(i,j,k) = -gfac * pgeml_arr(i,j,k);
2686  }
2687  }
2688  });
2689 
2690 
2691 
2692  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2693  const Real supcol = Real(t0c) - t_arr(i,j,k);
2694  if (supcol <= Real(0.0)) {
2695  return;
2696  }
2697 
2698  const Real n0sfac = amrex::max(
2699  amrex::min(std::exp(Real(alpha_wdm6) * supcol),
2700  Real(n0smax) / Real(n0s)),
2701  Real(1.0));
2702  const Real supsat =
2703  amrex::max(qv_arr(i,j,k), Real(qmin)) - qsati_arr(i,j,k);
2704  const Real satdt = supsat / dtcld;
2705  int ifsat = 0;
2706 
2707  const Real qi_val = qi_arr(i,j,k);
2708  const Real qs_val = qs_arr(i,j,k);
2709  const Real qg_val = qg_arr(i,j,k);
2710  const Real xni = xni_arr(i,j,k);
2711  const Real xni_safe = amrex::max(xni, Real(1.0e-30));
2712  const Real xmi = den_arr(i,j,k) * qi_val / xni_safe;
2713  const Real diameter = amrex::min(
2714  Real(dicon) * std::sqrt(xmi), Real(dimax));
2715  const Real rhi = rhi_arr(i,j,k);
2716  const Real work1i = work1_arr(i,j,k,1);
2717 
2718  if (qi_val > Real(0.0) && ifsat != 1) {
2719  pidep_arr(i,j,k) = Real(4.0) * diameter * xni
2720  * (rhi - Real(1.0)) / work1i;
2721  Real supice = satdt - prevp_arr(i,j,k);
2722  if (pidep_arr(i,j,k) < Real(0.0)) {
2723  pidep_arr(i,j,k) = amrex::max(
2724  amrex::max(pidep_arr(i,j,k), satdt / Real(2.0)),
2725  supice);
2726  pidep_arr(i,j,k) = amrex::max(
2727  pidep_arr(i,j,k), -qi_val / dtcld);
2728  } else {
2729  pidep_arr(i,j,k) = amrex::min(
2730  amrex::min(pidep_arr(i,j,k), satdt / Real(2.0)),
2731  supice);
2732  }
2733  if (std::abs(prevp_arr(i,j,k) + pidep_arr(i,j,k))
2734  >= std::abs(satdt)) {
2735  ifsat = 1;
2736  }
2737  }
2738 
2739  if (qs_val > Real(0.0) && ifsat != 1) {
2740  const Real coeres_s = rslope2_arr(i,j,k,1)
2741  * std::sqrt(rslope_arr(i,j,k,1) * rslopeb_arr(i,j,k,1));
2742  psdep_arr(i,j,k) = (rhi - Real(1.0)) * n0sfac
2743  * (precs1_loc * rslope2_arr(i,j,k,1)
2744  + precs2_loc * work2_arr(i,j,k) * coeres_s)
2745  / work1i;
2746  Real supice = satdt - prevp_arr(i,j,k) - pidep_arr(i,j,k);
2747  if (psdep_arr(i,j,k) < Real(0.0)) {
2748  psdep_arr(i,j,k) = amrex::max(
2749  psdep_arr(i,j,k), -qs_val / dtcld);
2750  psdep_arr(i,j,k) = amrex::max(
2751  amrex::max(psdep_arr(i,j,k), satdt / Real(2.0)),
2752  supice);
2753  } else {
2754  psdep_arr(i,j,k) = amrex::min(
2755  amrex::min(psdep_arr(i,j,k), satdt / Real(2.0)),
2756  supice);
2757  }
2758  if (std::abs(prevp_arr(i,j,k) + pidep_arr(i,j,k)
2759  + psdep_arr(i,j,k)) >= std::abs(satdt)) {
2760  ifsat = 1;
2761  }
2762  }
2763 
2764  if (qg_val > Real(0.0) && ifsat != 1) {
2765  const Real coeres_g = rslope2_arr(i,j,k,2)
2766  * std::sqrt(rslope_arr(i,j,k,2) * rslopeb_arr(i,j,k,2));
2767  pgdep_arr(i,j,k) = (rhi - Real(1.0))
2768  * (precg1_loc * rslope2_arr(i,j,k,2)
2769  + precg2_loc * work2_arr(i,j,k) * coeres_g)
2770  / work1i;
2771  Real supice = satdt - prevp_arr(i,j,k) - pidep_arr(i,j,k)
2772  - psdep_arr(i,j,k);
2773  if (pgdep_arr(i,j,k) < Real(0.0)) {
2774  pgdep_arr(i,j,k) = amrex::max(
2775  pgdep_arr(i,j,k), -qg_val / dtcld);
2776  pgdep_arr(i,j,k) = amrex::max(
2777  amrex::max(pgdep_arr(i,j,k), satdt / Real(2.0)),
2778  supice);
2779  } else {
2780  pgdep_arr(i,j,k) = amrex::min(
2781  amrex::min(pgdep_arr(i,j,k), satdt / Real(2.0)),
2782  supice);
2783  }
2784  if (std::abs(prevp_arr(i,j,k) + pidep_arr(i,j,k)
2785  + psdep_arr(i,j,k) + pgdep_arr(i,j,k))
2786  >= std::abs(satdt)) {
2787  ifsat = 1;
2788  }
2789  }
2790 
2791  if (supsat > Real(0.0) && ifsat != 1) {
2792  const Real supice = satdt - prevp_arr(i,j,k) - pidep_arr(i,j,k)
2793  - psdep_arr(i,j,k) - pgdep_arr(i,j,k);
2794  const Real xni0 = wdm6_literal(1.0e3) * std::exp(wdm6_literal(0.1) * supcol);
2795  const Real roqi0 = wdm6_literal(4.92e-11) * std::pow(xni0, wdm6_literal(1.33));
2796  const Real pigen_raw = amrex::max(
2797  Real(0.0),
2798  (roqi0 / den_arr(i,j,k) - amrex::max(qi_val, Real(0.0))) / dtcld);
2799  pigen_arr(i,j,k) = amrex::min(
2800  amrex::min(pigen_raw, satdt), supice);
2801  }
2802  });
2803 
2804 
2805 
2806  const Real roqimax_loc = m_roqimax;
2807  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2808  const Real supcol = Real(t0c) - t_arr(i,j,k);
2809 
2810  if (qi_arr(i,j,k) > Real(0.0)) {
2811  const Real qimax = roqimax_loc / den_arr(i,j,k);
2812  psaut_arr(i,j,k) = amrex::max(
2813  Real(0.0), (qi_arr(i,j,k) - qimax) / dtcld);
2814  }
2815 
2816  if (qs_arr(i,j,k) > Real(0.0)) {
2817  // Fortran :2510 alpha2 = 1.e-3*exp(0.09*(-supcol)). Both
2818  // literals are unsuffixed and they push OPPOSITE ways, so
2819  // neither can be judged alone: 1.e-3 contributes +4.749745e-08
2820  // and 0.09 contributes -3.5763e-09*supcol, and the residual
2821  // is their signed sum. Verified with zero free parameters
2822  // against measured supcol at (199,3), k=91..98: predicted
2823  // and measured relative error agree to 7 digits at every
2824  // cell, ratio 1.0000. At k=91 that value is 7.652614e-08,
2825  // which is exactly the step-2 rhoQ6/qgraup plotfile
2826  // residual, so this literal pair is that residual.
2827  const Real alpha2 = wdm6_literal(1.e-3)
2828  * std::exp(wdm6_literal(0.09) * (-supcol));
2829  pgaut_arr(i,j,k) = amrex::min(
2830  amrex::max(
2831  Real(0.0), alpha2 * (qs_arr(i,j,k) - Real(qs0))),
2832  qs_arr(i,j,k) / dtcld);
2833  }
2834  });
2835 
2836 
2837 
2838  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2839  const Real supcol = Real(t0c) - t_arr(i,j,k);
2840  if (supcol < Real(0.0)) {
2841  const Real n0sfac = amrex::max(
2842  amrex::min(std::exp(Real(alpha_wdm6) * supcol),
2843  Real(n0smax) / Real(n0s)),
2844  Real(1.0));
2845 
2846  if (qs_arr(i,j,k) > Real(0.0)
2847  && rhw_arr(i,j,k) < Real(1.0)) {
2848  const Real coeres = rslope2_arr(i,j,k,1)
2849  * std::sqrt(rslope_arr(i,j,k,1)
2850  * rslopeb_arr(i,j,k,1));
2851  psevp_arr(i,j,k) = (rhw_arr(i,j,k) - Real(1.0))
2852  * n0sfac
2853  * (precs1_loc * rslope2_arr(i,j,k,1)
2854  + precs2_loc * work2_arr(i,j,k) * coeres)
2855  / work1_arr(i,j,k,0);
2856  psevp_arr(i,j,k) = amrex::min(
2857  amrex::max(psevp_arr(i,j,k),
2858  -qs_arr(i,j,k) / dtcld),
2859  Real(0.0));
2860  }
2861 
2862  if (qg_arr(i,j,k) > Real(0.0)
2863  && rhw_arr(i,j,k) < Real(1.0)) {
2864  const Real coeres = rslope2_arr(i,j,k,2)
2865  * std::sqrt(rslope_arr(i,j,k,2)
2866  * rslopeb_arr(i,j,k,2));
2867  pgevp_arr(i,j,k) = (rhw_arr(i,j,k) - Real(1.0))
2868  * (precg1_loc * rslope2_arr(i,j,k,2)
2869  + precg2_loc * work2_arr(i,j,k) * coeres)
2870  / work1_arr(i,j,k,0);
2871  pgevp_arr(i,j,k) = amrex::min(
2872  amrex::max(pgevp_arr(i,j,k),
2873  -qg_arr(i,j,k) / dtcld),
2874  Real(0.0));
2875  }
2876  }
2877  });
2878 
2879 
2880 
2881  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
2882  const Real qmin_l = Real(qmin);
2883  const Real qcrmin_l = Real(qcrmin);
2884  const Real ncmin_l = Real(ncmin);
2885  const Real nrmin_l = Real(nrmin);
2886  const Real t0c_l = Real(t0c);
2887  const Real one_l = Real(1.0);
2888  const Real zero_l = Real(0.0);
2889  const Real delta2 =
2890  (qr_arr(i,j,k) < wdm6_literal(1.0e-4) && qs_arr(i,j,k) < wdm6_literal(1.0e-4))
2891  ? one_l : zero_l;
2892  const Real delta3 =
2893  (qr_arr(i,j,k) < wdm6_literal(1.0e-4)) ? one_l : zero_l;
2894 
2895  if (t_arr(i,j,k) <= t0c_l) {
2896  Real value, source, factor, xlf, xlwork2;
2897 
2898  value = amrex::max(qmin_l, qc_arr(i,j,k));
2899  source = (praut_arr(i,j,k) + pracw_arr(i,j,k)
2900  + paacw_arr(i,j,k) + paacw_arr(i,j,k)) * dtcld;
2901  if (source > value) {
2902  factor = value / source;
2903  praut_arr(i,j,k) = praut_arr(i,j,k) * factor;
2904  pracw_arr(i,j,k) = pracw_arr(i,j,k) * factor;
2905  paacw_arr(i,j,k) = paacw_arr(i,j,k) * factor;
2906  }
2907 
2908  value = amrex::max(qmin_l, qi_arr(i,j,k));
2909  source = (psaut_arr(i,j,k) - pigen_arr(i,j,k)
2910  - pidep_arr(i,j,k) + praci_arr(i,j,k)
2911  + psaci_arr(i,j,k) + pgaci_arr(i,j,k)) * dtcld;
2912  if (source > value) {
2913  factor = value / source;
2914  psaut_arr(i,j,k) = psaut_arr(i,j,k) * factor;
2915  pigen_arr(i,j,k) = pigen_arr(i,j,k) * factor;
2916  pidep_arr(i,j,k) = pidep_arr(i,j,k) * factor;
2917  praci_arr(i,j,k) = praci_arr(i,j,k) * factor;
2918  psaci_arr(i,j,k) = psaci_arr(i,j,k) * factor;
2919  pgaci_arr(i,j,k) = pgaci_arr(i,j,k) * factor;
2920  }
2921 
2922  value = amrex::max(qmin_l, qr_arr(i,j,k));
2923  source = (-praut_arr(i,j,k) - prevp_arr(i,j,k)
2924  - pracw_arr(i,j,k) + piacr_arr(i,j,k)
2925  + psacr_arr(i,j,k) + pgacr_arr(i,j,k)) * dtcld;
2926  if (source > value) {
2927  factor = value / source;
2928  praut_arr(i,j,k) = praut_arr(i,j,k) * factor;
2929  prevp_arr(i,j,k) = prevp_arr(i,j,k) * factor;
2930  pracw_arr(i,j,k) = pracw_arr(i,j,k) * factor;
2931  piacr_arr(i,j,k) = piacr_arr(i,j,k) * factor;
2932  psacr_arr(i,j,k) = psacr_arr(i,j,k) * factor;
2933  pgacr_arr(i,j,k) = pgacr_arr(i,j,k) * factor;
2934  }
2935 
2936  value = amrex::max(qmin_l, qs_arr(i,j,k));
2937  source = -(psdep_arr(i,j,k) + psaut_arr(i,j,k)
2938  - pgaut_arr(i,j,k) + paacw_arr(i,j,k)
2939  + piacr_arr(i,j,k) * delta3
2940  + praci_arr(i,j,k) * delta3
2941  - pracs_arr(i,j,k) * (one_l - delta2)
2942  + psacr_arr(i,j,k) * delta2
2943  + psaci_arr(i,j,k) - pgacs_arr(i,j,k)) * dtcld;
2944  if (source > value) {
2945  factor = value / source;
2946  psdep_arr(i,j,k) = psdep_arr(i,j,k) * factor;
2947  psaut_arr(i,j,k) = psaut_arr(i,j,k) * factor;
2948  pgaut_arr(i,j,k) = pgaut_arr(i,j,k) * factor;
2949  paacw_arr(i,j,k) = paacw_arr(i,j,k) * factor;
2950  piacr_arr(i,j,k) = piacr_arr(i,j,k) * factor;
2951  praci_arr(i,j,k) = praci_arr(i,j,k) * factor;
2952  psaci_arr(i,j,k) = psaci_arr(i,j,k) * factor;
2953  pracs_arr(i,j,k) = pracs_arr(i,j,k) * factor;
2954  psacr_arr(i,j,k) = psacr_arr(i,j,k) * factor;
2955  pgacs_arr(i,j,k) = pgacs_arr(i,j,k) * factor;
2956  }
2957 
2958  value = amrex::max(qmin_l, qg_arr(i,j,k));
2959  source = -(pgdep_arr(i,j,k) + pgaut_arr(i,j,k)
2960  + piacr_arr(i,j,k) * (one_l - delta3)
2961  + praci_arr(i,j,k) * (one_l - delta3)
2962  + psacr_arr(i,j,k) * (one_l - delta2)
2963  + pracs_arr(i,j,k) * (one_l - delta2)
2964  + pgaci_arr(i,j,k) + paacw_arr(i,j,k)
2965  + pgacr_arr(i,j,k) + pgacs_arr(i,j,k)) * dtcld;
2966  if (source > value) {
2967  factor = value / source;
2968  pgdep_arr(i,j,k) = pgdep_arr(i,j,k) * factor;
2969  pgaut_arr(i,j,k) = pgaut_arr(i,j,k) * factor;
2970  piacr_arr(i,j,k) = piacr_arr(i,j,k) * factor;
2971  praci_arr(i,j,k) = praci_arr(i,j,k) * factor;
2972  psacr_arr(i,j,k) = psacr_arr(i,j,k) * factor;
2973  pracs_arr(i,j,k) = pracs_arr(i,j,k) * factor;
2974  paacw_arr(i,j,k) = paacw_arr(i,j,k) * factor;
2975  pgaci_arr(i,j,k) = pgaci_arr(i,j,k) * factor;
2976  pgacr_arr(i,j,k) = pgacr_arr(i,j,k) * factor;
2977  pgacs_arr(i,j,k) = pgacs_arr(i,j,k) * factor;
2978  }
2979 
2980  value = amrex::max(ncmin_l, nc_arr(i,j,k));
2981  source = (nrauto_arr(i,j,k) + nccol_arr(i,j,k)
2982  + nraccr_arr(i,j,k) + naacw_arr(i,j,k)
2983  + naacw_arr(i,j,k)) * dtcld;
2984  if (source > value) {
2985  factor = value / source;
2986  nrauto_arr(i,j,k) = nrauto_arr(i,j,k) * factor;
2987  nccol_arr(i,j,k) = nccol_arr(i,j,k) * factor;
2988  nraccr_arr(i,j,k) = nraccr_arr(i,j,k) * factor;
2989  naacw_arr(i,j,k) = naacw_arr(i,j,k) * factor;
2990  }
2991 
2992  value = amrex::max(nrmin_l, nr_arr(i,j,k));
2993  source = (-nrauto_arr(i,j,k) + nrcol_arr(i,j,k)
2994  + niacr_arr(i,j,k) + nsacr_arr(i,j,k)
2995  + ngacr_arr(i,j,k)) * dtcld;
2996  if (source > value) {
2997  factor = value / source;
2998  nrauto_arr(i,j,k) = nrauto_arr(i,j,k) * factor;
2999  nrcol_arr(i,j,k) = nrcol_arr(i,j,k) * factor;
3000  niacr_arr(i,j,k) = niacr_arr(i,j,k) * factor;
3001  nsacr_arr(i,j,k) = nsacr_arr(i,j,k) * factor;
3002  ngacr_arr(i,j,k) = ngacr_arr(i,j,k) * factor;
3003  }
3004 
3005  work2_arr(i,j,k) = -(prevp_arr(i,j,k) + psdep_arr(i,j,k)
3006  + pgdep_arr(i,j,k) + pigen_arr(i,j,k)
3007  + pidep_arr(i,j,k));
3008  qv_arr(i,j,k) = qv_arr(i,j,k) + work2_arr(i,j,k) * dtcld;
3009  qc_arr(i,j,k) = amrex::max(
3010  qc_arr(i,j,k) - (praut_arr(i,j,k) + pracw_arr(i,j,k)
3011  + paacw_arr(i,j,k) + paacw_arr(i,j,k))
3012  * dtcld,
3013  zero_l);
3014  qr_arr(i,j,k) = amrex::max(
3015  qr_arr(i,j,k) + (praut_arr(i,j,k) + pracw_arr(i,j,k)
3016  + prevp_arr(i,j,k) - piacr_arr(i,j,k)
3017  - pgacr_arr(i,j,k) - psacr_arr(i,j,k))
3018  * dtcld,
3019  zero_l);
3020  qi_arr(i,j,k) = amrex::max(
3021  qi_arr(i,j,k) - (psaut_arr(i,j,k) + praci_arr(i,j,k)
3022  + psaci_arr(i,j,k) + pgaci_arr(i,j,k)
3023  - pigen_arr(i,j,k) - pidep_arr(i,j,k))
3024  * dtcld,
3025  zero_l);
3026  qs_arr(i,j,k) = amrex::max(
3027  qs_arr(i,j,k) + (psdep_arr(i,j,k) + psaut_arr(i,j,k)
3028  + paacw_arr(i,j,k) - pgaut_arr(i,j,k)
3029  + piacr_arr(i,j,k) * delta3
3030  + praci_arr(i,j,k) * delta3
3031  + psaci_arr(i,j,k) - pgacs_arr(i,j,k)
3032  - pracs_arr(i,j,k) * (one_l - delta2)
3033  + psacr_arr(i,j,k) * delta2) * dtcld,
3034  zero_l);
3035  qg_arr(i,j,k) = amrex::max(
3036  qg_arr(i,j,k) + (pgdep_arr(i,j,k) + pgaut_arr(i,j,k)
3037  + piacr_arr(i,j,k) * (one_l - delta3)
3038  + praci_arr(i,j,k) * (one_l - delta3)
3039  + psacr_arr(i,j,k) * (one_l - delta2)
3040  + pracs_arr(i,j,k) * (one_l - delta2)
3041  + pgaci_arr(i,j,k) + paacw_arr(i,j,k)
3042  + pgacr_arr(i,j,k) + pgacs_arr(i,j,k))
3043  * dtcld,
3044  zero_l);
3045  nc_arr(i,j,k) = amrex::max(
3046  nc_arr(i,j,k) + (-nrauto_arr(i,j,k) - nccol_arr(i,j,k)
3047  - nraccr_arr(i,j,k) - naacw_arr(i,j,k)
3048  - naacw_arr(i,j,k)) * dtcld,
3049  zero_l);
3050  nr_arr(i,j,k) = amrex::max(
3051  nr_arr(i,j,k) + (nrauto_arr(i,j,k) - nrcol_arr(i,j,k)
3052  - niacr_arr(i,j,k) - nsacr_arr(i,j,k)
3053  - ngacr_arr(i,j,k)) * dtcld,
3054  zero_l);
3055  xlf = Real(xls) - xl_arr(i,j,k);
3056  xlwork2 = -Real(xls) * (psdep_arr(i,j,k) + pgdep_arr(i,j,k)
3057  + pidep_arr(i,j,k) + pigen_arr(i,j,k))
3058  - xl_arr(i,j,k) * prevp_arr(i,j,k)
3059  - xlf * (piacr_arr(i,j,k) + paacw_arr(i,j,k)
3060  + paacw_arr(i,j,k) + pgacr_arr(i,j,k)
3061  + psacr_arr(i,j,k));
3062  t_arr(i,j,k) = t_arr(i,j,k) - xlwork2 / cpm_arr(i,j,k) * dtcld;
3063  } else {
3064  Real value, source, factor, xlf, xlwork2;
3065 
3066  value = amrex::max(qmin_l, qc_arr(i,j,k));
3067  source = (praut_arr(i,j,k) + pracw_arr(i,j,k)
3068  + paacw_arr(i,j,k) + paacw_arr(i,j,k)) * dtcld;
3069  if (source > value) {
3070  factor = value / source;
3071  praut_arr(i,j,k) = praut_arr(i,j,k) * factor;
3072  pracw_arr(i,j,k) = pracw_arr(i,j,k) * factor;
3073  paacw_arr(i,j,k) = paacw_arr(i,j,k) * factor;
3074  }
3075 
3076  value = amrex::max(qmin_l, qr_arr(i,j,k));
3077  source = (-paacw_arr(i,j,k) - praut_arr(i,j,k)
3078  + pseml_arr(i,j,k) + pgeml_arr(i,j,k)
3079  - pracw_arr(i,j,k) - paacw_arr(i,j,k)
3080  - prevp_arr(i,j,k)) * dtcld;
3081  if (source > value) {
3082  factor = value / source;
3083  praut_arr(i,j,k) = praut_arr(i,j,k) * factor;
3084  prevp_arr(i,j,k) = prevp_arr(i,j,k) * factor;
3085  pracw_arr(i,j,k) = pracw_arr(i,j,k) * factor;
3086  paacw_arr(i,j,k) = paacw_arr(i,j,k) * factor;
3087  pseml_arr(i,j,k) = pseml_arr(i,j,k) * factor;
3088  pgeml_arr(i,j,k) = pgeml_arr(i,j,k) * factor;
3089  }
3090 
3091  value = amrex::max(qcrmin_l, qs_arr(i,j,k));
3092  source = (pgacs_arr(i,j,k) - pseml_arr(i,j,k)
3093  - psevp_arr(i,j,k)) * dtcld;
3094  if (source > value) {
3095  factor = value / source;
3096  pgacs_arr(i,j,k) = pgacs_arr(i,j,k) * factor;
3097  psevp_arr(i,j,k) = psevp_arr(i,j,k) * factor;
3098  pseml_arr(i,j,k) = pseml_arr(i,j,k) * factor;
3099  }
3100 
3101  value = amrex::max(qcrmin_l, qg_arr(i,j,k));
3102  source = -(pgacs_arr(i,j,k) + pgevp_arr(i,j,k)
3103  + pgeml_arr(i,j,k)) * dtcld;
3104  if (source > value) {
3105  factor = value / source;
3106  pgacs_arr(i,j,k) = pgacs_arr(i,j,k) * factor;
3107  pgevp_arr(i,j,k) = pgevp_arr(i,j,k) * factor;
3108  pgeml_arr(i,j,k) = pgeml_arr(i,j,k) * factor;
3109  }
3110 
3111  value = amrex::max(ncmin_l, nc_arr(i,j,k));
3112  source = (nrauto_arr(i,j,k) + nccol_arr(i,j,k)
3113  + nraccr_arr(i,j,k) + naacw_arr(i,j,k)
3114  + naacw_arr(i,j,k)) * dtcld;
3115  if (source > value) {
3116  factor = value / source;
3117  nrauto_arr(i,j,k) = nrauto_arr(i,j,k) * factor;
3118  nccol_arr(i,j,k) = nccol_arr(i,j,k) * factor;
3119  nraccr_arr(i,j,k) = nraccr_arr(i,j,k) * factor;
3120  naacw_arr(i,j,k) = naacw_arr(i,j,k) * factor;
3121  }
3122 
3123  value = amrex::max(nrmin_l, nr_arr(i,j,k));
3124  source = (-nrauto_arr(i,j,k) + nrcol_arr(i,j,k)
3125  - nseml_arr(i,j,k) - ngeml_arr(i,j,k)) * dtcld;
3126  if (source > value) {
3127  factor = value / source;
3128  nrauto_arr(i,j,k) = nrauto_arr(i,j,k) * factor;
3129  nrcol_arr(i,j,k) = nrcol_arr(i,j,k) * factor;
3130  nseml_arr(i,j,k) = nseml_arr(i,j,k) * factor;
3131  ngeml_arr(i,j,k) = ngeml_arr(i,j,k) * factor;
3132  }
3133 
3134  work2_arr(i,j,k) = -(prevp_arr(i,j,k) + psevp_arr(i,j,k)
3135  + pgevp_arr(i,j,k));
3136  qv_arr(i,j,k) = qv_arr(i,j,k) + work2_arr(i,j,k) * dtcld;
3137  qc_arr(i,j,k) = amrex::max(
3138  qc_arr(i,j,k) - (praut_arr(i,j,k) + pracw_arr(i,j,k)
3139  + paacw_arr(i,j,k) + paacw_arr(i,j,k))
3140  * dtcld,
3141  zero_l);
3142  qr_arr(i,j,k) = amrex::max(
3143  qr_arr(i,j,k) + (praut_arr(i,j,k) + pracw_arr(i,j,k)
3144  + prevp_arr(i,j,k) + paacw_arr(i,j,k)
3145  + paacw_arr(i,j,k) - pseml_arr(i,j,k)
3146  - pgeml_arr(i,j,k)) * dtcld,
3147  zero_l);
3148  qs_arr(i,j,k) = amrex::max(
3149  qs_arr(i,j,k) + (psevp_arr(i,j,k) - pgacs_arr(i,j,k)
3150  + pseml_arr(i,j,k)) * dtcld,
3151  zero_l);
3152  qg_arr(i,j,k) = amrex::max(
3153  qg_arr(i,j,k) + (pgacs_arr(i,j,k) + pgevp_arr(i,j,k)
3154  + pgeml_arr(i,j,k)) * dtcld,
3155  zero_l);
3156  nc_arr(i,j,k) = amrex::max(
3157  nc_arr(i,j,k) + (-nrauto_arr(i,j,k) - nccol_arr(i,j,k)
3158  - nraccr_arr(i,j,k) - naacw_arr(i,j,k)
3159  - naacw_arr(i,j,k)) * dtcld,
3160  zero_l);
3161  nr_arr(i,j,k) = amrex::max(
3162  nr_arr(i,j,k) + (nrauto_arr(i,j,k) - nrcol_arr(i,j,k)
3163  + nseml_arr(i,j,k) + ngeml_arr(i,j,k))
3164  * dtcld,
3165  zero_l);
3166  xlf = Real(xls) - xl_arr(i,j,k);
3167  xlwork2 = -xl_arr(i,j,k) * (prevp_arr(i,j,k)
3168  + psevp_arr(i,j,k)
3169  + pgevp_arr(i,j,k))
3170  - xlf * (pseml_arr(i,j,k) + pgeml_arr(i,j,k));
3171  t_arr(i,j,k) = t_arr(i,j,k) - xlwork2 / cpm_arr(i,j,k) * dtcld;
3172  }
3173  });
3174 
3175 
3176 
3177  const Real hsub = Real(xls);
3178  const Real hvap = Real(xlv0);
3179  const Real cvap = Real(cpv);
3180  const Real ttp = Real(t0c) + wdm6_literal(0.01);
3181  const Real dldt = cvap - Real(cliq);
3182  const Real xa = -dldt / Real(rv);
3183  const Real xb = xa + hvap / (Real(rv) * ttp);
3184  const Real dldti = cvap - Real(cice);
3185  const Real xai = -dldti / Real(rv);
3186  const Real xbi = xai + hsub / (Real(rv) * ttp);
3187 
3188  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
3189  const Real tr = ttp / t_arr(i,j,k);
3190  Real qsw = Real(psat) * std::exp(std::log(tr) * xa)
3191  * std::exp(xb * (Real(1.) - tr));
3192  qsw = amrex::min(qsw, wdm6_literal(0.99) * p_arr(i,j,k));
3193  qsw = Real(ep2) * qsw / (p_arr(i,j,k) - qsw);
3194  qsw = amrex::max(qsw, Real(qmin));
3195  qsatw_arr(i,j,k) = qsw;
3196 
3197  Real qsi;
3198  if (t_arr(i,j,k) < ttp) {
3199  qsi = Real(psat) * std::exp(std::log(tr) * xai)
3200  * std::exp(xbi * (Real(1.) - tr));
3201  } else {
3202  qsi = Real(psat) * std::exp(std::log(tr) * xa)
3203  * std::exp(xb * (Real(1.) - tr));
3204  }
3205  qsi = amrex::min(qsi, wdm6_literal(0.99) * p_arr(i,j,k));
3206  qsi = Real(ep2) * qsi / (p_arr(i,j,k) - qsi);
3207  qsi = amrex::max(qsi, Real(qmin));
3208  qsati_arr(i,j,k) = qsi;
3209 
3210  rhw_arr(i,j,k) = amrex::max(qv_arr(i,j,k) / qsw, Real(qmin));
3211  });
3212 
3213 
3214  const Real g16a_cbrt24 = wdm6_default_real_pow(24.0, 0.3333333);
3215 
3216 
3217  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
3218  qrs_tmp_arr(i,j,k,0) = qr_arr(i,j,k);
3219  qrs_tmp_arr(i,j,k,1) = qs_arr(i,j,k);
3220  qrs_tmp_arr(i,j,k,2) = qg_arr(i,j,k);
3221  ncr_tmp_arr(i,j,k) = nr_arr(i,j,k);
3222  });
3223 
3224  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
3225  Real rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3, rain_vt, rain_vtn;
3226  Real snow_rslope, snow_rslopeb, snow_rslope2, snow_rslope3, snow_vt, snow_n0sfac;
3227  Real graup_rslope, graup_rslopeb, graup_rslope2, graup_rslope3, graup_vt;
3228 
3229  wdm6_slope_rain_cell(qrs_tmp_arr(i,j,k,0), ncr_tmp_arr(i,j,k),
3230  den_arr(i,j,k), denfac_arr(i,j,k),
3231  Real(qcrmin), Real(nrmin),
3232  rslopermax_loc, rsloperbmax_loc,
3233  rsloper2max_loc, rsloper3max_loc,
3234  Real(bvtr), pvtr_loc, pvtrn_loc, pidnr_loc,
3235  rain_rslope, rain_rslopeb, rain_rslope2, rain_rslope3,
3236  rain_vt, rain_vtn);
3237  wdm6_slope_snow_cell(qrs_tmp_arr(i,j,k,1), den_arr(i,j,k), denfac_arr(i,j,k),
3238  t_arr(i,j,k), pidn0s_loc, Real(alpha_wdm6),
3240  rslopesmax_loc, rslopesbmax_loc,
3241  rslopes2max_loc, rslopes3max_loc,
3242  Real(bvts), pvts_loc,
3243  snow_rslope, snow_rslopeb, snow_rslope2, snow_rslope3,
3244  snow_vt, snow_n0sfac);
3245  wdm6_slope_graup_cell(qrs_tmp_arr(i,j,k,2), den_arr(i,j,k), denfac_arr(i,j,k),
3246  pidn0g_loc, Real(qcrmin),
3247  rslopegmax_loc, rslopegbmax_loc,
3248  rslopeg2max_loc, rslopeg3max_loc,
3249  slope_bvtg_loc, pvtg_loc,
3250  graup_rslope, graup_rslopeb, graup_rslope2, graup_rslope3,
3251  graup_vt);
3252 
3253  rslope_arr(i,j,k,0) = rain_rslope;
3254  rslope_arr(i,j,k,1) = snow_rslope;
3255  rslope_arr(i,j,k,2) = graup_rslope;
3256  rslopeb_arr(i,j,k,0) = rain_rslopeb;
3257  rslopeb_arr(i,j,k,1) = snow_rslopeb;
3258  rslopeb_arr(i,j,k,2) = graup_rslopeb;
3259  rslope2_arr(i,j,k,0) = rain_rslope2;
3260  rslope2_arr(i,j,k,1) = snow_rslope2;
3261  rslope2_arr(i,j,k,2) = graup_rslope2;
3262  rslope3_arr(i,j,k,0) = rain_rslope3;
3263  rslope3_arr(i,j,k,1) = snow_rslope3;
3264  rslope3_arr(i,j,k,2) = graup_rslope3;
3265  work1_arr(i,j,k,0) = rain_vt;
3266  work1_arr(i,j,k,1) = snow_vt;
3267  work1_arr(i,j,k,2) = graup_vt;
3268  workn_arr(i,j,k) = rain_vtn;
3269 
3270  avedia_arr(i,j,k,1) = rslope_arr(i,j,k,0) * g16a_cbrt24;
3271  if (avedia_arr(i,j,k,1) <= Real(di82)) {
3272  nc_arr(i,j,k) += nr_arr(i,j,k);
3273  nr_arr(i,j,k) = Real(0.0);
3274  qc_arr(i,j,k) += qr_arr(i,j,k);
3275  qr_arr(i,j,k) = Real(0.0);
3276  }
3277  });
3278 
3279 
3280 
3281  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
3282  if (rhw_arr(i,j,k) > Real(1.0)) {
3283  const Real ratio = rhw_arr(i,j,k) / Real(satmax);
3284  const Real fraction = amrex::min(Real(1.0),
3285  std::exp(std::log(ratio) * Real(actk)));
3286  Real ncact_raw = (nn_arr(i,j,k) + nc_arr(i,j,k)) * fraction - nc_arr(i,j,k);
3287  Real ncact = amrex::max(Real(0.0), ncact_raw);
3288  ncact /= dtcld;
3289  const Real ncact_cap = amrex::max(nn_arr(i,j,k), Real(0.0)) / dtcld;
3290  ncact = amrex::min(ncact, ncact_cap);
3291  const Real actr_um = Real(actr) * wdm6_literal(1.0e-6);
3292  const Real pcact = amrex::min(
3293  Real(4.0) * pi_wdm6_loc * Real(denr)
3294  * actr_um * actr_um * actr_um * ncact
3295  / (Real(3.0) * den_arr(i,j,k)),
3296  amrex::max(qv_arr(i,j,k), Real(0.0)) / dtcld);
3297 
3298  ncact_arr(i,j,k) = ncact;
3299  act_ratio_arr(i,j,k) = ratio;
3300  act_fraction_arr(i,j,k) = fraction;
3301  act_raw_arr(i,j,k) = ncact_raw;
3302  act_cap_arr(i,j,k) = ncact_cap;
3303  pcact_arr(i,j,k) = pcact;
3304  qv_arr(i,j,k) = amrex::max(qv_arr(i,j,k) - pcact * dtcld, Real(0.0));
3305  qc_arr(i,j,k) = amrex::max(qc_arr(i,j,k) + pcact * dtcld, Real(0.0));
3306  nn_arr(i,j,k) = amrex::max(nn_arr(i,j,k) - ncact * dtcld, Real(0.0));
3307  nc_arr(i,j,k) = amrex::max(nc_arr(i,j,k) + ncact * dtcld, Real(0.0));
3308  t_arr(i,j,k) += pcact * xl_arr(i,j,k) / cpm_arr(i,j,k) * dtcld;
3309  }
3310 
3311  const Real tr = ttp / t_arr(i,j,k);
3312  Real qsw = Real(psat) * std::exp(std::log(tr) * xa)
3313  * std::exp(xb * (Real(1.0) - tr));
3314  qsw = amrex::min(qsw, wdm6_literal(0.99) * p_arr(i,j,k));
3315  qsw = Real(ep2) * qsw / (p_arr(i,j,k) - qsw);
3316  qsw = amrex::max(qsw, Real(qmin));
3317  qsatw_arr(i,j,k) = qsw;
3318 
3319  work1_arr(i,j,k,0) = wdm6_conden(
3320  t_arr(i,j,k), qv_arr(i,j,k), qsw, xl_arr(i,j,k), cpm_arr(i,j,k),
3321  Real(qmin), Real(rv));
3322  work2_arr(i,j,k) = qc_arr(i,j,k) + work1_arr(i,j,k,0);
3323 
3324  Real pcond = amrex::min(
3325  amrex::max(work1_arr(i,j,k,0) / dtcld, Real(0.0)),
3326  amrex::max(qv_arr(i,j,k), Real(0.0)) / dtcld);
3327  if (qc_arr(i,j,k) > Real(0.0) && work1_arr(i,j,k,0) < Real(0.0)) {
3328  pcond = amrex::max(work1_arr(i,j,k,0), -qc_arr(i,j,k)) / dtcld;
3329  }
3330  pcond_arr(i,j,k) = pcond;
3331 
3332  if (pcond == -qc_arr(i,j,k) / dtcld) {
3333  nn_arr(i,j,k) += nc_arr(i,j,k);
3334  nc_arr(i,j,k) = Real(0.0);
3335  }
3336 
3337  qv_arr(i,j,k) = amrex::max(qv_arr(i,j,k) - pcond * dtcld, Real(0.0));
3338  qc_arr(i,j,k) = amrex::max(qc_arr(i,j,k) + pcond * dtcld, Real(0.0));
3339  t_arr(i,j,k) += pcond * xl_arr(i,j,k) / cpm_arr(i,j,k) * dtcld;
3340  });
3341 
3342 
3343  const Real g17_pidnc = pi_wdm6_loc * Real(denr) / Real(6.0);
3344  const Real g17_pidnr = Real(4.0) * pi_wdm6_loc * Real(denr);
3345 
3346 
3347  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
3348  if (qc_arr(i,j,k) <= Real(qmin)) qc_arr(i,j,k) = Real(0.0);
3349  if (qi_arr(i,j,k) <= Real(qmin)) qi_arr(i,j,k) = Real(0.0);
3350 
3351  if (qr_arr(i,j,k) >= Real(qcrmin) && nr_arr(i,j,k) >= Real(nrmin)) {
3352  Real lamdr = std::exp(std::log(
3353  (g17_pidnr * nr_arr(i,j,k)) / (den_arr(i,j,k) * qr_arr(i,j,k))
3354  ) * wdm6_literal(0.33333333));
3355  if (lamdr <= Real(lamdarmin)) {
3356  lamdr = Real(lamdarmin);
3357  nr_arr(i,j,k) = den_arr(i,j,k) * qr_arr(i,j,k)
3358  * std::pow(lamdr, Real(3.0)) / g17_pidnr;
3359  } else if (lamdr >= Real(lamdarmax)) {
3360  lamdr = Real(lamdarmax);
3361  nr_arr(i,j,k) = den_arr(i,j,k) * qr_arr(i,j,k)
3362  * std::pow(lamdr, Real(3.0)) / g17_pidnr;
3363  }
3364  }
3365 
3366  if (qc_arr(i,j,k) >= Real(qmin) && nc_arr(i,j,k) >= Real(ncmin)) {
3367  Real lamdc = std::exp(std::log(
3368  (g17_pidnc * nc_arr(i,j,k)) / (den_arr(i,j,k) * qc_arr(i,j,k))
3369  ) * wdm6_literal(0.33333333));
3370  if (lamdc <= Real(lamdacmin)) {
3371  lamdc = Real(lamdacmin);
3372  nc_arr(i,j,k) = den_arr(i,j,k) * qc_arr(i,j,k)
3373  * std::pow(lamdc, Real(3.0)) / g17_pidnc;
3374  } else if (lamdc >= Real(lamdacmax)) {
3375  lamdc = Real(lamdacmax);
3376  nc_arr(i,j,k) = den_arr(i,j,k) * qc_arr(i,j,k)
3377  * std::pow(lamdc, Real(3.0)) / g17_pidnc;
3378  }
3379  }
3380  });
3381 
3382 
3383 
3384 
3385  } // End minor timestep loop
3386 
3387 
3388  // Convert updated temperature back to potential temperature, mirroring
3389  // the bridge leg above. Without this the native path left
3390  // mic_fab_vars[theta] at its pre-microphysics value while the bridge
3391  // leg advanced it, and Copy_Micro_to_State then formed
3392  // RhoTheta = rho * theta from the stale field, dropping microphysical
3393  // latent heating from the thermodynamic state. Confirmed by comparing
3394  // theta before and after the bridge call: native PRE theta equalled
3395  // POST theta at 100/100 levels, and the resulting
3396  // divergence 6.625510053 at k=90 matched the step-1 theta error exactly.
3397  {
3398  const Real configured_rdOcp = m_rdOcp;
3399  const bool use_anelastic_reference_pressure =
3401  ParallelFor(box, [=] AMREX_GPU_DEVICE (int i, int j, int k) {
3402  w1_theta(i,j,k) = wdm6_theta_from_temperature_and_pressure(
3403  t_arr(i,j,k), p_arr(i,j,k), configured_rdOcp,
3404  use_anelastic_reference_pressure);
3405  });
3406  }
3407 
3408 #ifdef ERF_USE_WDM6_FORT
3409  }
3410 #endif
3411 
3412  } // MFIter loop
3413 }
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_diffac(Real a, Real b, Real c, Real d, Real e, Real rv_arg)
Definition: ERF_AdvanceWDM6.cpp:64
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_xka(Real x, Real y)
Definition: ERF_AdvanceWDM6.cpp:59
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_venfac(Real a, Real b, Real c, Real den0_arg)
Definition: ERF_AdvanceWDM6.cpp:71
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void wdm6_nislfv_rain_plm6_column(int km, Real *precip1, Real *precip2, Real dt, int iter, Real pidn0s, Real pidn0g, Real qcrmin, Real alpha, Real n0smax, Real n0s, Real t0c, Real rslopesmax, Real rslopesbmax, Real rslopes2max, Real rslopes3max, Real bvts, Real pvts, Real rslopegmax, Real rslopegbmax, Real rslopeg2max, Real rslopeg3max, Real bvtg, Real pvtg, Array4< Real > const &sed_cell, Array4< Real > const &sed_node, int i_s, int j_s, int klo_s)
Definition: ERF_AdvanceWDM6.cpp:281
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_xlcal(Real x, Real xlv0_arg, Real xlv1_arg, Real t0c_arg)
Definition: ERF_AdvanceWDM6.cpp:35
constexpr amrex::Real wdm6_slope_t0c
Definition: ERF_AdvanceWDM6.cpp:199
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void wdm6_slope_rain_cell(Real qr, Real nr, Real den, Real denfac, Real qcrmin_arg, Real nrmin_arg, Real rslopermax_arg, Real rsloperbmax_arg, Real rsloper2max_arg, Real rsloper3max_arg, Real bvtr_arg, Real pvtr_arg, Real pvtrn_arg, Real pidnr_arg, Real &rslope, Real &rslopeb, Real &rslope2, Real &rslope3, Real &vt, Real &vtn)
Definition: ERF_AdvanceWDM6.cpp:141
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void wdm6_slope_snow_cell(Real qs, Real den, Real denfac, Real t, Real pidn0s_arg, Real alpha_arg, Real n0smax_arg, Real n0s_arg, Real t0c_arg, Real qcrmin_arg, Real rslopesmax_arg, Real rslopesbmax_arg, Real rslopes2max_arg, Real rslopes3max_arg, Real bvts_arg, Real pvts_arg, Real &rslope, Real &rslopeb, Real &rslope2, Real &rslope3, Real &vt, Real &n0sfac)
Definition: ERF_AdvanceWDM6.cpp:218
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_cpmcal(Real x, Real qmin_arg, Real cpd_arg, Real cpv_arg)
Definition: ERF_AdvanceWDM6.cpp:29
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_xni_exact(Real qi, Real den, Real qmin_arg)
Definition: ERF_AdvanceWDM6.cpp:134
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_default_real_pow(double base, double exponent)
Definition: ERF_AdvanceWDM6.cpp:40
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void wdm6_slope_graup_cell(Real qg, Real den, Real denfac, Real pidn0g_arg, Real qcrmin_arg, Real rslopegmax_arg, Real rslopegbmax_arg, Real rslopeg2max_arg, Real rslopeg3max_arg, Real bvtg_arg, Real pvtg_arg, Real &rslope, Real &rslopeb, Real &rslope2, Real &rslope3, Real &vt)
Definition: ERF_AdvanceWDM6.cpp:248
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_conden(Real a, Real b, Real c, Real d, Real e, Real qmin_arg, Real rv_arg)
Definition: ERF_AdvanceWDM6.cpp:80
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE Real wdm6_rslopec_exact(Real qc, Real den, Real nc, Real pidnc_arg)
Definition: ERF_AdvanceWDM6.cpp:123
constexpr amrex::Real R_v
Definition: ERF_Constants.H:50
constexpr amrex::Real Cp_d
Definition: ERF_Constants.H:51
constexpr amrex::Real CONST_GRAV
Definition: ERF_Constants.H:72
constexpr amrex::Real Cp_l
Definition: ERF_Constants.H:53
constexpr amrex::Real Cp_v
Definition: ERF_Constants.H:52
constexpr amrex::Real R_d
Definition: ERF_Constants.H:49
AMREX_ALWAYS_ASSERT_WITH_MESSAGE(axis >=0 &&axis< AMREX_SPACEDIM, "prob.axis must be 0, 1 or 2")
ParmParse pp("prob")
const int khi
Definition: ERF_InitCustomPert_Bubble.H:25
const int klo
Definition: ERF_InitCustomPert_KE.H:9
auto qv_arr
Definition: ERF_InitCustomPert_MultiSpeciesBubble.H:222
constexpr amrex::Real lat_vap
Definition: ERF_MicrophysicsConstants.H:113
constexpr amrex::Real lsub
Definition: ERF_MicrophysicsConstants.H:111
constexpr amrex::Real rhoh2o
Definition: ERF_MicrophysicsConstants.H:42
constexpr amrex::Real lat_ice
Definition: ERF_MicrophysicsConstants.H:114
constexpr amrex::Real rhos
Definition: ERF_MicrophysicsConstants.H:40
Arena * Arena_Used
Definition: ERF_Morrison_Advance_F.H:23
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
constexpr amrex::Real one
Definition: ERF_NumericalConstants.H:37
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE void sedimentation_add_column_sums(const amrex::Array4< amrex::Real > &sed, int n, int i, int j, int klo, int khi, amrex::Real sign, F &&w) noexcept
Definition: ERF_SedimentationFlux.H:74
amrex::Real Real
Definition: ERF_ShocInterface.H:19
AMREX_FORCE_INLINE amrex::IntVect TileNoZ()
Definition: ERF_TileNoZ.H:11
constexpr amrex::Real wdm6_literal(double d)
Definition: ERF_WDM6.H:98
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE amrex::Real wdm6_theta_from_temperature_and_pressure(const amrex::Real temperature, const amrex::Real pressure, const amrex::Real configured_rdOcp, const bool use_anelastic_reference_pressure) noexcept
Definition: ERF_WDM6.H:83
void mp_wdm6_run_c(double *t, double *qv, double *qc, double *qi, double *qr, double *qs, double *qg, double *nn, double *nc, double *nr, double *den, double *p, double *delz, double delt, double g, double cpd, double cpv, double rd, double rv, double t0c, double ep1, double ep2, double qmin, double xls, double xlv0, double xlf0, double den0, double denr, double cliq, double cice, double psat, double ccn0, double *xland, double *rain, double *rainncv, double *sr, double *snow, double *snowncv, double *graupel, double *graupelncv, double *rainonly, double *snowonly, int ims, int ime, int jms, int jme, int kms, int kme, int its, int ite, int jts, int jte, int kts, int kte, int microphysics_debug, int diag_i_dbg, int diag_j_dbg)
void mp_wdm6_init_c(double den0, double denr, double dens, double cl, double cpv, double ccn0, int hail_opt)
bool boxes_span_domain() const
True when every box spans the domain in z (required by the Fortran bridges)
Definition: ERF_MicrophysicsColumns.H:44
bool m_use_anelastic_reference_pressure
Definition: ERF_NullMoist.H:191
amrex::Real m_precs2
Definition: ERF_WDM6.H:336
static constexpr amrex::Real ncmin
Definition: ERF_WDM6.H:195
static constexpr amrex::Real qcrmin
Definition: ERF_WDM6.H:194
amrex::Real m_pidn0g
Definition: ERF_WDM6.H:340
amrex::Real m_precr2
Definition: ERF_WDM6.H:332
bool m_hail_opt
Definition: ERF_WDM6.H:319
static constexpr amrex::Real nrmin
Definition: ERF_WDM6.H:196
amrex::Real m_pvtrn
Definition: ERF_WDM6.H:331
amrex::Real m_rslopecmax
Definition: ERF_WDM6.H:341
static constexpr amrex::Real lamdarmax
Definition: ERF_WDM6.H:185
amrex::Real m_pidn0s
Definition: ERF_WDM6.H:337
amrex::Real m_qc1
Definition: ERF_WDM6.H:326
static constexpr amrex::Real di100
Definition: ERF_WDM6.H:208
amrex::Real m_pvts
Definition: ERF_WDM6.H:336
static constexpr amrex::Real pfrz1
Definition: ERF_WDM6.H:192
amrex::Real m_rslopec3max
Definition: ERF_WDM6.H:341
static constexpr amrex::Real dicon
Definition: ERF_WDM6.H:190
amrex::Real m_pvtr
Definition: ERF_WDM6.H:331
amrex::Real m_rslopegmax
Definition: ERF_WDM6.H:342
static constexpr amrex::Real bvtr
Definition: ERF_WDM6.H:176
amrex::Real m_rslopesmax
Definition: ERF_WDM6.H:342
amrex::Real m_pvtg
Definition: ERF_WDM6.H:340
static constexpr amrex::Real lamdacmax
Definition: ERF_WDM6.H:188
static constexpr amrex::Real alpha_wdm6
Definition: ERF_WDM6.H:202
amrex::Real m_pi_wdm6
Definition: ERF_WDM6.H:325
amrex::Real m_rslopes2max
Definition: ERF_WDM6.H:344
amrex::Real m_rslopegbmax
Definition: ERF_WDM6.H:343
amrex::Real m_rslopes3max
Definition: ERF_WDM6.H:345
amrex::Real m_qck1
Definition: ERF_WDM6.H:326
amrex::Real m_rdOcp
Definition: ERF_WDM6.H:300
static constexpr amrex::Real qs0
Definition: ERF_WDM6.H:199
amrex::Real m_rslopeg2max
Definition: ERF_WDM6.H:344
static constexpr amrex::Real n0s
Definition: ERF_WDM6.H:201
amrex::Real m_rslopesbmax
Definition: ERF_WDM6.H:343
amrex::Geometry m_geom
Definition: ERF_WDM6.H:293
static constexpr amrex::Real di2000
Definition: ERF_WDM6.H:210
amrex::Real m_precg1
Definition: ERF_WDM6.H:340
amrex::Real m_rsloperbmax
Definition: ERF_WDM6.H:343
amrex::Real m_precr1
Definition: ERF_WDM6.H:332
static constexpr amrex::Real di82
Definition: ERF_WDM6.H:211
amrex::Real m_g7pbr
Definition: ERF_WDM6.H:329
static constexpr amrex::Real actr
Definition: ERF_WDM6.H:205
static constexpr amrex::Real lamdarmin
Definition: ERF_WDM6.H:186
static constexpr amrex::Real lamdacmin
Definition: ERF_WDM6.H:189
amrex::Real m_ccn0
Definition: ERF_WDM6.H:296
amrex::Real m_pidnc
Definition: ERF_WDM6.H:326
amrex::Real m_qc0
Definition: ERF_WDM6.H:326
amrex::Real m_bvtg
Definition: ERF_WDM6.H:320
amrex::Real m_rsloper3max
Definition: ERF_WDM6.H:345
amrex::Real m_rslopeg3max
Definition: ERF_WDM6.H:345
amrex::Real m_pidnr
Definition: ERF_WDM6.H:333
amrex::Real m_g4pbr
Definition: ERF_WDM6.H:329
static constexpr amrex::Real bvts
Definition: ERF_WDM6.H:184
amrex::Real m_n0g
Definition: ERF_WDM6.H:320
static constexpr amrex::Real di600
Definition: ERF_WDM6.H:209
amrex::Real m_precg2
Definition: ERF_WDM6.H:340
amrex::Real m_rslopermax
Definition: ERF_WDM6.H:342
static constexpr amrex::Real ncrk2
Definition: ERF_WDM6.H:207
amrex::Real m_xlv1
Definition: ERF_WDM6.H:325
amrex::Real m_pacrg
Definition: ERF_WDM6.H:340
static constexpr amrex::Real ncrk1
Definition: ERF_WDM6.H:206
static constexpr amrex::Real avtr
Definition: ERF_WDM6.H:175
amrex::Real m_pacrc
Definition: ERF_WDM6.H:337
amrex::Real m_roqimax
Definition: ERF_WDM6.H:332
static constexpr amrex::Real dimax
Definition: ERF_WDM6.H:191
static constexpr amrex::Real actk
Definition: ERF_WDM6.H:204
static constexpr amrex::Real pfrz2
Definition: ERF_WDM6.H:193
amrex::Real m_precs1
Definition: ERF_WDM6.H:336
static constexpr amrex::Real satmax
Definition: ERF_WDM6.H:203
static constexpr amrex::Real n0smax
Definition: ERF_WDM6.H:200
amrex::Real m_rsloper2max
Definition: ERF_WDM6.H:344
amrex::Real m_rslopec2max
Definition: ERF_WDM6.H:341
@ xlf
Definition: ERF_AdvanceMorrison.cpp:159
@ qr
Definition: ERF_WDM6.H:30
@ qv
Definition: ERF_WDM6.H:27
@ qc
Definition: ERF_WDM6.H:28
@ qi
Definition: ERF_WDM6.H:29
@ rain_accum
Definition: ERF_WDM6.H:36
@ pres
Definition: ERF_WDM6.H:26
@ nr
Definition: ERF_WDM6.H:35
@ graupel_accum
Definition: ERF_WDM6.H:38
@ qg
Definition: ERF_WDM6.H:32
@ theta
Definition: ERF_WDM6.H:24
@ qs
Definition: ERF_WDM6.H:31
@ nc
Definition: ERF_WDM6.H:34
@ precip_accum
Definition: ERF_WDM6.H:39
@ nn
Definition: ERF_WDM6.H:33
@ rho
Definition: ERF_WDM6.H:23
@ tabs
Definition: ERF_WDM6.H:25
@ snow_accum
Definition: ERF_WDM6.H:37
@ tk
Definition: ERF_AdvanceWDM6.cpp:273
@ work_col
Definition: ERF_AdvanceWDM6.cpp:273
@ den
Definition: ERF_AdvanceWDM6.cpp:273
@ denfac
Definition: ERF_AdvanceWDM6.cpp:273
@ rq2_col
Definition: ERF_AdvanceWDM6.cpp:273
@ rq_col
Definition: ERF_AdvanceWDM6.cpp:273
@ NumComps
Definition: ERF_AdvanceWDM6.cpp:273
@ dz
Definition: ERF_AdvanceWDM6.cpp:273
@ NumComps
Definition: ERF_AdvanceWDM6.cpp:277
@ qr
Definition: ERF_WDM6.H:112
@ qs
Definition: ERF_WDM6.H:112
@ nr
Definition: ERF_WDM6.H:112
@ NumComps
Definition: ERF_WDM6.H:112
@ qg
Definition: ERF_WDM6.H:112
@ qi
Definition: ERF_WDM6.H:112
@ fall_s
Definition: ERF_WSM6.H:368
@ n0sfac
Definition: ERF_WSM6.H:354
@ work2
Definition: ERF_WSM6.H:347
@ pcond
Definition: ERF_WSM6.H:317
@ qsum
Definition: ERF_WSM6.H:344
@ psmlt
Definition: ERF_WSM6.H:338
@ fall_g
Definition: ERF_WSM6.H:368
@ work1c
Definition: ERF_WSM6.H:307
@ pgmlt
Definition: ERF_WSM6.H:339
@ rhi
Definition: ERF_WSM6.H:360
@ fall_r
Definition: ERF_WSM6.H:368
@ xni
Definition: ERF_WSM6.H:349
real(c_double), parameter cice
Definition: ERF_module_model_constants.F90:30
real(c_double), parameter g
Definition: ERF_module_model_constants.F90:19
real(c_double), parameter cliq
Definition: ERF_module_model_constants.F90:29
real(c_double), parameter xlv0
Definition: ERF_module_model_constants.F90:51
real(c_double), parameter cpv
Definition: ERF_module_model_constants.F90:26
real(c_double), parameter xls
Definition: ERF_module_model_constants.F90:56
real(c_double), parameter psat
Definition: ERF_module_model_constants.F90:31
real(kind=kind_phys), parameter, private dens
Definition: ERF_module_mp_wdm6.F90:61
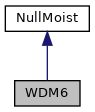
Here is the call graph for this function:

◆ Copy_Micro_to_State()

void WDM6::Copy_Micro_to_State ( amrex::MultiFab &  cons_in)
overridevirtual

Reimplemented from NullMoist.

10 {
11  // Conservative update of all fields
12  for (MFIter mfi(cons, TilingIfNotGPU()); mfi.isValid(); ++mfi)
13  {
14  const auto& box3d = mfi.tilebox();
15  auto states = cons.array(mfi);
16 
17  const auto& rho = mic_fab_vars[MicVar_WDM6::rho]->array(mfi);
18  const auto& theta = mic_fab_vars[MicVar_WDM6::theta]->array(mfi);
19  const auto& qv = mic_fab_vars[MicVar_WDM6::qv]->array(mfi);
20  const auto& qc = mic_fab_vars[MicVar_WDM6::qc]->array(mfi);
21  const auto& qi = mic_fab_vars[MicVar_WDM6::qi]->array(mfi);
22  const auto& qr = mic_fab_vars[MicVar_WDM6::qr]->array(mfi);
23  const auto& qs = mic_fab_vars[MicVar_WDM6::qs]->array(mfi);
24  const auto& qg = mic_fab_vars[MicVar_WDM6::qg]->array(mfi);
25  const auto& nn = mic_fab_vars[MicVar_WDM6::nn]->array(mfi);
26  const auto& nc = mic_fab_vars[MicVar_WDM6::nc]->array(mfi);
27  const auto& nr = mic_fab_vars[MicVar_WDM6::nr]->array(mfi);
28 
29  ParallelFor(box3d, [=] AMREX_GPU_DEVICE(int i, int j, int k) noexcept
30  {
31  states(i,j,k,RhoTheta_comp) = rho(i,j,k) * theta(i,j,k);
32 
33  states(i,j,k,RhoQ1_comp) = rho(i,j,k) * amrex::max(Real(0), qv(i,j,k));
34  states(i,j,k,RhoQ2_comp) = rho(i,j,k) * amrex::max(Real(0), qc(i,j,k));
35  states(i,j,k,RhoQ3_comp) = rho(i,j,k) * amrex::max(Real(0), qi(i,j,k));
36  states(i,j,k,RhoQ4_comp) = rho(i,j,k) * amrex::max(Real(0), qr(i,j,k));
37  states(i,j,k,RhoQ5_comp) = rho(i,j,k) * amrex::max(Real(0), qs(i,j,k));
38  states(i,j,k,RhoQ6_comp) = rho(i,j,k) * amrex::max(Real(0), qg(i,j,k));
39 
40  // Number concentrations
41  states(i,j,k,RhoQ7_comp) = rho(i,j,k) * amrex::max(Real(0), nc(i,j,k));
42  states(i,j,k,RhoQ8_comp) = rho(i,j,k) * amrex::max(Real(0), nn(i,j,k));
43  states(i,j,k,RhoQ9_comp) = rho(i,j,k) * amrex::max(Real(0), nr(i,j,k));
44  });
45  }
46 
47  // No nn bookkeeping needed here. Copy_State_to_Micro decides per cell from
48  // the state itself, so once RhoQ8 has been written by the copyback above it
49  // is read back like any other variable.
50 
51  cons.FillBoundary(m_geom.periodicity());
52 }
#define RhoQ4_comp
Definition: ERF_IndexDefines.H:69
#define RhoTheta_comp
Definition: ERF_IndexDefines.H:54
#define RhoQ2_comp
Definition: ERF_IndexDefines.H:67
#define RhoQ3_comp
Definition: ERF_IndexDefines.H:68
#define RhoQ9_comp
Definition: ERF_IndexDefines.H:74
#define RhoQ1_comp
Definition: ERF_IndexDefines.H:66
#define RhoQ6_comp
Definition: ERF_IndexDefines.H:71
#define RhoQ8_comp
Definition: ERF_IndexDefines.H:73
#define RhoQ5_comp
Definition: ERF_IndexDefines.H:70
#define RhoQ7_comp
Definition: ERF_IndexDefines.H:72
@ rho
Definition: ERF_Kessler.H:25
@ theta
Definition: ERF_Kessler.H:26
@ qv
Definition: ERF_Kessler.H:31
@ nc
Definition: ERF_Morrison.H:47
@ nr
Definition: ERF_Morrison.H:48
@ qg
Definition: ERF_Morrison.H:114
@ qr
Definition: ERF_Morrison.H:112
@ qi
Definition: ERF_Morrison.H:111
@ qs
Definition: ERF_Morrison.H:113
@ qc
Definition: ERF_Morrison.H:110
@ cons
Definition: ERF_IndexDefines.H:254

Referenced by Update_State_Vars().

Here is the call graph for this function:
Here is the caller graph for this function:

◆ Copy_State_to_Micro() [1/2]

void WDM6::Copy_State_to_Micro ( const amrex::MultiFab &  cons_in)
overridevirtual

Reimplemented from NullMoist.

Referenced by Update_Micro_Vars().

Here is the caller graph for this function:

◆ Copy_State_to_Micro() [2/2]

void WDM6::Copy_State_to_Micro ( const amrex::MultiFab &  cons_in,
const amrex::MultiFab *  base_state 
)

◆ Define()

void WDM6::Define ( SolverChoice &  sc)
inlineoverridevirtual

Reimplemented from NullMoist.

123  {
125  m_rdOcp = sc.rdOcp;
127  m_axis = sc.ave_plane;
128  m_do_cond = (!sc.uses_shoc_family());
129  }
void set_anelastic_reference_pressure_mode(const SolverChoice &sc)
Definition: ERF_NullMoist.H:171
int m_axis
Definition: ERF_WDM6.H:298
MoistureType m_moisture_type
Definition: ERF_WDM6.H:301
bool m_do_cond
Definition: ERF_WDM6.H:299
MoistureType moisture_type
Moisture or microphysics model.
Definition: ERF_DataStruct.H:2942
int ave_plane
Averaging plane index used by diagnostics.
Definition: ERF_DataStruct.H:2990
amrex::Real rdOcp
Ratio of dry-air gas constant to c_p.
Definition: ERF_DataStruct.H:2738
bool uses_shoc_family() const noexcept
Query whether any SHOC-family PBL scheme is active.
Definition: ERF_DataStruct.H:2864
Here is the call graph for this function:

◆ Get_Surface_Precip_Accumulation_Ptrs()

SurfacePrecipAccumulationSources WDM6::Get_Surface_Precip_Accumulation_Ptrs ( const int &  ) const
inlineoverridevirtual

Reimplemented from NullMoist.

272  {
274  sources.total = {mic_fab_vars[MicVar_WDM6::precip_accum].get(), rhoh2o / amrex::Real(1000.0)};
275  sources.rain = {mic_fab_vars[MicVar_WDM6::rain_accum].get(), rhoh2o / amrex::Real(1000.0)};
276  sources.snow = {mic_fab_vars[MicVar_WDM6::snow_accum].get(), rhoh2o / amrex::Real(1000.0)};
277  sources.graupel = {mic_fab_vars[MicVar_WDM6::graupel_accum].get(), rhoh2o / amrex::Real(1000.0)};
278  return sources;
279  }
Definition: ERF_SurfacePrecipitation.H:34
SurfacePrecipAccumulationSource rain
Definition: ERF_SurfacePrecipitation.H:36
SurfacePrecipAccumulationSource snow
Definition: ERF_SurfacePrecipitation.H:37
SurfacePrecipAccumulationSource total
Definition: ERF_SurfacePrecipitation.H:35
SurfacePrecipAccumulationSource graupel
Definition: ERF_SurfacePrecipitation.H:38

◆ Init()

void WDM6::Init ( const amrex::MultiFab &  cons_in,
const amrex::BoxArray &  grids,
const amrex::Geometry &  geom,
const amrex::Real &  dt_advance,
std::unique_ptr< amrex::MultiFab > &  z_phys_nd,
std::unique_ptr< amrex::MultiFab > &  detJ_cc 
)
overridevirtual

Reimplemented from NullMoist.

17 {
18  dt = dt_advance;
19  m_geom = geom;
20 
21  m_z_phys_nd = z_phys_nd.get();
22  m_detJ_cc = detJ_cc.get();
23 
24  m_columns.define(cons_in.boxArray(), geom.Domain());
25 
26  // Read CCN concentration from input
27  amrex::ParmParse pp("wdm6");
28  pp.queryAdd("ccn0", m_ccn0); // default 100.0e6 m^-3
29 
30  // Graupel/hail regime selector. The Fortran gates on `hail_opt .eq. 1`
31  // (ERF_module_mp_wdm6.F90:3259), so every value other than 1 selects the
32  // graupel branch; the bool below reproduces that test exactly rather than
33  // inventing a stricter 0/1 validation the Fortran does not perform.
34  // Must be resolved before initialize_coeffs(), which branches on it.
35  int hail_opt_in = 0;
36  pp.queryAdd("hail_opt", hail_opt_in); // default 0 = graupel
37  m_hail_opt = (hail_opt_in == 1);
38 
39  amrex::Print() << "WDM6 Initialization: CCN0 = " << m_ccn0 << " #/m^3"
40  << ", hail_opt = " << (m_hail_opt ? 1 : 0)
41  << (m_hail_opt ? " (hail)" : " (graupel)") << "\n";
42 
43  MicVarMap.resize(m_qmoist_size);
46 
47  // Select appropriate Arena based on execution mode
48  // - Fortran bridge + GPU: Use managed memory for CPU (Fortran) ↔ GPU data transfer
49  // - Fortran bridge CPU-only: Use pinned memory for CPU efficiency
50  // - C++ GPU kernels: Use standard device memory
51 #if defined(ERF_USE_WDM6_FORT) && defined(AMREX_USE_GPU)
52  Arena* Arena_Used = The_Managed_Arena();
53 #elif defined(ERF_USE_WDM6_FORT)
54  Arena* Arena_Used = The_Pinned_Arena();
55 #else
56  Arena* Arena_Used = The_Arena();
57 #endif
58 
59  for (int ivar = 0; ivar < MicVar_WDM6::NumVars; ++ivar) {
60  mic_fab_vars[ivar] = std::make_shared<MultiFab>(cons_in.boxArray(), cons_in.DistributionMap(),
61  1, cons_in.nGrowVect(),
62  MFInfo().SetArena(Arena_Used));
63  mic_fab_vars[ivar]->setVal(0.0);
64  }
65 
66  m_sed.define(cons_in.boxArray(), cons_in.DistributionMap(),
67  {RhoQ3_comp, RhoQ4_comp, RhoQ5_comp, RhoQ6_comp, RhoQ9_comp});
68 
69  // Initialize nn to ccn0 / rho (matches WRF itimestep==1 behavior)
70  // This must be done here so nn is available before the first microphysics call
71  // NOTE: Can't write to cons_in (it's const), so only initialize mic_fab_vars.
72  // Copy_Micro_to_State will write it back to state after the first microphysics call.
73  // IMPORTANT: Use growntilebox to include ghost zones, since Copy_State_to_Micro will
74  // skip reading nn and expect it to be initialized everywhere.
75  // nn is NOT seeded here. The Fortran seeds it inside the per-step driver
76  // wdm6 (:219), immediately before the kernel, not in wdm6init, so the
77  // faithful ERF home is Copy_State_to_Micro, which is the per-step pack.
78  // Seeding here instead was also wrong on restart: Init runs again on a
79  // restart, so it discarded the checkpoint's evolved RhoQ8 and the first
80  // Copy_State_to_Micro kept the uniform background. See the state-based
81  // seeding in Copy_State_to_Micro below for the condition and its rationale.
82 
83  nlev = m_geom.Domain().length(2);
84  zlo = m_geom.Domain().smallEnd(2);
85  zhi = m_geom.Domain().bigEnd(2);
86 
88 }
void define(const amrex::BoxArray &ba, const amrex::Box &domain)
Build from a level's grids; call from the scheme's Init (which also runs on regrid)
Definition: ERF_MicrophysicsColumns.cpp:9
int nlev
Definition: ERF_WDM6.H:297
amrex::Real dt
Definition: ERF_WDM6.H:294
int m_qmoist_size
Definition: ERF_WDM6.H:287
amrex::Vector< int > MicVarMap
Definition: ERF_WDM6.H:291
amrex::MultiFab * m_detJ_cc
Definition: ERF_WDM6.H:304
int zlo
Definition: ERF_WDM6.H:297
int zhi
Definition: ERF_WDM6.H:297
void initialize_coeffs()
Definition: ERF_InitWDM6.cpp:176
@ NumVars
Definition: ERF_WDM6.H:40
void define(const amrex::BoxArray &cc_ba, const amrex::DistributionMapping &dm, const amrex::Vector< int > &a_cons_comp)
Definition: ERF_SedimentationFlux.H:43
Here is the call graph for this function:

◆ initialize_coeffs()

void WDM6::initialize_coeffs ( )
private
177 {
178  using amrex::Real;
179 
180  // Exact port of Fortran rgmma() function from WSM6
181  auto rgmma = [](Real x) -> Real {
182  if (x == Real(1.0)) return Real(0.0);
183  constexpr Real euler = Real(0.577215664901532);
184  Real result = x * std::exp(euler * x);
185  for (int i = 1; i <= 10000; ++i) {
186  Real y = Real(i);
187  result = result * (Real(1.0) + x/y) * std::exp(-x/y);
188  }
189  return Real(1.0) / result;
190  };
191 
192  // Physical constants
193  const Real den0 = Real(1.28);
194  const Real denr = Real(rhoh2o);
195  const Real dens_arg = dens_snow;
196  const Real cl = Real(Cp_l);
197  const Real cpv_loc = Real(Cp_v);
198 
199  // hail_opt branch
200  if (m_hail_opt) {
201  m_n0g = Real(4.0e4);
202  m_deng = Real(700.0);
203  m_avtg = Real(285.0);
204  m_bvtg = wdm6_literal(0.8);
205  m_lamdagmax = Real(2.0e4);
206  } else {
207  m_n0g = Real(4.0e6);
208  m_deng = Real(500.0);
209  m_avtg = Real(330.0);
210  m_bvtg = wdm6_literal(0.8);
211  m_lamdagmax = Real(6.0e4);
212  }
213 
214  // LITERAL PRECISION CONTRACT, second hazard class. The Fortran writes
215  // pi = 4.*atan(1.)
216  // at ERF_module_mp_wdm6.F90:3111. Neither literal carries a kind suffix, so
217  // `1.` is a default REAL and the generic ATAN resolves to its SINGLE
218  // precision specific; the whole expression is evaluated in float32 and only
219  // then widened to kind_phys. Measured with gfortran:
220  // 4.*atan(1.) = 3.14159274101257324219
221  // 4._kp*atan(1._kp) = 3.14159265358979311600
222  // relative difference = 2.7828e-08
223  // This is distinct from the unsuffixed-parameter hazard the contract already
224  // covers: nothing here is a rounded constant, it is an intrinsic whose result
225  // kind is chosen by its argument kind. pi is load-bearing -- it feeds pidn0s,
226  // pidnc, pidnr, pidn0r, pidn0s, pidn0g, pacrs, pacrc and the pi*pi in G10c's
227  // pfrzdtc -- so the error propagates broadly.
228  // Routed through wdm6_literal like every other constant: it is constexpr but
229  // not restricted to constant expressions, so it applies the same rounding to
230  // a runtime value. Do not re-expand the toggle inline here; the contract is
231  // that ERF_WDM6_F32_LITERALS is honoured in exactly one place.
232  m_pi_wdm6 = wdm6_literal(Real(4.0) * std::atan(Real(1.0)));
233  m_xlv1 = cl - cpv_loc;
234 
235  // Cloud droplet parameters. The Fortran, ERF_module_mp_wdm6.F90:3114-3116:
236  // qc0 = 4./3.*pi*denr*r0**3.*xncr0/den0
237  // qc1 = 4./3.*pi*denr*r0**3.*xncr1/den0
238  // qck1 = .104*9.8*peaut/(denr)**(1./3.)/xmyu*den0**(4./3.)
239  // qc0 takes xncr0 and qc1 takes xncr1, unconditionally: the maritime versus
240  // continental choice is made downstream by the slmsk branch that sets
241  // qcr = qc0 or qc1 (:628-632), not here. The previous code used xncr for qc0
242  // and a ccn0-dependent xncr_use for qc1, so with the default ccn0 = 1.0e8 it
243  // selected xncr0 for BOTH.
244  //
245  // qck1 is the consequential one. WDM6 divides by denr**(1./3.) alone; the
246  // previous code divided by (xncr*denr)**(1./3.), which is the WSM6 form at
247  // ERF_module_mp_wsm6.F90:105. WSM6 is single-moment and folds its fixed
248  // droplet number xncr into qck1; WDM6 is double-moment and already carries
249  // number explicitly as ncr(:,:,2)**(-1./3.) in praut, so the WSM6 form
250  // double-counts it. The error is exactly xncr**(1./3.) = (3.0e8)**(1/3) =
251  // 669.4, and praut and nraut were both measured low by that factor at
252  // (199,3,43) from bitwise-equal inputs.
253  m_qc0 = wdm6_literal(4.0/3.0) * m_pi_wdm6 * denr
254  * std::pow(r0, Real(3.0)) * xncr0 / den0;
255  m_qc1 = wdm6_literal(4.0/3.0) * m_pi_wdm6 * denr
256  * std::pow(r0, Real(3.0)) * xncr1 / den0;
257  // A FOURTH HAZARD CLASS under the literal precision contract: the float
258  // assumptions apply to the whole literal PRODUCT, not merely to each
259  // literal. In the Fortran, .104 and 9.8 are both default REAL, so
260  // `.104*9.8` is itself a default-REAL expression and the PRODUCT is
261  // evaluated in single precision before anything widens it:
262  // float32(float32(.104)*float32(9.8)) = 1.01920008659362792969
263  // Applying the float assumption to each operand separately and then
264  // multiplying performs the product in double:
265  // float32(.104)*float32(9.8) = 1.01920004086494486728
266  // a 4.486723e-08 relative difference. It lands on qck1 as a constant
267  // multiplicative factor, so praut carries exactly that relative error at
268  // every k, and nraut = 3.5e9*den*praut inherits it unchanged.
269  //
270  // Proven by reconstruction at clean SHA ac1e445fa from bitwise-equal
271  // PRE_G13A inputs, no Tier 2 instrumentation: of 61 live G13a cells across
272  // columns (108,3) and (199,3) over two steps, 59 reproduce BOTH legs'
273  // printed praut bitwise to 20 digits from the two qck1 variants; the other
274  // 2 are cells where the min(praut, qc/dtcld) clamp binds and the legs
275  // already agree bitwise.
276  //
277  // The nesting is load-bearing. wdm6_literal(0.104 * 9.8) is NOT equivalent
278  // and is worse at 1.169636e-07: it rounds the double product, whereas the
279  // Fortran rounds the product of already-rounded operands. Round the
280  // operands first, then round their product. Under Option B the helper is
281  // the identity, so this collapses to 0.104*9.8 in double, which is what
282  // -fdefault-real-8 gives on the Fortran side.
284  / std::pow(denr, wdm6_literal(1.0/3.0))
285  / xmyu * std::pow(den0, wdm6_literal(4.0/3.0));
286  m_pidnc = m_pi_wdm6 * denr / Real(6.0);
287 
288  // Rain coefficients
289  m_bvtr1 = Real(1.0) + bvtr;
290  m_bvtr2 = Real(2.0) + bvtr;
291  m_bvtr3 = Real(3.0) + bvtr;
292  m_bvtr4 = Real(4.0) + bvtr;
293  m_bvtr5 = Real(5.0) + bvtr;
294  m_bvtr6 = Real(6.0) + bvtr;
295  m_bvtr7 = Real(7.0) + bvtr;
296  m_bvtr2o5 = Real(2.5) + Real(0.5) * bvtr;
297  m_bvtr3o5 = Real(3.5) + Real(0.5) * bvtr;
298 
299  m_g1pbr = rgmma(m_bvtr1);
300  m_g2pbr = rgmma(m_bvtr2);
301  m_g3pbr = rgmma(m_bvtr3);
302  m_g4pbr = rgmma(m_bvtr4);
303  m_g5pbr = rgmma(m_bvtr5);
304  m_g6pbr = rgmma(m_bvtr6);
305  m_g7pbr = rgmma(m_bvtr7);
308 
309  m_pvtr = avtr * m_g5pbr / Real(24.0);
310  m_pvtrn = avtr * m_g2pbr;
311  m_eacrr = Real(1.0);
312  m_pacrr = m_pi_wdm6 * n0r * avtr * m_g3pbr * Real(0.25) * m_eacrr;
313  // Fortran WDM6 :3200-3201
314  // precr1 = 2.*pi*1.56
315  // precr2 = 2.*pi*.31*avtr**.5*g7pbro2
316  // NEITHER carries n0r. WSM6 :121-122 does -- precr1 = 2.*pi*n0r*.78 and
317  // precr2 = 2.*pi*n0r*.31*avtr**.5*g5pbro2 -- for the same reason qck1
318  // differs between the schemes: WSM6 is single-moment and folds the fixed
319  // intercept n0r into its coefficients, while WDM6 is double-moment and
320  // multiplies by ncr(:,:,3) explicitly at the use site in prevp. precr1 had
321  // already been ported from the WDM6 form; precr2 kept WSM6's n0r, making it
322  // 8.0e6 times too large. That drove the raw prevp far enough negative to
323  // hit its satdt/2 clamp on the native leg only: at (103,3,34) on step 3 the
324  // bridge held prevp at -8.3286e-09 while the native leg sat exactly on the
325  // clamp at -2.5824185419052320E-06, 310x larger.
326  m_precr1 = wdm6_literal(2.0) * m_pi_wdm6 * wdm6_literal(1.56);
328  * std::pow(avtr, wdm6_literal(0.5)) * m_g7pbro2;
329  // Fortran: roqimax = 2.08e22*dimax**8
330  // Two mismatches, both confirmed against the Tier 2 psaut trace:
331  // - 2.08e22 is unsuffixed there, so it is float32-rounded before being
332  // promoted. Route it through wdm6_literal so it follows the same
333  // switch as the ERF_WDM6.H constants.
334  // - dimax**8 has an INTEGER exponent, which gfortran expands to repeated
335  // multiplication, not a libm pow call. Written as explicit squaring
336  // here so the two sides agree structurally rather than by luck. For
337  // this value the two routes happen to agree bitwise, but that is not
338  // guaranteed in general and should not be relied on.
339  {
340  const Real d2 = dimax * dimax;
341  const Real d4 = d2 * d2;
342  m_roqimax = wdm6_literal(2.08e22) * (d4 * d4);
343  }
344  // Fortran: xmmax = (dimax/dicon)**2, again an integer exponent.
345  {
346  const Real r = dimax / dicon;
347  m_xmmax = r * r;
348  }
349 
350  m_pidn0r = m_pi_wdm6 * denr * n0r;
351  m_pidnr = Real(4.0) * m_pi_wdm6 * denr;
352 
353  // Snow coefficients
354  m_bvts1 = Real(1.0) + bvts;
355  m_bvts2 = Real(2.5) + Real(0.5) * bvts;
356  m_bvts3 = Real(3.0) + bvts;
357  m_bvts4 = Real(4.0) + bvts;
358  m_g1pbs = rgmma(m_bvts1);
359  m_g3pbs = rgmma(m_bvts3);
360  m_g4pbs = rgmma(m_bvts4);
362  m_pvts = avts * m_g4pbs / Real(6.0);
363  m_pacrs = m_pi_wdm6 * n0s * avts * m_g3pbs * Real(0.25);
364  // Fortran :3248-3249
365  // precs1 = 4.*n0s*.65
366  // precs2 = 4.*n0s*.44*avts**.5*g5pbso2
367  // .65 and .44 are unsuffixed so they carry the float assumption; 4. and
368  // avts**.5 are binary-exact and need no routing. Proven at Tier 2 on the
369  // G13E psdep decomposition at (199,3), k=85..98: coeres, rh-1 and work1
370  // are all bitwise, precs1 diverged exactly 3.667978e-08 and precs2 exactly
371  // 5.418604e-09, matching float32(.65) and float32(.44), and psdep's
372  // 2.523449e-08 is the term-weighted mix of the two.
373  m_precs1 = Real(4.0) * n0s * wdm6_literal(0.65);
374  m_precs2 = Real(4.0) * n0s * wdm6_literal(0.44)
375  * std::pow(avts, Real(0.5)) * m_g5pbso2;
376  m_pidn0s = m_pi_wdm6 * dens_arg * n0s;
377  m_pacrc = m_pi_wdm6 * n0s * avts * m_g3pbs * Real(0.25) * eacrc;
378 
379  // Graupel/hail coefficients
380  m_bvtg1 = Real(1.0) + m_bvtg;
381  m_bvtg2 = Real(2.5) + Real(0.5) * m_bvtg;
382  m_bvtg3 = Real(3.0) + m_bvtg;
383  m_bvtg4 = Real(4.0) + m_bvtg;
384  m_g1pbg = rgmma(m_bvtg1);
385  m_g3pbg = rgmma(m_bvtg3);
386  m_g4pbg = rgmma(m_bvtg4);
387  m_pacrg = m_pi_wdm6 * m_n0g * m_avtg * m_g3pbg * Real(0.25);
389  m_pvtg = m_avtg * m_g4pbg / Real(6.0);
390  // Fortran :3264-3265, the graupel analogues of precs1/precs2 with the same
391  // unsuffixed .78 and .31. Routed on the same evidence class as precs1 and
392  // precs2 rather than on separate measurements: pgdep reads bitwise in the
393  // current column only because its branch is inactive there.
394  m_precg1 = Real(2.0) * m_pi_wdm6 * m_n0g * wdm6_literal(0.78);
395  m_precg2 = Real(2.0) * m_pi_wdm6 * m_n0g * wdm6_literal(0.31)
396  * std::pow(m_avtg, Real(0.5)) * m_g5pbgo2;
398 
399  // Slope parameter limits
400  m_rslopecmax = Real(1.0) / lamdacmax;
403 
404  m_rslopermax = Real(1.0) / lamdarmax;
405  m_rslopesmax = Real(1.0) / lamdasmax;
406  m_rslopegmax = Real(1.0) / m_lamdagmax;
407  m_rsloperbmax = std::pow(m_rslopermax, bvtr);
408  m_rslopesbmax = std::pow(m_rslopesmax, bvts);
409  m_rslopegbmax = std::pow(m_rslopegmax, m_bvtg);
416 }
amrex::Real m_g5pbro2
Definition: ERF_WDM6.H:330
amrex::Real m_bvtg1
Definition: ERF_WDM6.H:338
static constexpr amrex::Real n0r
Definition: ERF_WDM6.H:174
amrex::Real m_bvtr3o5
Definition: ERF_WDM6.H:328
amrex::Real m_g5pbr
Definition: ERF_WDM6.H:329
amrex::Real m_g3pbs
Definition: ERF_WDM6.H:335
amrex::Real m_pacrs
Definition: ERF_WDM6.H:336
static constexpr amrex::Real eacrc
Definition: ERF_WDM6.H:197
amrex::Real m_bvtg4
Definition: ERF_WDM6.H:338
amrex::Real m_bvtr7
Definition: ERF_WDM6.H:327
amrex::Real m_bvtr3
Definition: ERF_WDM6.H:327
amrex::Real m_pidn0r
Definition: ERF_WDM6.H:333
static constexpr amrex::Real avts
Definition: ERF_WDM6.H:183
static constexpr amrex::Real xmyu
Definition: ERF_WDM6.H:182
amrex::Real m_bvtr1
Definition: ERF_WDM6.H:327
amrex::Real m_g1pbs
Definition: ERF_WDM6.H:335
amrex::Real m_bvtg3
Definition: ERF_WDM6.H:338
amrex::Real m_bvtr2o5
Definition: ERF_WDM6.H:328
amrex::Real m_avtg
Definition: ERF_WDM6.H:320
amrex::Real m_g3pbg
Definition: ERF_WDM6.H:339
amrex::Real m_bvts1
Definition: ERF_WDM6.H:334
static constexpr amrex::Real dens_snow
Definition: ERF_WDM6.H:198
amrex::Real m_g1pbg
Definition: ERF_WDM6.H:339
amrex::Real m_pacrr
Definition: ERF_WDM6.H:331
static constexpr amrex::Real r0
Definition: ERF_WDM6.H:177
amrex::Real m_g5pbgo2
Definition: ERF_WDM6.H:339
amrex::Real m_g4pbs
Definition: ERF_WDM6.H:335
amrex::Real m_g3pbr
Definition: ERF_WDM6.H:329
static constexpr amrex::Real lamdasmax
Definition: ERF_WDM6.H:187
amrex::Real m_bvtr2
Definition: ERF_WDM6.H:327
static constexpr amrex::Real xncr0
Definition: ERF_WDM6.H:180
static constexpr amrex::Real peaut
Definition: ERF_WDM6.H:178
amrex::Real m_bvtr6
Definition: ERF_WDM6.H:327
amrex::Real m_g6pbr
Definition: ERF_WDM6.H:329
static constexpr amrex::Real xncr1
Definition: ERF_WDM6.H:181
amrex::Real m_bvts4
Definition: ERF_WDM6.H:334
amrex::Real m_lamdagmax
Definition: ERF_WDM6.H:320
amrex::Real m_g1pbr
Definition: ERF_WDM6.H:329
amrex::Real m_g2pbr
Definition: ERF_WDM6.H:329
amrex::Real m_bvts3
Definition: ERF_WDM6.H:334
amrex::Real m_bvtr5
Definition: ERF_WDM6.H:327
amrex::Real m_xmmax
Definition: ERF_WDM6.H:332
amrex::Real m_bvtr4
Definition: ERF_WDM6.H:327
amrex::Real m_bvtg2
Definition: ERF_WDM6.H:338
amrex::Real m_g5pbso2
Definition: ERF_WDM6.H:335
amrex::Real m_g4pbg
Definition: ERF_WDM6.H:339
amrex::Real m_deng
Definition: ERF_WDM6.H:320
amrex::Real m_eacrr
Definition: ERF_WDM6.H:331
amrex::Real m_g7pbro2
Definition: ERF_WDM6.H:330
amrex::Real m_bvts2
Definition: ERF_WDM6.H:334
real(kind=kind_phys) function rgmma(x)
Definition: ERF_module_mp_wdm6.F90:2185
Here is the call graph for this function:

◆ Qmoist_Ptr()

amrex::MultiFab* WDM6::Qmoist_Ptr ( const int &  varIdx)
inlineoverridevirtual

Reimplemented from NullMoist.

253  {
255  return mic_fab_vars[MicVarMap[varIdx]].get();
256  }
AMREX_ALWAYS_ASSERT(bx.length()[2]==khi+1)
Here is the call graph for this function:

◆ Qmoist_Restart_Vars()

void WDM6::Qmoist_Restart_Vars ( const SolverChoice &  ,
std::vector< int > &  a_idx,
std::vector< std::string > &  a_names 
) const
inlineoverridevirtual

Reimplemented from NullMoist.

265  {
266  a_idx = {0, 1, 2, 3};
267  a_names = {"RainAccum", "SnowAccum", "GraupAccum", "PrecipAccum"};
268  }

◆ Qmoist_Size()

int WDM6::Qmoist_Size ( )
inlineoverridevirtual

Reimplemented from NullMoist.

258 { return m_qmoist_size; }

◆ Qstate_Moist_NumConc_Size()

int WDM6::Qstate_Moist_NumConc_Size ( )
inlineoverridevirtual

Reimplemented from NullMoist.

260 { return n_qstate_moist_numconc_size; }
int n_qstate_moist_numconc_size
Definition: ERF_WDM6.H:289

◆ Qstate_Moist_Size()

int WDM6::Qstate_Moist_Size ( )
inlineoverridevirtual

Reimplemented from NullMoist.

259 { return n_qstate_moist_size; }
int n_qstate_moist_size
Definition: ERF_WDM6.H:288

◆ Sed_Flux()

const SedimentationFlux* WDM6::Sed_Flux ( ) const
inlineoverridevirtual

The sedimentation face fluxes of the most recent Advance, or null for a scheme that does not sediment (see ERF_SedimentationFlux.H)

Reimplemented from NullMoist.

250 { return &m_sed; }

◆ Set_dzmin()

void WDM6::Set_dzmin ( const amrex::Real  dz_min)
inlineoverridevirtual

Reimplemented from NullMoist.

221 { m_dzmin = dz_min; }
amrex::Real m_dzmin
Definition: ERF_WDM6.H:295

◆ Set_Lmask()

void WDM6::Set_Lmask ( amrex::iMultiFab *  )
inlineoverridevirtual

Import ERF's land/water mask. Only schemes whose physics branches on land vs water need to override this.

Reimplemented from NullMoist.

226 { m_lmask = lmask; }

◆ Update_Micro_Vars() [1/2]

void WDM6::Update_Micro_Vars ( amrex::MultiFab &  cons_in)
inlineoverridevirtual

Reimplemented from NullMoist.

237  {
238  Copy_State_to_Micro(cons_in);
239  }
void Copy_State_to_Micro(const amrex::MultiFab &cons_in) override
Here is the call graph for this function:

◆ Update_Micro_Vars() [2/2]

void WDM6::Update_Micro_Vars ( amrex::MultiFab &  cons_in,
const amrex::MultiFab *  base_state 
)
overridevirtual

Reimplemented from NullMoist.

◆ Update_State_Vars()

void WDM6::Update_State_Vars ( amrex::MultiFab &  cons_in,
const amrex::MultiFab &   
)
inlineoverridevirtual

Reimplemented from NullMoist.

243  {
244  Copy_Micro_to_State(cons_in);
245  }
void Copy_Micro_to_State(amrex::MultiFab &cons_in) override
Definition: ERF_UpdateWDM6.cpp:9
Here is the call graph for this function:

Member Data Documentation

◆ actk

constexpr amrex::Real WDM6::actk = wdm6_literal(0.6)
staticconstexpr

◆ actr

constexpr amrex::Real WDM6::actr = wdm6_literal(1.5)
staticconstexpr

◆ alpha_wdm6

constexpr amrex::Real WDM6::alpha_wdm6 = wdm6_literal(0.12)
staticconstexpr

◆ avtr

constexpr amrex::Real WDM6::avtr = wdm6_literal(841.9)
staticconstexpr

Referenced by AdvanceColumns().

◆ avts

constexpr amrex::Real WDM6::avts = wdm6_literal(11.72)
staticconstexpr

◆ bvtr

constexpr amrex::Real WDM6::bvtr = wdm6_literal(0.8)
staticconstexpr

◆ bvts

constexpr amrex::Real WDM6::bvts = wdm6_literal(0.41)
staticconstexpr

◆ dens_snow

constexpr amrex::Real WDM6::dens_snow = wdm6_literal(100.0)
staticconstexpr

◆ di100

constexpr amrex::Real WDM6::di100 = wdm6_literal(1.0e-4)
staticconstexpr

◆ di15

constexpr amrex::Real WDM6::di15 = wdm6_literal(15.0e-6)
staticconstexpr

◆ di2000

constexpr amrex::Real WDM6::di2000 = wdm6_literal(2000.0e-6)
staticconstexpr

◆ di600

constexpr amrex::Real WDM6::di600 = wdm6_literal(6.0e-4)
staticconstexpr

◆ di82

constexpr amrex::Real WDM6::di82 = wdm6_literal(82.0e-6)
staticconstexpr

◆ dicon

constexpr amrex::Real WDM6::dicon = wdm6_literal(11.9)
staticconstexpr

◆ dimax

constexpr amrex::Real WDM6::dimax = wdm6_literal(500.0e-6)
staticconstexpr

◆ dt

amrex::Real WDM6::dt {0.0}
private

◆ dtcldcr

constexpr amrex::Real WDM6::dtcldcr = wdm6_literal(120.0)
staticconstexpr

◆ eacrc

constexpr amrex::Real WDM6::eacrc = wdm6_literal(1.0)
staticconstexpr

◆ lamdacmax

constexpr amrex::Real WDM6::lamdacmax = wdm6_literal(5.0e5)
staticconstexpr

◆ lamdacmin

constexpr amrex::Real WDM6::lamdacmin = wdm6_literal(2.0e4)
staticconstexpr

◆ lamdarmax

constexpr amrex::Real WDM6::lamdarmax = wdm6_literal(5.0e4)
staticconstexpr

◆ lamdarmin

constexpr amrex::Real WDM6::lamdarmin = wdm6_literal(2.0e3)
staticconstexpr

◆ lamdasmax

constexpr amrex::Real WDM6::lamdasmax = wdm6_literal(1.0e5)
staticconstexpr

◆ m_avtg

amrex::Real WDM6::m_avtg {0}
private

◆ m_axis

int WDM6::m_axis {2}
private

Referenced by Define().

◆ m_bvtg

amrex::Real WDM6::m_bvtg {0}
private

◆ m_bvtg1

amrex::Real WDM6::m_bvtg1 {0}
private

◆ m_bvtg2

amrex::Real WDM6::m_bvtg2 {0}
private

◆ m_bvtg3

amrex::Real WDM6::m_bvtg3 {0}
private

◆ m_bvtg4

amrex::Real WDM6::m_bvtg4 {0}
private

◆ m_bvtr1

amrex::Real WDM6::m_bvtr1 {0}
private

◆ m_bvtr2

amrex::Real WDM6::m_bvtr2 {0}
private

◆ m_bvtr2o5

amrex::Real WDM6::m_bvtr2o5 {0}
private

◆ m_bvtr3

amrex::Real WDM6::m_bvtr3 {0}
private

◆ m_bvtr3o5

amrex::Real WDM6::m_bvtr3o5 {0}
private

◆ m_bvtr4

amrex::Real WDM6::m_bvtr4 {0}
private

◆ m_bvtr5

amrex::Real WDM6::m_bvtr5 {0}
private

◆ m_bvtr6

amrex::Real WDM6::m_bvtr6 {0}
private

◆ m_bvtr7

amrex::Real WDM6::m_bvtr7 {0}
private

◆ m_bvts1

amrex::Real WDM6::m_bvts1 {0}
private

◆ m_bvts2

amrex::Real WDM6::m_bvts2 {0}
private

◆ m_bvts3

amrex::Real WDM6::m_bvts3 {0}
private

◆ m_bvts4

amrex::Real WDM6::m_bvts4 {0}
private

◆ m_ccn0

amrex::Real WDM6::m_ccn0 {100.0e6}
private

◆ m_columns

MicrophysicsColumns WDM6::m_columns
private

◆ m_deng

amrex::Real WDM6::m_deng {0}
private

◆ m_detJ_cc

amrex::MultiFab* WDM6::m_detJ_cc {nullptr}
private

◆ m_do_cond

bool WDM6::m_do_cond {true}
private

Referenced by Define().

◆ m_dzmin

amrex::Real WDM6::m_dzmin {0.0}
private

Referenced by Set_dzmin().

◆ m_eacrr

amrex::Real WDM6::m_eacrr {0}
private

◆ m_g1pbg

amrex::Real WDM6::m_g1pbg {0}
private

◆ m_g1pbr

amrex::Real WDM6::m_g1pbr {0}
private

◆ m_g1pbs

amrex::Real WDM6::m_g1pbs {0}
private

◆ m_g2pbr

amrex::Real WDM6::m_g2pbr {0}
private

◆ m_g3pbg

amrex::Real WDM6::m_g3pbg {0}
private

◆ m_g3pbr

amrex::Real WDM6::m_g3pbr {0}
private

◆ m_g3pbs

amrex::Real WDM6::m_g3pbs {0}
private

◆ m_g4pbg

amrex::Real WDM6::m_g4pbg {0}
private

◆ m_g4pbr

amrex::Real WDM6::m_g4pbr {0}
private

◆ m_g4pbs

amrex::Real WDM6::m_g4pbs {0}
private

◆ m_g5pbgo2

amrex::Real WDM6::m_g5pbgo2 {0}
private

◆ m_g5pbr

amrex::Real WDM6::m_g5pbr {0}
private

◆ m_g5pbro2

amrex::Real WDM6::m_g5pbro2 {0}
private

◆ m_g5pbso2

amrex::Real WDM6::m_g5pbso2 {0}
private

◆ m_g6pbr

amrex::Real WDM6::m_g6pbr {0}
private

◆ m_g7pbr

amrex::Real WDM6::m_g7pbr {0}
private

◆ m_g7pbro2

amrex::Real WDM6::m_g7pbro2 {0}
private

◆ m_geom

amrex::Geometry WDM6::m_geom
private

◆ m_hail_opt

bool WDM6::m_hail_opt {false}
private

◆ m_lamdagmax

amrex::Real WDM6::m_lamdagmax {0}
private

◆ m_lmask

amrex::iMultiFab* WDM6::m_lmask {nullptr}
private

Referenced by Set_Lmask().

◆ m_moisture_type

MoistureType WDM6::m_moisture_type {MoistureType::None}
private

Referenced by Define().

◆ m_n0g

amrex::Real WDM6::m_n0g {0}
private

◆ m_pacrc

amrex::Real WDM6::m_pacrc {0}
private

◆ m_pacrg

amrex::Real WDM6::m_pacrg {0}
private

◆ m_pacrr

amrex::Real WDM6::m_pacrr {0}
private

◆ m_pacrs

amrex::Real WDM6::m_pacrs {0}
private

◆ m_pi_wdm6

amrex::Real WDM6::m_pi_wdm6 {0}
private

◆ m_pidn0g

amrex::Real WDM6::m_pidn0g {0}
private

◆ m_pidn0r

amrex::Real WDM6::m_pidn0r {0}
private

◆ m_pidn0s

amrex::Real WDM6::m_pidn0s {0}
private

◆ m_pidnc

amrex::Real WDM6::m_pidnc {0}
private

◆ m_pidnr

amrex::Real WDM6::m_pidnr {0}
private

◆ m_precg1

amrex::Real WDM6::m_precg1 {0}
private

◆ m_precg2

amrex::Real WDM6::m_precg2 {0}
private

◆ m_precr1

amrex::Real WDM6::m_precr1 {0}
private

◆ m_precr2

amrex::Real WDM6::m_precr2 {0}
private

◆ m_precs1

amrex::Real WDM6::m_precs1 {0}
private

◆ m_precs2

amrex::Real WDM6::m_precs2 {0}
private

◆ m_pvtg

amrex::Real WDM6::m_pvtg {0}
private

◆ m_pvtr

amrex::Real WDM6::m_pvtr {0}
private

◆ m_pvtrn

amrex::Real WDM6::m_pvtrn {0}
private

◆ m_pvts

amrex::Real WDM6::m_pvts {0}
private

◆ m_qc0

amrex::Real WDM6::m_qc0 {0}
private

◆ m_qc1

amrex::Real WDM6::m_qc1 {0}
private

◆ m_qck1

amrex::Real WDM6::m_qck1 {0}
private

◆ m_qmoist_size

int WDM6::m_qmoist_size = 4
private

Referenced by Qmoist_Ptr(), and Qmoist_Size().

◆ m_rdOcp

amrex::Real WDM6::m_rdOcp {RdoCp}
private

Referenced by Define().

◆ m_roqimax

amrex::Real WDM6::m_roqimax {0}
private

◆ m_rslopec2max

amrex::Real WDM6::m_rslopec2max {0}
private

◆ m_rslopec3max

amrex::Real WDM6::m_rslopec3max {0}
private

◆ m_rslopecmax

amrex::Real WDM6::m_rslopecmax {0}
private

◆ m_rslopeg2max

amrex::Real WDM6::m_rslopeg2max {0}
private

◆ m_rslopeg3max

amrex::Real WDM6::m_rslopeg3max {0}
private

◆ m_rslopegbmax

amrex::Real WDM6::m_rslopegbmax {0}
private

◆ m_rslopegmax

amrex::Real WDM6::m_rslopegmax {0}
private

◆ m_rsloper2max

amrex::Real WDM6::m_rsloper2max {0}
private

◆ m_rsloper3max

amrex::Real WDM6::m_rsloper3max {0}
private

◆ m_rsloperbmax

amrex::Real WDM6::m_rsloperbmax {0}
private

◆ m_rslopermax

amrex::Real WDM6::m_rslopermax {0}
private

◆ m_rslopes2max

amrex::Real WDM6::m_rslopes2max {0}
private

◆ m_rslopes3max

amrex::Real WDM6::m_rslopes3max {0}
private

◆ m_rslopesbmax

amrex::Real WDM6::m_rslopesbmax {0}
private

◆ m_rslopesmax

amrex::Real WDM6::m_rslopesmax {0}
private

◆ m_sed

SedimentationFlux WDM6::m_sed
private

Referenced by Sed_Flux().

◆ m_xlv1

amrex::Real WDM6::m_xlv1 {0}
private

◆ m_xmmax

amrex::Real WDM6::m_xmmax {0}
private

◆ m_z_phys_nd

amrex::MultiFab* WDM6::m_z_phys_nd {nullptr}
private

◆ mic_fab_vars

amrex::Array<FabPtr, MicVar_WDM6::NumVars> WDM6::mic_fab_vars
private

◆ MicVarMap

amrex::Vector<int> WDM6::MicVarMap
private

Referenced by Qmoist_Ptr().

◆ n0r

constexpr amrex::Real WDM6::n0r = wdm6_literal(8.0e6)
staticconstexpr

◆ n0s

constexpr amrex::Real WDM6::n0s = wdm6_literal(2.0e6)
staticconstexpr

◆ n0smax

constexpr amrex::Real WDM6::n0smax = wdm6_literal(1.0e11)
staticconstexpr

◆ n_qstate_moist_numconc_size

int WDM6::n_qstate_moist_numconc_size = 3
private

◆ n_qstate_moist_size

int WDM6::n_qstate_moist_size = 9
private

Referenced by Qstate_Moist_Size().

◆ ncmin

constexpr amrex::Real WDM6::ncmin = wdm6_literal(1.0e1)
staticconstexpr

◆ ncrk1

constexpr amrex::Real WDM6::ncrk1 = wdm6_literal(3.03e3)
staticconstexpr

◆ ncrk2

constexpr amrex::Real WDM6::ncrk2 = wdm6_literal(2.59e15)
staticconstexpr

◆ nlev

int WDM6::nlev {0}
private

◆ nrmin

constexpr amrex::Real WDM6::nrmin = wdm6_literal(1.0e-2)
staticconstexpr

◆ peaut

constexpr amrex::Real WDM6::peaut = wdm6_literal(0.55)
staticconstexpr

◆ pfrz1

constexpr amrex::Real WDM6::pfrz1 = wdm6_literal(100.0)
staticconstexpr

◆ pfrz2

constexpr amrex::Real WDM6::pfrz2 = wdm6_literal(0.66)
staticconstexpr

◆ qcrmin

constexpr amrex::Real WDM6::qcrmin = wdm6_literal(1.0e-9)
staticconstexpr

◆ qs0

constexpr amrex::Real WDM6::qs0 = wdm6_literal(6.0e-4)
staticconstexpr

◆ r0

constexpr amrex::Real WDM6::r0 = wdm6_literal(0.8e-5)
staticconstexpr

◆ satmax

constexpr amrex::Real WDM6::satmax = wdm6_literal(1.0048)
staticconstexpr

◆ xmyu

constexpr amrex::Real WDM6::xmyu = wdm6_literal(1.718e-5)
staticconstexpr

◆ xncr

constexpr amrex::Real WDM6::xncr = wdm6_literal(3.0e8)
staticconstexpr

◆ xncr0

constexpr amrex::Real WDM6::xncr0 = wdm6_literal(5.0e7)
staticconstexpr

◆ xncr1

constexpr amrex::Real WDM6::xncr1 = wdm6_literal(5.0e8)
staticconstexpr

◆ zhi

int WDM6::zhi {0}
private

◆ zlo

int WDM6::zlo {0}
private

The documentation for this class was generated from the following files: