ERF
Energy Research and Forecasting: An Atmospheric Modeling Code
erf_sbm::SBMTransport Class Reference

#include <ERF_SBMTransport.H>

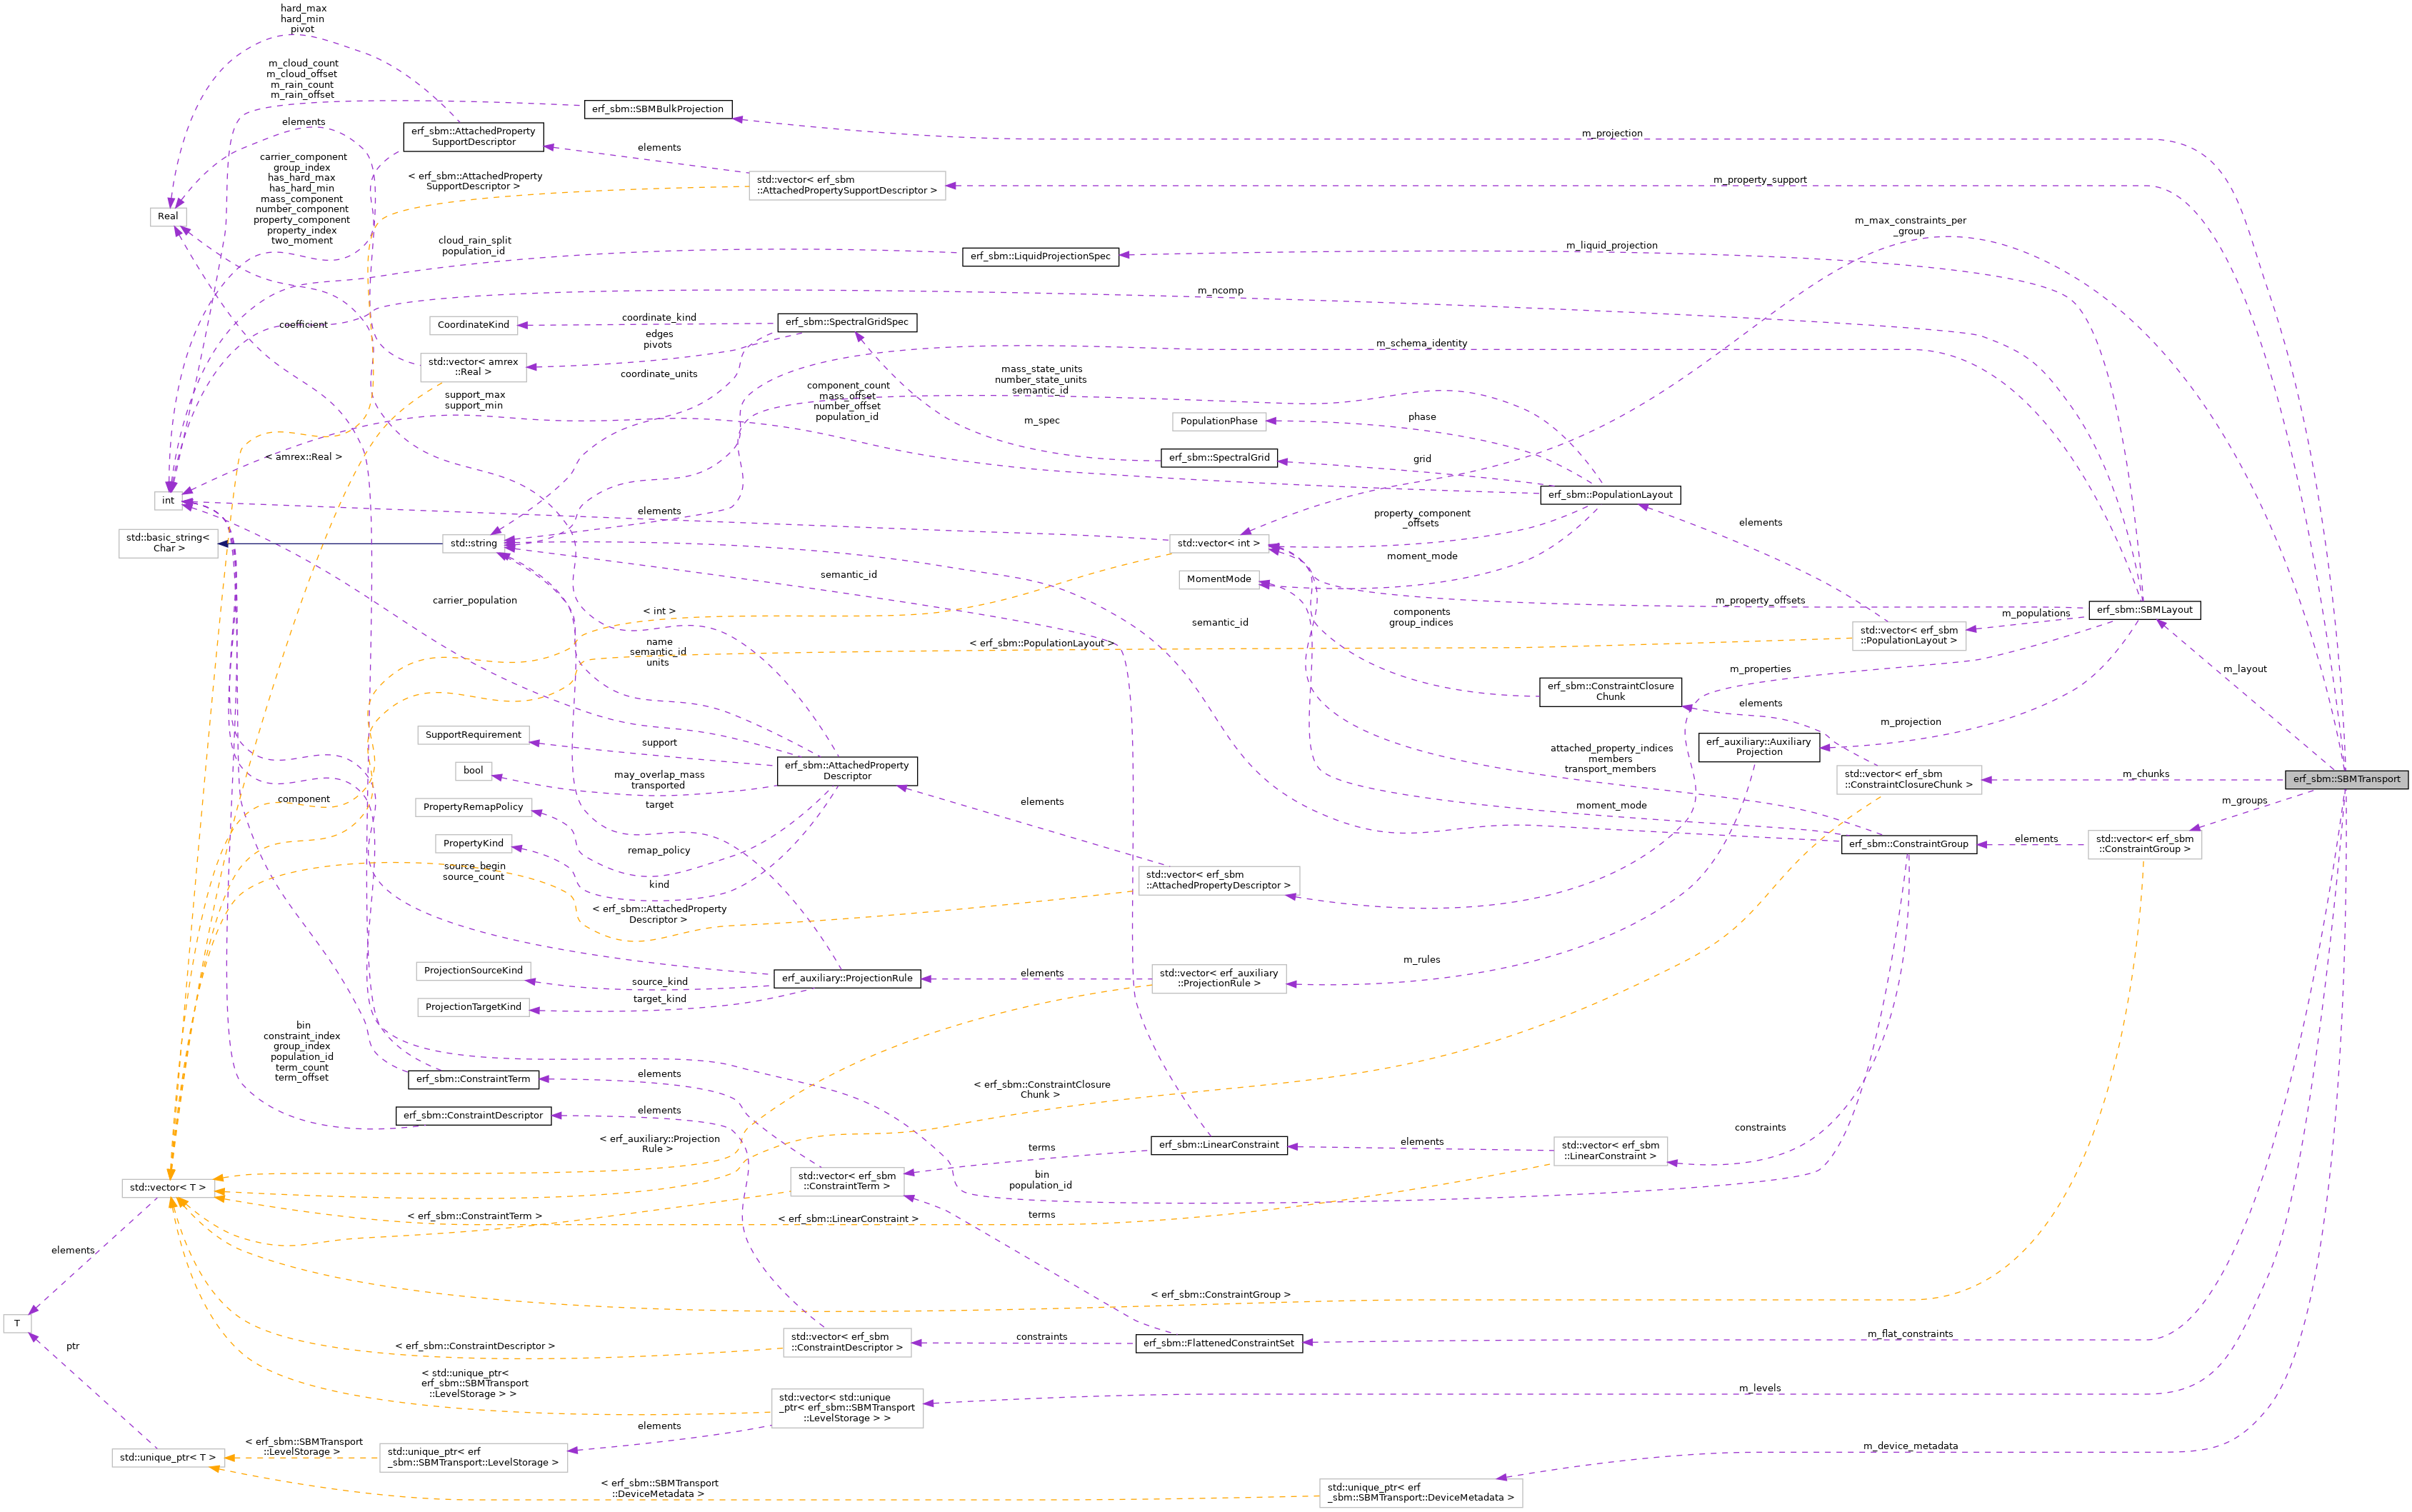
Collaboration diagram for erf_sbm::SBMTransport:

Classes

struct  DeviceMetadata
 
struct  LevelStorage
 

Public Member Functions

 SBMTransport (const SBMLayout &layout, int number_of_levels, int max_groups_per_chunk=16)
 
 ~SBMTransport ()
 
 SBMTransport (const SBMTransport &)=delete
 
SBMTransport & operator= (const SBMTransport &)=delete
 
void define (int level, const amrex::BoxArray &cell_ba, const amrex::DistributionMapping &dm)
 
bool rebuild_static_measure (int level, const amrex::MultiFab &detJ, const amrex::MultiFab &mx, const amrex::MultiFab &my, std::string &diagnostic)
 
void advance_stage_from_host (int level, erf_auxiliary::HostIntegrator method, int stage, double step_old_time, double input_time, double target_time, double host_stage_interval, SBMStateManager &state_manager, const amrex::MultiFab &S_old_cons, const amrex::MultiFab &S_new_cons, amrex::MultiFab &S_data_cons, const amrex::MultiFab &avg_xmom, const amrex::MultiFab &avg_ymom, const amrex::MultiFab &avg_zmom, const amrex::Geometry &geometry, int qc_component, int qr_component)
 
void advance_stage (int level, erf_auxiliary::HostIntegrator method, int stage, double step_old_time, double input_time, double target_time, double host_stage_interval, SBMStateManager &state_manager, const amrex::MultiFab &conserved_anchor, const amrex::MultiFab &conserved_input, amrex::MultiFab &conserved_target, const amrex::MultiFab &avg_xmom, const amrex::MultiFab &avg_ymom, const amrex::MultiFab &avg_zmom, const amrex::Geometry &geometry, int qc_component, int qr_component)
 
void destroy (int level)
 
bool is_defined (int level) const
 
bool measure_is_ready (int level) const
 
const amrex::MultiFab & static_measure (int level) const
 
const erf_auxiliary::CompletedStepFluxLedger & projected_ledger (int level) const
 
const erf_auxiliary::CompletedStepFluxLedger & completed_spectral_ledger (int level) const
 

Private Attributes

const SBMLayout & m_layout
 
SBMBulkProjection m_projection
 
std::vector< ConstraintGroup > m_groups
 
FlattenedConstraintSet m_flat_constraints
 
std::vector< AttachedPropertySupportDescriptor > m_property_support
 
std::vector< ConstraintClosureChunk > m_chunks
 
std::vector< int > m_max_constraints_per_group
 
std::vector< std::unique_ptr< LevelStorage > > m_levels
 
std::unique_ptr< DeviceMetadata > m_device_metadata
 

Detailed Description

Bounded mapped advection for the authoritative SBM spectrum.

The state manager remains the owner of prognostic state. This object owns per-level stage scratch, the static mapped measure, the compact projected qc/qr completed-step face ledger, and an optional all-component completed spectral face ledger for AMR-capable instances. Operational AMR execution remains disabled by the ERF runtime guard.

Constructor & Destructor Documentation

◆ SBMTransport() [1/2]

erf_sbm::SBMTransport::SBMTransport ( const SBMLayout &  layout,
int  number_of_levels,
int  max_groups_per_chunk = 16 
)
explicit
276  : m_layout(layout),
277  m_projection(layout),
281  m_chunks(make_constraint_closure_chunks(layout, max_groups_per_chunk)),
283  m_levels(static_cast<std::size_t>(number_of_levels)),
284  m_device_metadata(std::make_unique<DeviceMetadata>())
285 {
286  AMREX_ALWAYS_ASSERT(number_of_levels > 0);
287  if (AMREX_SPACEDIM != 3) {
288  throw std::invalid_argument(
289  "SBM M3 mapped transport currently requires three dimensions");
290  }
291 
292  std::vector<ConstraintDescriptor> local_descriptors;
293  std::vector<ConstraintTerm> local_terms;
294  std::vector<LocalPropertySupport> local_supports;
295  m_device_metadata->host_groups.resize(m_groups.size());
296  std::vector<int> group_chunk(m_groups.size(), -1);
297  std::vector<int> group_local(m_groups.size(), -1);
298 
299  for (std::size_t chunk_index = 0; chunk_index < m_chunks.size();
300  ++chunk_index) {
301  const auto& chunk = m_chunks[chunk_index];
302  int chunk_ratio_components = 0;
303  std::vector<int> global_to_local(
304  static_cast<std::size_t>(m_layout.ncomp()), -1);
305  for (std::size_t local = 0; local < chunk.components.size(); ++local) {
306  global_to_local[static_cast<std::size_t>(chunk.components[local])] =
307  static_cast<int>(local);
308  }
309  for (std::size_t local_group = 0;
310  local_group < chunk.group_indices.size(); ++local_group) {
311  const int group_index = chunk.group_indices[local_group];
312  const auto& group =
313  m_groups[static_cast<std::size_t>(group_index)];
314  group_chunk[static_cast<std::size_t>(group_index)] =
315  static_cast<int>(chunk_index);
316  group_local[static_cast<std::size_t>(group_index)] =
317  static_cast<int>(local_group);
318  auto& device_group =
320  ->host_groups[static_cast<std::size_t>(group_index)];
321  device_group.constraints_begin =
322  static_cast<int>(local_descriptors.size());
323  device_group.supports_begin =
324  static_cast<int>(local_supports.size());
325  device_group.chunk_index = static_cast<int>(chunk_index);
326  device_group.local_group_index = static_cast<int>(local_group);
327 
328  for (const auto& descriptor : m_flat_constraints.constraints) {
329  if (descriptor.group_index != group_index) {
330  continue;
331  }
332  ConstraintDescriptor local_descriptor = descriptor;
333  local_descriptor.term_offset =
334  static_cast<int>(local_terms.size());
335  for (int term_index = 0; term_index < descriptor.term_count;
336  ++term_index) {
337  auto term =
338  m_flat_constraints.terms[static_cast<std::size_t>(
339  descriptor.term_offset + term_index)];
340  const int local_component =
341  global_to_local[static_cast<std::size_t>(
342  term.component)];
343  if (local_component < 0) {
344  throw std::logic_error("SBM closure chunk split an "
345  "atomic constraint group");
346  }
347  term.component = local_component;
348  local_terms.push_back(term);
349  }
350  local_descriptor.group_index = static_cast<int>(local_group);
351  local_descriptors.push_back(local_descriptor);
352  ++device_group.linear_constraint_count;
353  }
354 
355  for (const auto& support : m_property_support) {
356  if (support.group_index != group_index) {
357  continue;
358  }
359  LocalPropertySupport local_support;
360  local_support.property_global = support.property_component;
361  local_support.carrier_global = support.carrier_component;
362  local_support.property_local =
363  global_to_local[static_cast<std::size_t>(
364  support.property_component)];
365  local_support.carrier_local =
366  global_to_local[static_cast<std::size_t>(
367  support.carrier_component)];
368  local_support.hard_min = support.hard_min;
369  local_support.hard_max = support.hard_max;
370  local_support.has_hard_min = support.has_hard_min;
371  local_support.has_hard_max = support.has_hard_max;
372  if (local_support.property_local < 0 ||
373  local_support.carrier_local < 0) {
374  throw std::logic_error(
375  "SBM closure chunk split an attached-property group");
376  }
377  local_supports.push_back(local_support);
378  ++device_group.support_count;
379  }
380  // Keep the strict persisted upper edge open during transport by
381  // reserving eta of the endpoint_low margin for interior 2M bins.
382  if (group.moment_mode == MomentMode::TwoMoment) {
383  const auto population = std::find_if(
384  m_layout.populations().begin(), m_layout.populations().end(),
385  [&group](const PopulationLayout& candidate) {
386  return candidate.population_id == group.population_id;
387  });
388  if (population == m_layout.populations().end()) {
389  throw std::logic_error(
390  "SBM transport group has no matching population layout");
391  }
392  if (group.bin < population->grid.nbins() - 1) {
393  const int mass_global = population->mass_offset + group.bin;
394  const int number_global =
395  population->number_offset + group.bin;
396  device_group.canonical_mass_local =
397  global_to_local[static_cast<std::size_t>(mass_global)];
398  device_group.canonical_number_local =
399  global_to_local[static_cast<std::size_t>(number_global)];
400  if (device_group.canonical_mass_local < 0 ||
401  device_group.canonical_number_local < 0) {
402  throw std::logic_error(
403  "SBM closure chunk split an interior two-moment "
404  "canonical-reserve group");
405  }
406  const Real lower = population->grid.edges()[
407  static_cast<std::size_t>(group.bin)];
408  const Real upper = population->grid.edges()[
409  static_cast<std::size_t>(group.bin + 1)];
410  const Real width = upper - lower;
411  const Real eta =
413  device_group.canonical_mass_coefficient =
414  -(Real(1.0) + eta) / width;
415  device_group.canonical_number_coefficient =
416  (Real(1.0) - eta) * upper / width;
417  device_group.canonical_reserve = 1;
418  }
419  }
420  device_group.ratio_count = device_group.linear_constraint_count +
421  2 * device_group.support_count +
422  device_group.canonical_reserve;
423  device_group.ratio_offset = chunk_ratio_components;
424  AMREX_ALWAYS_ASSERT(device_group.ratio_count >= 0);
426  device_group.ratio_count <=
427  std::numeric_limits<int>::max() - chunk_ratio_components);
428  chunk_ratio_components += device_group.ratio_count;
429  m_max_constraints_per_group[static_cast<std::size_t>(group_index)] =
430  device_group.ratio_count;
431  }
432  }
433 
434  auto& device = *m_device_metadata;
435  device.local_constraints.resize(local_descriptors.size());
436  device.local_terms.resize(local_terms.size());
437  device.local_supports.resize(local_supports.size());
438  if (!local_descriptors.empty()) {
439  amrex::Gpu::copy(amrex::Gpu::hostToDevice, local_descriptors.begin(),
440  local_descriptors.end(),
441  device.local_constraints.begin());
442  }
443  if (!local_terms.empty()) {
444  amrex::Gpu::copy(amrex::Gpu::hostToDevice, local_terms.begin(),
445  local_terms.end(), device.local_terms.begin());
446  }
447  if (!local_supports.empty()) {
448  amrex::Gpu::copy(amrex::Gpu::hostToDevice, local_supports.begin(),
449  local_supports.end(), device.local_supports.begin());
450  }
451  device.global_constraints.resize(m_flat_constraints.constraints.size());
452  device.global_terms.resize(m_flat_constraints.terms.size());
453  if (!m_flat_constraints.constraints.empty()) {
454  amrex::Gpu::copy(amrex::Gpu::hostToDevice,
457  device.global_constraints.begin());
458  }
459  if (!m_flat_constraints.terms.empty()) {
460  amrex::Gpu::copy(
461  amrex::Gpu::hostToDevice, m_flat_constraints.terms.begin(),
462  m_flat_constraints.terms.end(), device.global_terms.begin());
463  }
464 
465  std::vector<Real> host_edges;
466  std::vector<Real> host_pivots;
467  std::vector<int> host_property_components;
468  std::vector<int> edge_offsets, pivot_offsets, property_offsets;
469  for (const auto& population : m_layout.populations()) {
470  edge_offsets.push_back(static_cast<int>(host_edges.size()));
471  host_edges.insert(host_edges.end(), population.grid.edges().begin(),
472  population.grid.edges().end());
473  pivot_offsets.push_back(static_cast<int>(host_pivots.size()));
474  host_pivots.insert(host_pivots.end(), population.grid.pivots().begin(),
475  population.grid.pivots().end());
476  property_offsets.push_back(
477  static_cast<int>(host_property_components.size()));
478  host_property_components.insert(
479  host_property_components.end(),
480  population.property_component_offsets.begin(),
481  population.property_component_offsets.end());
482  }
483  device.edges.resize(host_edges.size());
484  device.pivots.resize(host_pivots.size());
485  device.property_components.resize(host_property_components.size());
486  if (!host_edges.empty()) {
487  amrex::Gpu::copy(amrex::Gpu::hostToDevice, host_edges.begin(),
488  host_edges.end(), device.edges.begin());
489  }
490  if (!host_pivots.empty()) {
491  amrex::Gpu::copy(amrex::Gpu::hostToDevice, host_pivots.begin(),
492  host_pivots.end(), device.pivots.begin());
493  }
494  if (!host_property_components.empty()) {
495  amrex::Gpu::copy(
496  amrex::Gpu::hostToDevice, host_property_components.begin(),
497  host_property_components.end(), device.property_components.begin());
498  }
499  std::vector<PopulationRemapView> device_views;
500  device_views.reserve(m_layout.populations().size());
501  for (std::size_t p = 0; p < m_layout.populations().size(); ++p) {
502  const auto& population = m_layout.populations()[p];
503  auto view = population_remap_view(m_layout, population.population_id);
504  view.edges = device.edges.data() + edge_offsets[p];
505  view.pivots = population.grid.pivots().empty()
506  ? nullptr
507  : device.pivots.data() + pivot_offsets[p];
508  view.property_component_offsets =
509  population.property_component_offsets.empty()
510  ? nullptr
511  : device.property_components.data() + property_offsets[p];
512  device_views.push_back(view);
513  }
514  device.populations.resize(device_views.size());
515  if (!device_views.empty()) {
516  amrex::Gpu::copy(amrex::Gpu::hostToDevice, device_views.begin(),
517  device_views.end(), device.populations.begin());
518  }
519 }
AMREX_ALWAYS_ASSERT(bx.length()[2]==khi+1)
DiagnosticDescriptor descriptor
Definition: ERF_Plotfile2DCatalog.cpp:108
int chunk_index
Definition: ERF_SBMTransport.cpp:36
amrex::Real Real
Definition: ERF_ShocInterface.H:19
const std::vector< PopulationLayout > & populations() const noexcept
Definition: ERF_SBMLayout.H:99
int ncomp() const noexcept
Definition: ERF_SBMLayout.H:103
std::unique_ptr< DeviceMetadata > m_device_metadata
Definition: ERF_SBMTransport.H:108
std::vector< ConstraintClosureChunk > m_chunks
Definition: ERF_SBMTransport.H:105
SBMBulkProjection m_projection
Definition: ERF_SBMTransport.H:101
std::vector< ConstraintGroup > m_groups
Definition: ERF_SBMTransport.H:102
std::vector< std::unique_ptr< LevelStorage > > m_levels
Definition: ERF_SBMTransport.H:107
std::vector< AttachedPropertySupportDescriptor > m_property_support
Definition: ERF_SBMTransport.H:104
std::vector< int > m_max_constraints_per_group
Definition: ERF_SBMTransport.H:106
FlattenedConstraintSet m_flat_constraints
Definition: ERF_SBMTransport.H:103
const SBMLayout & m_layout
Definition: ERF_SBMTransport.H:98
@ p
Definition: ERF_WSM6.H:280
std::vector< ConstraintGroup > make_constraint_groups(const SBMLayout &layout)
Definition: ERF_SBMConstraintGroups.cpp:77
std::vector< AttachedPropertySupportDescriptor > make_attached_property_support_descriptors(const SBMLayout &layout)
Definition: ERF_SBMConstraintGroups.cpp:214
std::vector< ConstraintClosureChunk > make_constraint_closure_chunks(const SBMLayout &layout, const int max_groups)
Definition: ERF_SBMConstraintGroups.cpp:257
FlattenedConstraintSet make_constraint_descriptors(const SBMLayout &layout)
Definition: ERF_SBMConstraintGroups.cpp:208
PopulationRemapView population_remap_view(const SBMLayout &layout, const int population_id) noexcept
Definition: ERF_SBMRemapping.cpp:8
real(c_double), parameter epsilon
Definition: ERF_module_model_constants.F90:12
std::vector< ConstraintTerm > terms
Definition: ERF_SBMConstraintGroups.H:65
std::vector< ConstraintDescriptor > constraints
Definition: ERF_SBMConstraintGroups.H:64
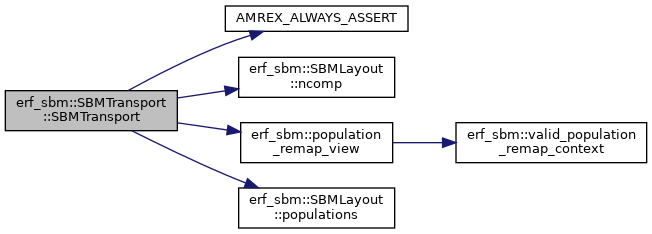
Here is the call graph for this function:

◆ ~SBMTransport()

erf_sbm::SBMTransport::~SBMTransport ( )
default

◆ SBMTransport() [2/2]

erf_sbm::SBMTransport::SBMTransport ( const SBMTransport &  )
delete

Member Function Documentation

◆ advance_stage()

void erf_sbm::SBMTransport::advance_stage ( int  level,
erf_auxiliary::HostIntegrator  method,
int  stage,
double  step_old_time,
double  input_time,
double  target_time,
double  host_stage_interval,
SBMStateManager &  state_manager,
const amrex::MultiFab &  conserved_anchor,
const amrex::MultiFab &  conserved_input,
amrex::MultiFab &  conserved_target,
const amrex::MultiFab &  avg_xmom,
const amrex::MultiFab &  avg_ymom,
const amrex::MultiFab &  avg_zmom,
const amrex::Geometry &  geometry,
int  qc_component,
int  qr_component 
)
633 {
635  auto& data = *m_levels[static_cast<std::size_t>(level)];
637  data.measure_ready,
638  "SBM M3 cannot advance before its static mapped measure is built");
639  AMREX_ALWAYS_ASSERT(state_manager.is_defined(level));
640  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
641  AMREX_ALWAYS_ASSERT(geometry.isPeriodic(dir));
642  }
643 
645  std::string diagnostic;
647  method, stage, host_stage_interval, recipe, diagnostic)) {
648  amrex::Abort("SBM M3 stage recipe: " + diagnostic);
649  }
650  if (!std::isfinite(step_old_time) || !std::isfinite(input_time) ||
651  !std::isfinite(target_time)) {
652  amrex::Abort("SBM M3 received a nonfinite semantic time");
653  }
654  if (!state_manager.step_active(level)) {
655  amrex::Abort("SBM M3 stage requires a state-manager begin-step transition at ERF::Advance");
656  }
657  const MultiFab& spectrum = stage == 0
658  ? state_manager.old_state(level)
659  : state_manager.new_state(level);
660  const double spectrum_time = stage == 0
661  ? state_manager.old_time(level)
662  : state_manager.new_time(level);
663  const double expected_spectrum_time = stage == 0 ? step_old_time : input_time;
664  if (spectrum_time != expected_spectrum_time || input_time != spectrum_time) {
665  std::ostringstream message;
666  message.precision(17);
667  message << "SBM M3 spectral input time mismatch at level " << level
668  << " stage " << stage << ": expected " << expected_spectrum_time
669  << " and requested input time " << input_time
670  << ", got " << spectrum_time;
671  amrex::Abort(message.str());
672  }
673  AMREX_ALWAYS_ASSERT(spectrum.nComp() == m_layout.ncomp());
674  AMREX_ALWAYS_ASSERT(erf_auxiliary::SameCellLayout(spectrum, data.target));
676  erf_auxiliary::SameCellLayout(spectrum, conserved_anchor));
678  erf_auxiliary::SameCellLayout(spectrum, conserved_input));
680  erf_auxiliary::SameCellLayout(spectrum, conserved_target));
681  AMREX_ALWAYS_ASSERT(erf_auxiliary::SameCellLayout(spectrum, data.measure));
682  AMREX_ALWAYS_ASSERT(conserved_anchor.nComp() > Rho_comp &&
683  conserved_input.nComp() > Rho_comp &&
684  conserved_target.nComp() > Rho_comp);
685  if (stage == 0) {
686  if (data.projected_ledger.step_active()) {
687  amrex::Abort("SBM M3 received stage 0 before the previous timestep "
688  "completed");
689  }
690  MultiFab::Copy(data.anchor, spectrum, 0, 0, m_layout.ncomp(), 0);
691  } else if (!data.projected_ledger.step_active() ||
692  data.projected_ledger.next_stage() != stage) {
693  amrex::Abort("SBM M3 stage arrived before stage 0 or out of order");
694  }
695  if (data.spectral_ledger.is_defined() &&
696  !data.spectral_ledger.begin_stage(method, stage, step_old_time,
697  recipe, diagnostic)) {
698  amrex::Abort("SBM M4a spectral face-ledger stage sequence: " + diagnostic);
699  }
700 
701  const MultiFab& trial_state =
703  ? data.anchor
704  : spectrum;
705  const MultiFab& trial_conserved =
707  ? conserved_anchor
708  : conserved_input;
710  Rho_comp, diagnostic)) {
711  amrex::Abort("SBM M3 target density: " + diagnostic);
712  }
713 
714  build_intensive(data.input_intensive, spectrum, conserved_input,
715  geometry.periodicity(), "input");
716  MultiFab::Copy(data.physical_input_intensive, data.input_intensive, 0, 0,
717  m_layout.ncomp(), 2);
718  build_intensive(data.base_intensive, trial_state, trial_conserved,
719  geometry.periodicity(), "limiter-trial base");
720  build_intensive(data.anchor_intensive, data.anchor, conserved_anchor,
721  geometry.periodicity(), "old-step anchor");
722 
723  // Transform every 2M pair in place to endpoint-number coordinates. The
724  // canonical transform is shared with persisted-state reconstruction and
725  // is intentionally performed before native scalar WENO-Z3.
726  data.invalid.setVal(Real(0.0));
727  const auto populations = m_device_metadata->populations.data();
728  const int population_count =
729  static_cast<int>(m_layout.populations().size());
730  for (amrex::MFIter mfi(data.input_intensive, amrex::TilingIfNotGPU());
731  mfi.isValid(); ++mfi) {
732  const amrex::Box bx = mfi.tilebox();
733  const auto input = data.input_intensive.array(mfi);
734  const auto invalid = data.invalid.array(mfi);
735  const auto endpoint_populations = populations;
737  bx, [=] AMREX_GPU_DEVICE(int i, int j, int k) noexcept {
738  int cell_invalid = 0;
739  for (int p = 0; p < population_count; ++p) {
740  const auto& pop = endpoint_populations[p];
741  if (pop.moment_mode != MomentMode::TwoMoment) {
742  continue;
743  }
744  for (int bin = 0; bin < pop.nbins; ++bin) {
745  const int mass_comp = pop.mass_offset + bin;
746  const int number_comp = pop.number_offset + bin;
749  input(i, j, k, number_comp),
750  input(i, j, k, mass_comp), pop.edges[bin],
751  pop.edges[bin + 1], endpoint)) {
752  cell_invalid = 1;
753  } else {
754  input(i, j, k, mass_comp) = endpoint.L;
755  input(i, j, k, number_comp) = endpoint.H;
756  }
757  }
758  }
759  invalid(i, j, k, 0) = static_cast<Real>(cell_invalid);
760  });
761  }
762  if (data.invalid.max(0) != Real(0.0)) {
763  amrex::Abort("SBM M3 input spectrum could not be represented in "
764  "endpoint-number coordinates");
765  }
766  data.input_intensive.FillBoundary(geometry.periodicity());
767 
768  // Check the donor outgoing-demand condition against the semantic limiter
769  // base before constructing any low-order face rates.
770  const auto inv_dx = geometry.InvCellSizeArray();
771  const Real tau = static_cast<Real>(recipe.limiter_trial_interval);
772  data.outgoing_demand.setVal(Real(0.0));
773  for (amrex::MFIter mfi(data.outgoing_demand, amrex::TilingIfNotGPU());
774  mfi.isValid(); ++mfi) {
775  const amrex::Box bx = mfi.tilebox();
776  const auto fx = avg_xmom.const_array(mfi);
777  const auto fy = avg_ymom.const_array(mfi);
778  const auto fz = avg_zmom.const_array(mfi);
779  const auto rho = trial_conserved.const_array(mfi);
780  const auto omega = data.measure.const_array(mfi);
781  const auto out = data.outgoing_demand.array(mfi);
782  const auto dx_inv = inv_dx;
783  amrex::ParallelFor(bx, [=] AMREX_GPU_DEVICE(int i, int j,
784  int k) noexcept {
785  out(i, j, k, 0) = tau *
787  fx(i + 1, j, k, 0), fx(i, j, k, 0),
788  fy(i, j + 1, k, 0), fy(i, j, k, 0),
789  fz(i, j, k + 1, 0), fz(i, j, k, 0),
790  omega(i, j, k, 0), rho(i, j, k, Rho_comp), dx_inv);
791  });
792  }
793  const Real max_outgoing = data.outgoing_demand.max(0);
794  const Real cfl_tolerance =
796  if (!std::isfinite(max_outgoing) ||
797  max_outgoing > Real(1.0) + cfl_tolerance) {
798  std::ostringstream message;
799  message << "SBM M3 donor outgoing-demand condition failed: max="
800  << max_outgoing << " tau=" << tau
801  << " (no SBM subcycling is performed)";
802  amrex::Abort(message.str());
803  }
804 
805  data.projected_rate.setVal(Real(0.0));
806  const auto& device = *m_device_metadata;
807  for (std::size_t chunk_index = 0; chunk_index < m_chunks.size();
808  ++chunk_index) {
809  const auto& chunk = m_chunks[chunk_index];
810  std::vector<int> global_to_local(
811  static_cast<std::size_t>(m_layout.ncomp()), -1);
812  for (std::size_t local = 0; local < chunk.components.size(); ++local) {
813  global_to_local[static_cast<std::size_t>(chunk.components[local])] =
814  static_cast<int>(local);
815  }
816  data.low_rate.setVal(Real(0.0));
817  data.high_rate.setVal(Real(0.0));
818  data.accepted_rate.setVal(Real(0.0));
819 
820  // Low-order donor rates use the recipe-selected trial base.
821  for (amrex::MFIter mfi(data.input_intensive, amrex::TilingIfNotGPU());
822  mfi.isValid(); ++mfi) {
823  const amrex::Box bx = mfi.tilebox();
824  const auto z = data.base_intensive.const_array(mfi);
825  const auto fd_x = avg_xmom.const_array(mfi);
826  const auto fd_y = avg_ymom.const_array(mfi);
827  const auto fd_z = avg_zmom.const_array(mfi);
828  auto low_x = data.low_rate.dir(0).array(mfi);
829  auto low_y = data.low_rate.dir(1).array(mfi);
830  auto low_z = data.low_rate.dir(2).array(mfi);
831  for (std::size_t local = 0; local < chunk.components.size();
832  ++local) {
833  const int component = chunk.components[local];
834  const int local_component = static_cast<int>(local);
835  const amrex::Box xbx = amrex::surroundingNodes(bx, 0);
836  const amrex::Box ybx = amrex::surroundingNodes(bx, 1);
837  const amrex::Box zbx = amrex::surroundingNodes(bx, 2);
839  xbx, [=] AMREX_GPU_DEVICE(int i, int j, int k) noexcept {
840  const Real carrier = fd_x(i, j, k, 0);
841  const Real donor = carrier >= Real(0.0)
842  ? z(i - 1, j, k, component)
843  : z(i, j, k, component);
844  low_x(i, j, k, local_component) = carrier * donor;
845  });
847  ybx, [=] AMREX_GPU_DEVICE(int i, int j, int k) noexcept {
848  const Real carrier = fd_y(i, j, k, 0);
849  const Real donor = carrier >= Real(0.0)
850  ? z(i, j - 1, k, component)
851  : z(i, j, k, component);
852  low_y(i, j, k, local_component) = carrier * donor;
853  });
855  zbx, [=] AMREX_GPU_DEVICE(int i, int j, int k) noexcept {
856  const Real carrier = fd_z(i, j, k, 0);
857  const Real donor = carrier >= Real(0.0)
858  ? z(i, j, k - 1, component)
859  : z(i, j, k, component);
860  low_z(i, j, k, local_component) = carrier * donor;
861  });
862  }
863  }
864 
865  // ERF-native WENO-Z3 is applied to all input intensives. The 2M
866  // mass/number slots currently contain B_lo and B_hi, so the same
867  // builder also supplies the required endpoint-coordinate candidate.
868  for (amrex::MFIter mfi(data.input_intensive, amrex::TilingIfNotGPU());
869  mfi.isValid(); ++mfi) {
870  const amrex::Box bx = mfi.tilebox();
871  const GpuArray<const Array4<Real>, AMREX_SPACEDIM> flux_views{
872  {data.high_rate.dir(0).array(mfi),
873  data.high_rate.dir(1).array(mfi),
874  data.high_rate.dir(2).array(mfi)}};
875  for (std::size_t local = 0; local < chunk.components.size();
876  ++local) {
878  bx, data.input_intensive.const_array(mfi),
879  chunk.components[local], flux_views,
880  static_cast<int>(local), avg_xmom.const_array(mfi),
881  avg_ymom.const_array(mfi), avg_zmom.const_array(mfi),
883  }
884  }
885 
886  // Invert endpoint face rates into physical water-mass and number
887  // rates before the one common group limiter is applied.
888  for (const auto& population : m_layout.populations()) {
889  if (population.moment_mode != MomentMode::TwoMoment) {
890  continue;
891  }
892  for (int bin = 0; bin < population.grid.nbins(); ++bin) {
893  const int mass_global = population.mass_offset + bin;
894  const int number_global = population.number_offset + bin;
895  const int mass_local =
896  global_to_local[static_cast<std::size_t>(mass_global)];
897  const int number_local =
898  global_to_local[static_cast<std::size_t>(number_global)];
899  if (mass_local < 0 || number_local < 0) {
900  continue;
901  }
902  const Real lower =
903  population.grid.edges()[static_cast<std::size_t>(bin)];
904  const Real upper =
905  population.grid.edges()[static_cast<std::size_t>(bin + 1)];
906  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
907  auto& face_rate = data.high_rate.dir(dir);
908  for (amrex::MFIter mfi(face_rate, amrex::TilingIfNotGPU());
909  mfi.isValid(); ++mfi) {
910  const amrex::Box bx = mfi.tilebox();
911  const auto flux = face_rate.array(mfi);
913  bx,
914  [=] AMREX_GPU_DEVICE(int i, int j, int k) noexcept {
915  const Real blo = flux(i, j, k, mass_local);
916  const Real bhi = flux(i, j, k, number_local);
917  flux(i, j, k, mass_local) =
918  lower * blo + upper * bhi;
919  flux(i, j, k, number_local) = blo + bhi;
920  });
921  }
922  }
923  }
924  }
925 
926  data.invalid.setVal(Real(0.0));
927  data.cell_ratios.setVal(Real(0.0));
928  for (const int group_index : chunk.group_indices) {
929  const auto& group = m_groups[static_cast<std::size_t>(group_index)];
930  const auto& group_device =
931  device.host_groups[static_cast<std::size_t>(group_index)];
932  AMREX_ALWAYS_ASSERT(group_device.ratio_offset >= 0);
933  AMREX_ALWAYS_ASSERT(group_device.ratio_count >= 0);
935  group_device.ratio_offset <= data.cell_ratios.nComp());
937  group_device.ratio_count <=
938  data.cell_ratios.nComp() - group_device.ratio_offset);
939 
940  // Form the complete donor low-order trial H^L for this atomic
941  // group from the semantic limiter-trial base.
942  for (const int component : group.members) {
943  const int local_component =
944  global_to_local[static_cast<std::size_t>(component)];
945  AMREX_ALWAYS_ASSERT(local_component >= 0);
946  for (amrex::MFIter mfi(data.low_trial_h,
947  amrex::TilingIfNotGPU());
948  mfi.isValid(); ++mfi) {
949  const amrex::Box bx = mfi.tilebox();
950  const auto u = trial_state.const_array(mfi);
951  const auto omega = data.measure.const_array(mfi);
952  const auto fx = data.low_rate.dir(0).const_array(mfi);
953  const auto fy = data.low_rate.dir(1).const_array(mfi);
954  const auto fz = data.low_rate.dir(2).const_array(mfi);
955  const auto hlow = data.low_trial_h.array(mfi);
956  const Real dx = inv_dx[0], dy = inv_dx[1], dz = inv_dx[2];
958  bx, [=] AMREX_GPU_DEVICE(int i, int j, int k) noexcept {
959  const Real div =
961  fx(i + 1, j, k, local_component),
962  fx(i, j, k, local_component),
963  fy(i, j + 1, k, local_component),
964  fy(i, j, k, local_component),
965  fz(i, j, k + 1, local_component),
966  fz(i, j, k, local_component), dx, dy, dz);
967  hlow(i, j, k, local_component) =
968  omega(i, j, k, 0) * u(i, j, k, component) -
969  tau * div;
970  });
971  }
972  }
973 
974  const ConstraintDescriptor* local_constraints =
975  device.local_constraints.data();
976  const ConstraintTerm* local_terms = device.local_terms.data();
977  const LocalPropertySupport* local_supports =
978  device.local_supports.data();
979  for (amrex::MFIter mfi(data.cell_ratios, amrex::TilingIfNotGPU());
980  mfi.isValid(); ++mfi) {
981  const amrex::Box bx = mfi.tilebox();
982  const auto hlow = data.low_trial_h.const_array(mfi);
983  const FaceArraySet low_faces{
984  {data.low_rate.dir(0).const_array(mfi),
985  data.low_rate.dir(1).const_array(mfi),
986  data.low_rate.dir(2).const_array(mfi)}};
987  const FaceArraySet high_faces{
988  {data.high_rate.dir(0).const_array(mfi),
989  data.high_rate.dir(1).const_array(mfi),
990  data.high_rate.dir(2).const_array(mfi)}};
991  const auto base = data.base_intensive.const_array(mfi);
992  // Keep donor-envelope ratios in physical (M,N) coordinates.
993  // The high-order input scratch is endpoint-transformed below.
994  const auto input =
995  data.physical_input_intensive.const_array(mfi);
996  const auto anchor = data.anchor_intensive.const_array(mfi);
997  const auto ratios = data.cell_ratios.array(mfi);
998  const auto invalid = data.invalid.array(mfi);
999  const auto dx = inv_dx;
1000  const int constraints_begin = group_device.constraints_begin;
1001  const int linear_count = group_device.linear_constraint_count;
1002  const int supports_begin = group_device.supports_begin;
1003  const int support_count = group_device.support_count;
1004  const int ratio_offset = group_device.ratio_offset;
1005  const int canonical_reserve =
1006  group_device.canonical_reserve;
1007  const int canonical_mass_local =
1008  group_device.canonical_mass_local;
1009  const int canonical_number_local =
1010  group_device.canonical_number_local;
1012  group_device.canonical_mass_coefficient;
1014  group_device.canonical_number_coefficient;
1015  const Real roundoff =
1017  amrex::ParallelFor(bx, [=] AMREX_GPU_DEVICE(int i, int j,
1018  int k) noexcept {
1019  int bad = 0;
1020  for (int ci = 0; ci < linear_count; ++ci) {
1021  const auto& descriptor =
1022  local_constraints[constraints_begin + ci];
1023  Real margin = Real(0.0);
1024  Real scale = Real(0.0);
1025  for (int t = 0; t < descriptor.term_count; ++t) {
1026  const auto& term =
1027  local_terms[descriptor.term_offset + t];
1028  const Real value = hlow(i, j, k, term.component);
1029  margin = std::fma(term.coefficient, value, margin);
1030  scale += amrex::Math::abs(term.coefficient * value);
1031  }
1032  Real adverse = Real(0.0);
1033  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
1034  const Real left_delta = face_correction(
1035  descriptor, local_terms, low_faces, high_faces,
1036  i, j, k, dir, -1, tau, dx);
1037  const Real right_delta = face_correction(
1038  descriptor, local_terms, low_faces, high_faces,
1039  i, j, k, dir, 1, tau, dx);
1040  adverse += amrex::max(Real(0.0), -left_delta) +
1041  amrex::max(Real(0.0), -right_delta);
1042  }
1043  if (!amrex::Math::isfinite(margin) ||
1044  !amrex::Math::isfinite(adverse) ||
1045  margin < -roundoff * scale) {
1046  bad = 1;
1047  }
1048  ratios(i, j, k, ratio_offset + ci) =
1049  adverse > Real(0.0)
1050  ? clamp_unit(margin / adverse)
1051  : Real(1.0);
1052  }
1053 
1054  for (int si = 0; si < support_count; ++si) {
1055  const auto& support =
1056  local_supports[supports_begin + si];
1057  Real donor_min = std::numeric_limits<Real>::infinity();
1058  Real donor_max = -std::numeric_limits<Real>::infinity();
1059  int found = 0;
1060  include_neighbourhood(base, i, j, k, support, donor_min,
1061  donor_max, found);
1062  include_neighbourhood(input, i, j, k, support,
1063  donor_min, donor_max, found);
1064  include_neighbourhood(anchor, i, j, k, support,
1065  donor_min, donor_max, found);
1066  Real support_min = found != 0 ? donor_min : Real(0.0);
1067  Real support_max = found != 0 ? donor_max : Real(0.0);
1068  if (found != 0 && support.has_hard_min != 0) {
1069  support_min =
1070  amrex::max(support_min, support.hard_min);
1071  }
1072  if (found != 0 && support.has_hard_max != 0) {
1073  support_max =
1074  amrex::min(support_max, support.hard_max);
1075  }
1076  if (!amrex::Math::isfinite(support_min) ||
1077  !amrex::Math::isfinite(support_max) ||
1078  support_min > support_max) {
1079  bad = 1;
1080  }
1081 
1082  const Real property =
1083  hlow(i, j, k, support.property_local);
1084  const Real carrier =
1085  hlow(i, j, k, support.carrier_local);
1086  for (int side = 0; side < 2; ++side) {
1087  const bool upper = side != 0;
1088  const Real slope =
1089  upper ? support_max : support_min;
1090  const Real margin =
1091  upper ? slope * carrier - property
1092  : property - slope * carrier;
1093  const Real scale =
1094  amrex::Math::abs(property) +
1095  amrex::Math::abs(slope * carrier);
1096  Real adverse = Real(0.0);
1097  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
1098  const Real left_delta =
1099  property_face_correction(
1100  support, low_faces, high_faces, i, j, k,
1101  dir, -1, tau, dx, slope, upper);
1102  const Real right_delta =
1103  property_face_correction(
1104  support, low_faces, high_faces, i, j, k,
1105  dir, 1, tau, dx, slope, upper);
1106  adverse += amrex::max(Real(0.0), -left_delta) +
1107  amrex::max(Real(0.0), -right_delta);
1108  }
1109  if (!amrex::Math::isfinite(margin) ||
1110  !amrex::Math::isfinite(adverse) ||
1111  margin < -roundoff * scale) {
1112  bad = 1;
1113  }
1114  const int ratio_component =
1115  ratio_offset + linear_count + 2 * si + side;
1116  ratios(i, j, k, ratio_component) =
1117  adverse > Real(0.0)
1118  ? clamp_unit(margin / adverse)
1119  : Real(1.0);
1120  }
1121  }
1122 
1123  if (canonical_reserve != 0) {
1124  // This transport-only reserve joins the existing
1125  // closed FCT ratios; final canonical admission stays
1126  // the authoritative persisted-state check.
1127  const Real reserve = std::fma(
1129  hlow(i, j, k, canonical_mass_local),
1131  hlow(i, j, k, canonical_number_local));
1132  Real adverse = Real(0.0);
1133  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
1134  const Real left_delta =
1135  canonical_reserve_face_correction(
1139  canonical_number_coefficient, low_faces,
1140  high_faces, i, j, k, dir, -1, tau, dx);
1141  const Real right_delta =
1142  canonical_reserve_face_correction(
1146  canonical_number_coefficient, low_faces,
1147  high_faces, i, j, k, dir, 1, tau, dx);
1148  adverse += amrex::max(Real(0.0), -left_delta) +
1149  amrex::max(Real(0.0), -right_delta);
1150  }
1151  const int ratio_component =
1152  ratio_offset + linear_count + 2 * support_count;
1153  if (!amrex::Math::isfinite(reserve) ||
1154  !amrex::Math::isfinite(adverse)) {
1155  bad = 1;
1156  ratios(i, j, k, ratio_component) = Real(0.0);
1157  } else if (reserve <= Real(0.0)) {
1158  ratios(i, j, k, ratio_component) = Real(0.0);
1159  } else if (adverse <= Real(0.0)) {
1160  ratios(i, j, k, ratio_component) = Real(1.0);
1161  } else {
1162  ratios(i, j, k, ratio_component) =
1163  clamp_unit(reserve / adverse);
1164  }
1165  }
1166  if (bad != 0) {
1167  invalid(i, j, k, 0) = Real(1.0);
1168  }
1169  });
1170  }
1171  }
1172 
1173  // Every complete group has now written its own ratio components.
1174  // Exchange the chunk's ratio halo once before any group reads it.
1175  data.cell_ratios.FillBoundary(geometry.periodicity());
1176  if (data.invalid.max(0) != Real(0.0)) {
1177  amrex::Abort("SBM M3 donor low-order trial violates a linear or "
1178  "attached-property/canonical-reserve constraint");
1179  }
1180 
1181  for (const int group_index : chunk.group_indices) {
1182  const auto& group = m_groups[static_cast<std::size_t>(group_index)];
1183  const auto& group_device =
1184  device.host_groups[static_cast<std::size_t>(group_index)];
1185  AMREX_ALWAYS_ASSERT(group_device.ratio_offset >= 0);
1186  AMREX_ALWAYS_ASSERT(group_device.ratio_count >= 0);
1188  group_device.ratio_offset <= data.cell_ratios.nComp());
1190  group_device.ratio_count <=
1191  data.cell_ratios.nComp() - group_device.ratio_offset);
1192 
1193  // Each face/group lambda is the minimum budget from both
1194  // adjacent cells and every constraint in the complete group.
1195  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
1196  auto& lambda_field = data.face_lambda.dir(dir);
1197  for (amrex::MFIter mfi(lambda_field, amrex::TilingIfNotGPU());
1198  mfi.isValid(); ++mfi) {
1199  const amrex::Box bx = mfi.tilebox();
1200  const auto ratios = data.cell_ratios.const_array(mfi);
1201  const auto lambda = lambda_field.array(mfi);
1202  const int ratio_count = group_device.ratio_count;
1203  const int ratio_offset = group_device.ratio_offset;
1204  amrex::ParallelFor(bx, [=] AMREX_GPU_DEVICE(
1205  int i, int j, int k) noexcept {
1206  int li = i, lj = j, lk = k;
1207  if (dir == 0) {
1208  --li;
1209  } else if (dir == 1) {
1210  --lj;
1211  } else {
1212  --lk;
1213  }
1214  Real accepted = Real(1.0);
1215  for (int c = 0; c < ratio_count; ++c) {
1216  accepted =
1217  amrex::min(accepted,
1218  ratios(li, lj, lk, ratio_offset + c));
1219  accepted = amrex::min(
1220  accepted, ratios(i, j, k, ratio_offset + c));
1221  }
1222  lambda(i, j, k, 0) = clamp_unit(accepted);
1223  });
1224  }
1225  }
1226 
1227  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
1228  auto& accepted_field = data.accepted_rate.dir(dir);
1229  const auto& low_field = data.low_rate.dir(dir);
1230  const auto& high_field = data.high_rate.dir(dir);
1231  const auto& lambda_field = data.face_lambda.dir(dir);
1232  for (amrex::MFIter mfi(accepted_field, amrex::TilingIfNotGPU());
1233  mfi.isValid(); ++mfi) {
1234  const amrex::Box bx = mfi.tilebox();
1235  const auto low = low_field.const_array(mfi);
1236  const auto high = high_field.const_array(mfi);
1237  const auto lambda = lambda_field.const_array(mfi);
1238  const auto accepted = accepted_field.array(mfi);
1239  for (const int component : group.members) {
1240  const int local_component =
1241  global_to_local[static_cast<std::size_t>(
1242  component)];
1243  AMREX_ALWAYS_ASSERT(local_component >= 0);
1245  bx,
1246  [=] AMREX_GPU_DEVICE(int i, int j, int k) noexcept {
1247  const Real alpha = lambda(i, j, k, 0);
1248  accepted(i, j, k, local_component) =
1249  low(i, j, k, local_component) +
1250  alpha * (high(i, j, k, local_component) -
1251  low(i, j, k, local_component));
1252  });
1253  }
1254  }
1255  }
1256 
1257  // Accumulate only the accepted spectral mass rate into the
1258  // two-component fixed liquid projection ledger.
1259  const auto& projection_spec = m_layout.liquid_projection();
1260  if (group.population_id == projection_spec.population_id) {
1261  const int mass_component =
1262  m_layout.mass_offset(group.population_id) + group.bin;
1263  const int local_mass =
1264  global_to_local[static_cast<std::size_t>(mass_component)];
1265  const int projected_component =
1266  group.bin < projection_spec.cloud_rain_split ? 0 : 1;
1267  for (int dir = 0; dir < AMREX_SPACEDIM; ++dir) {
1268  MultiFab::Saxpy(data.projected_rate.dir(dir), Real(1.0),
1269  data.accepted_rate.dir(dir), local_mass,
1270  projected_component, 1, 0);
1271  }
1272  }
1273  }
1274 
1275  // Apply the ERF stage recurrence component by component while using
1276  // this bounded complete-group chunk's accepted face rates.
1277  for (std::size_t local = 0; local < chunk.components.size(); ++local) {
1278  const int component = chunk.components[local];
1280  context.method = method;
1281  context.level = level;
1282  context.stage = stage;
1283  context.step_old_time = step_old_time;
1284  context.input_time = input_time;
1285  context.target_time = target_time;
1286  context.recurrence = recipe;
1287  context.state_anchor = {&data.anchor, component, step_old_time};
1288  context.state_input = {&spectrum, component, input_time};
1289  context.state_target = {&data.target, component, target_time};
1290  context.rho_anchor = {&conserved_anchor, Rho_comp, step_old_time};
1291  context.rho_input = {&conserved_input, Rho_comp, input_time};
1292  context.rho_target = {&conserved_target, Rho_comp, target_time};
1293  context.measure_anchor = {&data.measure, 0, step_old_time};
1294  context.measure_input = {&data.measure, 0, input_time};
1295  context.measure_target = {&data.measure, 0, target_time};
1296  context.carrier = {&avg_xmom, &avg_ymom, &avg_zmom};
1298  context, data.accepted_rate, inv_dx, static_cast<int>(local));
1299  }
1300 
1301  if (data.spectral_ledger.is_defined()) {
1302  for (std::size_t local = 0; local < chunk.components.size(); ++local) {
1303  if (!data.spectral_ledger.accumulate_stage_component(
1304  data.accepted_rate, static_cast<int>(local),
1305  chunk.components[local], diagnostic)) {
1306  amrex::Abort("SBM M4a spectral chunk-to-ledger mapping: " +
1307  diagnostic);
1308  }
1309  }
1310  }
1311  }
1312 
1313  // Candidate-wide device admission combines finite-value checking, every
1314  // declared linear group inequality, and strict canonical persisted-state
1315  // validation. Diagnostic host scanning occurs only after this fast gate
1316  // fails.
1317  const ConstraintDescriptor* global_constraints =
1318  device.global_constraints.data();
1319  const ConstraintTerm* global_terms = device.global_terms.data();
1320  const PopulationRemapView* remap_populations = device.populations.data();
1321  const int global_constraint_count =
1322  static_cast<int>(m_flat_constraints.constraints.size());
1323  const int remap_population_count =
1324  static_cast<int>(m_layout.populations().size());
1325  data.invalid.setVal(Real(0.0));
1326  for (amrex::MFIter mfi(data.target, amrex::TilingIfNotGPU()); mfi.isValid();
1327  ++mfi) {
1328  const amrex::Box bx = mfi.tilebox();
1329  const auto candidate = data.target.const_array(mfi);
1330  const auto invalid = data.invalid.array(mfi);
1331  const int state_components = m_layout.ncomp();
1332  amrex::ParallelFor(bx, [=] AMREX_GPU_DEVICE(int i, int j,
1333  int k) noexcept {
1334  int bad = 0;
1335  for (int component = 0; component < state_components; ++component) {
1336  if (!amrex::Math::isfinite(candidate(i, j, k, component))) {
1337  bad = 1;
1338  }
1339  }
1340  const Real roundoff =
1342  for (int ci = 0; ci < global_constraint_count; ++ci) {
1343  const auto& descriptor = global_constraints[ci];
1344  Real margin = Real(0.0);
1345  Real scale = Real(0.0);
1346  for (int t = 0; t < descriptor.term_count; ++t) {
1347  const auto& term = global_terms[descriptor.term_offset + t];
1348  const Real value = candidate(i, j, k, term.component);
1349  margin = std::fma(term.coefficient, value, margin);
1350  scale += amrex::Math::abs(term.coefficient * value);
1351  }
1352  if (!amrex::Math::isfinite(margin) ||
1353  margin < -roundoff * scale)
1354  bad = 1;
1355  }
1357  candidate, i, j, k};
1358  for (int p = 0; p < remap_population_count; ++p) {
1359  const auto& population = remap_populations[p];
1360  for (int bin = 0; bin < population.nbins; ++bin) {
1362  population, bin, cell_state, state_components)) {
1363  bad = 1;
1364  }
1365  }
1366  }
1367  invalid(i, j, k, 0) = static_cast<Real>(bad);
1368  });
1369  }
1370  if (data.invalid.max(0) != Real(0.0)) {
1371  std::string reason;
1372  const bool host_admissible = erf_sbm::authoritative_state_admissible(
1373  data.target, m_layout, level, &reason);
1374  amrex::ignore_unused(host_admissible);
1375  if (reason.empty()) {
1376  reason = "candidate failed device linear/canonical admission";
1377  }
1378  amrex::Abort("SBM M3 candidate rejected before commit: " + reason);
1379  }
1380 
1381  // Only fully admitted candidates may finish an authoritative spectral
1382  // ledger stage. Chunk calls above accumulate components without advancing
1383  // the host stage sequence.
1384  // Ledger admission is MPI-collective: every rank on this level must enter
1385  // despite local recoverable errors; do not branch around these calls using
1386  // rank-local predicates.
1387  if (data.spectral_ledger.is_defined() &&
1388  !data.spectral_ledger.finish_stage(diagnostic)) {
1389  amrex::Abort("SBM M4a spectral face-ledger stage finish: " + diagnostic);
1390  }
1391  // Retain the existing two-component projected ledger and its exact host
1392  // stage recipe independently of the full spectral integral.
1393  if (!data.projected_ledger.accept_stage(method, stage, step_old_time,
1394  recipe, data.projected_rate,
1395  diagnostic)) {
1396  amrex::Abort("SBM M3 projected face-ledger stage sequence: " +
1397  diagnostic);
1398  }
1399  MultiFab::Copy(state_manager.new_target_storage(level), data.target, 0, 0,
1400  m_layout.ncomp(), 0);
1401  const bool physical_step_complete =
1402  (method == erf_auxiliary::HostIntegrator::CompressibleRK3 && stage == 2) ||
1403  (method == erf_auxiliary::HostIntegrator::AnelasticHeun && stage == 1);
1404  if (!state_manager.accept_stage_target(level, target_time,
1405  physical_step_complete, diagnostic)) {
1406  amrex::Abort("SBM M4a accepted-state lifecycle commit: " + diagnostic);
1407  }
1408  state_manager.project_to_core(level, conserved_target, qc_component,
1409  qr_component);
1410 }
void BuildScalarAdvectionFluxes(const amrex::Box &bx, const amrex::Array4< const amrex::Real > &scalar, const int scalar_comp, const amrex::GpuArray< const amrex::Array4< amrex::Real >, AMREX_SPACEDIM > &flx_arr, const int flux_comp, const amrex::Array4< const amrex::Real > &avg_xmom, const amrex::Array4< const amrex::Real > &avg_ymom, const amrex::Array4< const amrex::Real > &avg_zmom, const AdvType horiz_adv_type, const AdvType vert_adv_type, const amrex::Real horiz_upw_frac, const amrex::Real vert_upw_frac)
Definition: ERF_AdvectionSrcForScalars.H:204
#define Rho_comp
Definition: ERF_IndexDefines.H:42
const Real dy
Definition: ERF_InitCustomPert_ABL.H:45
const Real dx
Definition: ERF_InitCustomPert_ABL.H:44
AMREX_ALWAYS_ASSERT_WITH_MESSAGE(m_cloud_chamber_config.active, "Cloud Chamber: initializer reached without a parsed configuration")
for(int i=0;i< m_num_species;i++)
Definition: ERF_InitCustomPert_MultiSpeciesBubble.H:48
ParallelFor(fab_box, [=] AMREX_GPU_DEVICE(int i, int j, int k) { qrcuten_arr(i, j, k)=Real(0);qscuten_arr(i, j, k)=Real(0);qicuten_arr(i, j, k)=Real(0);})
int constraints_begin
Definition: ERF_SBMTransport.cpp:32
int ratio_count
Definition: ERF_SBMTransport.cpp:38
Real canonical_number_coefficient
Definition: ERF_SBMTransport.cpp:44
int canonical_mass_local
Definition: ERF_SBMTransport.cpp:41
int supports_begin
Definition: ERF_SBMTransport.cpp:34
int canonical_number_local
Definition: ERF_SBMTransport.cpp:42
int ratio_offset
Definition: ERF_SBMTransport.cpp:39
Real canonical_mass_coefficient
Definition: ERF_SBMTransport.cpp:43
int support_count
Definition: ERF_SBMTransport.cpp:35
int canonical_reserve
Definition: ERF_SBMTransport.cpp:40
int mass_offset(const int population) const
Definition: ERF_SBMLayout.cpp:179
const LiquidProjectionSpec & liquid_projection() const noexcept
Definition: ERF_SBMLayout.H:102
bool is_defined(int level) const
Definition: ERF_SBMTransport.cpp:1421
@ rho
Definition: ERF_Kessler.H:25
@ omega
Definition: ERF_Morrison.H:55
@ alpha
Definition: ERF_SLM.H:151
@ dz
Definition: ERF_AdvanceWDM6.cpp:272
@ t
Definition: ERF_WSM6.H:272
void ApplyAuxiliaryMappedStage(const AuxiliaryStageContext &context, const MappedFaceFluxRate &rate, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &dx_inv, const int rate_component)
Definition: ERF_AuxiliaryStage.cpp:169
bool MakeAuxiliaryStageRecipe(const HostIntegrator method, const int stage, const double host_stage_interval, AuxiliaryStageRecipe &recipe, std::string &diagnostic)
Definition: ERF_AuxiliaryStage.cpp:67
bool ValidatePositiveFiniteComponent(const amrex::MultiFab &field, const int component, std::string &diagnostic)
Definition: ERF_AuxiliaryMappedTransport.cpp:294
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE amrex::Real ComputationalMappedDivergence(const amrex::Real fx_hi, const amrex::Real fx_lo, const amrex::Real fy_hi, const amrex::Real fy_lo, const amrex::Real fz_hi, const amrex::Real fz_lo, const amrex::Real dx_inv, const amrex::Real dy_inv, const amrex::Real dzeta_inv) noexcept
Definition: ERF_AuxiliaryMappedTransport.H:119
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE amrex::Real MappedOutgoingDemandRate(const amrex::Real fx_hi, const amrex::Real fx_lo, const amrex::Real fy_hi, const amrex::Real fy_lo, const amrex::Real fz_hi, const amrex::Real fz_lo, const amrex::Real measure, const amrex::Real density, const amrex::GpuArray< amrex::Real, AMREX_SPACEDIM > &dx_inv) noexcept
Definition: ERF_AuxiliaryMappedTransport.H:136
bool SameCellLayout(const amrex::MultiFab &lhs, const amrex::MultiFab &rhs)
Definition: ERF_AuxiliaryMappedTransport.cpp:36
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE bool canonical_persisted_bin_state(const PopulationRemapView &population, const int bin, const amrex::Real *state, const int state_count) noexcept
Definition: ERF_SBMRemapping.H:475
AMREX_GPU_HOST_DEVICE AMREX_FORCE_INLINE bool try_two_moment_to_endpoints(const amrex::Real C, const amrex::Real M, const amrex::Real lower, const amrex::Real upper, EndpointTransform &result) noexcept
Definition: ERF_SpectralGrid.H:48
bool authoritative_state_admissible(const amrex::MultiFab &spectrum, const SBMLayout &layout, const int level, std::string *diagnostic)
Definition: ERF_SBMRestart.cpp:39
real(c_double), private ci
Definition: ERF_module_mp_morr_two_moment.F90:203
Definition: ERF_AuxiliaryStage.H:63
int level
Definition: ERF_AuxiliaryStage.H:65
ConstTimedFieldView rho_anchor
Definition: ERF_AuxiliaryStage.H:78
AuxiliaryStageRecipe recurrence
Definition: ERF_AuxiliaryStage.H:72
ConstTimedFieldView rho_input
Definition: ERF_AuxiliaryStage.H:79
int stage
Definition: ERF_AuxiliaryStage.H:66
ConstTimedFieldView measure_anchor
Definition: ERF_AuxiliaryStage.H:82
double input_time
Definition: ERF_AuxiliaryStage.H:69
ConstTimedFieldView measure_input
Definition: ERF_AuxiliaryStage.H:83
HostIntegrator method
Definition: ERF_AuxiliaryStage.H:64
ConstTimedFieldView state_input
Definition: ERF_AuxiliaryStage.H:75
double target_time
Definition: ERF_AuxiliaryStage.H:70
ConstTimedFieldView measure_target
Definition: ERF_AuxiliaryStage.H:84
double step_old_time
Definition: ERF_AuxiliaryStage.H:68
HostCarrierFluxView carrier
Definition: ERF_AuxiliaryStage.H:86
ConstTimedFieldView rho_target
Definition: ERF_AuxiliaryStage.H:80
MutableTimedFieldView state_target
Definition: ERF_AuxiliaryStage.H:76
ConstTimedFieldView state_anchor
Definition: ERF_AuxiliaryStage.H:74
Definition: ERF_AuxiliaryStage.H:41
double limiter_trial_interval
Definition: ERF_AuxiliaryStage.H:45
LimiterTrialBase limiter_trial_base
Definition: ERF_AuxiliaryStage.H:42
Definition: ERF_SpectralGrid.H:34
Definition: ERF_SBMRemapping.H:363
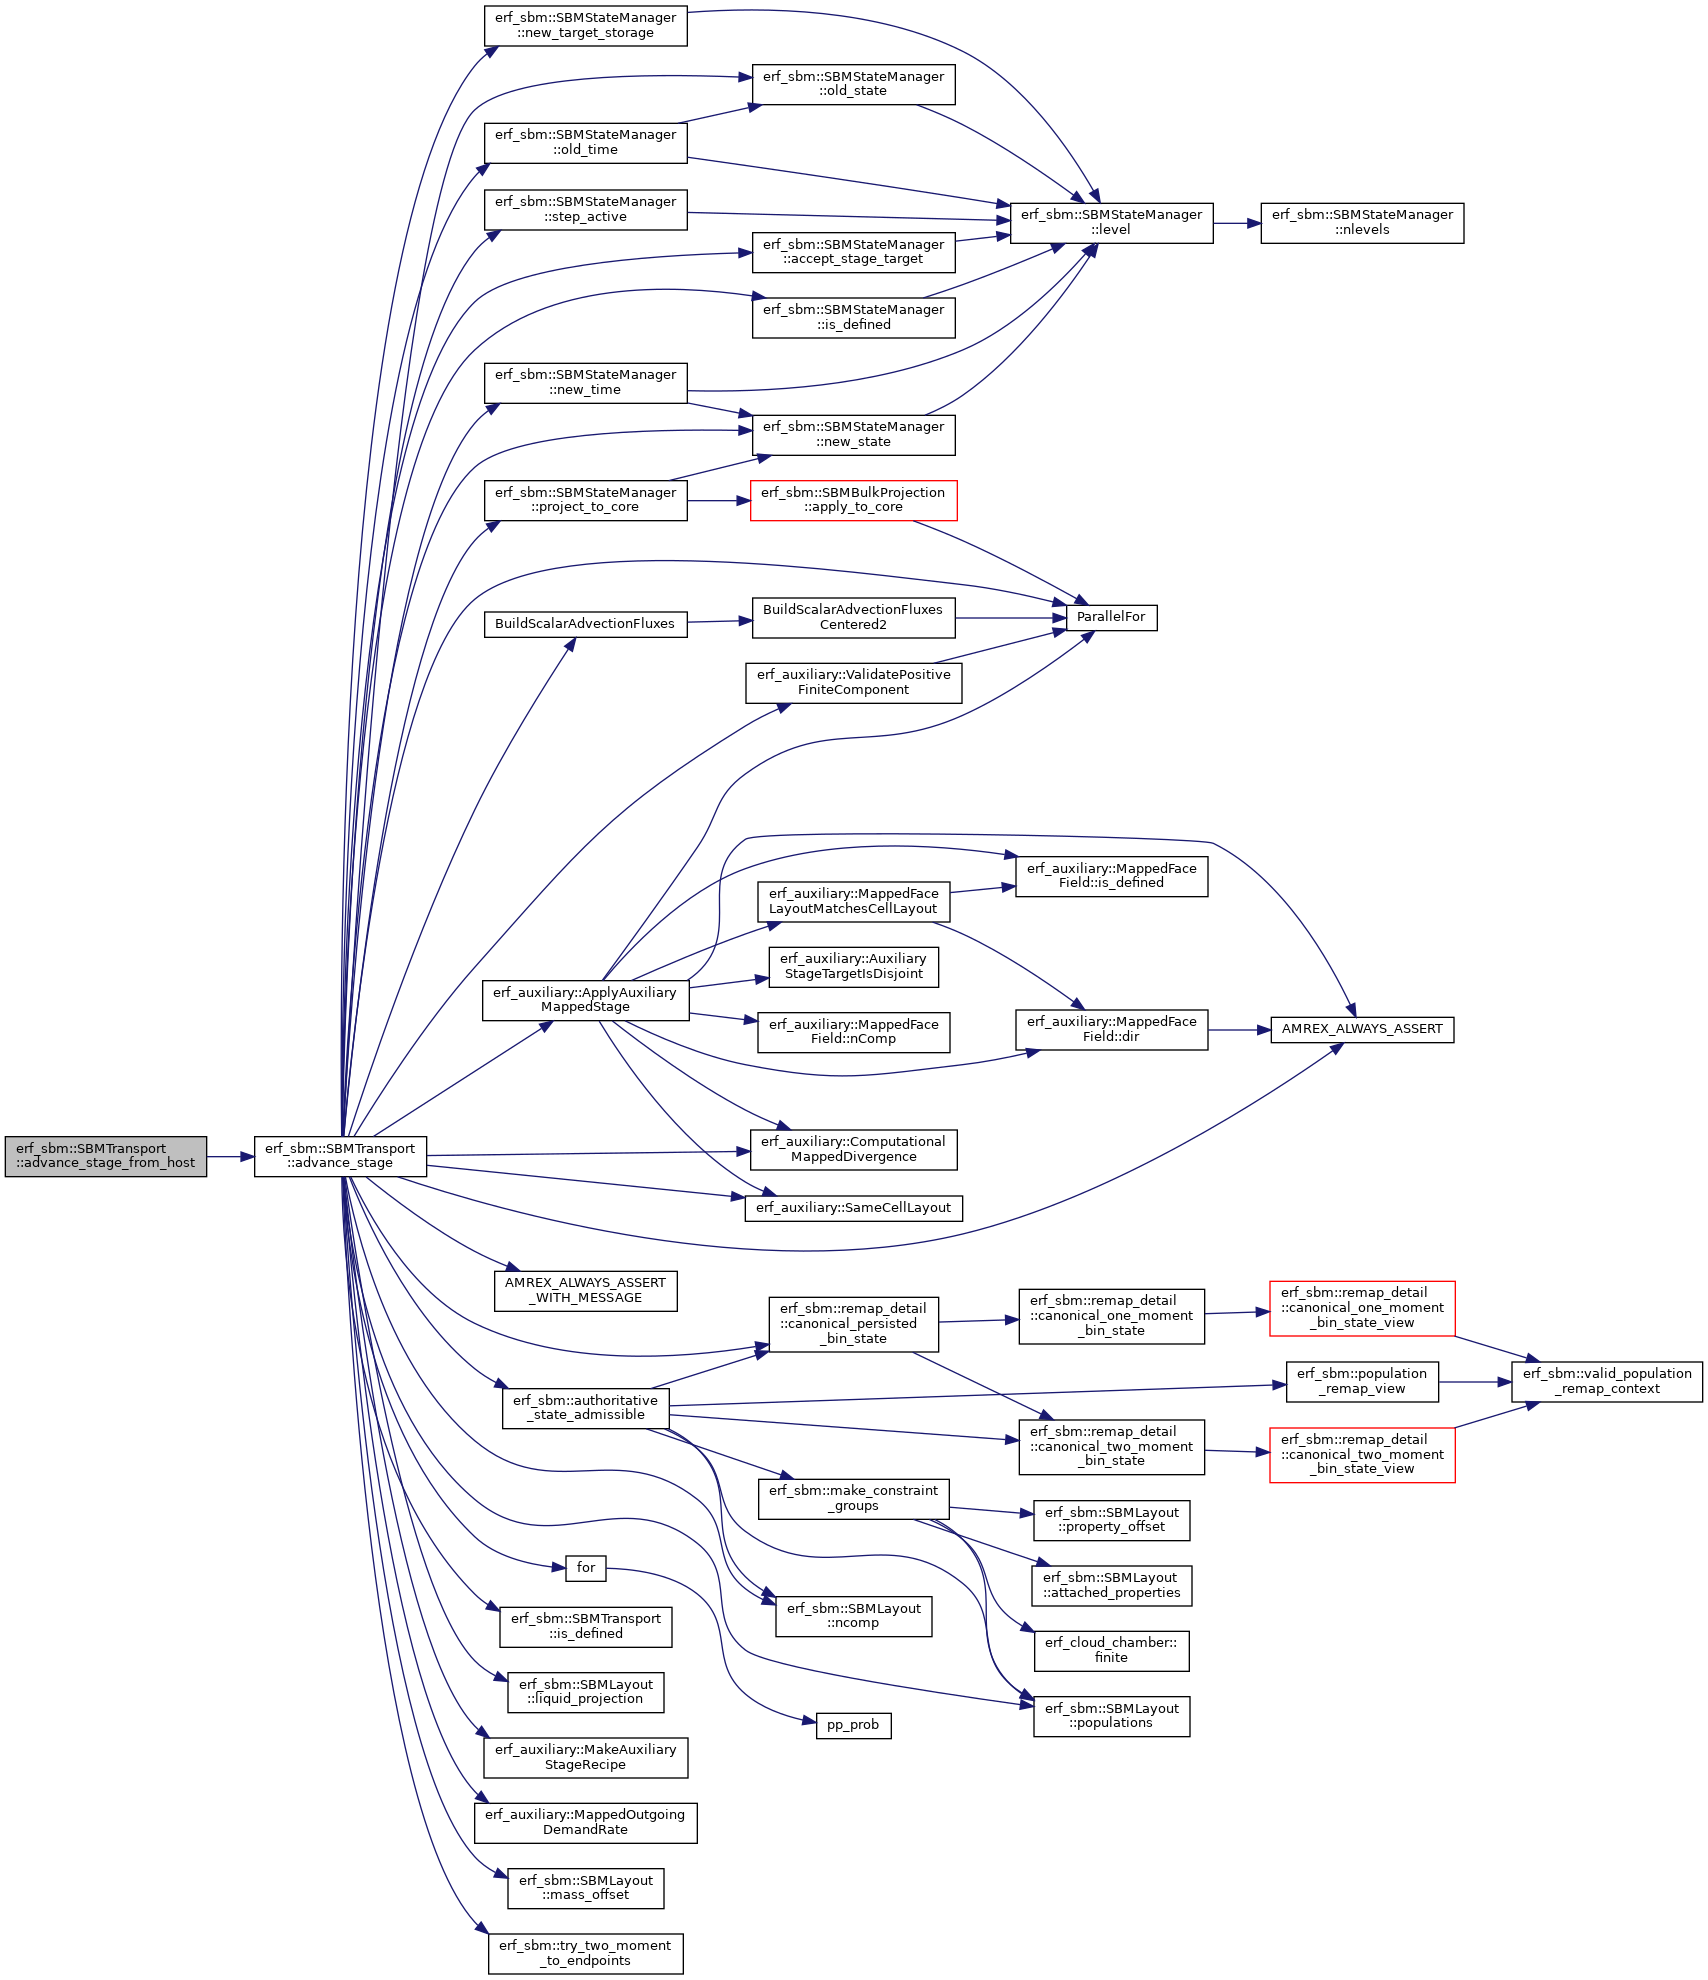
Referenced by advance_stage_from_host().

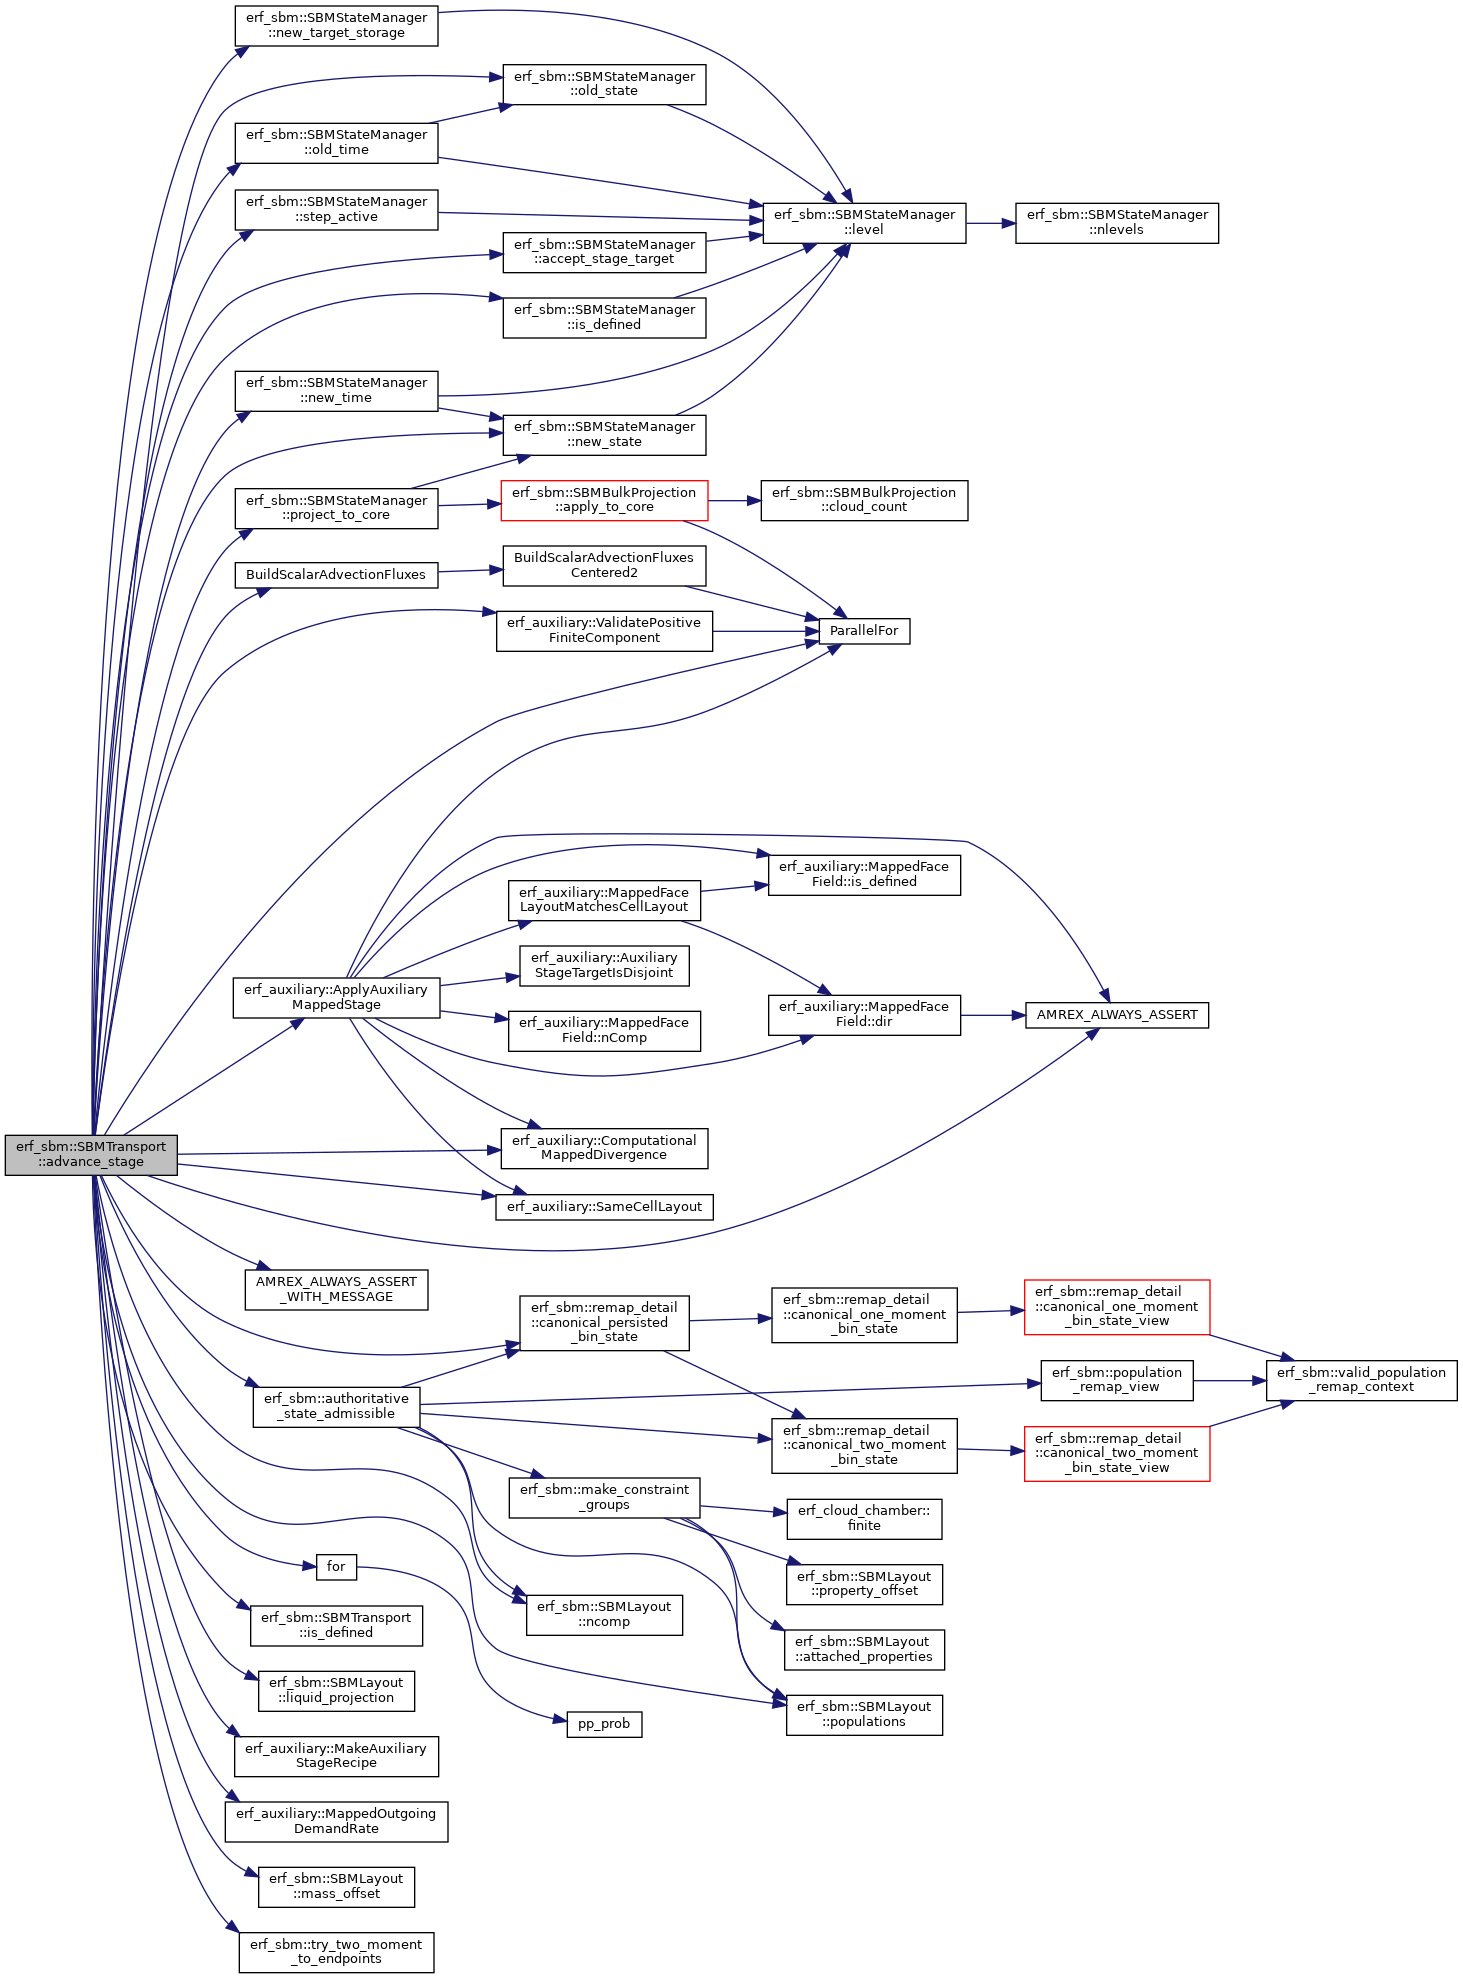
Here is the call graph for this function:
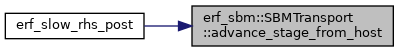
Here is the caller graph for this function:

◆ advance_stage_from_host()

void erf_sbm::SBMTransport::advance_stage_from_host ( int  level,
erf_auxiliary::HostIntegrator  method,
int  stage,
double  step_old_time,
double  input_time,
double  target_time,
double  host_stage_interval,
SBMStateManager &  state_manager,
const amrex::MultiFab &  S_old_cons,
const amrex::MultiFab &  S_new_cons,
amrex::MultiFab &  S_data_cons,
const amrex::MultiFab &  avg_xmom,
const amrex::MultiFab &  avg_ymom,
const amrex::MultiFab &  avg_zmom,
const amrex::Geometry &  geometry,
int  qc_component,
int  qr_component 
)

ERF slow-RHS seam. The conserved-state views are ordered as the old-step anchor, the actual host predictor/input, and the target being written. Keep this forwarding point shared by the ERF call site and seam-level tests so density-time pairing cannot drift silently.

604 {
605  // Preserve ERF's semantic state roles at the integration boundary:
606  // S_old anchors the step, S_new is the stage predictor, and S_data is the
607  // target. In particular, do not substitute S_data for the predictor
608  // density used to form the high-order intensive spectrum.
609  advance_stage(level, method, stage, step_old_time, input_time, target_time,
610  host_stage_interval, state_manager, S_old_cons, S_new_cons,
611  S_data_cons, avg_xmom, avg_ymom, avg_zmom, geometry,
612  qc_component, qr_component);
613 }
void advance_stage(int level, erf_auxiliary::HostIntegrator method, int stage, double step_old_time, double input_time, double target_time, double host_stage_interval, SBMStateManager &state_manager, const amrex::MultiFab &conserved_anchor, const amrex::MultiFab &conserved_input, amrex::MultiFab &conserved_target, const amrex::MultiFab &avg_xmom, const amrex::MultiFab &avg_ymom, const amrex::MultiFab &avg_zmom, const amrex::Geometry &geometry, int qc_component, int qr_component)
Definition: ERF_SBMTransport.cpp:616

Referenced by erf_slow_rhs_post().

Here is the call graph for this function:
Here is the caller graph for this function:

◆ completed_spectral_ledger()

const erf_auxiliary::CompletedStepFluxLedger & erf_sbm::SBMTransport::completed_spectral_ledger ( int  level) const

Authoritative all-component accepted transfer, defined for AMR-capable instances only.

1462 {
1463  if (!is_defined(level)) {
1464  throw std::logic_error("SBM transport level is not defined");
1465  }
1466  const auto& ledger = m_levels[static_cast<std::size_t>(level)]->spectral_ledger;
1467  if (!ledger.is_defined()) {
1468  throw std::logic_error(
1469  "completed spectral transfer is available only on AMR-capable transport instances");
1470  }
1471  if (!ledger.step_complete()) {
1472  throw std::logic_error(
1473  "spectral transfer is available only after a complete host step");
1474  }
1475  return ledger;
1476 }
Here is the call graph for this function:

◆ define()

void erf_sbm::SBMTransport::define ( int  level,
const amrex::BoxArray &  cell_ba,
const amrex::DistributionMapping &  dm 
)
525 {
526  AMREX_ALWAYS_ASSERT(level >= 0 &&
527  level < static_cast<int>(m_levels.size()));
528  AMREX_ALWAYS_ASSERT(m_levels[static_cast<std::size_t>(level)] == nullptr);
529  int max_chunk_components = 0;
530  int max_chunk_ratio_components = 0;
531  for (const auto& chunk : m_chunks) {
532  max_chunk_components = std::max(
533  max_chunk_components, static_cast<int>(chunk.components.size()));
534  int chunk_ratio_components = 0;
535  for (const int group : chunk.group_indices) {
536  chunk_ratio_components +=
537  m_max_constraints_per_group[static_cast<std::size_t>(group)];
538  }
539  max_chunk_ratio_components =
540  std::max(max_chunk_ratio_components, chunk_ratio_components);
541  }
542  auto data = std::make_unique<LevelStorage>();
543  const int ncomp = m_layout.ncomp();
544  data->anchor.define(cell_ba, dm, ncomp, 0);
545  data->target.define(cell_ba, dm, ncomp, 0);
546  data->input_intensive.define(cell_ba, dm, ncomp, 2);
547  data->physical_input_intensive.define(cell_ba, dm, ncomp, 2);
548  data->base_intensive.define(cell_ba, dm, ncomp, 2);
549  data->anchor_intensive.define(cell_ba, dm, ncomp, 2);
550  data->low_trial_h.define(cell_ba, dm, max_chunk_components, 0);
551  data->cell_ratios.define(cell_ba, dm,
552  std::max(1, max_chunk_ratio_components), 1);
553  data->invalid.define(cell_ba, dm, 1, 0);
554  data->outgoing_demand.define(cell_ba, dm, 1, 0);
555  data->measure.define(cell_ba, dm, 1, 0);
556  data->low_rate.define(cell_ba, dm, max_chunk_components, 0);
557  data->high_rate.define(cell_ba, dm, max_chunk_components, 0);
558  data->accepted_rate.define(cell_ba, dm, max_chunk_components, 0);
559  data->face_lambda.define(cell_ba, dm, 1, 0);
560  data->projected_rate.define(cell_ba, dm, 2, 0);
561  data->projected_ledger.define(cell_ba, dm, 2);
562  if (m_levels.size() > 1) {
563  data->spectral_ledger.define(cell_ba, dm, ncomp);
564  }
565  data->anchor.setVal(Real(0.0));
566  data->target.setVal(Real(0.0));
567  data->invalid.setVal(Real(0.0));
568  data->projected_rate.setVal(Real(0.0));
569  m_levels[static_cast<std::size_t>(level)] = std::move(data);
570 }
Here is the call graph for this function:

◆ destroy()

void erf_sbm::SBMTransport::destroy ( int  level)
1414 {
1415  AMREX_ALWAYS_ASSERT(level >= 0 &&
1416  level < static_cast<int>(m_levels.size()));
1417  m_levels[static_cast<std::size_t>(level)].reset();
1418 }
Here is the call graph for this function:

◆ is_defined()

bool erf_sbm::SBMTransport::is_defined ( int  level) const
1422 {
1423  if (level < 0 || level >= static_cast<int>(m_levels.size())) {
1424  throw std::out_of_range("SBM transport level is outside the workspace");
1425  }
1426  return static_cast<bool>(m_levels[static_cast<std::size_t>(level)]);
1427 }

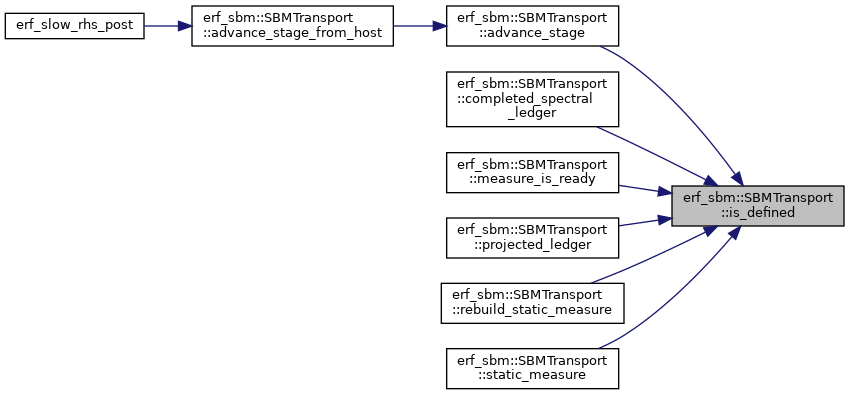
Referenced by advance_stage(), completed_spectral_ledger(), measure_is_ready(), projected_ledger(), rebuild_static_measure(), and static_measure().

Here is the caller graph for this function:

◆ measure_is_ready()

bool erf_sbm::SBMTransport::measure_is_ready ( int  level) const
1431 {
1432  if (!is_defined(level)) {
1433  return false;
1434  }
1435  return m_levels[static_cast<std::size_t>(level)]->measure_ready;
1436 }
Here is the call graph for this function:

◆ operator=()

SBMTransport& erf_sbm::SBMTransport::operator= ( const SBMTransport &  )
delete

◆ projected_ledger()

const erf_auxiliary::CompletedStepFluxLedger & erf_sbm::SBMTransport::projected_ledger ( int  level) const
1453 {
1454  if (!is_defined(level)) {
1455  throw std::logic_error("SBM transport level is not defined");
1456  }
1457  return m_levels[static_cast<std::size_t>(level)]->projected_ledger;
1458 }
const erf_auxiliary::CompletedStepFluxLedger & projected_ledger(int level) const
Definition: ERF_SBMTransport.cpp:1452
Here is the call graph for this function:

◆ rebuild_static_measure()

bool erf_sbm::SBMTransport::rebuild_static_measure ( int  level,
const amrex::MultiFab &  detJ,
const amrex::MultiFab &  mx,
const amrex::MultiFab &  my,
std::string &  diagnostic 
)
578 {
579  diagnostic.clear();
580  if (!is_defined(level)) {
581  diagnostic =
582  "static mapped measure requires a defined SBM transport level";
583  return false;
584  }
585  auto& data = *m_levels[static_cast<std::size_t>(level)];
586  data.measure_ready = false;
587  if (!erf_auxiliary::BuildMappedCellMeasure(data.measure, detJ, mx, my,
588  diagnostic))
589  return false;
590  data.measure_ready = true;
591  return true;
592 }
bool BuildMappedCellMeasure(amrex::MultiFab &omega, const amrex::MultiFab &detJ, const amrex::MultiFab &mx, const amrex::MultiFab &my, std::string &diagnostic)
Definition: ERF_AuxiliaryMappedTransport.cpp:42
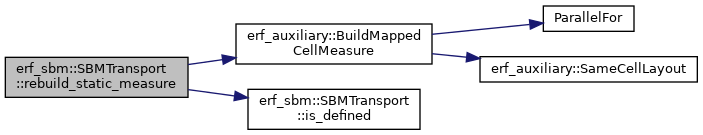
Here is the call graph for this function:

◆ static_measure()

const MultiFab & erf_sbm::SBMTransport::static_measure ( int  level) const
1440 {
1441  if (!is_defined(level)) {
1442  throw std::logic_error("SBM transport level is not defined");
1443  }
1444  const auto& data = *m_levels[static_cast<std::size_t>(level)];
1445  if (!data.measure_ready) {
1446  throw std::logic_error("SBM static measure is not ready");
1447  }
1448  return data.measure;
1449 }
Here is the call graph for this function:

Member Data Documentation

◆ m_chunks

std::vector<ConstraintClosureChunk> erf_sbm::SBMTransport::m_chunks
private

Referenced by advance_stage(), define(), and SBMTransport().

◆ m_device_metadata

std::unique_ptr<DeviceMetadata> erf_sbm::SBMTransport::m_device_metadata
private

Referenced by advance_stage(), and SBMTransport().

◆ m_flat_constraints

FlattenedConstraintSet erf_sbm::SBMTransport::m_flat_constraints
private

Referenced by advance_stage(), and SBMTransport().

◆ m_groups

std::vector<ConstraintGroup> erf_sbm::SBMTransport::m_groups
private

Referenced by advance_stage(), and SBMTransport().

◆ m_layout

const SBMLayout& erf_sbm::SBMTransport::m_layout
private

Referenced by advance_stage(), define(), and SBMTransport().

◆ m_levels

std::vector<std::unique_ptr<LevelStorage> > erf_sbm::SBMTransport::m_levels
private

◆ m_max_constraints_per_group

std::vector<int> erf_sbm::SBMTransport::m_max_constraints_per_group
private

Referenced by define(), and SBMTransport().

◆ m_projection

SBMBulkProjection erf_sbm::SBMTransport::m_projection
private

◆ m_property_support

std::vector<AttachedPropertySupportDescriptor> erf_sbm::SBMTransport::m_property_support
private

Referenced by SBMTransport().


The documentation for this class was generated from the following files: